Allen Institute for AI releases StateBench for long-document state tracking
StateBench divides state tracking into four levels to test how transformer, recurrent and hybrid models carry changing information through increasingly long sequences.
The Allen Institute for AI released StateBench, an open benchmark designed to measure how language models track changing information across long documents. The release includes a technical report, a public dataset and an Apache 2.0-licensed code repository, providing a controlled test of where different model architectures lose state as dependency chains grow.
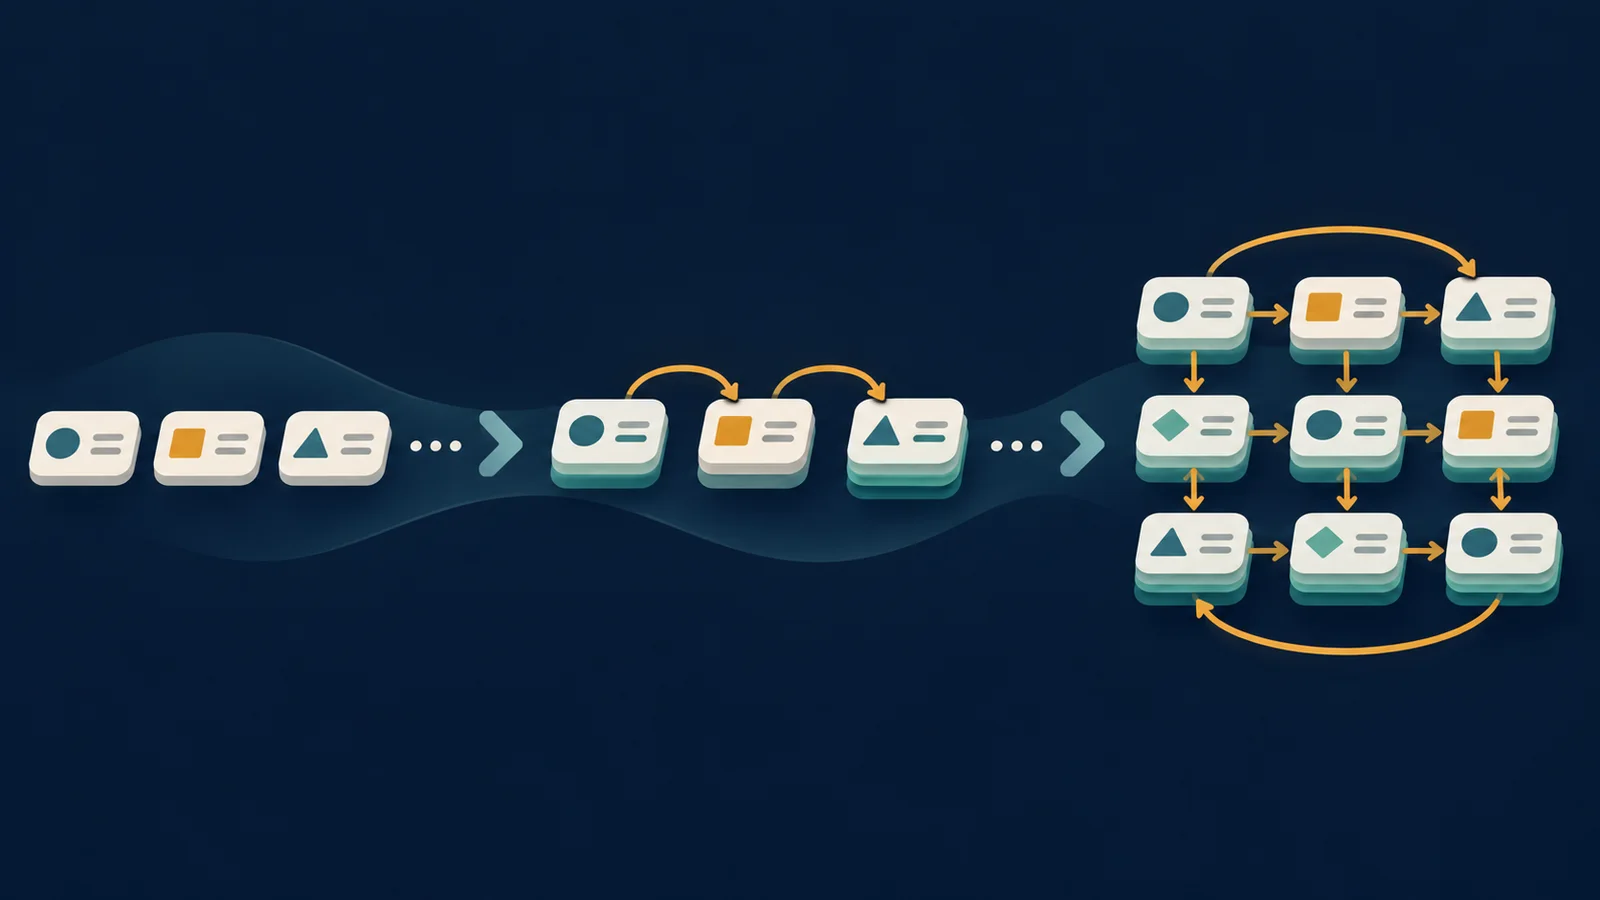
StateBench divides the problem into four nested levels. R-trivial tasks require recovering an immutable assignment; aperiodic tasks allow a value to be reassigned; soluble tasks add updates based on a variable’s current value; and general finite tasks let one variable take another variable’s value. In plain terms, the progression moves from remembering a fixed fact to following chains of interdependent changes where missing one update can corrupt the final answer.
To make comparisons controlled, the researchers begin with the same general finite assignment trace and derive the three easier versions from it. The resulting tasks preserve the number of variables, distinct values and assignment positions while changing the permitted update operation. The StateBench paper describes a static evaluation set spanning eight to 64,000 assignments, with each underlying structure rendered in six text formats to test sensitivity to presentation.
For the architecture-focused experiment, authors Jackson Petty, William Merrill and Ashish Sabharwal randomly initialized six 275-million-parameter models: two transformers, two Gated DeltaNet recurrent models and two transformer-Gated DeltaNet hybrids. They trained the models on sequences containing eight to 256 assignments, then evaluated them on sequences as long as 64,000 assignments, or 250 times the maximum training length.
The authors report that the directly trained Gated DeltaNet models generalized perfectly on the r-trivial, aperiodic and soluble tasks, while the hybrid models were near-perfect on those levels. The transformers learned in-distribution r-trivial and aperiodic tasks but did not generalize perfectly beyond the training range. The transformer using rotary position embeddings extended to roughly 10 times the training length before degrading, while the version without positional embeddings degraded immediately after the cutoff.
None of the tested architecture families generalized perfectly on the hardest, general finite level. The authors found that transformers did not completely learn that task even within the training distribution. Both Gated DeltaNet variants learned it in distribution, but only the variant allowing positive and negative eigenvalues reached roughly 10 times the training length before degrading; the positive-only variant degraded immediately beyond the training cutoff. These results are the authors’ benchmark findings and have not been independently replicated in the opened sources.
The benchmark also exposed a gap between targeted training and pretrained systems. According to the paper, pretrained open models generally performed strongly on r-trivial tasks, declined on longer aperiodic tasks and remained at chance on general finite tasks at every tested length. Results also varied substantially with surface format. Four tested frontier models performed strongly on r-trivial and aperiodic problems but fell to chance accuracy on soluble and general finite problems as inputs reached between 10,000 and 64,000 tokens.
StateBench currently assumes a fixed number of variables, so it does not cover settings in which new entities appear during a document. The paper also leaves open the exact theoretical position of positive-eigenvalue Gated DeltaNet above the aperiodic level. The Allen Institute for AI publishes StateBench’s code and hosts its dataset alongside the report.
More news
Ai2 releases XYBench to test how assistants handle mistaken premises
Apple researchers propose two-stage Attention-to-Mamba distillation
Apple study finds MMLU weakly tracks LLM judge quality