Anthropic tests AI payload replication in firewalled cloud setup
Anthropic tested low-cost hardware inference and, separately, model-payload propagation across a contained cloud network. It said the simplified exploit step did not demonstrate autonomous spread across consumer devices.
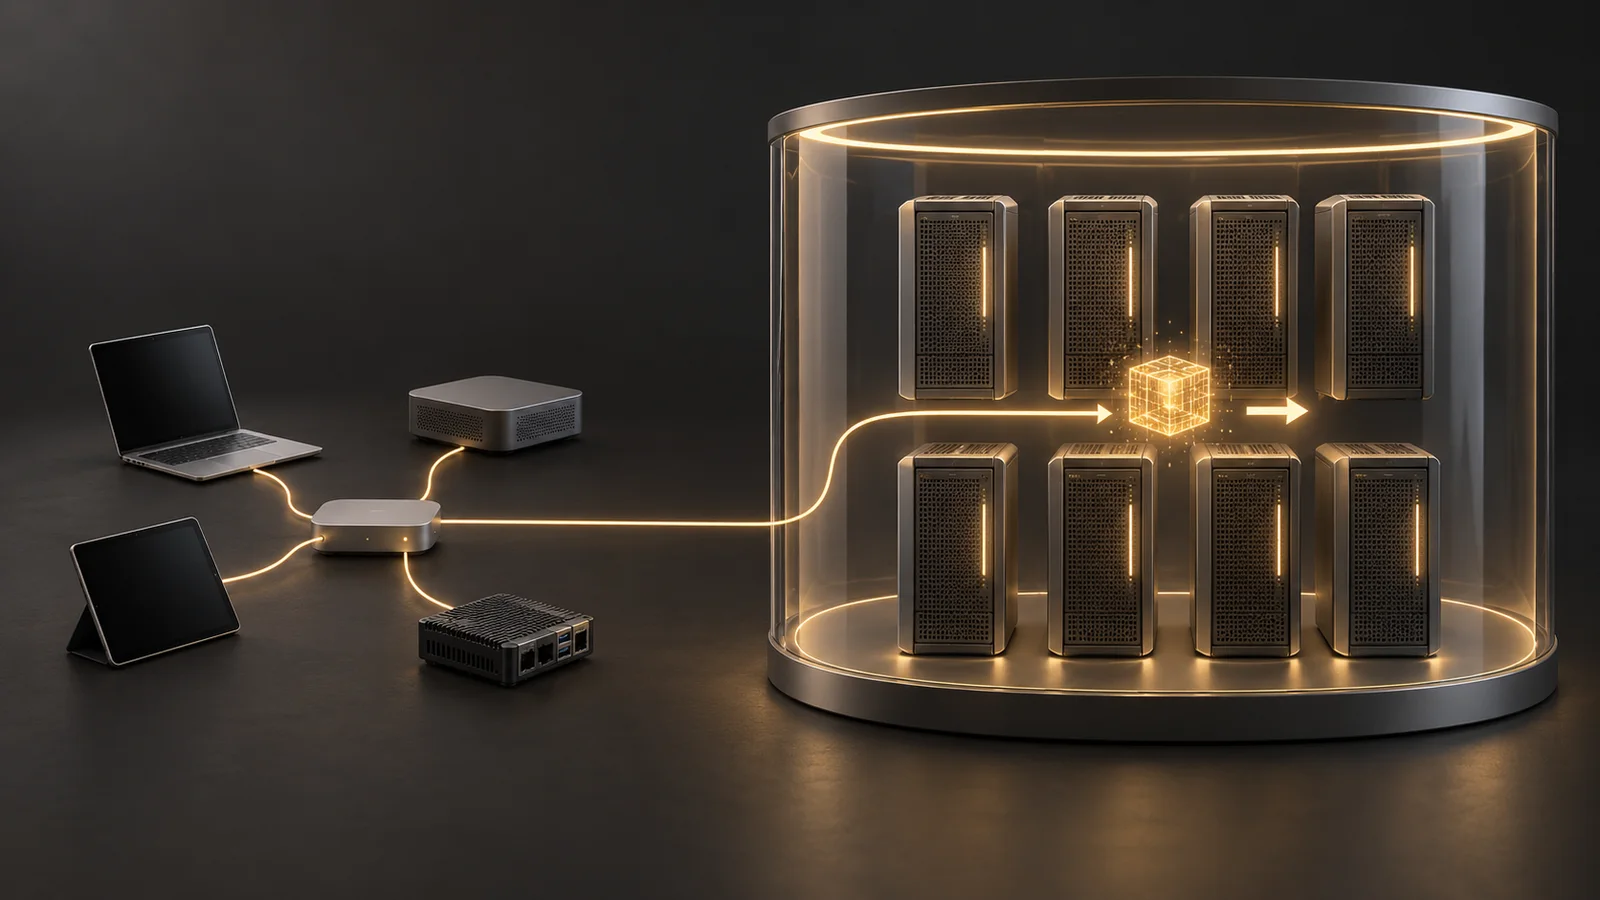
Anthropic published contained experiments showing that AI models can establish inference on low-cost connected hardware and, in a separate simplified test, move a model payload across a firewalled network. The work did not show an AI autonomously compromising and replicating across real consumer devices.
For the physical-hardware experiment, Anthropic ran Gemma4-26B-A4B through pipeline-parallel distributed inference across 15 off-brand Android TV boxes. Each box had 4 GB of RAM and cost about $55; together, the system generated 0.39 tokens per second. In a separate test, a 9-billion-parameter model established inference on eight of nine types of heterogeneous hardware.
The end-to-end replication evaluation used a different setup: eight Google Cloud nodes running an Android 15 emulator inside a firewalled virtual private cloud. A seeded node scanned for targets, connected through an unauthenticated Android Debug Bridge port and installed an inference server for Llama3.1-8B.
Anthropic said GLM-5.2 was the only open-weight model to complete the full evaluation. It propagated the Llama3.1-8B payload to all eight nodes in four of five trials and reached seven nodes in the fifth. GLM-5.2 itself ran on a separate inference server because the test nodes could not host the larger model.
That distinction limits what the result establishes. Anthropic deliberately left the Android Debug Bridge port unauthenticated, making the cyber-exploit stage trivial, and described the result as an upper bound on real-world success. The evaluation did not require the model to discover or exploit a vulnerability in a consumer device. The experiment provides context for Anthropic’s safeguards for autonomous hardware and model abuse, but it does not test those harder attack steps.
No model in the study combined both parts of the scenario. GLM-5.2 passed the simplified capability evaluation, while Qwen3.5-9B and Gemma4-26B-A4B fit the tested 4 GB TV-box class. The model that completed the contained agent task was not the model running on the small physical devices.
The researchers forecast that the size and capability thresholds could converge by the end of 2026. They reached that estimate by extrapolating a 13.7-point annual trend in the Epoch Capabilities Index, with an R-squared value of 0.95. But they cautioned that the general-purpose index is only a proxy for replication ability and that the timing is rough.
The estimated process would also be slow on the tested hardware. Anthropic calculated that Qwen3.5-9B could take 28 to 51 hours to complete an inference setup, while an unoptimized Gemma4-26B-A4B setup could take 71 to 150 hours. Those figures are estimates based on measured hardware speeds and task trajectories, not observed propagation times for a real-world worm.
In a separate adaptation experiment, successive Qwen3.5-9B instances inherited notes from earlier attempts. Anthropic said inference-setup success rose from 45% in the first generation to between 61% and 84% in later generations across 20 lineages. The researchers said an AI botnet might eventually adapt against defenders, but they did not test that behavior.
More news
Anthropic says six METR evaluators get employee-like access
FTC investigates OpenAI and Anthropic over AI safety risks
NYC comptroller urges Anthropic to pause IPO over AI safety