Apple study measures losses when language models serialize structured reasoning
Apple researchers tested how well language models preserve tree-structured expressions when one model turns them into text and another reconstructs them.
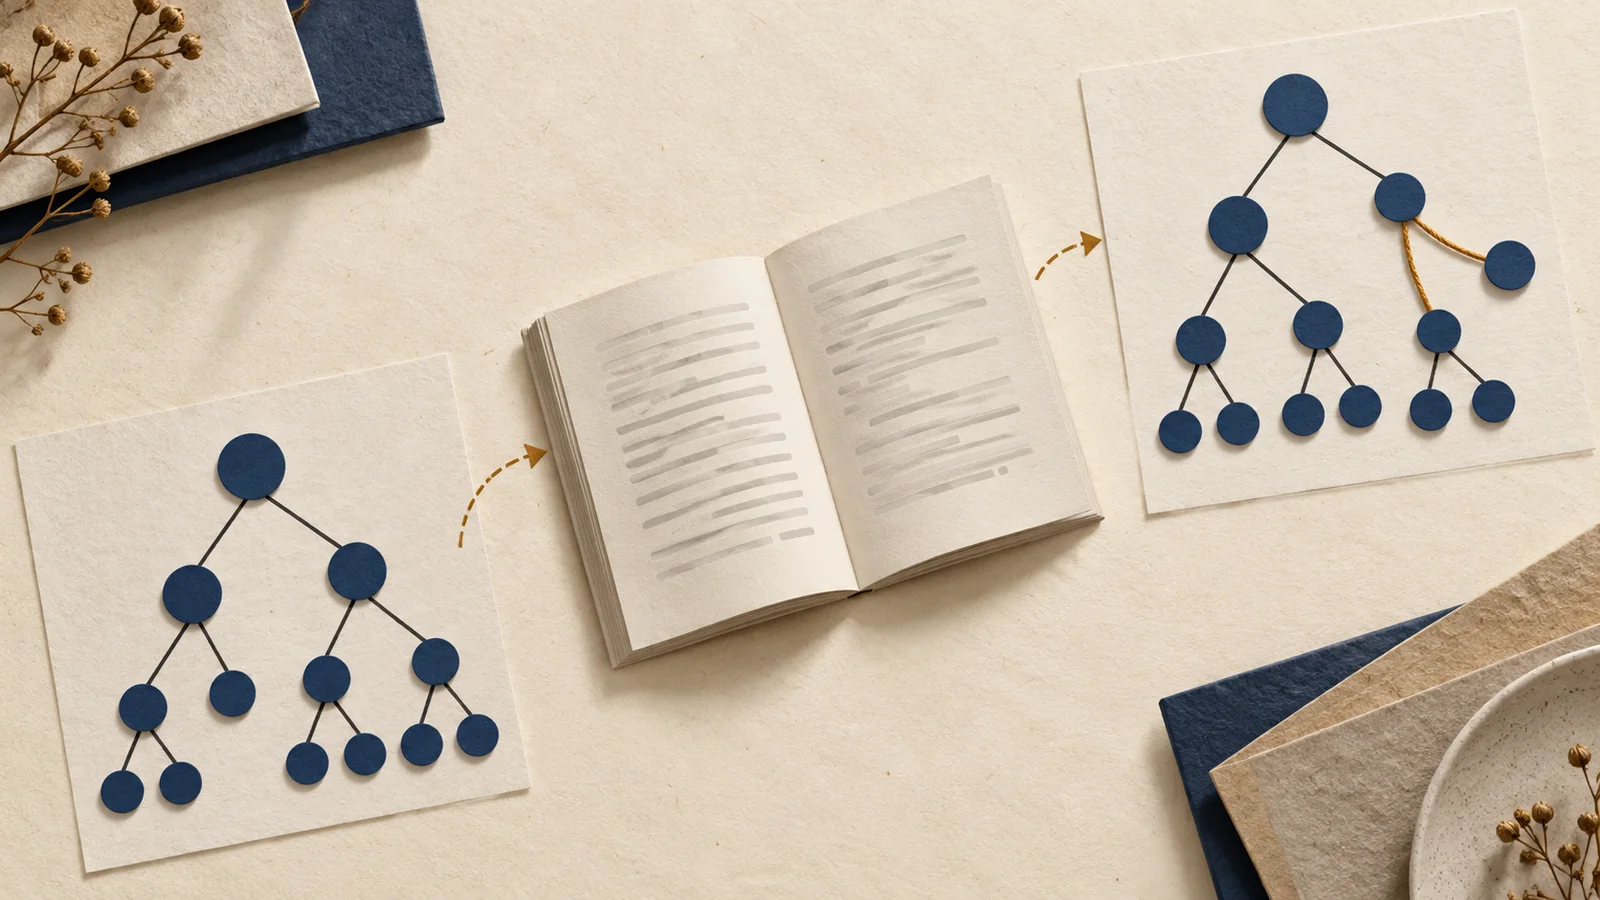
Apple researchers have published a study measuring how much tree-structured information survives when language models convert structured reasoning into natural language and another model reconstructs it. The authors tested 16 models and report that the best generator-extractor pairing recovered the original expression with 92.9% accuracy.
The study examines a communication bottleneck in workflows where models exchange free-text intermediates, including model-to-model systems and chain-of-thought-style reasoning. The authors report that reversing which model wrote the text and which model decoded it changed round-trip accuracy by as much as 60.4 percentage points. In their results, performance depended strongly on which model served in each role.
In the round-trip protocol, a generator turned a procedurally created arithmetic expression tree into a word problem. A separate extractor then tried to recover the expression from the word problem alone. The researchers used symbolic equivalence—checking whether two expressions have the same mathematical meaning—as an exact test, so wording differences did not count as failures when the underlying expression was preserved.
The authors tested every generator-extractor pairing across the 16-model set. From the resulting communication matrix, they estimated generation and extraction quality separately. They attribute at least 73.6% of observed round-trip failures to the generation stage. They also report that difficulty followed structural features such as operator count, tree depth and right-branching rather than model family.
The researchers further report that about 3,600 fine-tuning examples using the evaluation’s operators and tree shapes lifted every tested open-weight model above an untrained Gemini-3.1-Pro baseline under matched semantics. Training on a disjoint domain with new operators and vocabulary also improved every tested open-weight model, although those models still trailed the frontier models in the study.
The measurements come from procedurally generated arithmetic expression trees. The sources do not establish the same loss rate for arbitrary production agent messages or private chain-of-thought traces, and the research package records no independent replication or external audit of the reported results.
More news
Scale AI sets out Google Cloud architecture for enterprise agents
Deloitte UK profit rises 14% as firm cites AI advisory demand
Snowflake adds CoCo DDL workflow to Dynamic Tables Insights