Apple researchers turn idle Macs into a distributed GPU cloud
Apple's Minions pools idle Apple Silicon GPUs for distributed machine-learning inference, though the paper leaves its main performance and cost claims unquantified.
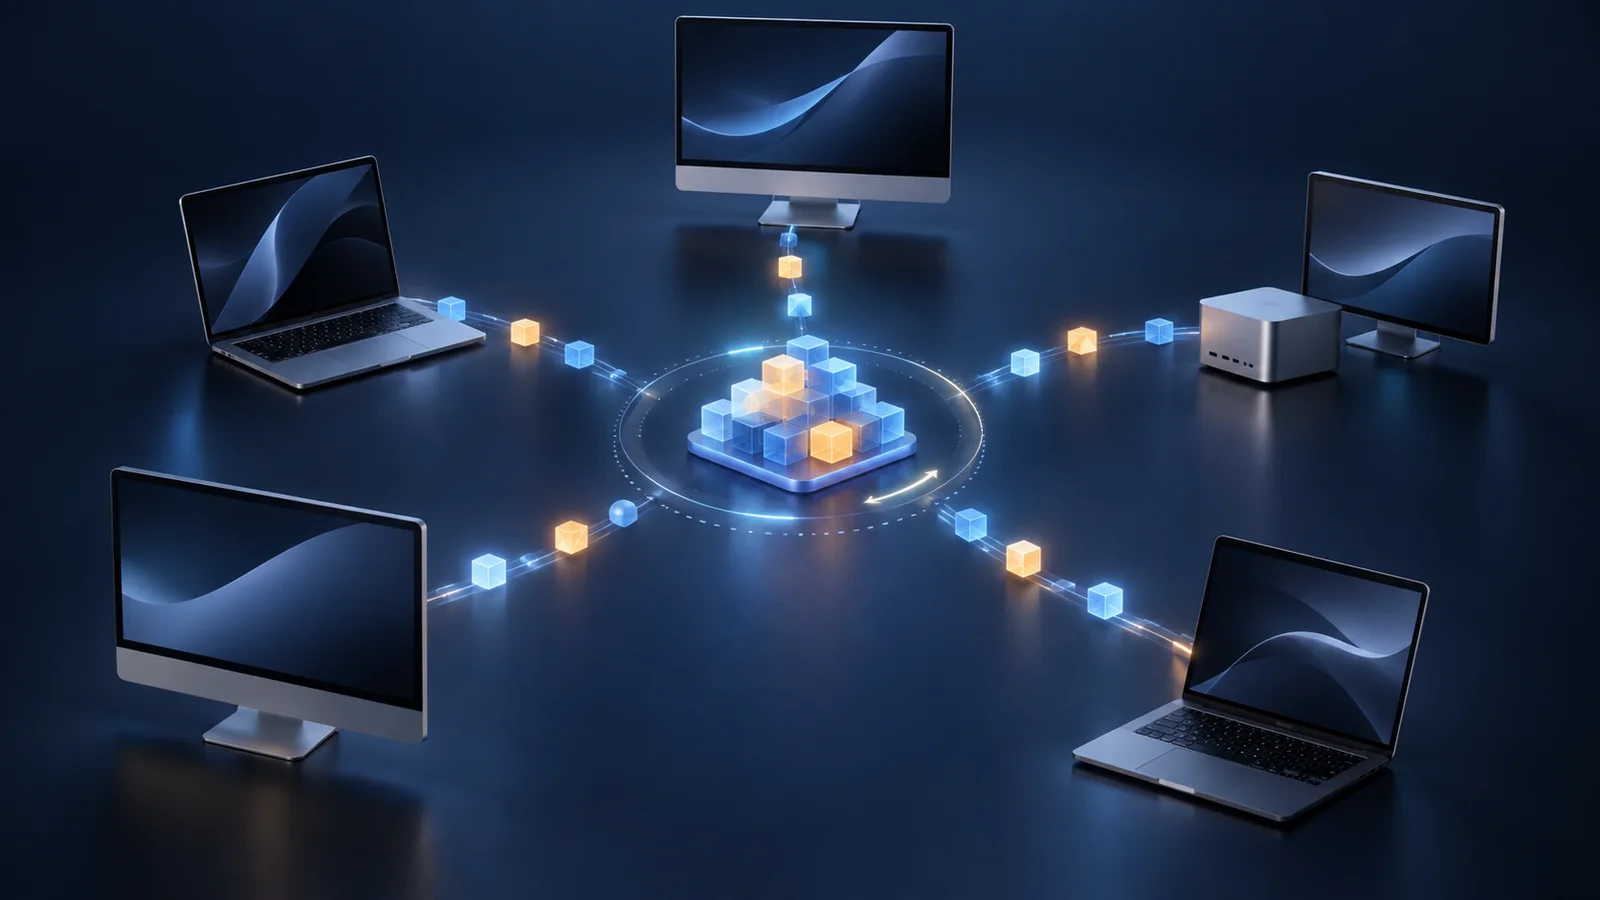
Apple researchers have presented Minions, a system that combines idle Apple Silicon GPUs across macOS devices into a virtual cloud for machine-learning inference.
The authors position the pool as another source of compute when centralized GPUs are constrained. In their paper, they report that some jobs previously waited more than 10 hours for centralized GPUs, while Minions often starts tasks within minutes. The paper gives no sample size, workload distribution or controlled comparison for that claim.
Four main components make up Minions: a server, a PostgreSQL metadata store, executors running on Apple Silicon Macs and a watchdog. The server validates submitted jobs, divides them into subtasks asynchronously and stores their metadata. Executors poll REST endpoints, claim eligible work, fetch inputs from object storage, run inference on the local GPU, upload results and report status. They do not connect directly to PostgreSQL.
There is no central scheduler. When multiple executors seek the same subtask, each tries to insert an ownership record protected by a multicolumn PostgreSQL unique constraint; only one insert succeeds. PostgreSQL documents that such constraints reject duplicate value combinations. Jobs otherwise use first-in, first-out ordering, although device owners can set preferences for particular teams, projects or tasks.
The authors treat interruptions as routine: a Mac may lose its network connection, go to sleep, power off or have its executor stopped. Executors send heartbeats every five minutes. If the watchdog finds an executor with active work is unresponsive, it returns the unfinished subtask to the queue for another device. The paper reports no controlled fault-injection tests, recovery-time measurements, retry limits or analysis of duplicate results.
The current implementation supports embedding generation with Hugging Face transformer models and large-language-model completion through Ollama. Ollama’s macOS requirements confirm GPU acceleration on Apple M-series Macs, while x86 Macs are CPU-only. Minions uses Amazon S3 for inputs and outputs and derives Grafana monitoring data from PostgreSQL. For readers following Apple’s systems work, its study of minimal coding-agent harnesses offers adjacent context; Minions focuses on the compute layer for inference.
The researchers characterize new GPU purchases as unnecessary, infrastructure cost as zero and scaling as organic. Those are the paper’s operational claims, not a full cost accounting: it does not quantify electricity, storage, networking, administration or device depreciation. The authors also say Apple Silicon GPUs are largely idle in normal use and that Minions raises utilization, but provide neither baseline idle measurements nor before-and-after utilization rates.
The authors say Minions has supported inference work across multiple teams, but do not disclose the fleet size, Mac models, number of participating devices, deployment duration, model sizes, throughput or comparative benchmarks. They also identify confidentiality as a concern when devices sit outside a team’s immediate organization. Their proposed controls are dedicated PostgreSQL databases and isolated executor pools, but the paper does not describe protections against untrusted devices. Minions currently targets inference; distributed model training appears only as future work.
More news
Apple adds MLX distributed inference across Mac Studio systems
Apple launches M6 and M5 Pro Mac mini for local AI workloads
Apple reportedly tests China's CXMT memory chips to ease AI-driven DRAM shortage