Apple researchers swap free-form agent reasoning for candidate selection
Apple-affiliated researchers say parallel scoring of reusable reasoning candidates sharply cut wall-clock latency for small multimodal search agents in seven-benchmark tests.
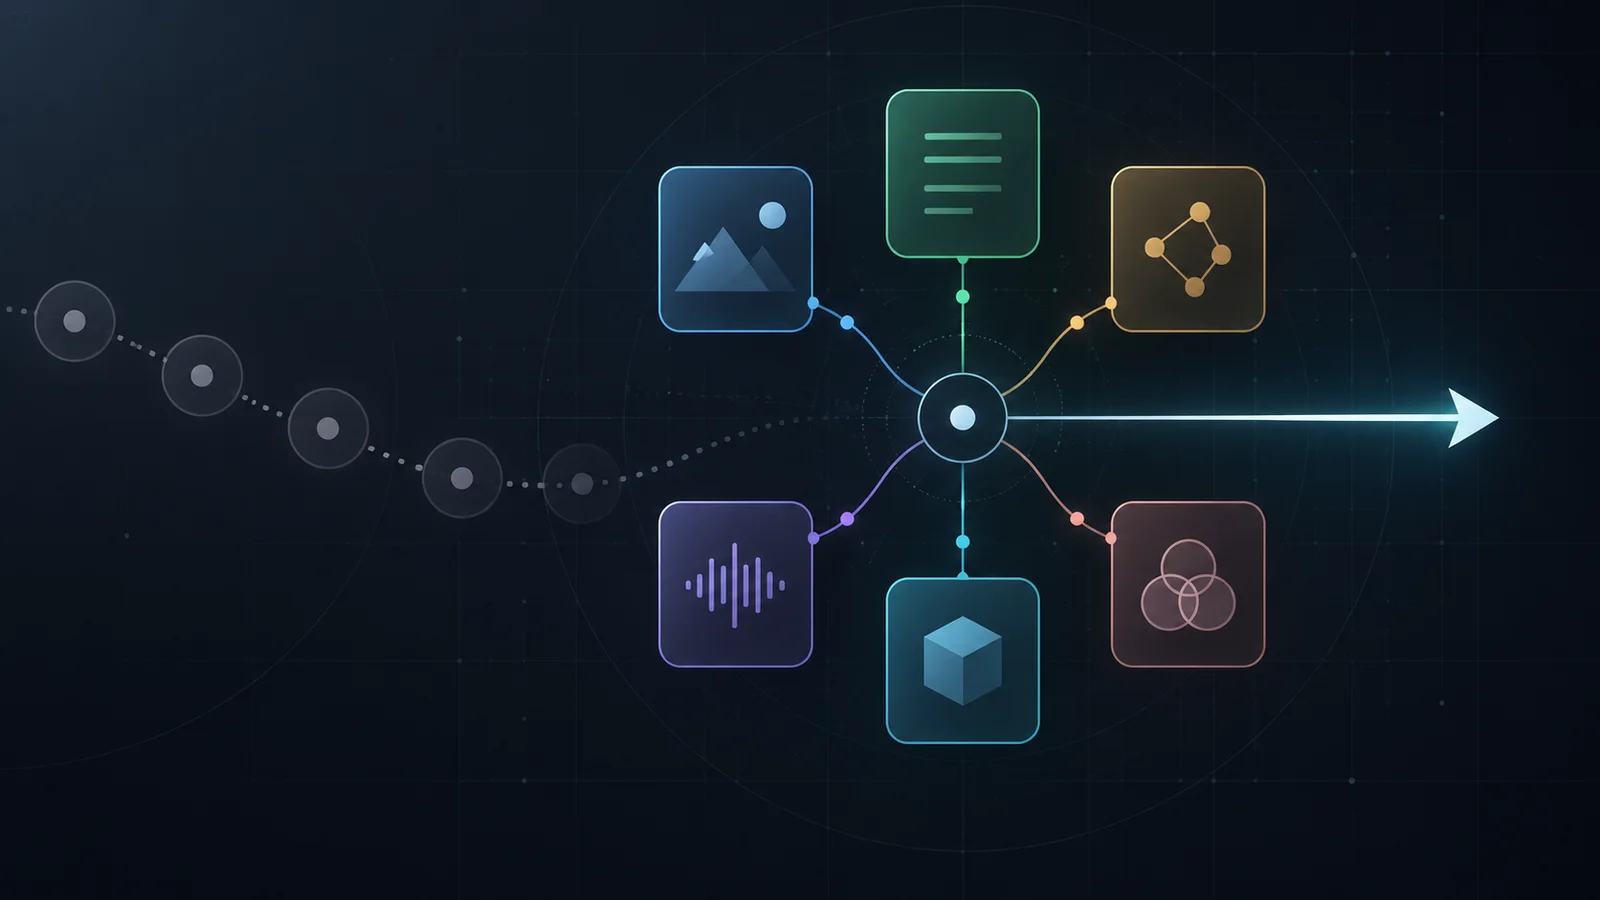
Apple-affiliated researchers introduced Selection-Based Structured Reasoning, a framework that lets small multimodal search agents choose from reusable reasoning candidates instead of generating a new free-form trace before every action.
In the authors’ tests, the change reduced mean per-turn reasoning latency by 91.9% to 94.6% and mean model latency per question by 28.7% to 53.9% across paired 4-billion-parameter configurations. These are researcher-reported measurements from one NVIDIA H100 running an offline SGLang inference engine. The per-question metric excludes tool execution and evaluation by an LLM judge.
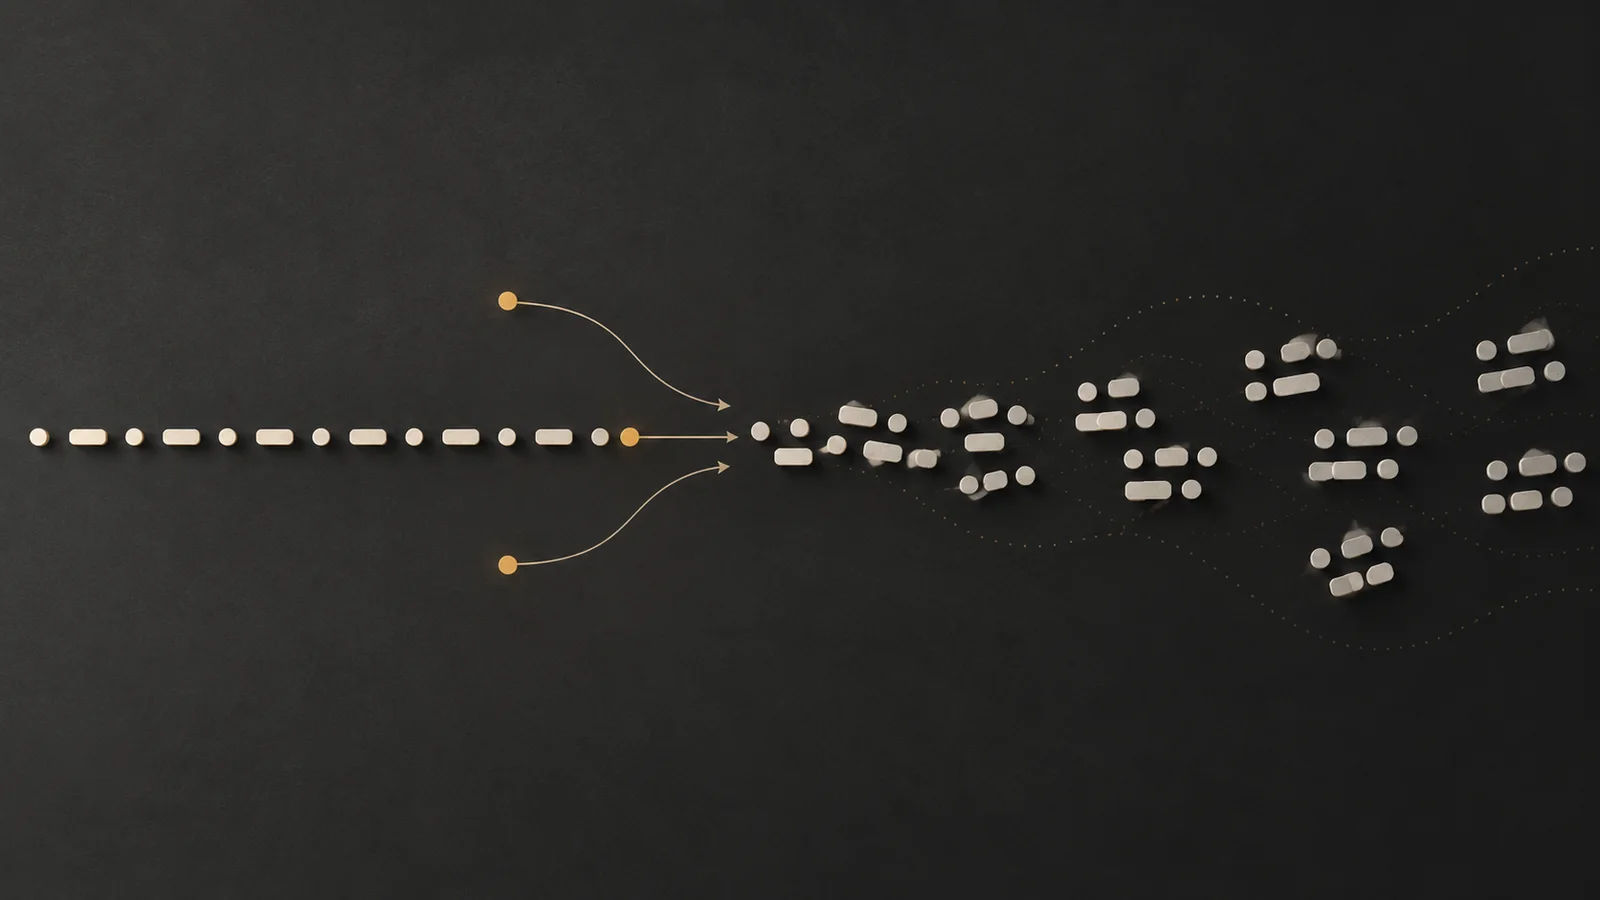
The method changes the shape of the reasoning step. At each turn, the same language model assigns every prewritten candidate a length-normalized likelihood based on the interaction history. Since the candidate text is already known, teacher-forced prefilling can score tokens within each candidate concurrently. Candidates can also be scored concurrently while reusing a cache of the interaction history.
The harness inserts the selected text into the context, then the model generates the specific next action — such as a search query, image crop or final answer — token by token. This removes the sequential dependency created when a model must generate an entire reasoning trace before it can act.
That does not guarantee less total computation. The paper’s cost analysis says the system scores all candidate tokens, while compute and candidate-cache storage increase with the library’s total token count. The method is faster only when parallel scoring throughput is high enough relative to autoregressive decoding after accounting for runtime overhead.
The experiments used a fixed library of six manually written candidates across seven multimodal search benchmarks. They covered image search, text search, image inspection, answering from gathered evidence, answering from the image and answering from general knowledge. The researchers evaluated Qwen3-VL models with 2 billion and 4 billion parameters using a common harness for reverse-image search, text search and image cropping.
Results varied by training objective. The authors reported that a 4B SSR model trained with GRPO averaged 61.37% success across the seven benchmarks, compared with 58.65% for its paired free-form GRPO model and 61.25% for the strongest trained 4B baseline in the paper’s comparison table. SSR also improved the paired 2B GRPO result and essentially matched free-form supervised fine-tuning. It trailed free-form reasoning under the GSPO and SAPO objectives, however, so the paper does not show an across-the-board accuracy gain.
SSR targets inference-time action selection, a different problem from work that turns failed agent attempts into training insights for later rollouts and model updates. For the latency profile, the researchers sampled 100 questions from each benchmark and counted model-side prefill, reasoning, action generation and other inference across each trajectory.
The opened records identify the work as an arXiv paper. They do not establish independent replication or peer review, or show whether the reported reductions extend to other accelerators, inference engines, larger models, larger candidate libraries or production workloads.
More news
Apple study finds English data mixing outpaced extra tuning in constrained Arabic pre-training
Apple study finds LLM translation grading unreliable in most settings
Apple study finds LLM conditioning gains can reduce fluency