Apple researchers propose weighted state souping for long-context retrieval
Apple researchers proposed query-dependent weighting for cached state-space-model encodings, aiming to preserve reusable context as retrieval deteriorates across growing document and tool collections.
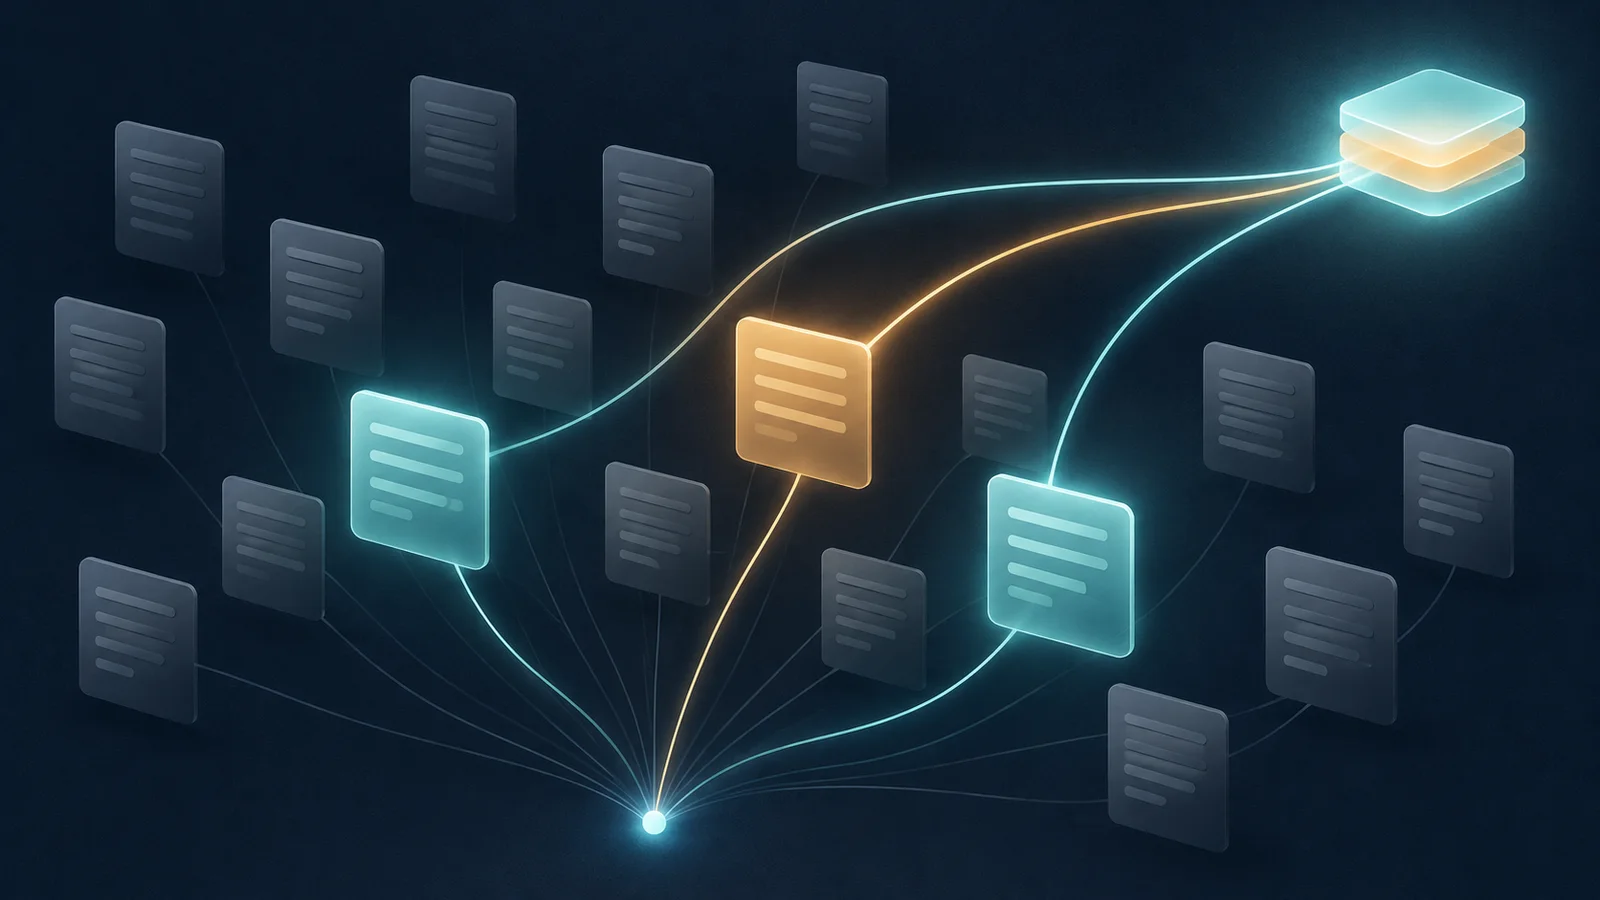
Apple researchers have proposed weighted state souping, a method meant to preserve reusable, precomputed state-space-model representations while limiting the retrieval decline seen in crowded long contexts.
The paper builds on state souping, which stores the internal states created when a recurrent model encodes separate chunks. Rather than average every cached state equally, the new method derives a key from each chunk and a vector from the user’s query, then initializes the model with a softmax-weighted combination of those states. Each chunk gets one scalar weight, shared across layers and heads, that remains fixed while the model processes the query and generates an answer.
The authors tested 1.5-billion-parameter Mamba-2 models with mean, weighted and sparse souping against sequential Mamba-2 and a parameter-matched Transformer. The evaluations covered document question answering, RULER retrieval and variable-tracking tasks, and tool-use tests based on the Berkeley Function Calling Leaderboard.
According to the paper, weighted souping maintained roughly stable performance as document or tool pools grew to 128 chunks, despite training on pools of no more than 24. For RULER, the authors capped training contexts at 2,048 tokens and evaluated lengths from 1,000 to 128,000 tokens, reporting robust results beyond the training length. The sources reviewed do not include an independent replication, and the paper presents task-specific curves rather than a single aggregate accuracy improvement.
A sparse version retains only the highest-scoring chunks before applying softmax. The experiments used the top four chunks for document question answering and tool-use tests, and the top 20 for RULER. The authors reported that sparse souping matched or improved on the full weighted method in their tests, particularly on HotpotQA and MuSiQue. They also warned that a cutoff set too low can remove information needed to answer a question.
The efficiency case hinges on where cached states are stored. The paper reports that sparse-soup encoding time can stay effectively constant as context grows when the number of fetched states remains fixed, though scoring still grows linearly with the number of chunks. Each cached state in the tested Mamba-2 setup occupied 33.6 MB in bfloat16. Moving states from system memory or disk can narrow the advantage, and the authors say retrieval can be slower than re-encoding in the worst case.
The method requires training or additional fine-tuning; it is not an inference-only change. It is also sensitive to chunk boundaries, while independently encoded chunks cannot form cross-chunk representations during encoding. Apple says the work was accepted at the NeurIPS 2026 workshop on personalized, aligned and long-term memory for AI systems. The sources reviewed do not describe a product release or deployment.
More news
Apple study finds stronger gating can slow in-context learning in Mamba
Apple researchers propose two-stage Attention-to-Mamba distillation
Apple researchers derive a theoretical ceiling for KL-regularized model alignment