Cohere introduces RCP-nDCG@10 retrieval metric
Cohere's RCP-nDCG@10 combines rubric judgments, pairwise preferences and cross-query calibration to address gaps in conventional relevance labels.
Cohere introduced RCP-nDCG@10, a method for evaluating enterprise retrieval systems when benchmark relevance labels are incomplete. The company says it used the metric instead of traditional normalized discounted cumulative gain to optimize its fifth-generation Embed and Rerank models.
Conventional nDCG treats documents missing from the original relevance judgments, known as qrels, as having no gain—even when they may answer the query. A retrieval system can therefore get no credit for surfacing relevant material outside a benchmark’s labeled set. The work covers the same enterprise-search field as Cohere’s Compass Cloud managed retrieval platform.
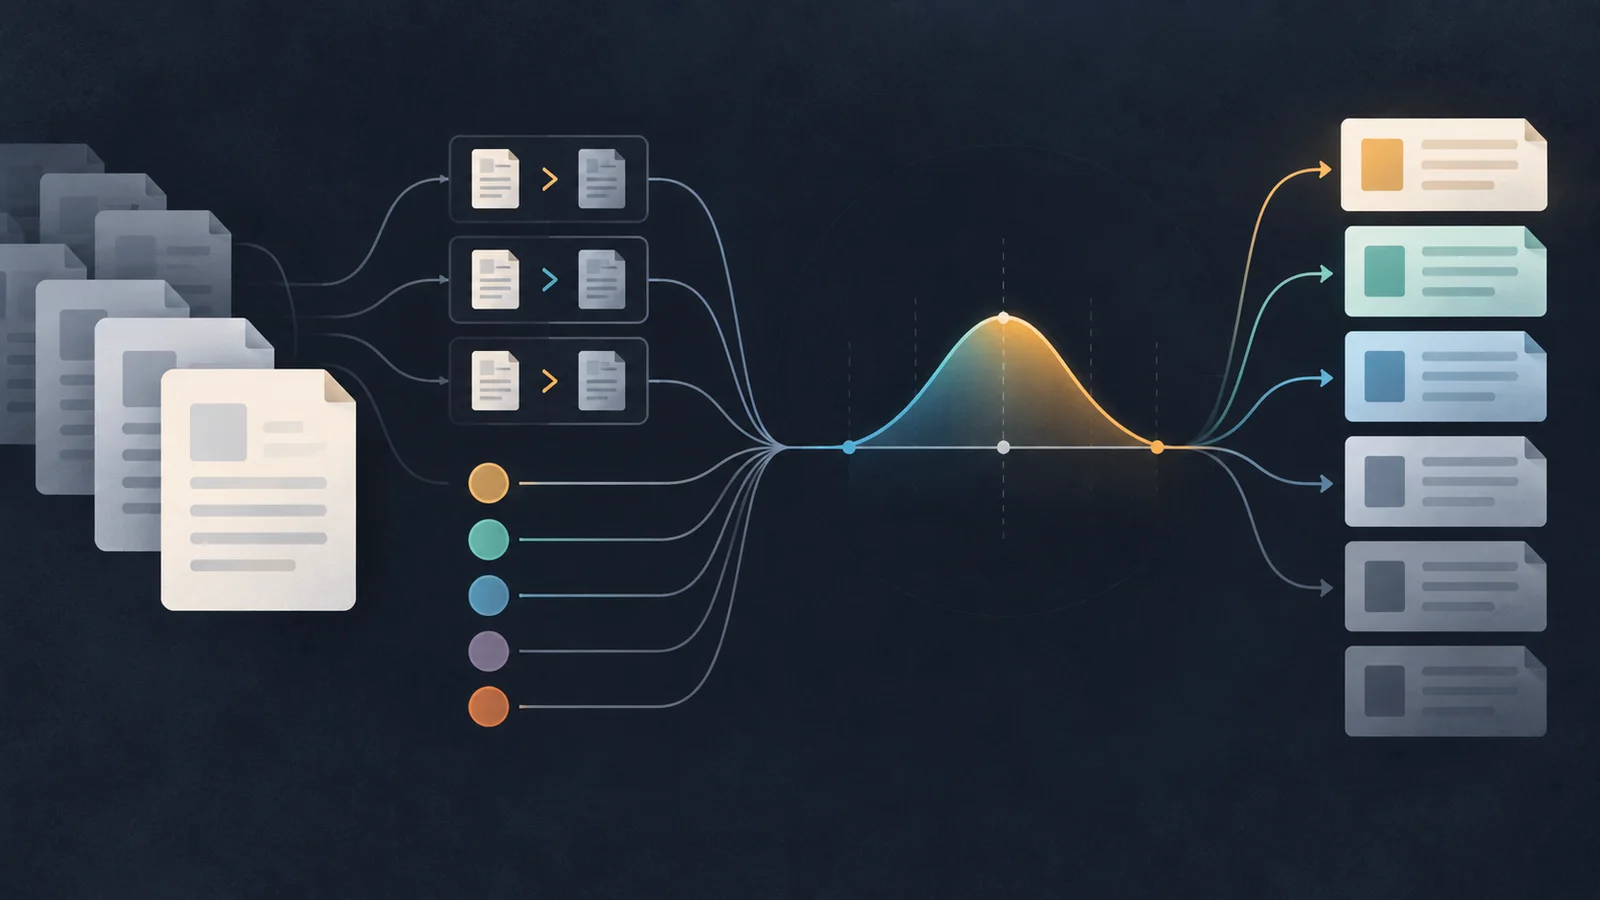
RCP, short for Rubric-Calibrated Preferences, combines two signals from a large-language-model judge. A listwise Bradley-Terry tournament orders documents within each query. Five yes-or-no rubric criteria, arranged from less to more stringent, provide an absolute relevance standard. The Cohere-authored paper says a two-parameter item-response model maps those query-level tournament results onto a common scale. RCP-nDCG then uses the calibrated relevance probabilities instead of conventional nDCG’s discrete gains.
A benchmark’s candidate pool needs to be labeled once, according to the paper. Rerankers can then reorder and score that pool without additional judge calls. Introducing documents from outside the pool requires new judgments and a fresh calibration fit, and scores can be compared only within a single fit.
For validation, Cohere ran a blind study with 46 external annotators and 311 contests across 292 distinct queries. Three annotators reviewed each contest, yielding 7,080 grades for 2,268 distinct documents; 22 contests ended without a verdict. The study used selected tasks from NanoBEIR, BRIGHT and English-language ViDoRe v3 corpora. It oversampled cases where RCP-nDCG and qrel-based nDCG disagreed and showed reviewers a randomized union of two systems’ top five results.
Cohere says reviewers favored the system chosen by RCP-nDCG in 70% of cases where the two metrics picked different winners. The paper gives a narrower result for 185 contests in which exactly one metric matched annotators’ preferred reranker: RCP-nDCG was the matching metric 72.4% of the time, compared with an estimated chance level of about 53%.
The authors report that RCP gains separated a human-rated useful document from a non-useful one with an area under the curve of 0.910, versus 0.651 for benchmark qrels. On NanoBEIR, RCP-nDCG significantly separated an average of 63.5% of 91 reranker pairs, compared with 34.1% for qrel-based nDCG, using paired tests at the 5% level, according to the paper. These findings come from a Cohere-authored arXiv v1 preprint; the supplied research does not establish peer review or independent replication.
The paper also describes several limits. RCP-nDCG does not penalize redundant results or assess factual correctness, and its human comparison counted score differences below 0.02 at depth five as ties. The authors caution that models trained with RCP feedback should be tested against other labels because the metric could favor its own training signal.
Cohere released an Apache-2.0-licensed repository containing the library, command-line tool, examples, reproduction scripts and links to the public datasets used in the paper.
More news
Metaview raises $60 million Series C to grow recruiting agents
Databricks launches ai_decide beta for governed AI decisions
Apple study finds LLM conditioning gains can reduce fluency