Dharma AI releases 2B document field extractor
Dharma AI’s 2-billion-parameter Field Extractor turns document images into structured JSON in open or schema-directed mode.
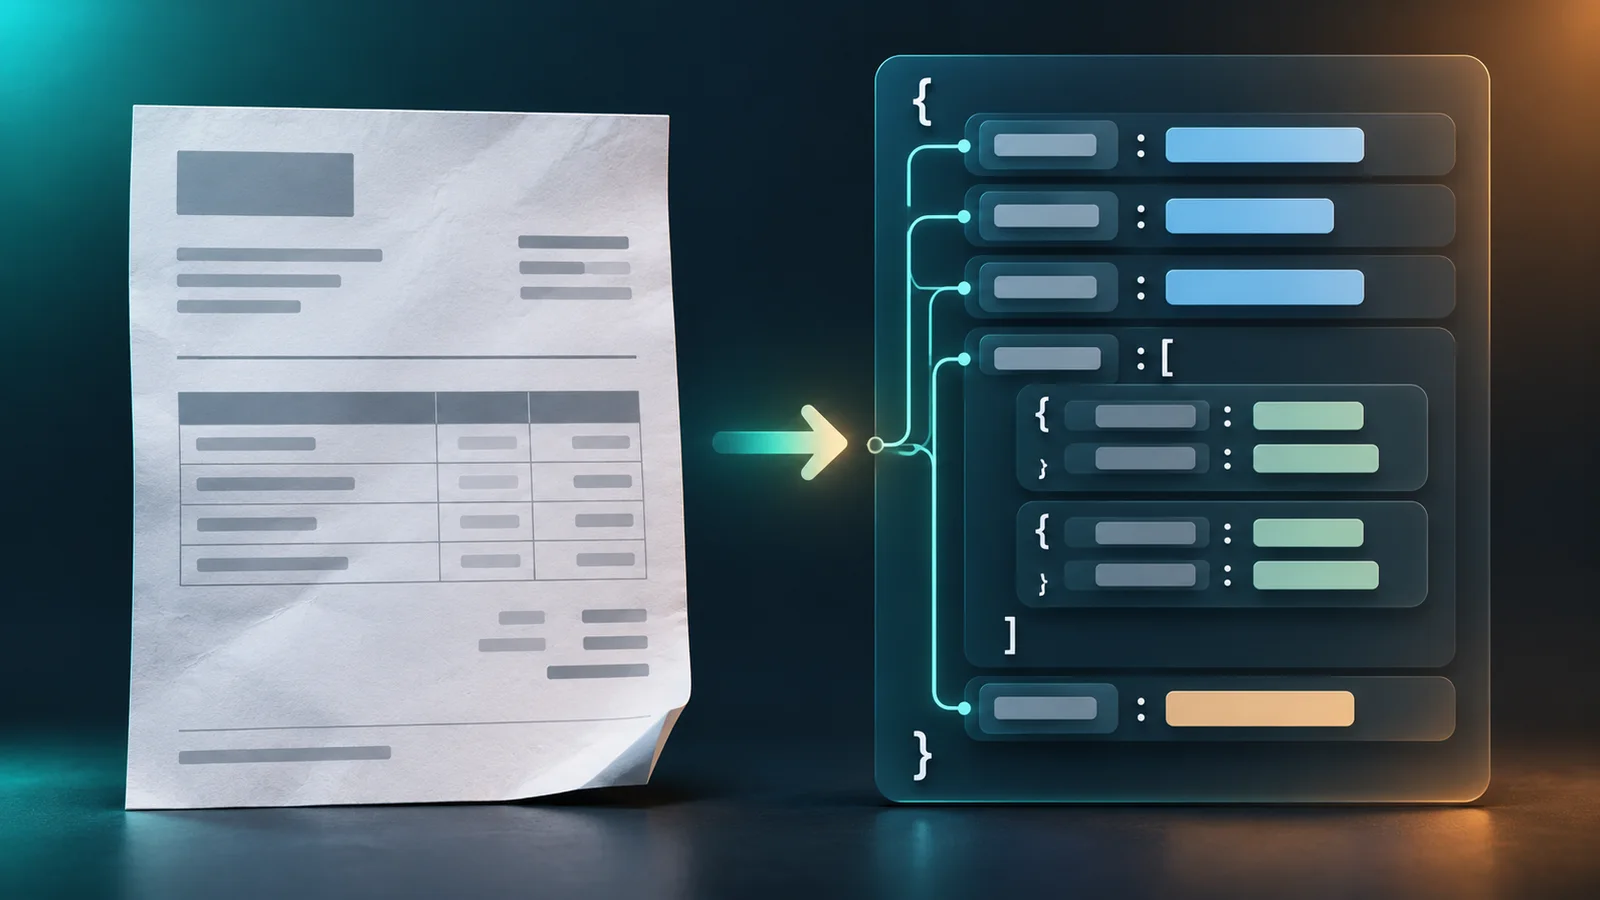
Dharma AI released a 2-billion-parameter document model that extracts requested fields from images and returns structured JSON. The company positions Field Extractor for repeated, high-volume work that moves information from invoices, forms, identity documents and other records into operational systems, without fine-tuning a separate model for each document type.
Field Extractor supports open and schema-directed extraction. Open mode requires no predefined field list. Dharma AI says the model uses page context and layout to identify structured content and return key-value pairs, making the mode suitable when a document’s contents are not known in advance.
Schema-directed mode is for systems that already expect a particular data shape. Users supply exact key names and assign string, number or boolean types. According to Dharma AI, the model retains those keys, fills tables row by row, omits extra fields and returns null when a requested value is absent. The company says this typed JSON can reduce the custom mapping between document extraction and a downstream database or application.
The target workflows include supplier invoices feeding business systems, medical requisitions feeding schedulers, contracts feeding compliance systems and identity-document fields feeding employee records. Dharma AI says one checkpoint can process invoices, forms, bank statements, IDs and receipts without document-type-specific fine-tuning.
The company describes Field Extractor as a LoRA adapter trained on 43,384 examples over DharmaOCR-LITE v1.1, a 2-billion-parameter base previously specialized for optical character recognition. The training mix included English public-web documents from multiple domains, internally sourced Brazilian documents in Portuguese and a smaller multilingual portion covering other European and Asian languages.
For its benchmark, Dharma AI tested 546 documents in three conditions: open extraction, a partial schema containing real fields and a schema that also requested nonexistent fields. The company scored the 1,638 cases by multiplying field-level F1 for path-matched fields, Levenshtein similarity for matched values and the share of outputs that were valid JSON.
Dharma AI reported a score of 0.834 for Field Extractor, compared with 0.816 for the closest tested frontier configuration, Claude Opus 5, and 0.741 for GPT-5.6 Luna. The results have not been independently replicated. The company also said its run cost about six to 147 times less than the frontier APIs it tested, based on measured API tokens and published list prices versus one L40S GPU priced at $2.24 an hour. Dharma AI cautioned that the GPU calculation was not a sales price and that deployment costs vary with hardware, volume and latency requirements.
The release did not provide per-scenario scores, confidence intervals, throughput or latency. It said the public SROIE and FUNSD datasets were included in the benchmark but excluded from training. An earlier DharmaOCR paper covered separate 3-billion- and 7-billion-parameter OCR models and does not independently validate the new benchmark. As observed on Nov. 14, Dharma AI’s Hugging Face organization page listed only the Dharma-OCR-LITE repository; the release did not link a separate downloadable Field Extractor checkpoint or state its license.
More news
Google opens Tabletop collaboration experiment via U.S. waitlist
Adobe expands removal tools across Photoshop, Premiere and Lightroom
Google opens Antigravity teamwork tools to external researchers