Google Research introduces multi-agent frameworks for coherent long-form video
Google Research introduced four multi-agent frameworks that combine planning, visual memory, segment generation and prompt refinement to limit drift across multi-shot AI video.
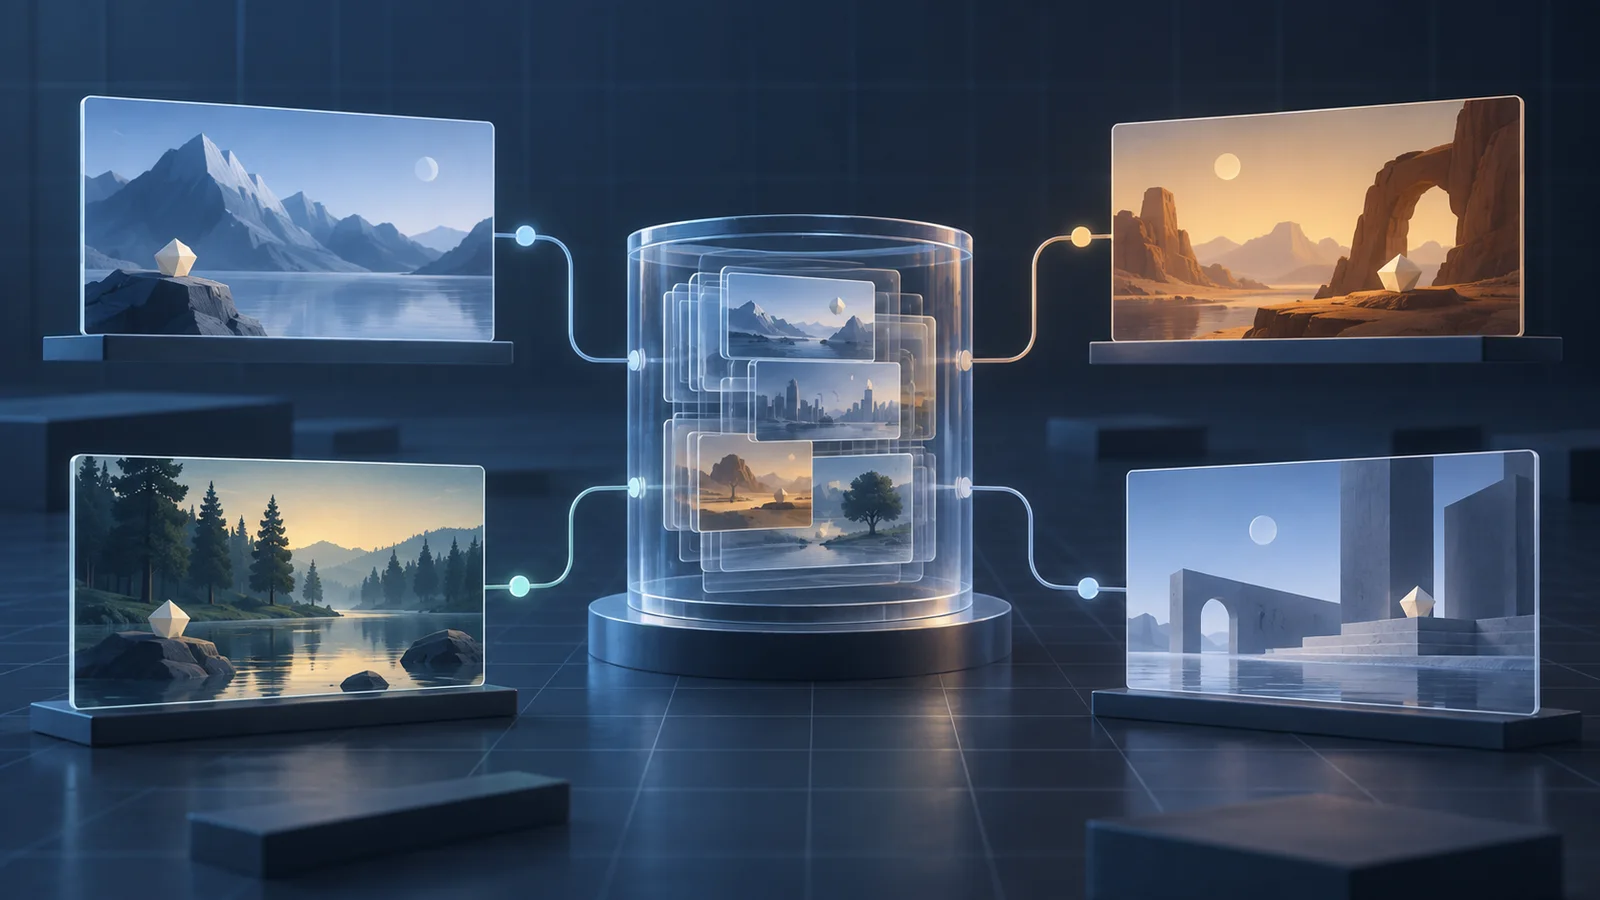
Google Research introduced four multi-agent research frameworks on September 24 to reduce character, scene and narrative drift across multi-shot AI video. The systems turn long-form generation into a sequence of coordinated planning, memory, generation and evaluation steps rather than one extended generation request.
The suite comprises Co-Director, CANVAS, A²RD and VQQA. Google presented them as research systems, not generally available products. The associated A²RD experiments cover videos from one to 10 minutes, and Google’s post includes a researcher-selected 10-minute demonstration. Neither the demonstration nor the papers’ benchmark results independently validates reliability in production.
A plan above individual shots
Co-Director treats video storytelling as a global optimization task. A multi-armed bandit — an algorithm that balances testing new options against reusing promising ones — chooses among combinations of creative strategy, narrative mode and visual style. Those choices steer agents that build a storyline and storyboard, generate keyframes, video and audio, and assemble the result. A multimodal model scores the completed video and returns a factored reward to the planning layer for another iteration.
The top-level loop is designed to catch errors that could propagate through a linear production pipeline. Co-Director also applies narrower feedback loops to storylines and keyframes before final assembly. Google Research has separately explored agentic workflows for answer-first tool-use data generation.
A memory for the narrative world
CANVAS handles continuity at the storyboard level. It stores representations of characters, locations and object states in persistent visual memory, retrieves earlier visual anchors when those elements return, and updates the memory as the story advances. The process is intended to keep a recurring character, room or prop consistent, or reflect a specific story-driven change, after intervening scenes.
A²RD extends state tracking into segment-by-segment video generation. Its retrieve-synthesize-refine-update loop consults multimodal memory, produces the next segment, evaluates frames and motion, and writes the result back to memory. It can switch between extrapolation, which advances the action, and interpolation, which anchors a new segment to established entities and environments.
VQQA provides a separate refinement mechanism. It generates questions about whether a video satisfies its prompt, uses a vision-language model’s answers as natural-language feedback, and rewrites the prompt before generating another candidate. A global rater compares candidates with the original request and selects the highest-scoring output. The process changes prompts rather than editing pixels in an existing video.
Results remain researchers’ claims
The Co-Director authors report an average score of 81.4 on their 400-scenario GenAd-Bench, compared with 75.7 for a four-iteration random-search baseline and 68.5 for a one-iteration base agentic pipeline. The benchmark uses a multimodal large language model as a judge, and the authors also ran a human study on a 50-scenario subset.
The CANVAS authors report gains over their best-performing baseline of 21.6% in background continuity, 9.6% in character consistency and 7.6% in prop consistency. The A²RD authors report improvements of up to 30% in consistency and 20% in narrative coherence across benchmarks spanning one- to 10-minute videos. The VQQA authors report absolute gains over unrefined generation of 11.57 percentage points on T2V-CompBench and 8.43 points on VBench2. These figures come from the teams’ own papers and benchmarks and should be read as researcher-reported results, not as independent validation.
The papers also document trade-offs. CANVAS requires multiple candidate images for its selection process and does not fully model fine-grained physical interactions or complex motion. A²RD adds computation over passive baselines and does not report human-rater agreement scores. VQQA depends on the reasoning and generation limits of its underlying models, while its sequential feedback loop adds latency compared with parallel candidate selection.
More news

xAI launches Team Bots for shared workflows

AWS adds xAI’s Grok 4.7 to Amazon Bedrock

OpenAI adds $5 million and up to $5 million in credits to Lenfest AI program
