Hugging Face makes Tokenizers v1 release candidate installable
Hugging Face’s installable Tokenizers v1 Rust release candidate adds new splitting, caching, memory-management and parallel paths, though work remains before 1.0.0.
Hugging Face has made a Rust release candidate for Tokenizers v1 installable. Developers can try redesigned encoding and decoding paths, but the project has not yet reached a final 1.0.0 release. The company says the changes are intended to keep CPU tokenization from leaving faster model workloads waiting for data as training sets, concurrent serving and long-input processing scale.
Developers can select the pre-release with cargo add tokenizers --pre, according to Hugging Face’s engineering post. The project’s repository identifies the current line as v1.0.0.rc.0 and says it does not yet ship every planned feature. Hugging Face separately lists work that remains before 1.0.0.
The release candidate reorganizes the former single crate into a required tk-encode runtime plus optional tk-serialize, tk-convert and tk-train components. The umbrella tokenizers crate preserves existing Rust paths. Hugging Face says v1 is designed to preserve the API, vocabulary, merge ranks and token IDs produced by the released v0.23 library across the measured paths.
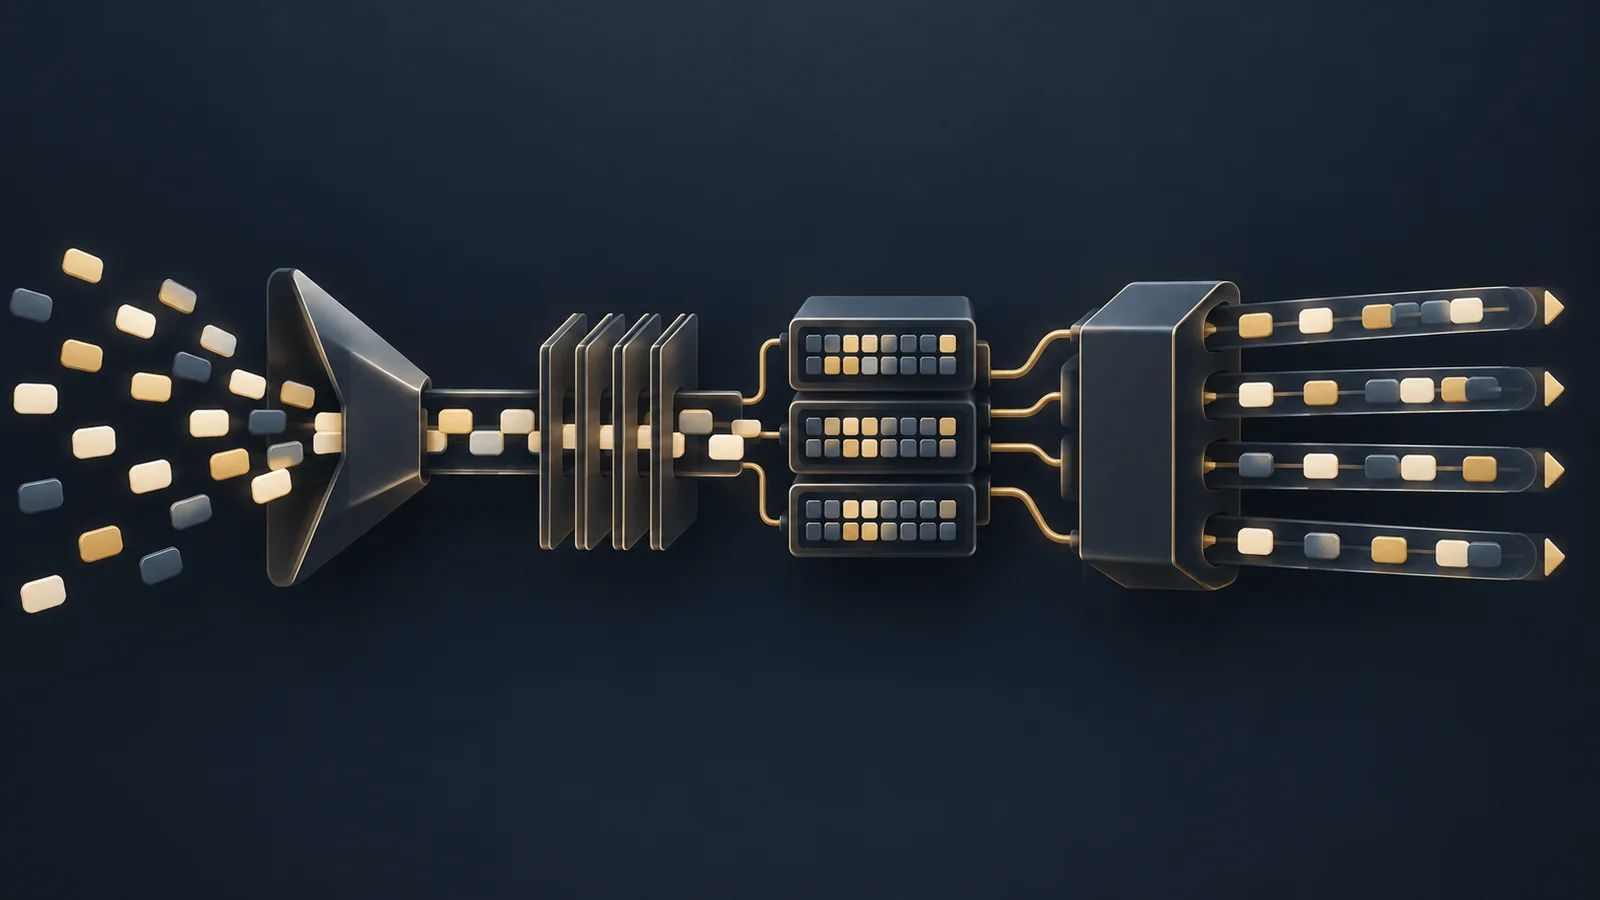
Much of the encoding work targets byte-pair encoding, or BPE, which repeatedly joins the highest-ranked adjacent symbol pair inside each pre-token. For recognized byte-level BPE grammars, a new bitcannon splitter replaces general-purpose regular-expression processing with Boolean operations across bitstreams and SIMD-capable CPU instructions. Patterns the implementation does not recognize stay on the regex path and do not receive that speedup.
A thread-local WordCache stores token IDs for previously processed pre-tokens, allowing repeated words to bypass the BPE merge process. Inputs with little repetition can still incur lookup costs without many cache hits. The rewritten merge loop reuses caller-owned scratch memory, keeps symbols in a flat array linked by indices and packs candidate pairs into 64-bit values. It also sends multiple pre-token spans through a single model call, reducing repeated allocation and data movement.
For parallel workloads, a single tokenizer can serve multiple threads, with each thread drawing scratch buffers and cache space from its own sub-pool. Hugging Face identifies encode_batch as the API that scales across cores. The implemented work also covers decoding directly into reusable byte buffers, fewer intermediate strings and copies, buffered streaming, parallel batch decoding, role_to_token support and Node.js bindings.
Elsewhere in its developer stack, Hugging Face has also released WebGPU kernels for local AI. The Tokenizers measurements cover CPU-side Rust code.
In Hugging Face’s own tokbench measurements, the single-threaded encode path ran 3 to 30 times faster than v0.23 across 10 model families on an Apple M4 Max and reached 76% of linear scaling across eight workers. The company says its method excluded load time, checked hashes of output IDs, compared only verified common test cells, started repeats in separate processes and pinned workers to eight physical cores. DataPhoenix did not independently reproduce those results. The figures cover the Rust crate; Hugging Face says its Python bindings use the same core code but add per-call overhead that the benchmarks exclude.
The remaining 1.0.0 checklist includes using one encoding implementation for training validation, making offsets and masks optional, reworking normalizers, adding bitnorm and SentencePiece precompiled support, simplifying the Python bindings, and supplying inference-only C and C++ bindings. GPU encoding and batch decoding are listed as exploratory work for after 1.0.0, subject to more prototyping and measurement.
More news
Sam Altman expected to attend Trump-Xi state dinner
Demo Stage premieres October 7. Tech Talks return October 15. Submit your project or talk proposal.
 Dmytro Spodarets·Sep 22, 2026
Anthropic says Claude leads 26% of measured AI R&D work