IBM releases Granite Switch 4.1 for chat, decisions and speech on one endpoint
IBM's Granite Switch 4.1 combines an 8B or 30B language model, decision and safety adapters, and an English speech encoder in one deployable checkpoint. Its speed and efficiency figures remain vendor claims.
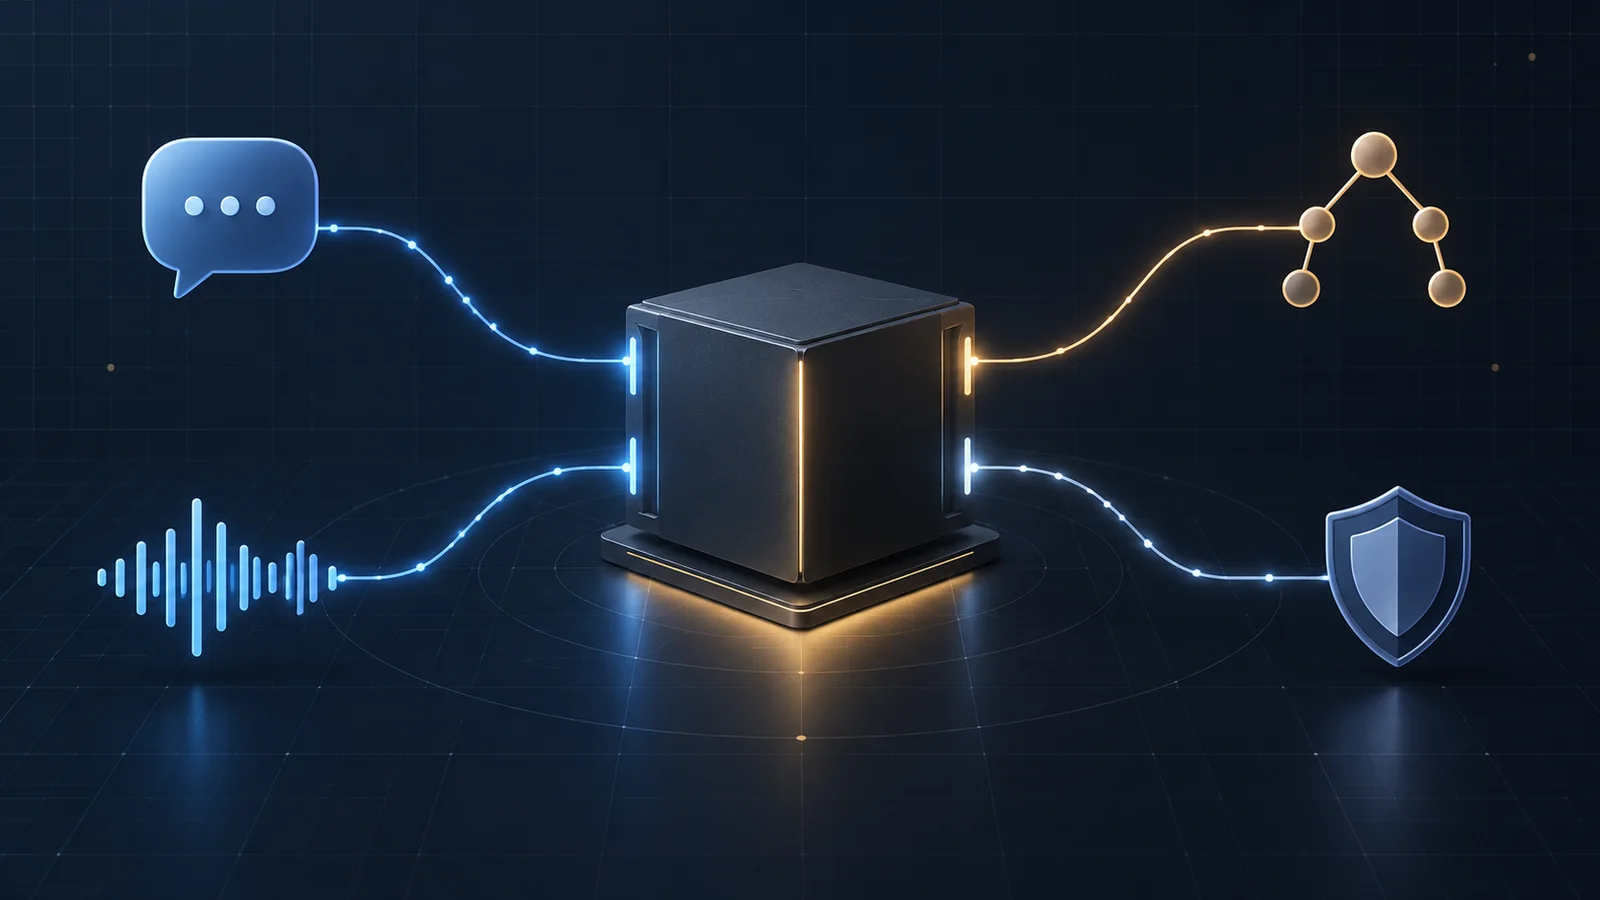
IBM’s Granite team announced Granite Switch 4.1, a pair of 8 billion- and 30 billion-parameter models designed to handle chat, general-purpose decisions, safety screening and speech transcription through one running model endpoint.
The design packages those capabilities into one deployable checkpoint, letting an operator route several kinds of requests through the same loaded model instead of serving a separate full model for each task. IBM says the composed checkpoint uses approximately the same video memory as its base language model and could therefore reduce GPU requirements, but that claim has not been independently verified.
The Granite Switch 4.1 8B and Granite Switch 4.1 30B model cards list the same modular components: a base Granite language model; an adapter for general-purpose decisions; a guardian-core adapter for detecting safety risks; and the 470 million-parameter English Granite Speech 5.0 TurboCTC encoder. The cards say control tokens inserted by the chat template select an adapter when needed, and the checkpoint applies that adapter’s LoRA weights across decoder layers for the relevant span of tokens.
LoRA adapters are small sets of additional weights that alter a base model for a particular task without replacing the full model. Granite Switch uses an Activated LoRA, or aLoRA, approach in which adapted weights take effect only after an invocation marker. The NeurIPS 2025 paper says this lets an adapter reuse the base model’s existing key-value cache rather than recomputing the earlier context.
IBM’s Granite Switch repository says its composition process embeds compatible adapters, their control tokens and a chat template into a single checkpoint. The package is designed to work with Hugging Face Transformers and vLLM. Neither model card listed a Hugging Face Inference Provider when reviewed, so the one-endpoint description refers to the deployment architecture rather than confirmed availability from a particular managed host.
IBM also claims Granite Switch can move among chat, decision and speech requests at high speed, and reports that a five-step retrieval-augmented generation workflow ran faster than a Jev-27B comparison. It further says its Guardian aLoRA beat Jev 1.13, Microsoft-Decision-1, GPT-Luna-Decisions and Clef-Flash on average in safety-related decision tasks, and calls the embedded speech system the fastest model on the OpenASR leaderboard. Those comparisons have not been independently reproduced, and the available leaderboard material did not expose enough data to confirm the speech ranking.
The model cards also spell out important limits. The speech encoder and language model were not jointly trained, and the English-only speech path returns lowercase text without punctuation. A transcription error can therefore pass silently into a later language-model or adapter response. IBM also says guardian-core is not a replacement for application-level safety testing; the checkpoints omit the factuality-detection, factuality-correction and policy-guardrail adapters available elsewhere in its Guardian Library.
Both checkpoints are listed under the Apache 2.0 license. Their model cards label the release date as October 14, 2026, while IBM’s launch post is dated October 15; the sources do not explain the difference.
More news
IBM and NASA release open-source lunar foundation model
IBM releases Granite TimeSeries PatchTST-FM-r2
Google expands limited access to Earth AI geospatial agents