Researchers train fixed AI-agent teams to reason together
Researchers developed a framework that learns reusable ways for fixed teams of AI models to divide work and audit answers, outperforming compute-matched controls most clearly on math and physics tests.
Researchers at Stanford University, Together AI and Emory University developed a framework for fixed teams of AI models to reuse collaboration and auditing strategies learned from earlier problem-solving runs.
Across five math and physics benchmarks, the Self-Organizing Agent Teams preprint reports average final-answer accuracy of 66.7%. The strongest individual model in the roster reached 48.8%, while a compute-matched control—in which the strongest model performed every team role sequentially—reached 58.7%.
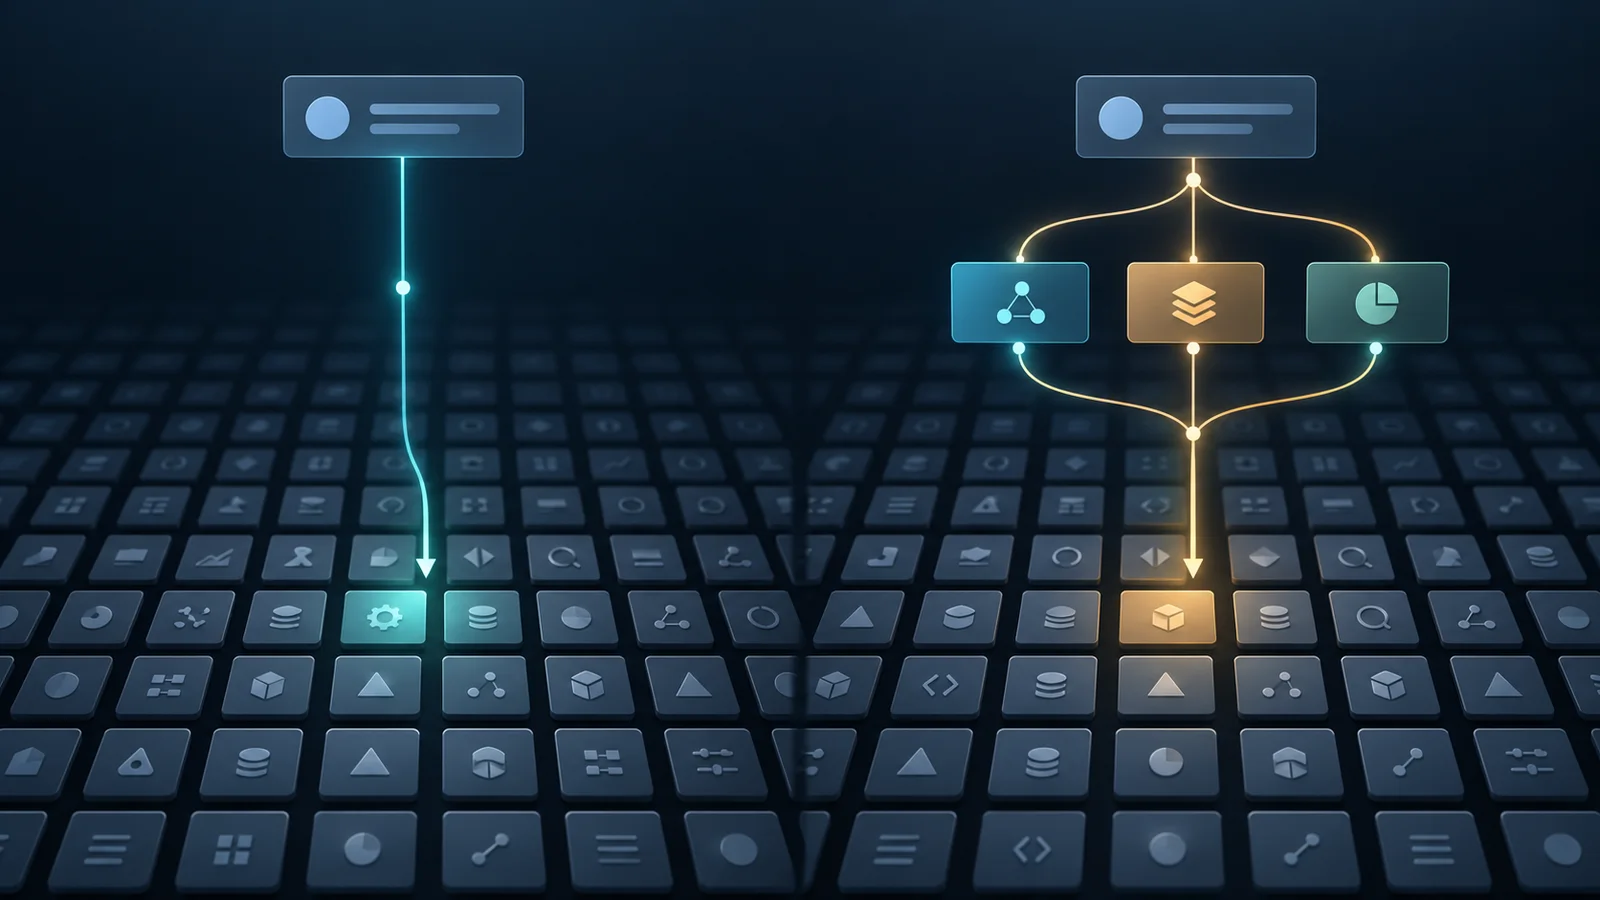
The authors call the framework SAT and treat organization as something a model team can learn. Its reusable strategies specify roles, conversation phases, participation, information flow and how a final answer is assembled. The researchers learned those strategies offline and froze them before evaluation instead of generating a new task breakdown for each test question.
For math and physics, the fixed roster contained o3-mini, Claude Sonnet 4 and DeepSeek-V3. It learned from 15 AIME 2024 problems, then was evaluated on held-out AIME 2024 questions and transferred unchanged to AIME 2025, AIME 2026, HMMT February 2026 and TheoremQA physics.
AIME 2026 produced the largest reported gain over the independent-answer oracle. SAT reached 71.2% accuracy, compared with 42.2% for the strongest member, while an oracle that could select among the members’ independent answers covered 57.8% of problems. The team’s 13.4-percentage-point edge over that oracle indicates that, on this test, interaction produced correct answers absent from the models’ initial independent responses.
The improvement was not uniform. SAT tied the linearization control at 39.4% on HMMT February 2026. On TheoremQA physics, it scored 77.2%, compared with 71.1% for the strongest member and 74.0% for a Mixture of Agents baseline.
A second fixed roster—Gemini 2.5 Flash, Llama 4 Maverick and GPT-4.1—learned separately from 25 GPQA Diamond problems. Across GPQA, MMLU-Pro and selected BBEH logic tasks, SAT averaged 72.8%. That was only 0.7 percentage points above a 72.1% linearization result using Gemini 2.5 Flash, and SAT trailed the Mixture of Agents baseline on MMLU-Pro and a homogeneous-team baseline on BBEH.
The paper identifies answer selection as a constraint. On the knowledge and logic tests, the team’s candidate pool contained a correct answer on 87.9% of problems on average, but its final selected answer was correct 72.8% of the time. The 15.1-point gap shows that generating a correct candidate did not ensure the team could recognize it. Final accuracy also fell below the 79.6% coverage of an oracle choosing among independent member answers.
To examine when collaboration helped, the researchers asked a separate panel of 10 models to choose between one correct and one incorrect reasoning certificate. Across eight benchmarks, that measure of how readily correct reasoning could be distinguished from a plausible error correlated with SAT’s improvement over its strongest member. The paper reports a Spearman correlation of 0.90 and an exact permutation p-value of 0.005; leave-one-benchmark-out correlations ranged from 0.86 to 0.96.
The authors describe that analysis as post hoc and correlational. It does not show that making correct reasoning easier to identify causes a team to become more accurate, and the paper says experiments that directly alter this property are still needed.
One HMMT case study illustrates cross-model repair. All three models first answered incorrectly, o3-mini supplied an invariant and counting method, DeepSeek-V3 corrected the decisive counting error, and Claude Sonnet 4 audited the fix before the team returned the correct answer, 3,840.
The evaluation covers two fixed three-model rosters on academic benchmarks; it does not test production workflows, changing rosters or open-ended enterprise tasks. The paper was submitted to arXiv on Sept. 19, 2026, as a preprint rather than a peer-reviewed publication.
More news
Meta researchers split control from execution in longer AI agent workflows
Google outlines three building blocks for autonomous wet labs
Apple study finds tool-discovery gains shift with task complexity