Shopify brings generative retrieval to production search and recommendations
Shopify says separate SID-LLM models are generating candidates in its production search and recommendation systems, built on a shared product representation.
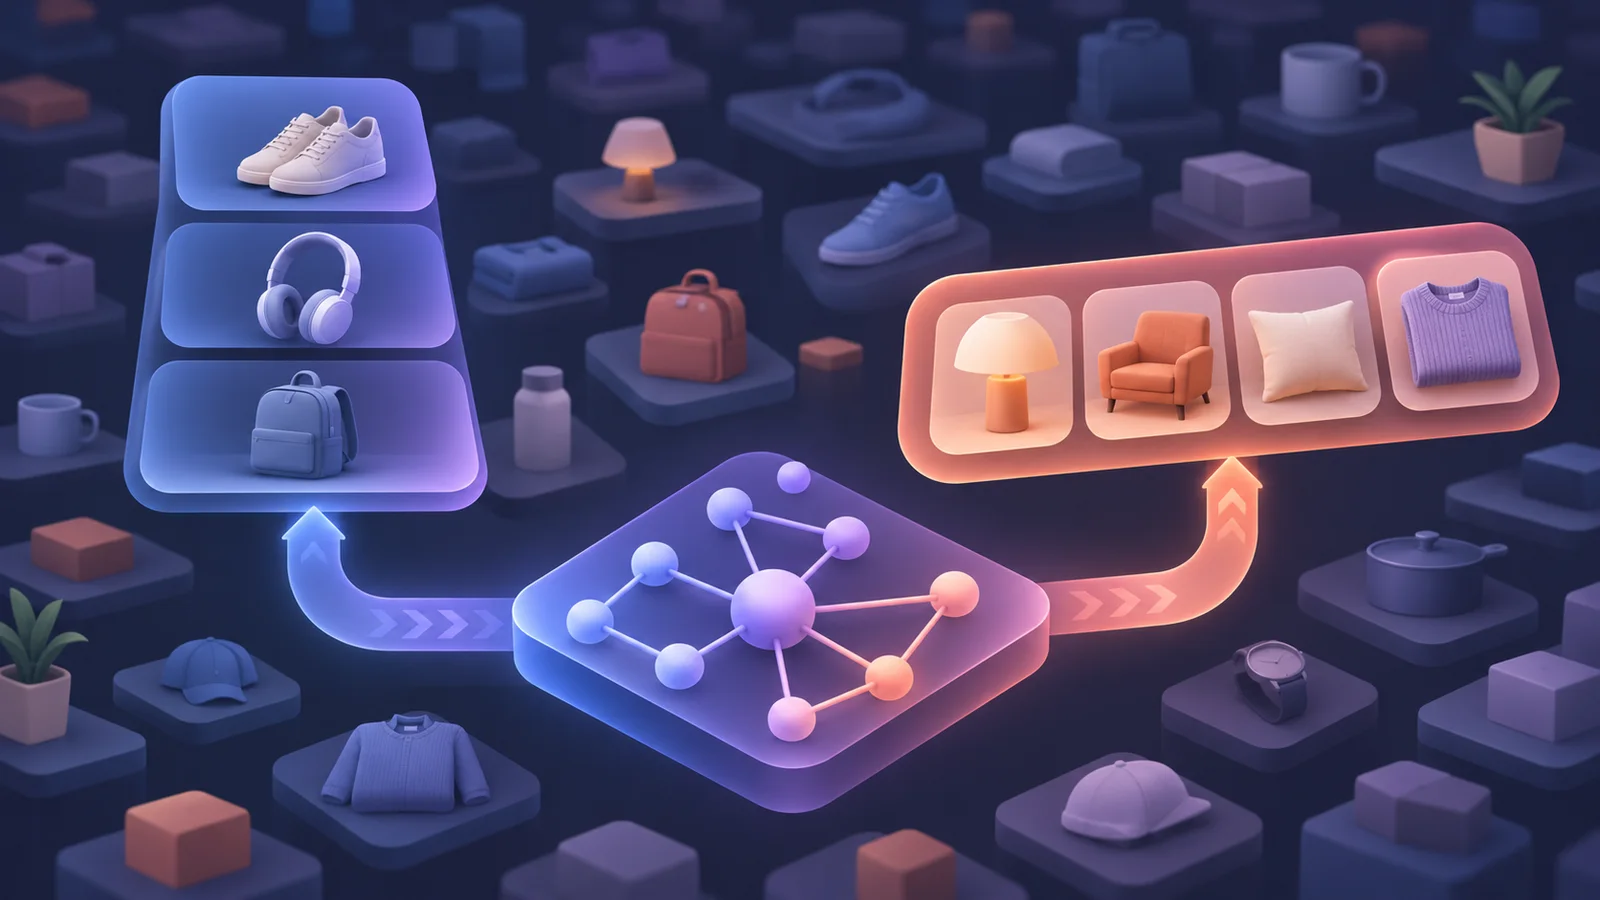
Shopify has deployed task-specific generative models to generate product candidates in its production search and recommendation systems. Rather than replacing Shopify’s existing retrieval and ranking pipelines, the models add candidates to them.
Both deployments use the same SID-LLM product representation and joint pre-training strategy. Shopify says the system covers a catalog containing billions of products, with hundreds of millions eligible at a time. The company also reports better retrieval quality and increases in orders and conversion on a tested Shop home-feed surface, although those results and its latency figures have not been independently reproduced.
SID-LLM represents each product with a three-token “semantic ID,” a compact code based on product meaning instead of a conventional catalog identifier. Shopify jointly pre-trains on catalog, search and recommendation data, giving both tasks the same representation and objective. Its technical report on the production system says the single student model distilled from both task-specific teachers remains experimental; production uses separate models for search and recommendations.
For search, a multi-token generator produces 250 candidates before a 350-million-parameter ranker narrows them to the top 100 semantic IDs. Shopify combines those candidates with keyword and embedding retrieval, while SID-LLM also supplies similarity features to two later learned ranking stages. For recommendations, an autoregressive model based on Liquid AI’s open-weight LFM2-2.6B generates 200 products from a buyer’s interaction history. Those products join candidates from other generators in a shared pool before ranking.
In Shopify’s offline search ablation, the full stack with SID-LLM recorded OneDCG@10 of 0.32690, compared with 0.30570 without it. The corresponding personalized-search scores were 0.35718 and 0.32979. Shopify also says successive search A/B tests measuring purchases and clicks supported the production rollout, but it did not publish numerical online search lifts.
Shopify evaluated recommendations using 70,747 users who made a purchase during a held-out seven-day window. It reported 24.61% Recall@50 for SID-LLM and a 2.65-percentage-point increase in recall for the combined candidate pool, versus 1.64 points for the next-best listed generator. In a Shop home-feed A/B test, Shopify attributed relative lifts of 7.95% in orders, 8.60% in converting users and 9.85% in conversion rate to adding SID-LLM. The report says all three passed a Dunnett multiple-comparison correction, but it does not disclose the test duration, sample size, traffic allocation or absolute event counts.
For the search generator and ranker, Shopify reported server-side latency of 17.5 milliseconds at the median, 29.2 ms at p95 and 38.2 ms at p99. The simulated production benchmark ran on one B200 GPU partition at 50 offered requests per second, so the figures do not represent complete storefront or user-perceived latency. Shopify rebuilds the constrained-decoding index from a daily catalog snapshot, and each serving process loads a validated snapshot at startup.
More news
AWS details full fine-tuning in SageMaker serverless customization
Starburst opens Context Studio private preview for governed agent context
OpenAI, Groupe Figaro sign ChatGPT journalism partnership