Xiaomi releases MiMo-V2.6-Pro-RL open-weight multimodal model
Xiaomi MiMo released downloadable weights for MiMo-V2.6-Pro-RL, which it describes as a sparse mixture-of-experts model for text, images, video and audio with a context window of up to 1 million tokens.
Xiaomi MiMo released downloadable weights for MiMo-V2.6-Pro-RL, along with a model card and linked technical report. The repository labels the release with an MIT license.
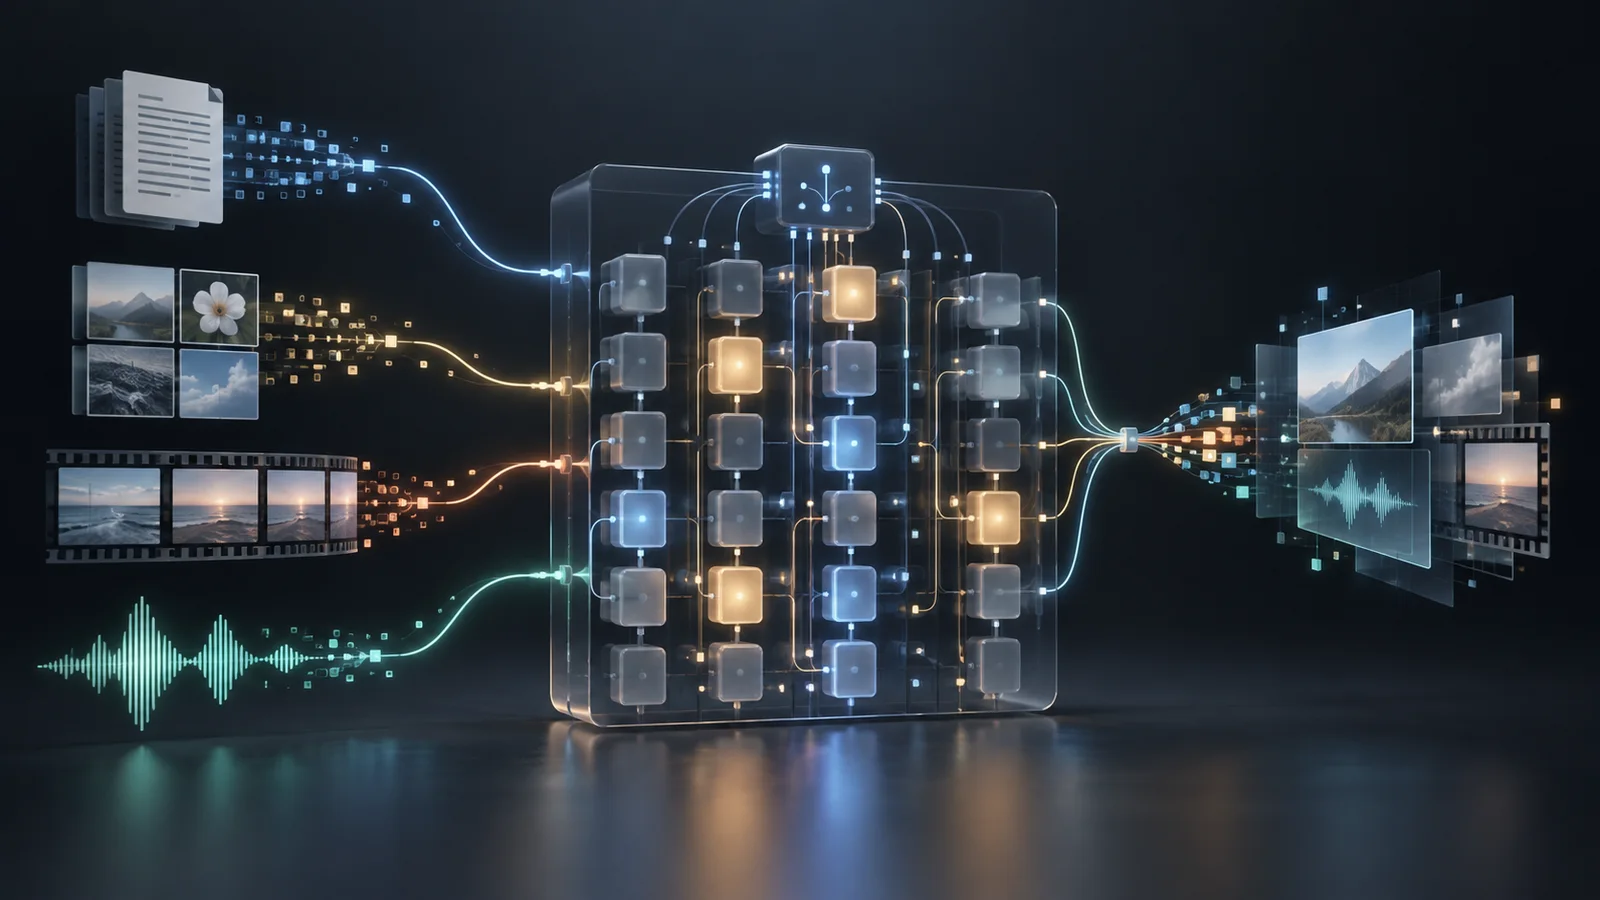
Xiaomi says the model processes text, images, video and audio, with a maximum context length of 1 million tokens. It describes MiMo-V2.6-Pro-RL as a sparse mixture-of-experts model containing 1.02 trillion parameters in total and activating 42 billion for a given input.
According to the model card, the system has 384 routed experts and activates eight at a time. Its 70-layer language-model backbone comprises 60 sliding-window-attention layers and 10 global-attention layers.
The disclosed architecture also includes a 681-million-parameter MiMo vision transformer, a 308-million-parameter AudioTokenizer encoder and a 127-million-parameter audio patch encoder. Xiaomi describes a five-layer speculative decoder that predicts seven subsequent tokens per forward pass for parallel verification.
The model card’s benchmark tables contain Xiaomi’s own evaluation results, not independently verified rankings. The evidence reviewed for this story included no independent reproduction of those scores.
Xiaomi says the model is also available through Xiaomi AI Studio, MiMo Code, Xiaomi MiMo Desktop, the Xiaomi MiMo Open Platform API and OpenRouter. The research for this story did not independently test those services.
One specification remains unresolved: the model card gives MiMo-V2.6-Pro-RL a total parameter count of 1.02 trillion, while the Hugging Face interface separately displays a model size of 524 billion parameters. The available sources do not explain the difference.
More news
Sam Altman expected to attend Trump-Xi state dinner
Demo Stage premieres October 7. Tech Talks return October 15. Submit your project or talk proposal.
 Dmytro Spodarets·Sep 22, 2026
Anthropic says Claude leads 26% of measured AI R&D work