3D-aware Conditional Image Synthesis
This paper describes a 3D-aware conditional generative model for controllable photorealistic image synthesis. It integrates 3D representations with conditional generative modeling, i.e., enabling controllable high-resolution 3D-aware rendering by conditioning on user inputs.
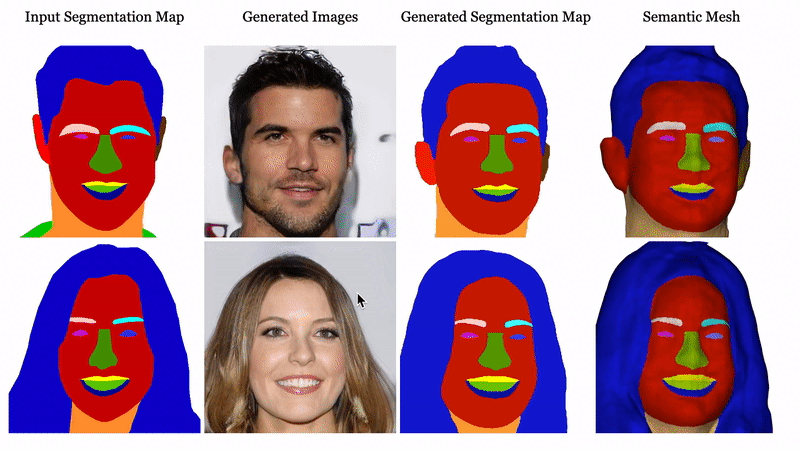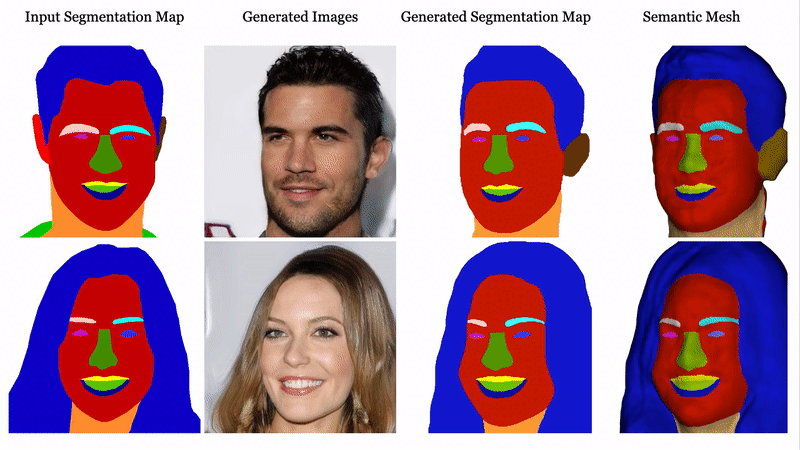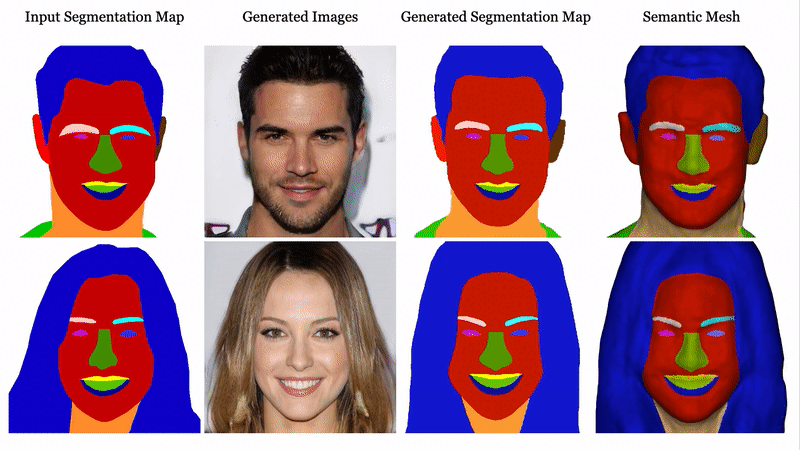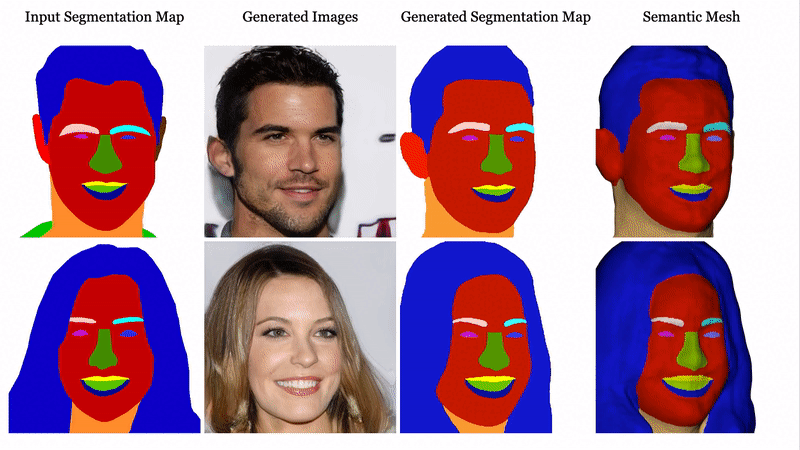
Abstract
We propose a 3D-aware conditional generative model for controllable photorealistic image synthesis. Given a 2D label map, such as a segmentation or edge map, our model synthesizes a photo from different viewpoints. Existing approaches fail to either synthesize images based on a conditional input or suffer from noticeable viewpoint inconsistency. Moreover, many of them lack explicit user control of 3D geometry. To tackle the aforementioned challenges, we integrate 3D representations with conditional generative modeling, i.e., enabling controllable high-resolution 3D-aware rendering by conditioning on user inputs. Our model learns to assign a semantic label to every 3D point in addition to color and density, which enables us to render the image and pixel-aligned label map simultaneously. By interactive editing of label maps projected onto user-specified viewpoints, our system can be used as a tool for 3D editing of generated content. Finally, we show that such 3D representations can be learned from widely-available monocular images and label map pairs.
Video

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024