GLIGEN: Open-Set Grounded Text-to-Image Generation
GLIGEN (Grounded-Language-to-Image Generation) is a novel approach that builds upon and extends the functionality of existing pre-trained text-to-image diffusion models by enabling them to also be conditioned on grounding inputs. Take a closer look!
Abstract
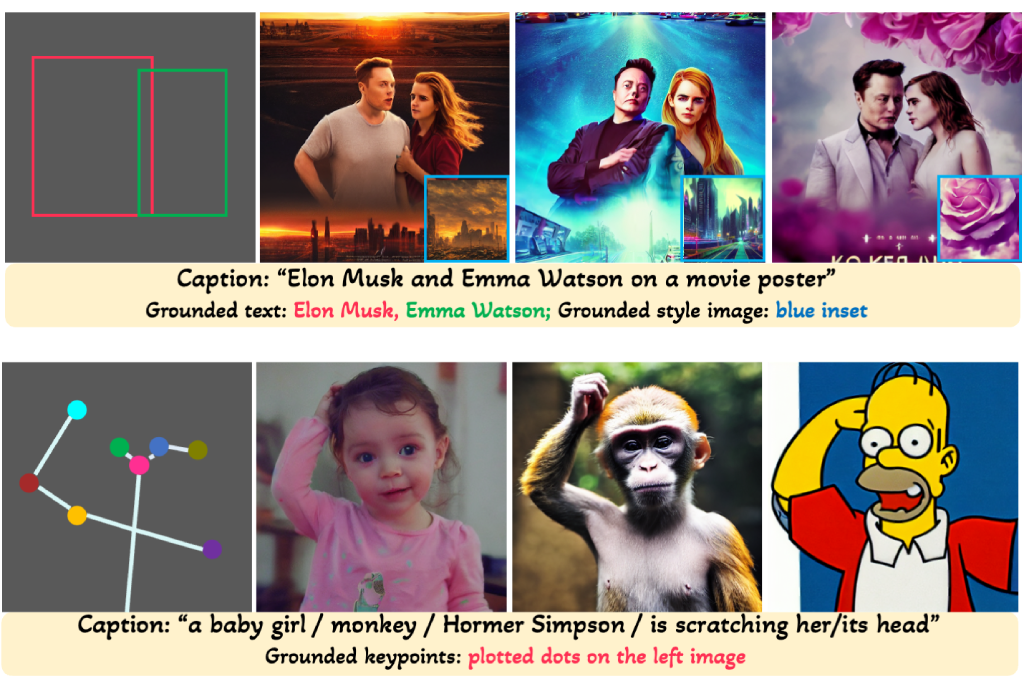
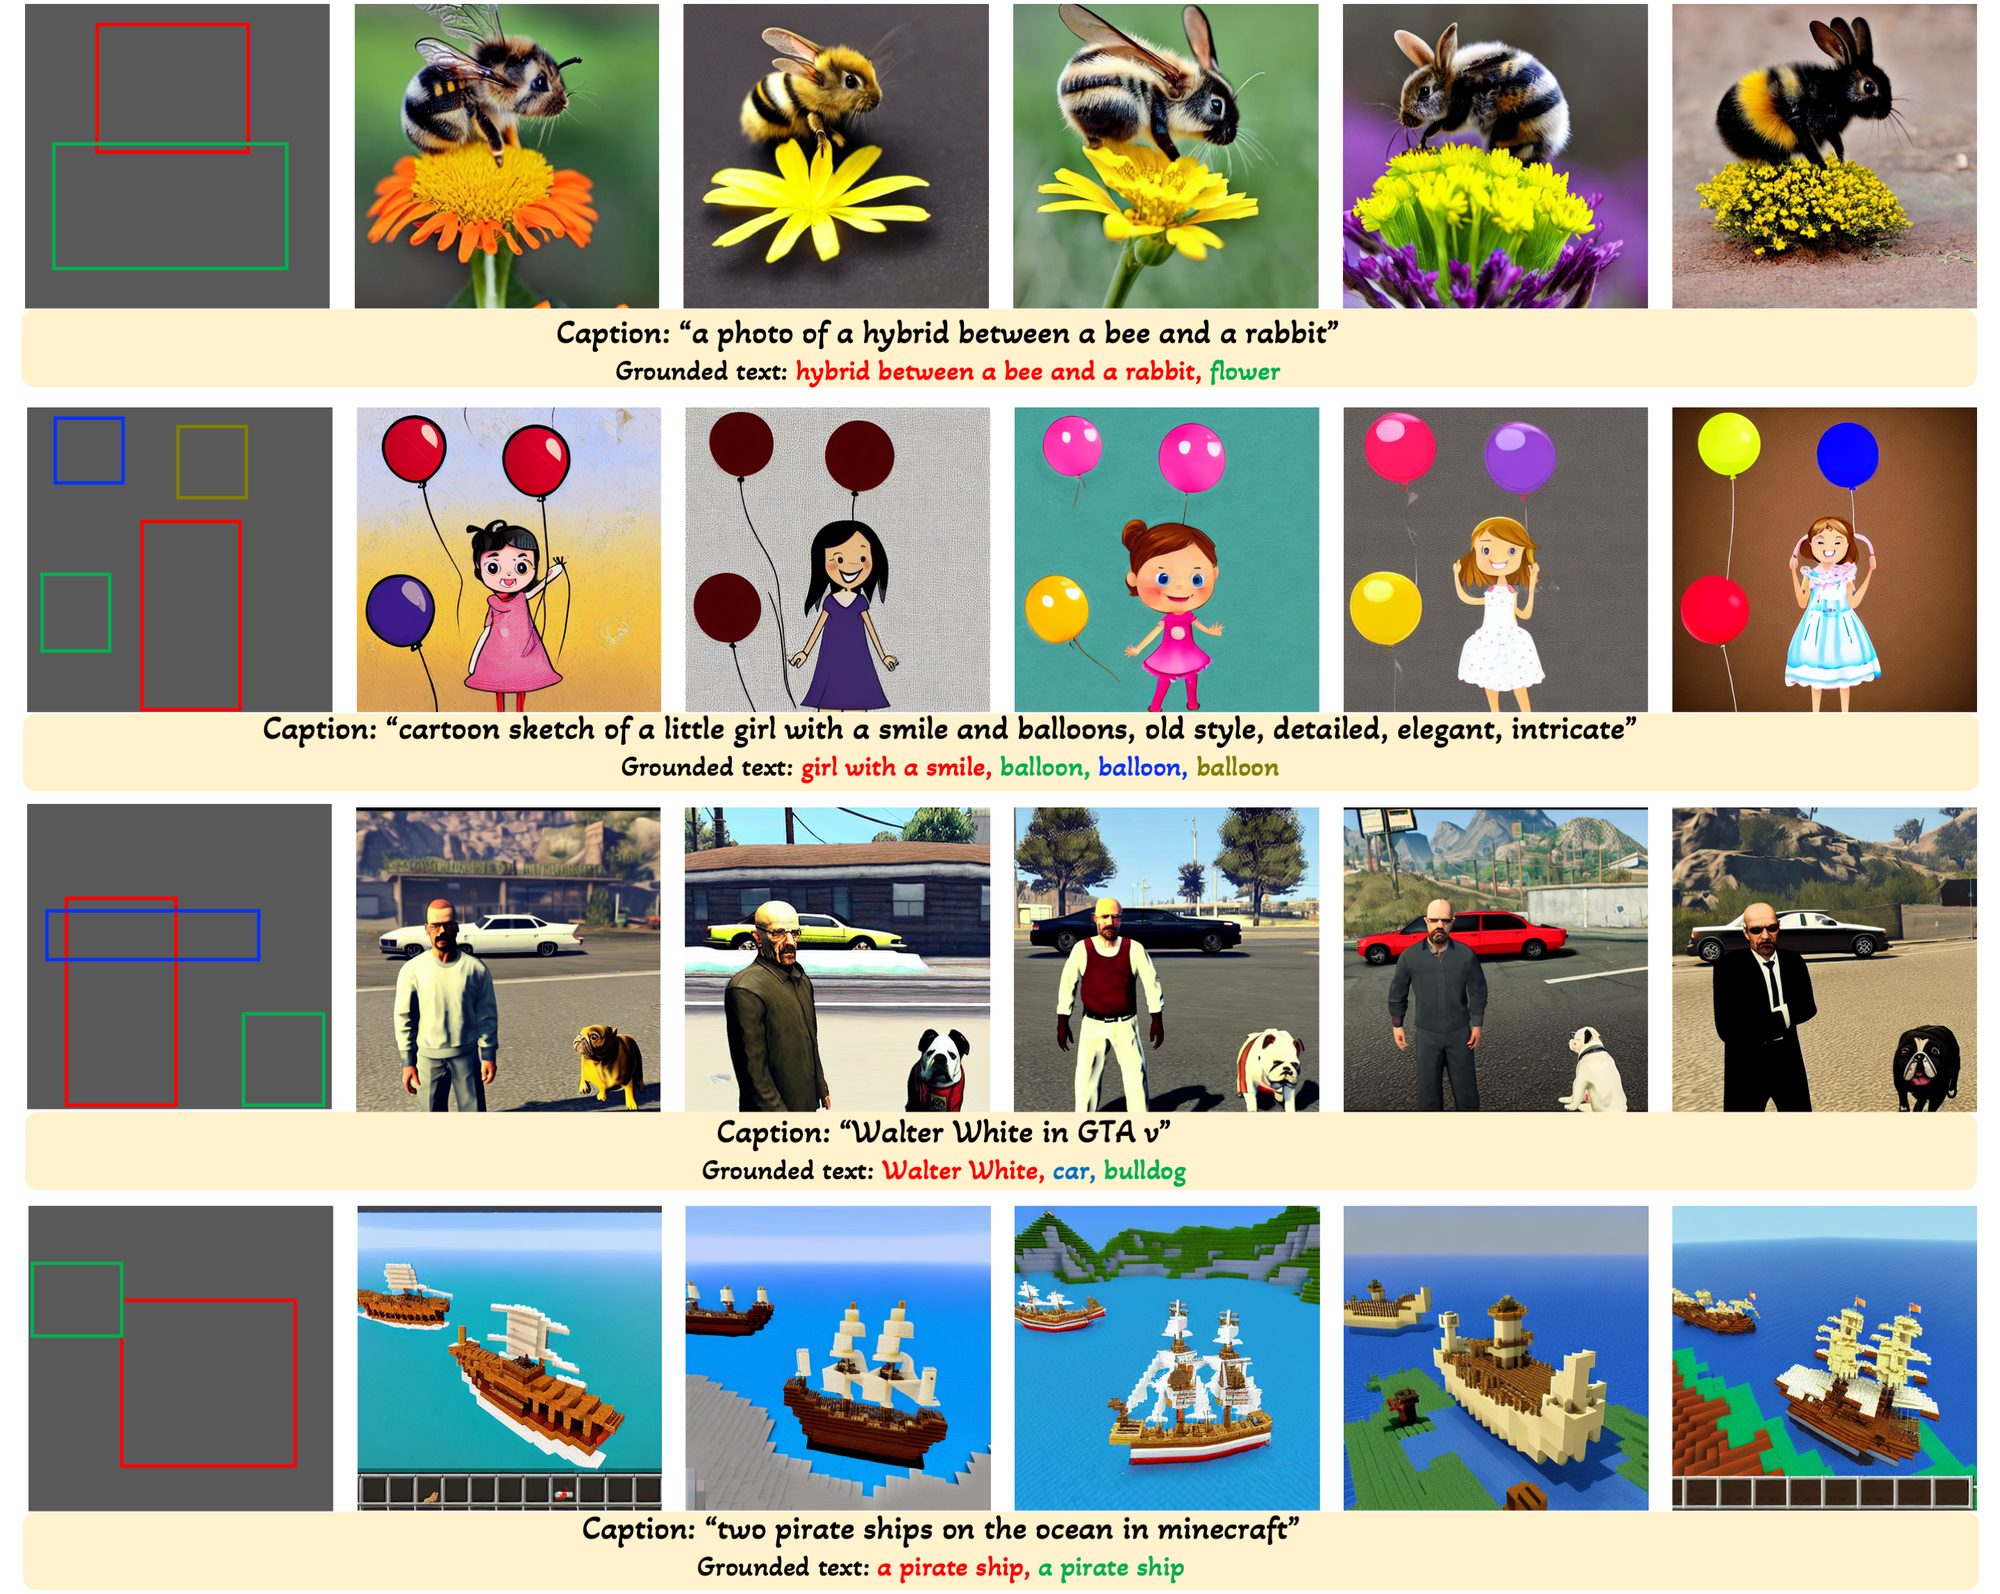
Large-scale text-to-image diffusion models have made amazing advances. However, the status quo is to use text input alone, which can impede controllability. In this work, we propose GLIGEN, Grounded-Language-to-Image Generation, a novel approach that builds upon and extends the functionality of existing pre-trained text-to-image diffusion models by enabling them to also be conditioned on grounding inputs. To preserve the vast concept knowledge of the pre-trained model, we freeze all of its weights and inject the grounding information into new trainable layers via a gated mechanism. Our model achieves open-world grounded text2img generation with caption and bounding box condition inputs, and the grounding ability generalizes well to novel spatial configuration and concepts. GLIGEN’s zero-shot performance on COCO and LVIS outperforms that of existing supervised layout-to-image baselines by a large margin.
Results

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024