SinMDM: Single Motion Diffusion
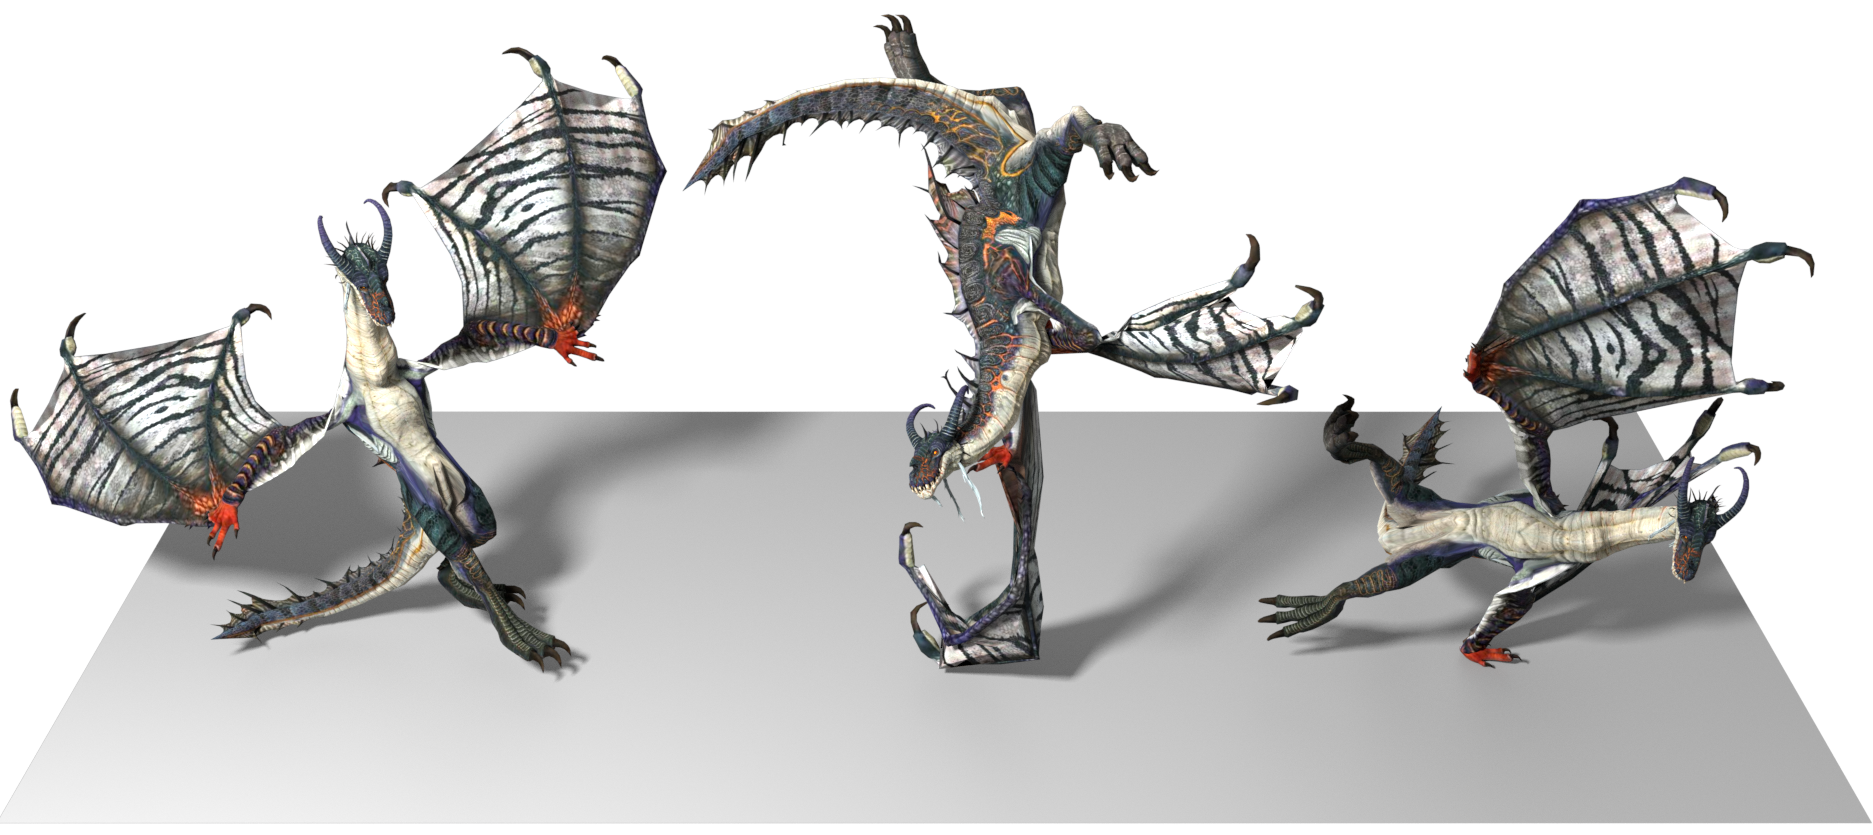
This paper presents a Single Motion Diffusion Model, dubbed SinMDM, a model designed to learn the internal motifs of a single motion sequence with arbitrary topology and synthesize motions of arbitrary length that are faithful to them. Check it out!
Abstract
Synthesizing realistic animations of humans, animals, and even imaginary creatures has long been a goal for artists and computer graphics professionals. Compared to the imaging domain, which is rich with large available datasets, the number of data instances for the motion domain is limited, particularly for the animation of animals and exotic creatures (e.g., dragons), which have unique skeletons and motion patterns. In this work, we present a Single Motion Diffusion Model, dubbed SinMDM, a model designed to learn the internal motifs of a single motion sequence with arbitrary topology and synthesize motions of arbitrary length that are faithful to them. We harness the power of diffusion models and present a denoising network designed specifically for the task of learning from a single input motion. Our transformer-based architecture avoids overfitting by using local attention layers that narrow the receptive field, and encourages motion diversity by using relative positional embedding. SinMDM can be applied in a variety of contexts, including spatial and temporal in-betweening, motion expansion, style transfer, and crowd animation. Our results show that SinMDM outperforms existing methods both in quality and time-space efficiency. Moreover, while current approaches require additional training for different applications, our work facilitates these applications at inference time.
Video

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024