Ai2 demonstrates the scalability of its post-training recipe with the performant Tülu 3 405B
Tülu 3 is an open-source research project by the Allen Institute for AI (Ai2) that provides a comprehensive open-source post-training methodology for large language models. The recently released Tülu 3 405B demonstrates that the Tülu 3 post-training recipe is both efficient and scalable.
What is Tülu 3?
In November, the Allen Institute for AI (Ai2) released several research artifacts under the Tülu 3 name. These artifacts and recipes included: a dataset covering core skills like math, instruction following, knowledge recall, chat, and safety (Tülu 3 Data); a toolkit for data curation and decontamination (Tülu 3 Data Toolkit); an evaluation framework, and most importantly, training code and infrastructure supporting supervised fine-tuning (SFT), direct preference optimization (DPO), and reinforcement learning methods (RL).
Tülu 3: Democratizing access to reliable post-training methods
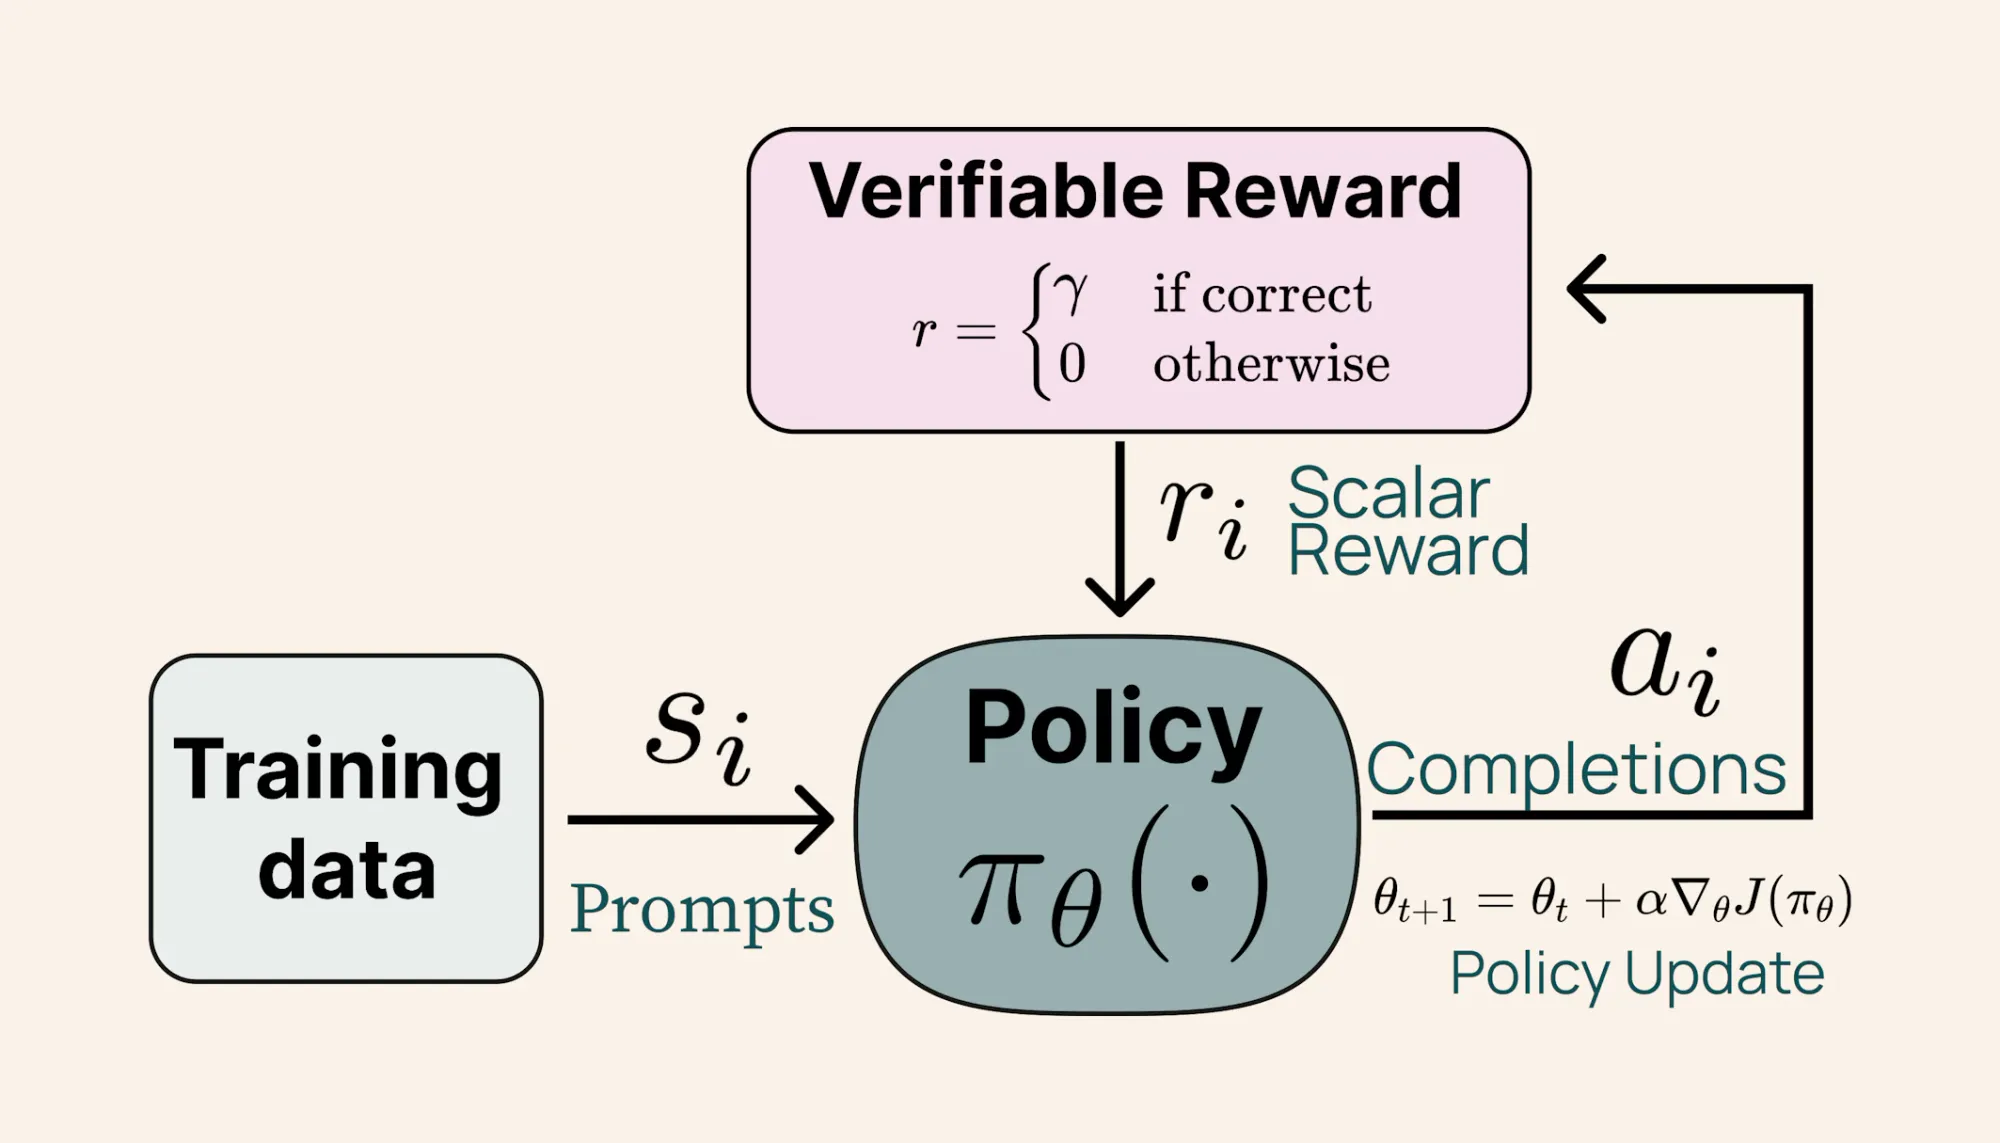
Upon release, Tülu 3 shipped with four models and checkpoints, including Tülu 3 8B and Tülu 3 70B, a pair of models developed by taking the pretrained, openly available Llama 3.1 models and submitting them to a five-part post-training recipe involving prompt curation and synthesis, SFT on the curated prompts and their completions, DPO on preference data, a novel RL method that rewards the model any time it provides a verifiable solution to a problem, and a final evaluation stage.
The motivation to do this, says Ai2, is that progress in truly open methods for model post-training was stalling as closed-source entities continued to develop increasingly complex and effective methods at the cost of reproducibility and a clear understanding of how post-training impacts model performance. With the full Tülu 3 release, Ai2 aimed at providing the open-source community with enough tools to replicate its best-performing post-training recipe.
To further jumpstart the interest on advancing open research into post-training methods, the Tülu 3 8B and Tülu 3 70B were benchmarked against some of the most popular similarly-sized open weights models, along with a few closed source contenders, including GPT-3.5 Turbo, GPT 4o-mini, and Claude 3.5 Haiku. The research team found that both models displayed performance competitive with their open weights and proprietary counterparts.
Introducing Tülu 3 405B
After the November release, a lingering question on whether the Tülu 3 post-training recipe would adequately scale remained. Thus, to demonstrate the scalability of the Tülu 3 post-training recipe, Ai2 has announced the availability of Tülu 3 405B, a model based on Llama 3.1 405B. Although the research team encountered technical challenges including increased compute demands—the model had to be trained using 256 GPU running in parallel—and limited hyperparameter tuning, the Tülu 3 recipe was successfully scaled, yielding "the largest model trained with a fully-open recipe to date."
Extensive testing reveals that Tülu 3 405B outperforms other 405B open weights models like Llama 3.1 405B Instruct and Nous Hermes 3 405B in several benchmarks, and that it can hold its own against other large models like the recently viralized DeepSeek V3 or GPT 4o (Nov 2024).
Ellie Ramirez-Camara is the News Editor at Data Phoenix, where she writes the daily AI newsdesk — covering model releases, research, funding rounds, and policy across the AI and machine-learning industry. She tracks announcements from labs and startups alike and distills them into clear, source-linked reporting for practitioners.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
