Ai2 releases XYBench to test how assistants handle mistaken premises
Ai2 released XYBench to measure whether AI assistants answer users’ literal requests, address their underlying goals and redirect misconceptions.
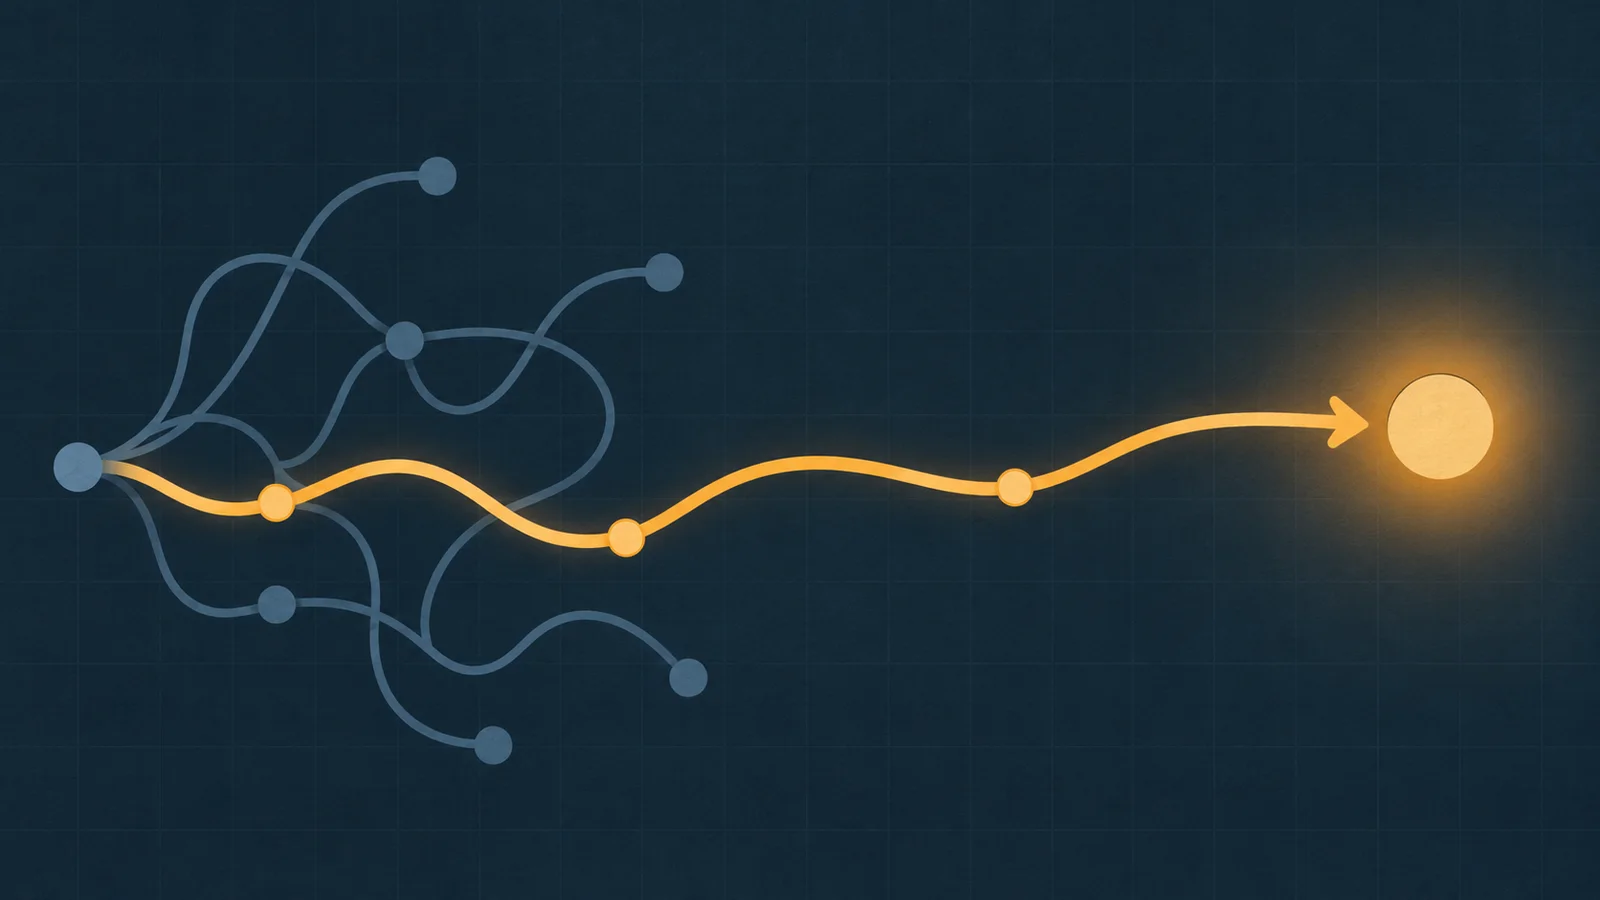
Ai2 released XYBench, a benchmark designed to test whether AI assistants recognize when a user’s requested approach rests on a misconception and redirect the response toward the underlying goal. The public test gives developers separate measures of whether a response supplies a literal solution, proposes a more useful alternative and makes that alternative the focus.
The benchmark authors say XYBench contains 8,115 questions drawn from programming forums, other community material and synthetic everyday scenarios. It targets what researchers call the XY problem: a person wants to achieve X, assumes method Y will work and asks only for help with Y. That means an assistant can give a technically responsive answer without solving the actual problem.
The paper defines three measures. Pragmatic solution checks separately whether a response contains at least one approach addressing the stated request and at least one alternative addressing the intended request. An automated judge first breaks the answer into distinct suggestions, called approach units, and labels each one.
Pragmatic emphasis looks at the answer as a whole, classifying whether it is organized mainly around the literal request, mainly around the underlying goal or balances the two. A brief mention of a better alternative does not make an otherwise literal answer pragmatic. Misconception identification is derived from the approach-unit labels: a response qualifies if it discourages the stated approach while encouraging the intended one, or if it encourages the intended approach without also encouraging the stated one.
The authors used Claude Sonnet 4.5 as the automated judge for those classifications. They report that two study authors independently annotated 500 responses—100 from Stack Overflow and 400 from the WikiHow-derived set—to validate it. Average human-judge exact agreement was 97.5% to 100% for solution presence, 84.6% to 93.3% for misconception identification and 74.2% to 79.8% for emphasis.
The paper also reports Krippendorff’s alpha of 0.587 to 0.600 for emphasis and 0.634 to 0.866 for misconception identification, compared with at least 0.915 for solution presence. Those figures are the authors’ validation results, not an independent audit. Related research on LLM-judge quality provides context for model-based evaluation.
Ai2 says the benchmark combines 1,557 Stack Overflow questions, 184 from other Stack Exchange sites, 102 manually curated examples and 6,272 questions generated from WikiHow guides using Claude Sonnet 4.5. The published repository and dataset card, however, currently list 6,268 WikiHow questions. Their displayed subset counts add to 8,111, four fewer than the 8,115 total in the release and paper. The gated dataset files were not independently counted.
In a single-turn test with one response per question, the authors evaluated Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B and DeepSeek-V4 Pro. On Stack Overflow questions, they report that stated-request solutions appeared in 75% to 86% of responses, while intended-goal solutions appeared in 59% to 71%. They say the models centered the intended goal in 35% to 41% of responses and the stated request in 47% to 57%.
The authors further report Stack Overflow misconception-identification rates from 47% to 60% across the five models, compared with 79% for the highest-scored human answers under the same automated metrics. In a separate multiple-choice test, six models chose a goal-focused answer in 71% to 84% of cases, even though the five models in the generation test centered their written answers on the intended goal only 35% to 41% of the time. These are research claims based on the benchmark’s automated scoring and were not independently reproduced.
The authors limit their conclusions to an English-language, single-turn evaluation weighted toward procedural problems. Most everyday questions were synthetically generated, the WikiHow-derived subset has no human reference answers, and the judge-validation sample covered 500 responses rather than the full benchmark. Ai2 made the evaluation code public, while the dataset card labels the data CC BY-NC-SA 3.0 and requires users to accept access conditions before downloading the underlying files.
More news
OpenAI introduces LifeVal benchmark for everyday AI tasks
Apple study finds LLM translation grading unreliable in most settings
Apple study finds MMLU weakly tracks LLM judge quality