AMD presents Nitro-P for pixel-space text-to-image generation
A transformer maps coarse image structure in patches, and a second network uses that map to update pixels across the whole image.
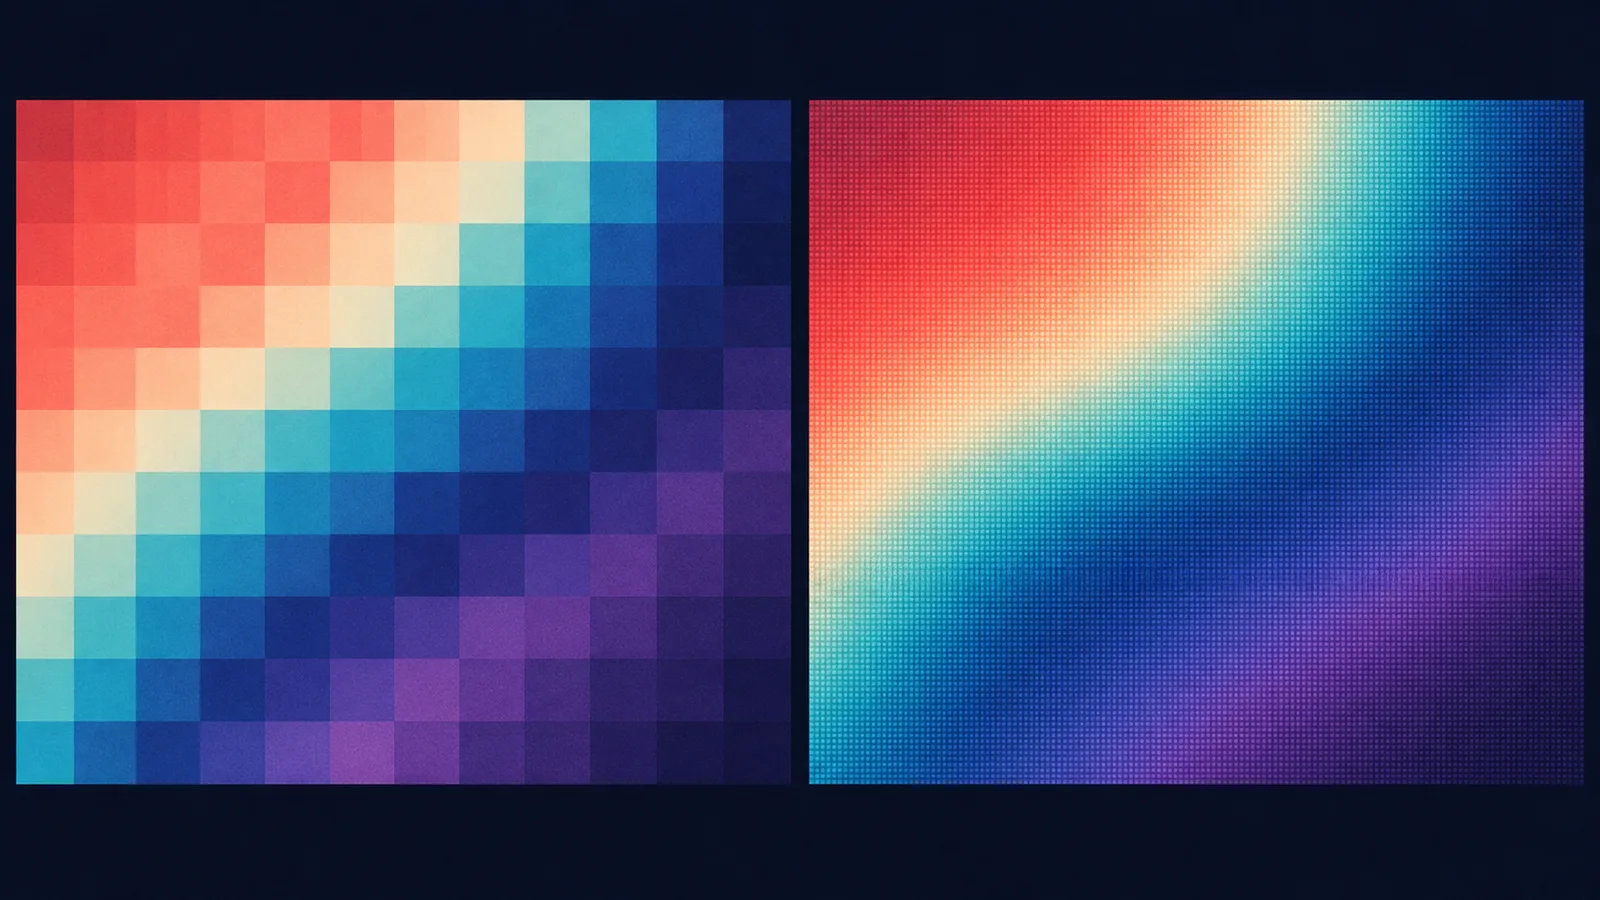
AMD presented Nitro-P on November 20. The company says the text-to-image diffusion framework removes noise directly from red, green and blue (RGB) pixel values, eliminating the final decoding pass used by its predecessor, Nitro-E.
AMD’s Nitro-E framework denoises a compressed representation of the image. A separate autoencoder then converts that representation to RGB pixels.
In Nitro-P, AMD’s E-MMDiT transformer uses the text prompt and 16×16 pixel patches to build a coarse map of the image. The map guides a reconstruction network called a U-Net. At the U-Net’s bottleneck, the map adjusts the strength and baseline of normalized signals at each location.
The U-Net processes the entire image at several resolutions, passing detail from earlier layers to later ones. It predicts how each RGB value should change as the model removes noise. AMD reported fewer visible patch artifacts in its visual comparison with a decoder that processes each patch separately.
AMD reported end-to-end throughput on one Instinct MI300X GPU with ROCm 6.3.4 and a batch size of 32. At 512×512 pixels, the distilled one-step Nitro-P generated 90.02 images per second versus 44.13 for one-step Nitro-E. At 20 steps, AMD reported 10.26 for Nitro-P and 18.83 for Nitro-E.
At 1024×1024 pixels, AMD reported 26.00 images per second for one-step Nitro-P and 11.00 for one-step Nitro-E. At 20 steps, it reported 2.44 for Nitro-P and 4.66 for Nitro-E.
AMD also announced training code and model weights, including checkpoints for one-step generation.
More news
Google rolls out Genie 4 to eligible AI Ultra subscribers
OpenAI rolls out Live Dictation across all ChatGPT plans
Snowflake adds generally available TwelveLabs video AI to Cortex functions