AWS adds KV cache-aware routing to SageMaker real-time endpoints
Amazon SageMaker AI can now place LLM requests using cache state reported by model containers, moving beyond inferred prefix affinity with a managed index that also accounts for instance load.
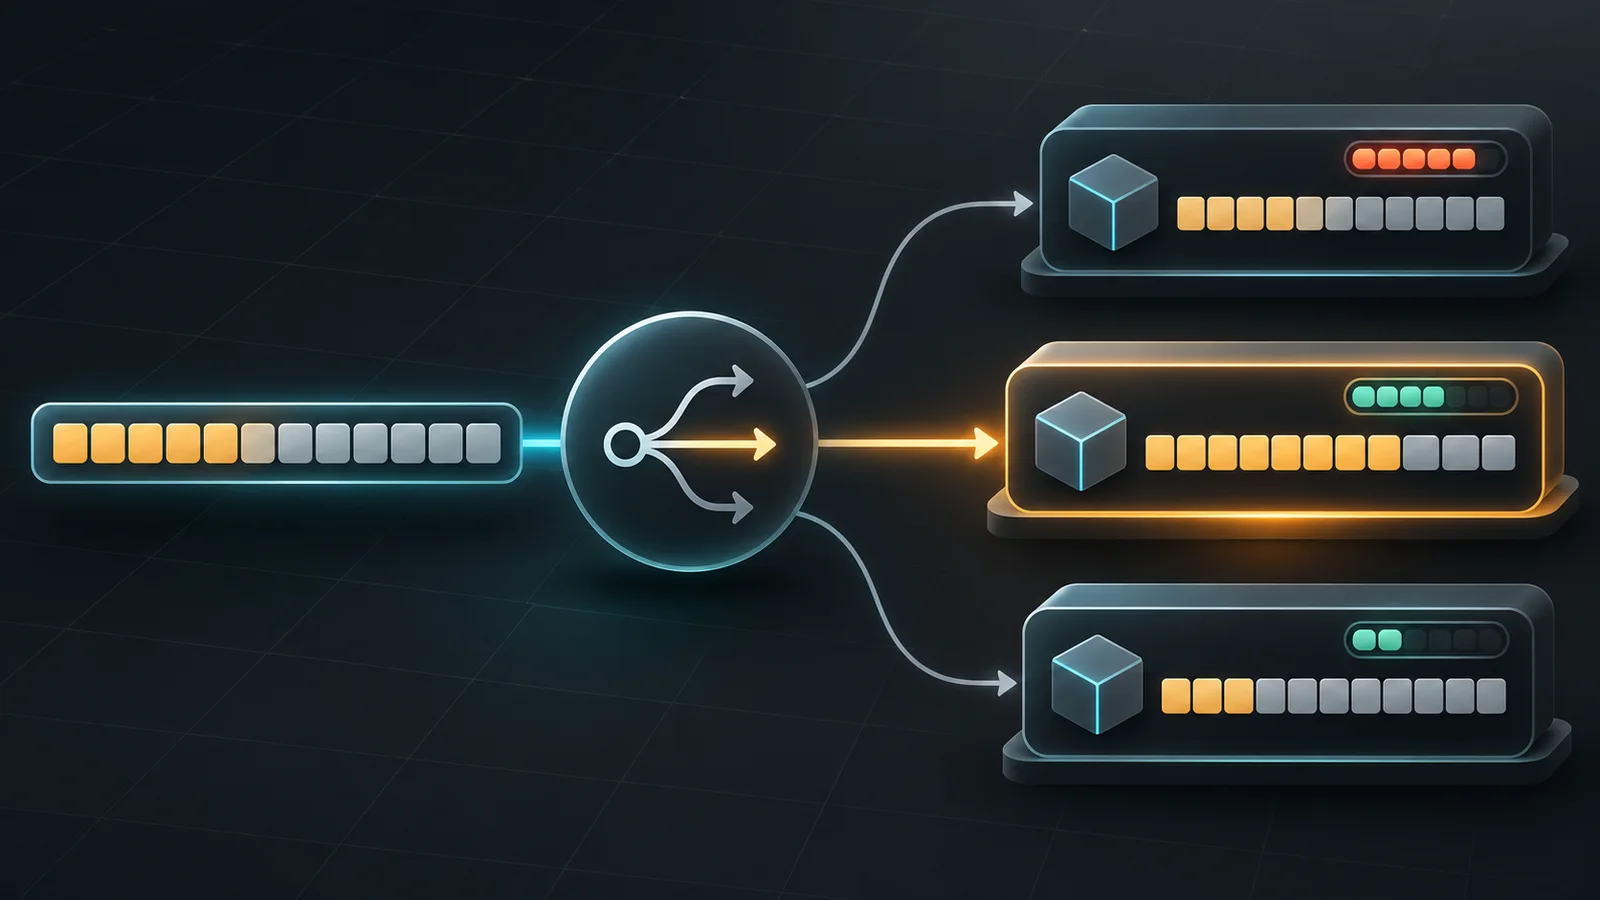
AWS has added KV cache-aware routing to Amazon SageMaker AI real-time endpoints, giving the managed service a way to direct an LLM request using cache state reported by model containers. According to AWS, the router looks for the destination holding the longest cached match for a prompt, then weighs that match against how busy each candidate is.
The update changes how SageMaker establishes request affinity. SageMaker’s earlier prefix-aware mode hashes a fixed-length portion of each incoming request and consistently sends matching prefixes to the same destination, subject to a configured concurrency threshold. That method cannot tell whether the destination still holds the relevant cache entry after an eviction. The new mode instead consumes store and eviction events from the container, allowing routing decisions to follow the cache state that the container reports.
A key-value, or KV, cache keeps intermediate calculations for previously processed prompt tokens in GPU memory. Reusing those calculations can reduce the work required before a model begins generating a response. AWS says SageMaker maintains a managed endpoint index that maps truncated one-way hashes of cached content to the instances or inference-component copies holding it. According to the company, the index does not store prompts, token IDs, request payloads or KV tensors.
AWS says SageMaker tokenizes the prompt and queries the index when a request arrives. If several destinations hold cached portions, the router favors longer matches without sending work to an overloaded instance. A slow lookup, no useful match or busy matching destinations triggers the same load-aware behavior as the LEAST_OUTSTANDING_REQUESTS strategy. The feature becomes active only when a single-model endpoint has at least two instances or SageMaker inference components have at least two copies.
To enable the mode, customers set RoutingStrategy to KV_AWARE and turn on container cache events with SM_VLLM_KV_EVENTS_CONFIG; AWS says client invocation APIs remain unchanged. At launch, AWS limits support to GPU-backed real-time single-model and inference-component endpoints running its vLLM Deep Learning Container with vLLM 0.33.0 or later, or the server-sagemaker-cuda-v2.8.0 Amazon Linux build or later. Requests must use OpenAI-compatible Completions or Chat Completions payloads, and bidirectional streaming is not supported.
In an internal benchmark, AWS said Llama 3.1 70B Instruct running on seven ml.p5.48xlarge instances cut median time to first token by as much as 97%, increased throughput by as much as 234%, and lifted KV cache hit rates from a 3%-48% range to 80%-93%. The company cautioned that results depend on the workload. No independent reproduction or customer deployment evidence was included in the source set.
AWS says the feature is available in every commercial AWS Region that supports SageMaker AI real-time inference, with no additional feature charge beyond the endpoint instances. When the source set was checked, the linked SageMaker routing API reference still listed only RANDOM, LEAST_OUTSTANDING_REQUESTS and PREFIX_AWARE as valid RoutingStrategy values, not KV_AWARE.
More news
AWS documents SageMaker AI data preparation workflows
AWS adds usage metering to SageMaker bidirectional streams
Amazon reports $94.8 billion increase in property spending tied mainly to AI