The latest Data Phoenix news tagged LLM inference.
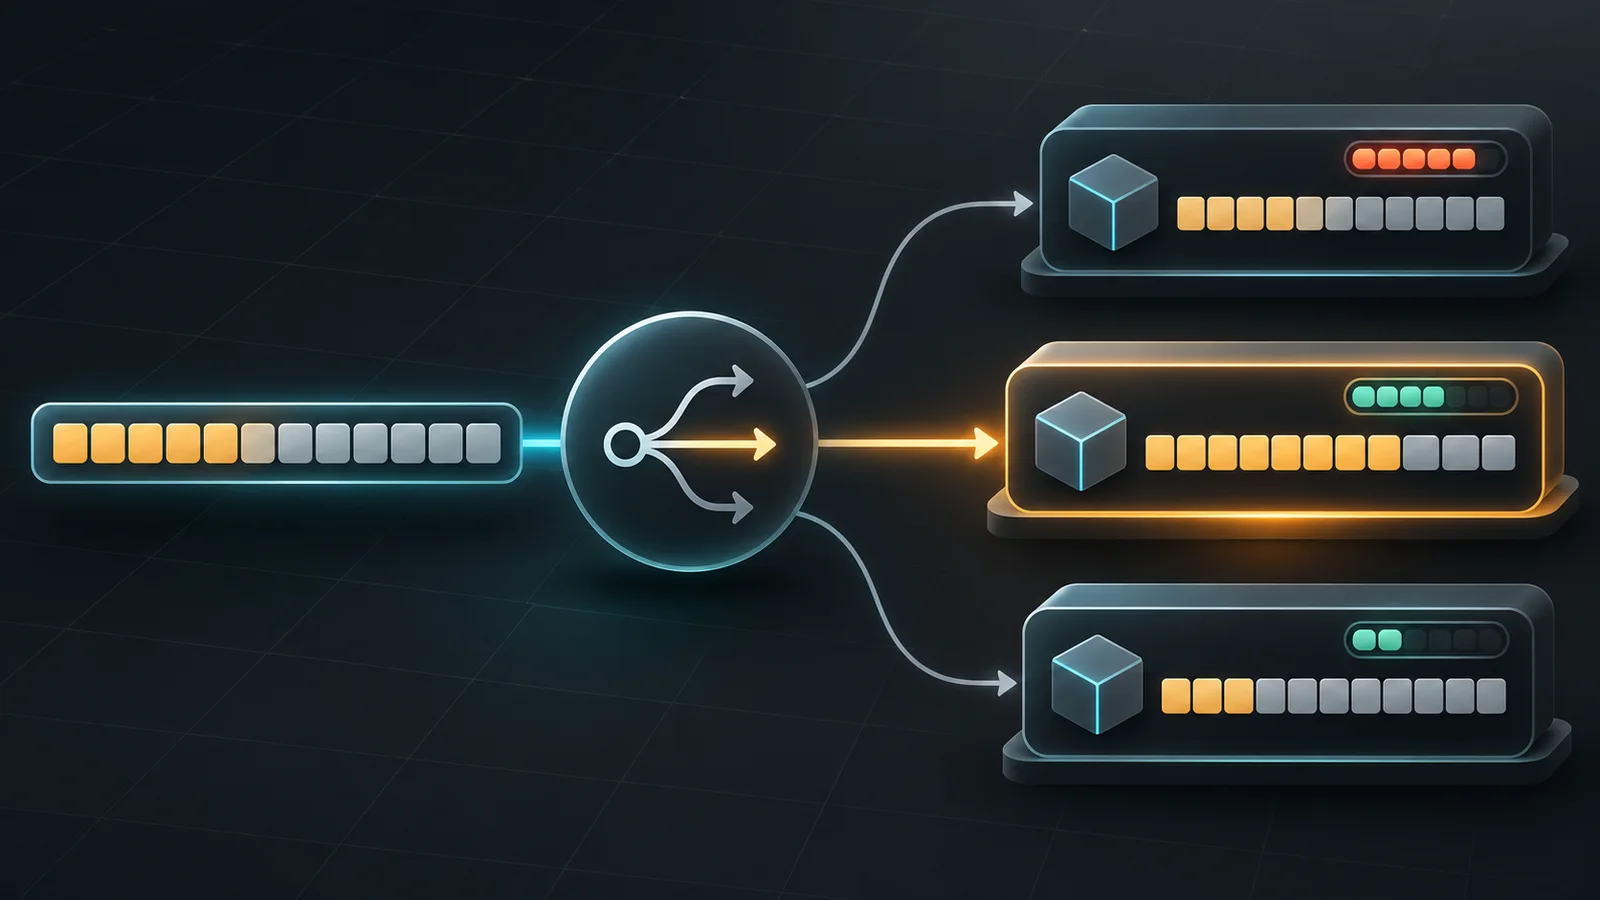
Amazon SageMaker AI can now place LLM requests using cache state reported by model containers, moving beyond inferred prefix affinity with a managed…
AWS launched a managed routing layer for SageMaker HyperPod on Amazon EKS that directs inference requests using live queue, cache and model-serving…
Cohere detailed a hardware-aware dynamic speculative-decoding technique it says runs about 23% faster than fixed-K decoding on its Command A model.