Databricks says declarative Spark pipelines cut failed-run compute in agent benchmark
Databricks says a 528-build test found Spark Declarative Pipelines used less compute and code than procedural PySpark, but required more model tokens and did not eliminate silent errors.
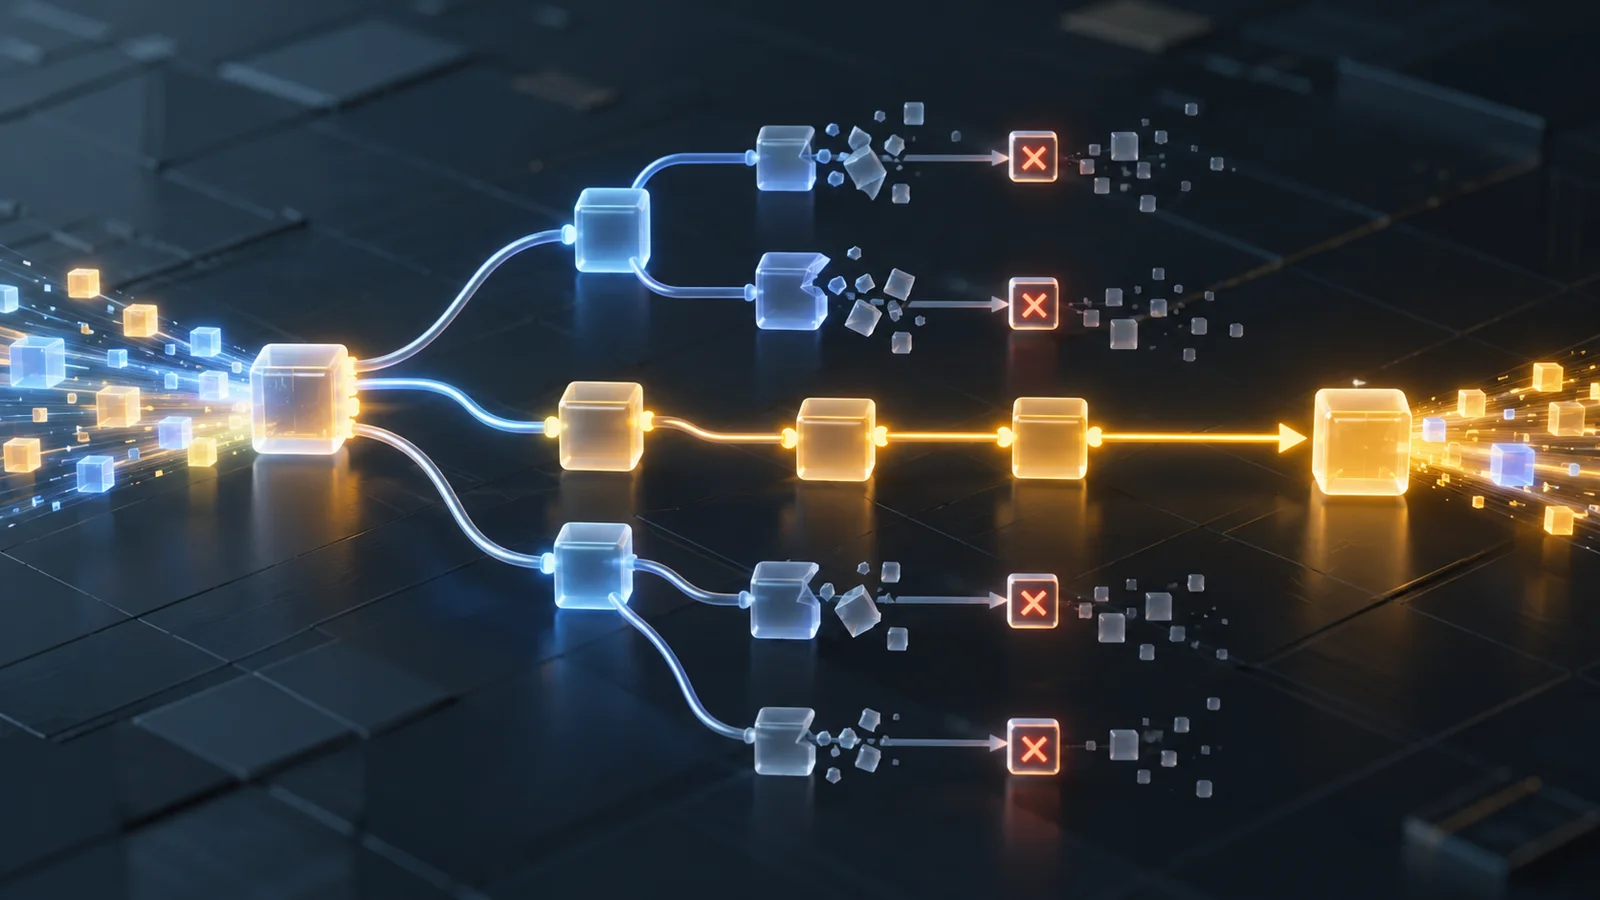
Databricks benchmarked 528 agent-authored data-pipeline builds and reported sharply lower compute use on failed attempts with Spark Declarative Pipelines, along with shorter code than with procedural PySpark. The declarative approach used more model tokens, however, and Databricks’ materials do not show that it reduced silent semantic errors.
The test covered 22 data-engineering tasks, 12 generated input datasets per task and two authoring approaches, producing 264 builds in each arm. Databricks said all builds used Opus 4.8. Each task specified required tables, columns and data types, and an automated grader checked the output without knowing which approach produced it. Declarative builds first passed through Spark’s dry-run validation; failed builds could be revised up to a fixed iteration limit.
Output completion was similar. Databricks reported that 255 of 264 procedural builds and 258 of 264 declarative builds reached completed or materialized output. The study supplement separates completion from correct completion: after excluding completed outputs with silent defects, it lists 182 procedural builds and 172 declarative builds as correct completions.
Pre-execution validation was the test’s main dividing line. Apache Spark’s programming guide says a spark-pipelines dry-run checks pipeline code without reading or writing data and can catch syntax, analysis and graph-validation errors before a full run. Databricks’ blog says 55 declarative builds stopped before producing output. The linked working paper counts 79 structural defects intercepted across iterations, compared with zero at a pre-execution gate for procedural PySpark, which had no equivalent gate. Those figures use different units and are not interchangeable.
Across the benchmark, Databricks reported 596 executor-seconds for procedural runs and 17 for declarative runs, about a 34-fold difference. A failed procedural run used as much as about 521 executor-seconds, compared with about 0.5 executor-seconds for a rejected declarative attempt. The paper says the compute comparison was measured separately on one uniform Amazon EKS Spark Connect cluster; the safety, token and code measurements were run locally.
That compute saving came with a model-usage tradeoff. Databricks said declarative builds used about 2.3 times as many LLM tokens, with a median build cost of roughly $0.50 against $0.26 for procedural builds at the Opus 4.8 list rates used in the study.
For completed builds, the declarative approach had a median 64 lines of code, versus 131 for procedural PySpark, a 51% reduction, according to Databricks. The company also reported an approximately 44% smaller abstract-syntax tree. The paper’s mean figures were 67.9 lines for declarative builds and 134.0 for procedural builds, about 49% fewer; its mean and the blog’s median describe separate summaries. Databricks also said 19 procedural builds loaded data into memory and processed it row by row, a pattern absent from the declarative builds.
The blog described silent-error rates as broadly similar: 73 of 264 procedural builds, or 27.7%, and 85 of 264 declarative builds, or 32.2%. It said the rates were within roughly 15% of each other and that the gap was too small to treat as a real difference.
The current linked paper does not fully match that account. It lists 86 declarative silent defects, or 32.6%, and calls the raw difference statistically significant before tracing much of it to a missing timezone-handling idiom in the declarative skill. A 36-cell skill-swap removed seven timezone defects, but the supplement says the full post-swap completion rate was not remeasured. The study otherwise fixed one model, used synthetic event streams with injected defect traps and gave the declarative arm an API skill that the procedural arm did not need.
More news
Databricks says kernels and packing cut Qwen fine-tuning time sixfold
Databricks details AI Runtime workflow for agent-led model research
Databricks opens Private Network Gateway public preview on Azure