Google outlines verifiable private federated learning system for Gboard
Google Research says Gboard has deployed a federated-learning system that lets outsiders verify which protected server workloads can process encrypted user data.
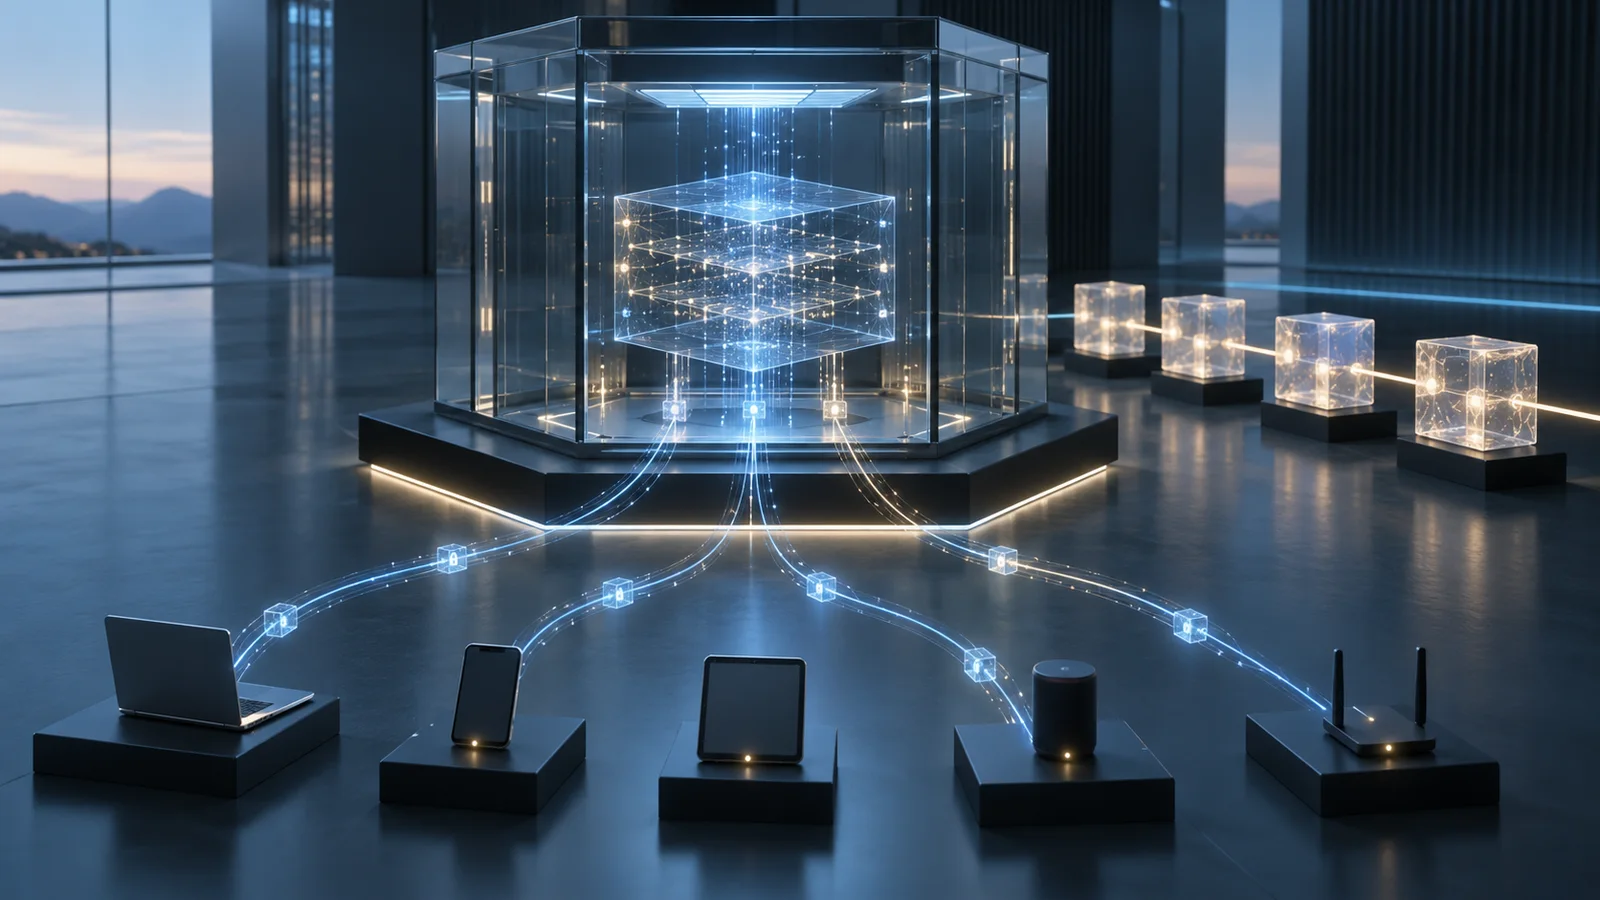
Google Research has outlined a federated-learning system that encrypts training examples on users’ devices and restricts their server-side processing to approved workloads running in trusted execution environments. The company says Gboard has deployed the system for English and Japanese next-word prediction models.
The system governs privacy in federated model training. It is distinct from synthetic-data work such as Google Research’s separate answer-first tool-use data generation project.
Google attributes stronger privacy guarantees and improved accuracy to the deployments, but its public material does not identify exact rollout dates, model versions or the number of models in production. The available performance and privacy comparisons come from Google Research and a Google-authored paper, not an independent audit or reproduction.
A trusted execution environment, or TEE, is an isolated part of a server designed to shield code and data from the rest of the machine. In Google’s architecture, a device encrypts its training examples locally and binds the upload to an access policy. A key-management service inside a TEE releases the decryption key only when remote attestation shows that the requesting root or worker workload matches the binaries and configuration authorized by that policy.
The root TEE runs the published Python training program and delegates parallel computation to worker TEEs over encrypted channels after checking their attestations. The paper says the access policy includes the permitted Python program and hashes for the root and worker binaries, preventing the key-management service from releasing keys to a differently measured workload.
Google says devices also require the key-management software and access policies to appear in Rekor’s public record. Rekor is an append-only, cryptographically auditable transparency log, so outside observers can inspect the set of recorded workloads that could receive access. Google Research also says the key-management and data-processing binaries can be reproduced from the open-source Confidential Federated Compute repository, giving auditors a way to connect reviewed source code with the binary hashes used in attestation. This research did not independently rebuild those binaries or compare them with a production attestation record.
The published Python program contains privacy-relevant logic, including limits on the zero-concentrated differential privacy budget. Google says workload operators receive only metrics and differentially private model weights. The architecture may load proprietary model parameters or per-user processing information at runtime, but Google’s external privacy claim depends on all privacy-relevant behavior remaining fixed in the published program and on auditors being able to inspect how those additional inputs are used. The paper does not claim a complete correctness proof for every algorithm and system component.
In a Japanese-model experiment, Google reports that its previous workflow incorporated 8.5 million of 35.5 million available devices over 3,000 rounds and 38 days. The TEE workflow collected and used 17.8 million uploads after about six days of collection. For an English-model A/B test with 3.5 million devices in each arm, the paper says the best TEE-trained arm used a zCDP budget of 0.215, compared with 0.641 for the production model when adjusted to the same mechanism; typing-speed and suggestion-modification measures were neutral. Google also reports that the tested English model trained in three weeks, versus two months for the previous production model.
The design still carries the limits of confidential computing. Google identifies stronger defenses against side-channel observations as future work, while a separate 2026 study of confidential virtual machines documented page-table and cache leakage outside major confidential-VM threat models. The Google-authored paper says the reported system trained models with up to 10 million parameters and used as few as 14 machines; substantially larger models may require accelerator-enabled TEEs and further work on communication bottlenecks.
More news
MIT and Sakana AI propose SIFT to prioritize coding-agent benchmark runs
AWS details multi-turn RL workflow for SageMaker search agents
NetApp puts approval gates around Workload Factory AI agents