GS Caltex puts SageMaker Canvas models into production pipelines
GS Caltex moved no-code models built by process engineers in SageMaker Canvas into governed production workflows that run scheduled batch inference, AWS said.
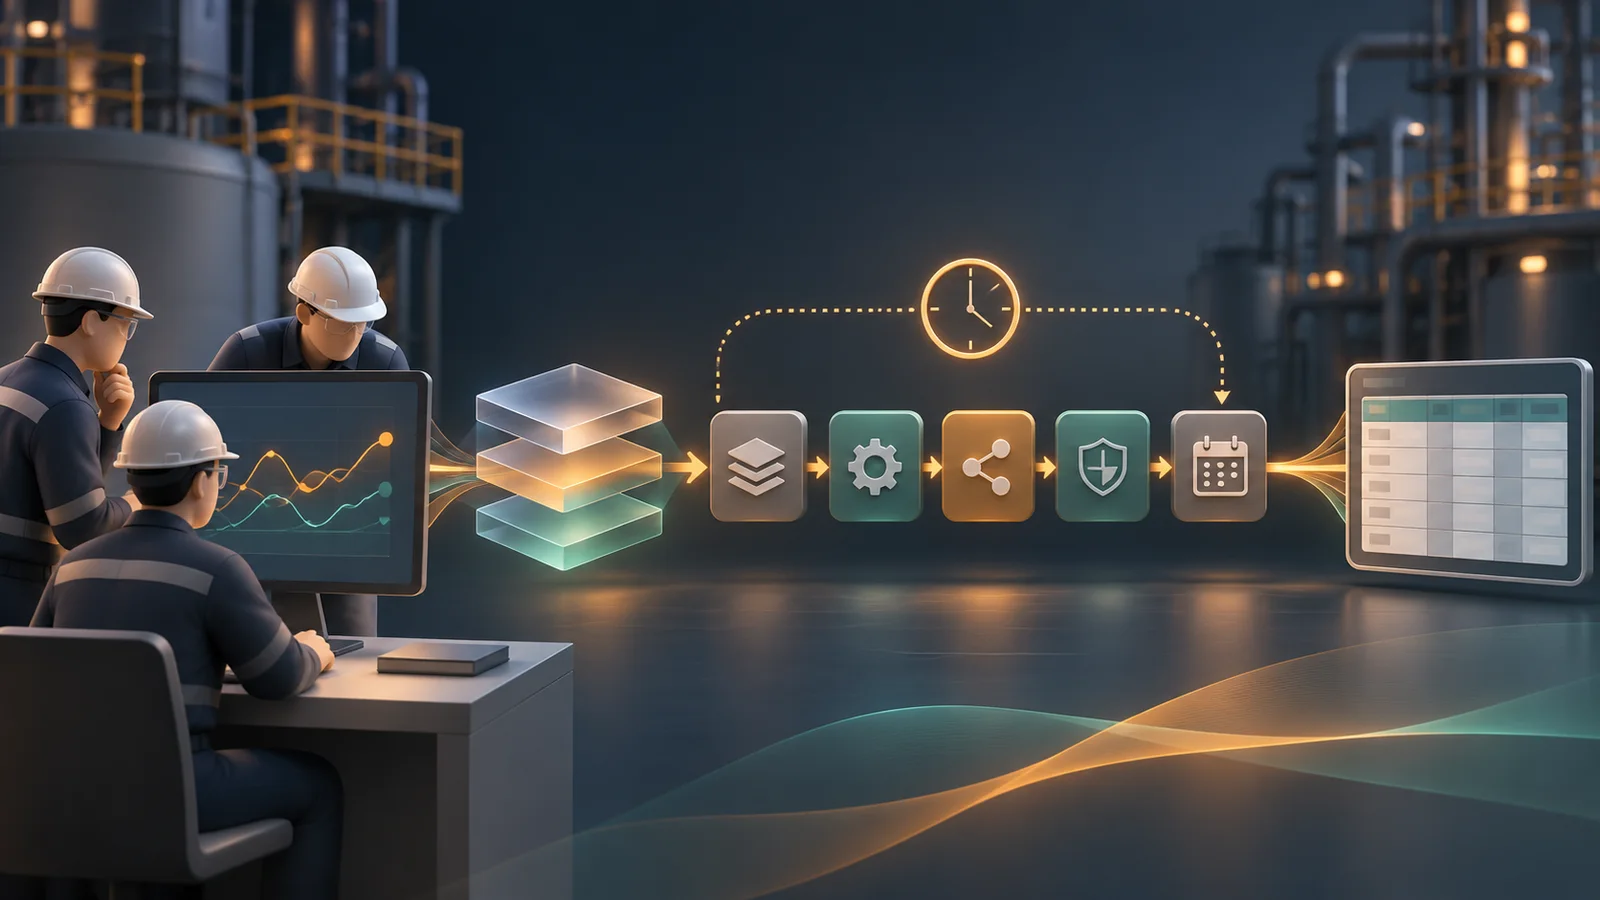
GS Caltex connected models built by process engineers in Amazon SageMaker Canvas to managed production workflows in SageMaker Pipelines, AWS said in a case study published Nov. 13. The arrangement lets process engineers build and validate models without code, while ML engineers control production configuration, approval, deployment and scheduled inference.
GS Caltex runs batch inference every 30 minutes, according to AWS. In the architecture AWS described, an Amazon EventBridge rule starts a SageMaker Pipeline. The pipeline reads and writes data in Amazon S3 and invokes SageMaker Processing and Batch Transform jobs. AWS presented these scheduled jobs, which release compute after each run, as an alternative to a continuously running inference endpoint.
This is not a one-click handoff from Canvas. ML engineers set production data paths, provide model configuration, connect preprocessing and inference jobs, and write the code that ties approval and scheduling to the workflow. The pipeline reuses the Data Wrangler preprocessing flow and trained model that process engineers validated in Canvas, with engineers adapting environment-specific paths and settings. Learned preprocessing values are reused rather than fitted again for each inference batch.
The inference pipeline follows five ordered steps: prepare the input, run the Canvas preprocessing flow, remove the target column and CSV header, execute Batch Transform with the approved model, and combine the predictions with the preprocessed data.
Validated Canvas model versions go into SageMaker Model Registry with model files, inference configuration and evaluation results for ML-engineer review. AWS documentation allows Canvas-built models to be registered for production MLOps, and an earlier AWS guide shows how to move Canvas models through Model Registry.
The GS Caltex reference implementation checks that a model package is complete and approved before creating the SageMaker model resource. AWS cautioned that Model Registry records approval status but does not enforce the check for every inference request, leaving that safeguard to deployment code. ML engineers can inspect pipeline-step status and CloudWatch logs. The case study also recommends alerts for job failures and delays, along with checks for schema mismatches, row alignment, overlapping runs, runtime and cost before the schedule is enabled.
GS Caltex said the workflow cut model deployment time for ML engineers to a few hours from about a week. The company also reported meaningful inference-cost savings from scheduled batch jobs, but the AWS case study supplied no amount, percentage, baseline or measured usage data. The public reference code uses a sample loan-classification model, not a disclosed copy of the company’s production workload. AWS did not identify GS Caltex’s industrial process, model type, workload size, facilities or model-quality results.
More news
IBM expands Apptio with AI cost and value-management tools
A&O Shearman values AI commitment at $1.1 billion, mostly in lawyer time
IBM says sovereignty confidence is running ahead of proof