MBZUAI and Khalifa University researchers introduce FaceGuardian for identity-safe image editing
Researchers at MBZUAI and Khalifa University say FaceGuardian keeps protected source photos visually similar while reducing identity preservation in later diffusion edits.
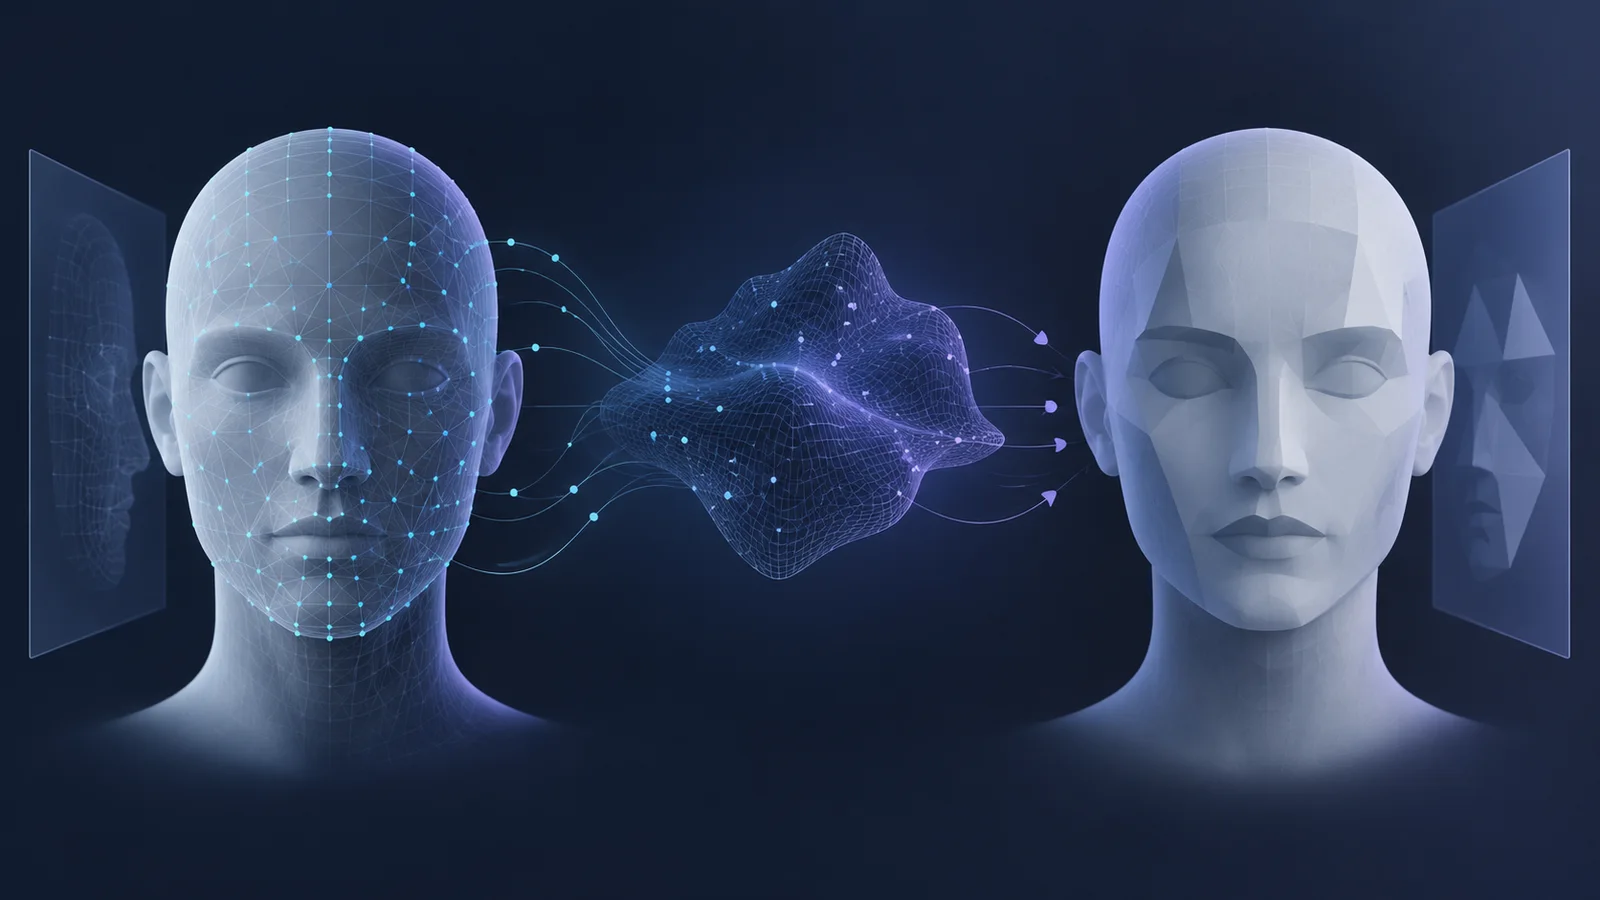
Researchers at MBZUAI and Khalifa University introduced FaceGuardian, a defense designed to stop diffusion-model edits from preserving the biometric identity in a source photo.
The paper appears in the official IEEE SaTML 2026 program. MBZUAI and coauthor Hashmat Shadab Malik say it won the Best Paper Award at the LifeGenIP workshop at ECCV 2026. The LifeGenIP schedule lists the paper for an oral presentation on September 8 and includes a Best Paper Award ceremony, but it does not identify the winner.
FaceGuardian works in a learned, low-dimensional representation of realistic facial features, which the researchers call the semantic manifold, instead of adding noise directly to image pixels. MBZUAI says the researchers first translate a face into a StyleGAN latent code and fine-tune the generator for hundreds of steps to reconstruct the image. They then freeze StyleGAN and optimize only the code for about 50 steps. The resulting protected image is intended to remain visually similar to the person while causing later diffusion edits to lose that person’s biometric identity.
In tests described by MBZUAI, the researchers edited celebrity-dataset images with InstructPix2Pix and LEDITS++. They measured similarity to the originals with a face-recognition, or FR, score, where a lower score indicated stronger identity disruption.
On one dataset, the researchers reported an FR score of 0.272 for FaceGuardian, compared with 0.315 for the next-best method and 0.833 for unprotected images. After compression, they reported 0.361 for FaceGuardian and 0.709 for FaceLock, the next-best method in that comparison. MBZUAI also says the method remained effective after resizing.
The paper abstract says the authors observed up to a 12% FR-score improvement over recent methods across multiple prompts and real-world degradations, and that the method remained resilient to input transformations. The results have not been independently reproduced in the sources reviewed.
Lead author Fahad Shamshad told MBZUAI that the tested diffusion models were open source and the experiments used a gray-box setting. Applying FaceGuardian to closed models and video remains future work.
More news
Apple study finds independent token sampling can distort distributions
Google Research introduces Diffusion Controller to steer image generation
Google Research distills query fan-out into a 53.9-million-parameter retriever