MBZUAI and Inception42 launch six Jais 3 models and Jais-ASR
MBZUAI’s Institute of Foundation Models and Inception42 launched six Jais 3 text models plus Jais-ASR for Arabic-language writing, speech and agent workflows.
MBZUAI’s Institute of Foundation Models and Inception42 launched six Jais 3 text models and Jais Speech on October 15 for Arabic writing, speech and agent workflows. All six text-model repositories and the speech releases were available on Hugging Face when checked that day, giving developers immediate access to the model files.
The text fleet includes dense models with 0.9 billion, 3.7 billion, 7 billion and 32 billion parameters; a 36B-A4B model with 4 billion active parameters; and a 375B-A23B model with 23 billion active parameters. IFM describes the 36B model as combining mixture-of-experts layers with Mixture-of-Values Attention, while the 375B model uses a mixture-of-experts architecture. For readers following the university’s broader work, DataPhoenix recently covered another MBZUAI model project.
The developers say Jais 3 was trained for Modern Standard Arabic, Emirati and Egyptian dialects, Arabizi, translation, diacritics and Arabic cultural subject matter. IFM also says the models can connect to tools for multi-step agent workflows, including tool and MCP calls, web search, terminal use, and reading or editing Arabic documents, presentations and spreadsheets. These are developer-described capabilities, not independently tested findings.
The speech component, called Jais-ASR, covers Modern Standard Arabic and dialects across 19 Arab countries, according to IFM. The institute says it also handles Arabic code-switching with English, French, Spanish and Italian, can add diacritics, and identifies the language or dialect. In IFM’s evaluation across six public test sets, Jais-ASR averaged a 22.85% word error rate and an 8.37% character error rate, which the institute said were the lowest averages in its comparison. The result has not been independently replicated.
IFM and Inception42 also said the 375B model achieved the highest Arabic average among the open models they compared. They reported that the 3.7B model led their small-model comparison, while the 7B and 32B models led the compared groups at their respective sizes. Those benchmark results came from the developers’ own evaluations and have not been independently replicated.
The Jais 3 collection displayed all six text-model repositories when observed, while the Jais Speech collection displayed Jais-ASR and five alternate speech-model formats. IFM says the text checkpoints and code use the Apache 2.0 license, and the 32B model card provides instructions for serving the model with vLLM or SGLang. IFM also released five training-stage checkpoints for each text-model size, along with recipes, logs, sample data and evaluation materials.
The official sources differ on context length. MBZUAI’s announcement says all six text models support 512,000 tokens, while IFM’s technical post lists a 128K-token window for the 0.9B model and 512K for the other five.
More news
KineMask gives video models an initial push, then predicts collisions
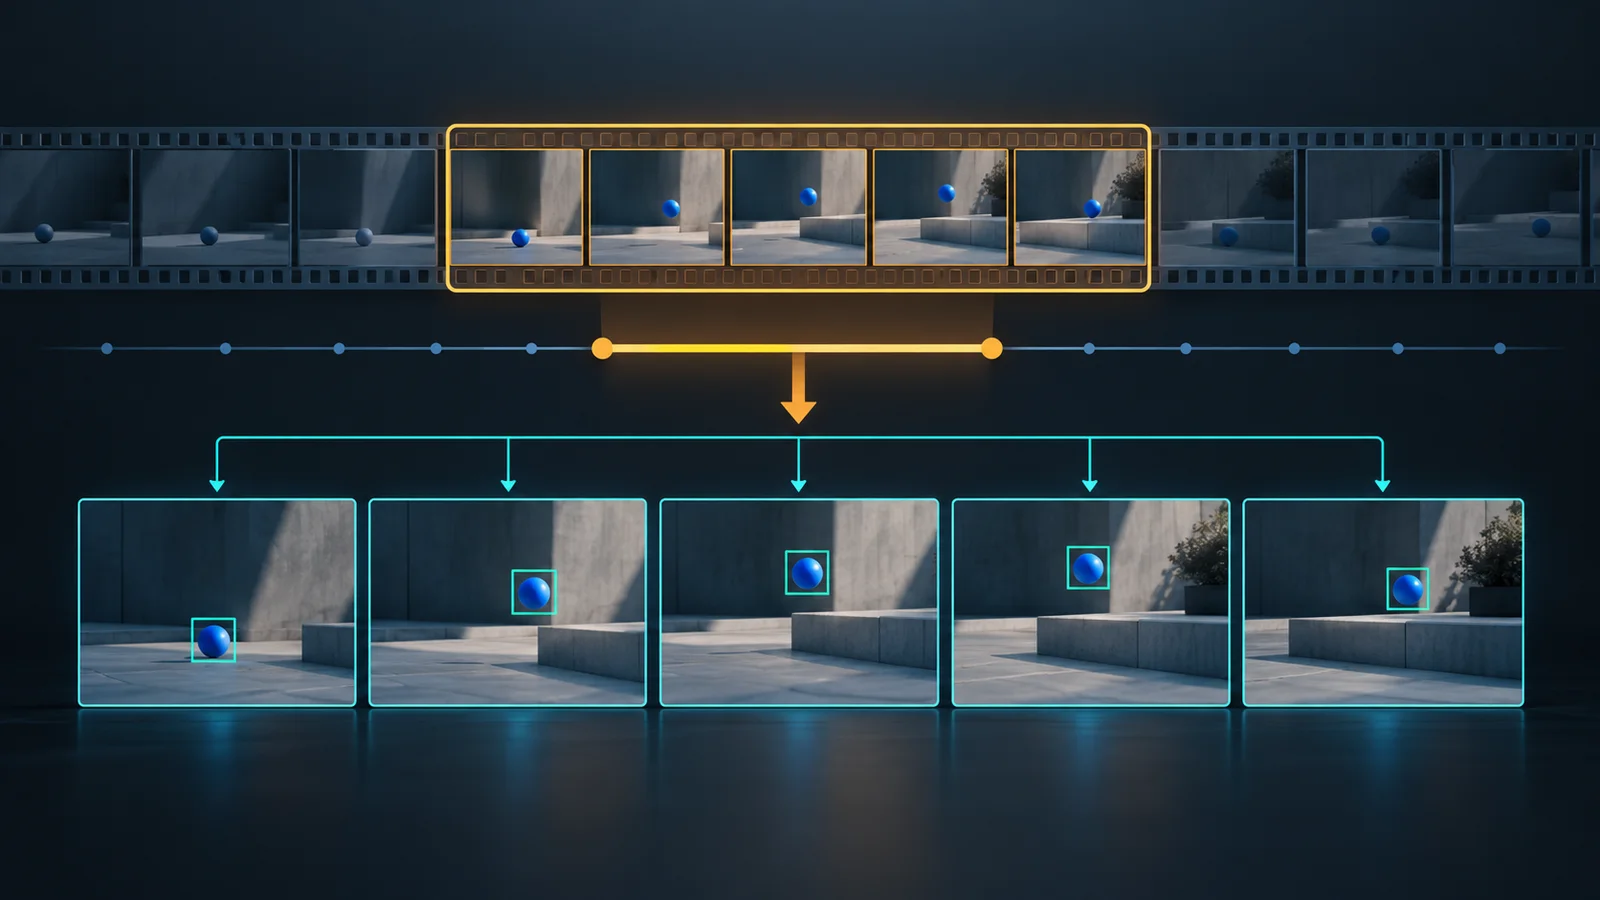
MBZUAI researchers propose parallel decoding to speed video object tracking
MBZUAI and Khalifa University researchers introduce FaceGuardian for identity-safe image editing