NVIDIA releases Dynamo deployment recipes for four Korean open models
NVIDIA released Dynamo recipes for A.X K2, K-EXAONE 2.0, Solar Open 2 and Motif-3, outlining multi-GPU configurations for B200 systems.
NVIDIA released Dynamo-optimized deployment recipes for A.X K2 from SK Telecom, K-EXAONE 2.0 from LG AI Research, Solar Open 2 from Upstage and Motif-3 from Motif Technologies. The configurations provide model-specific starting points for serving the four open models across multiple NVIDIA B200 GPUs.
The recipes are optimized for B200 GPUs and can deliver “up to 2x performance out of the box,” according to NVIDIA, which also said they reduce deployment work. The performance figure is a company claim, not an independently verified benchmark result. NVIDIA’s release does not disclose a workload, baseline, per-model result or test environment.
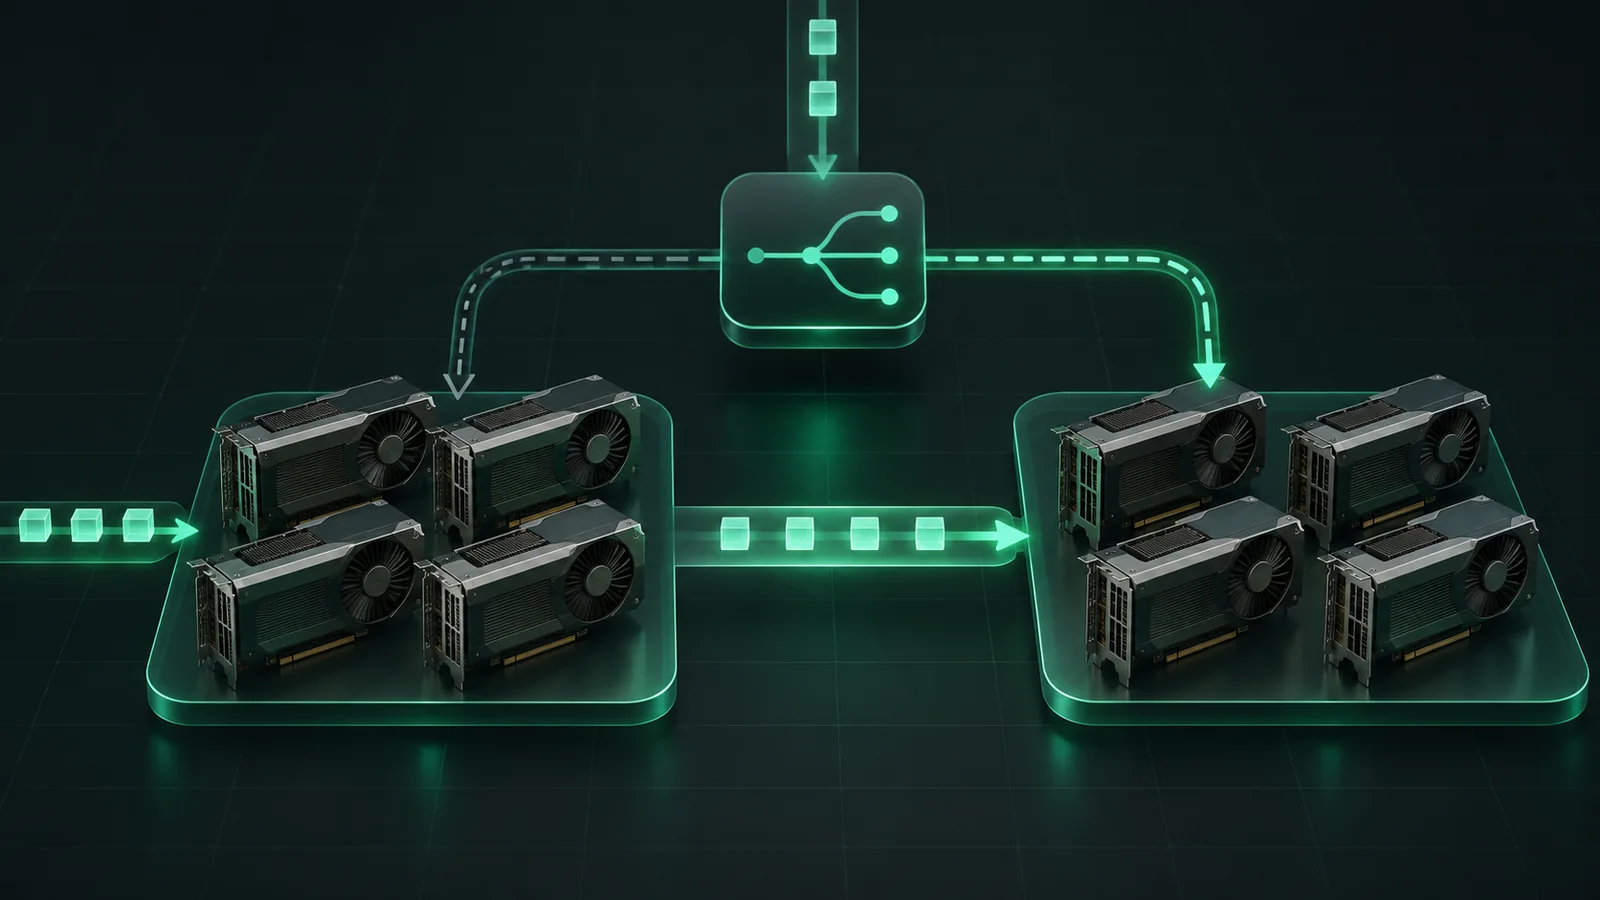
Dynamo is NVIDIA’s open-source distributed inference-serving framework. In an aggregated setup, one worker pool handles both prompt processing and token generation. A disaggregated setup divides those jobs between separate prefill and decode pools; the frontend sends a request to a prefill worker first and then to a decode worker.
Dynamo’s KV-aware router weighs the relevant key-value cache state held by each worker against its decode load, then chooses the lowest-cost worker. A KV cache stores attention state from tokens the model has already processed, so reusing it can avoid repeating part of the computation. Workers can report cache changes to the router over ZMQ or NATS Core. Without those events, the router can estimate cache state from its own routing decisions.
In disaggregated deployments, prefill workers must pass that cache state to the decode workers that continue generation. Dynamo uses the NVIDIA Inference Xfer Library, or NIXL, for these point-to-point transfers. NIXL provides a common interface for moving data across GPU and CPU memory and storage backends, with plugins for transports including UCX.
The live recipe index lists aggregated and disaggregated B200 deployments for each model. A.X K2 uses eight GPUs in aggregated mode or 12 in a two-prefill, one-decode topology. K-EXAONE 2.0 uses four or eight GPUs, respectively; its disaggregated recipe uses NIXL over UCX on InfiniBand RDMA. Solar Open 2 uses four GPUs in aggregated mode or eight with one prefill and two decode workers. Motif-3 uses two GPUs in aggregated mode or eight in a three-prefill, one-decode layout.
The repository currently lists Motif-3 in its experimental section, which it describes as functional but under active development and not yet fully validated for production use.
More news
NVIDIA launches PAIR beta to distribute local AI inference across home PCs
Together AI launches self-tuning compiler for open-model inference
NVIDIA releases Nemotron 3.5 Transcribe and Granary v2