Sakana AI's Fugu Ultra claims top SWE-Bench Pro score, but testers report a real-world gap
Tokyo-based Sakana AI's Fugu Ultra claims a leading 73.7% on SWE-Bench Pro per its own benchmarks, but independent testers reported a real-world performance gap within a day.
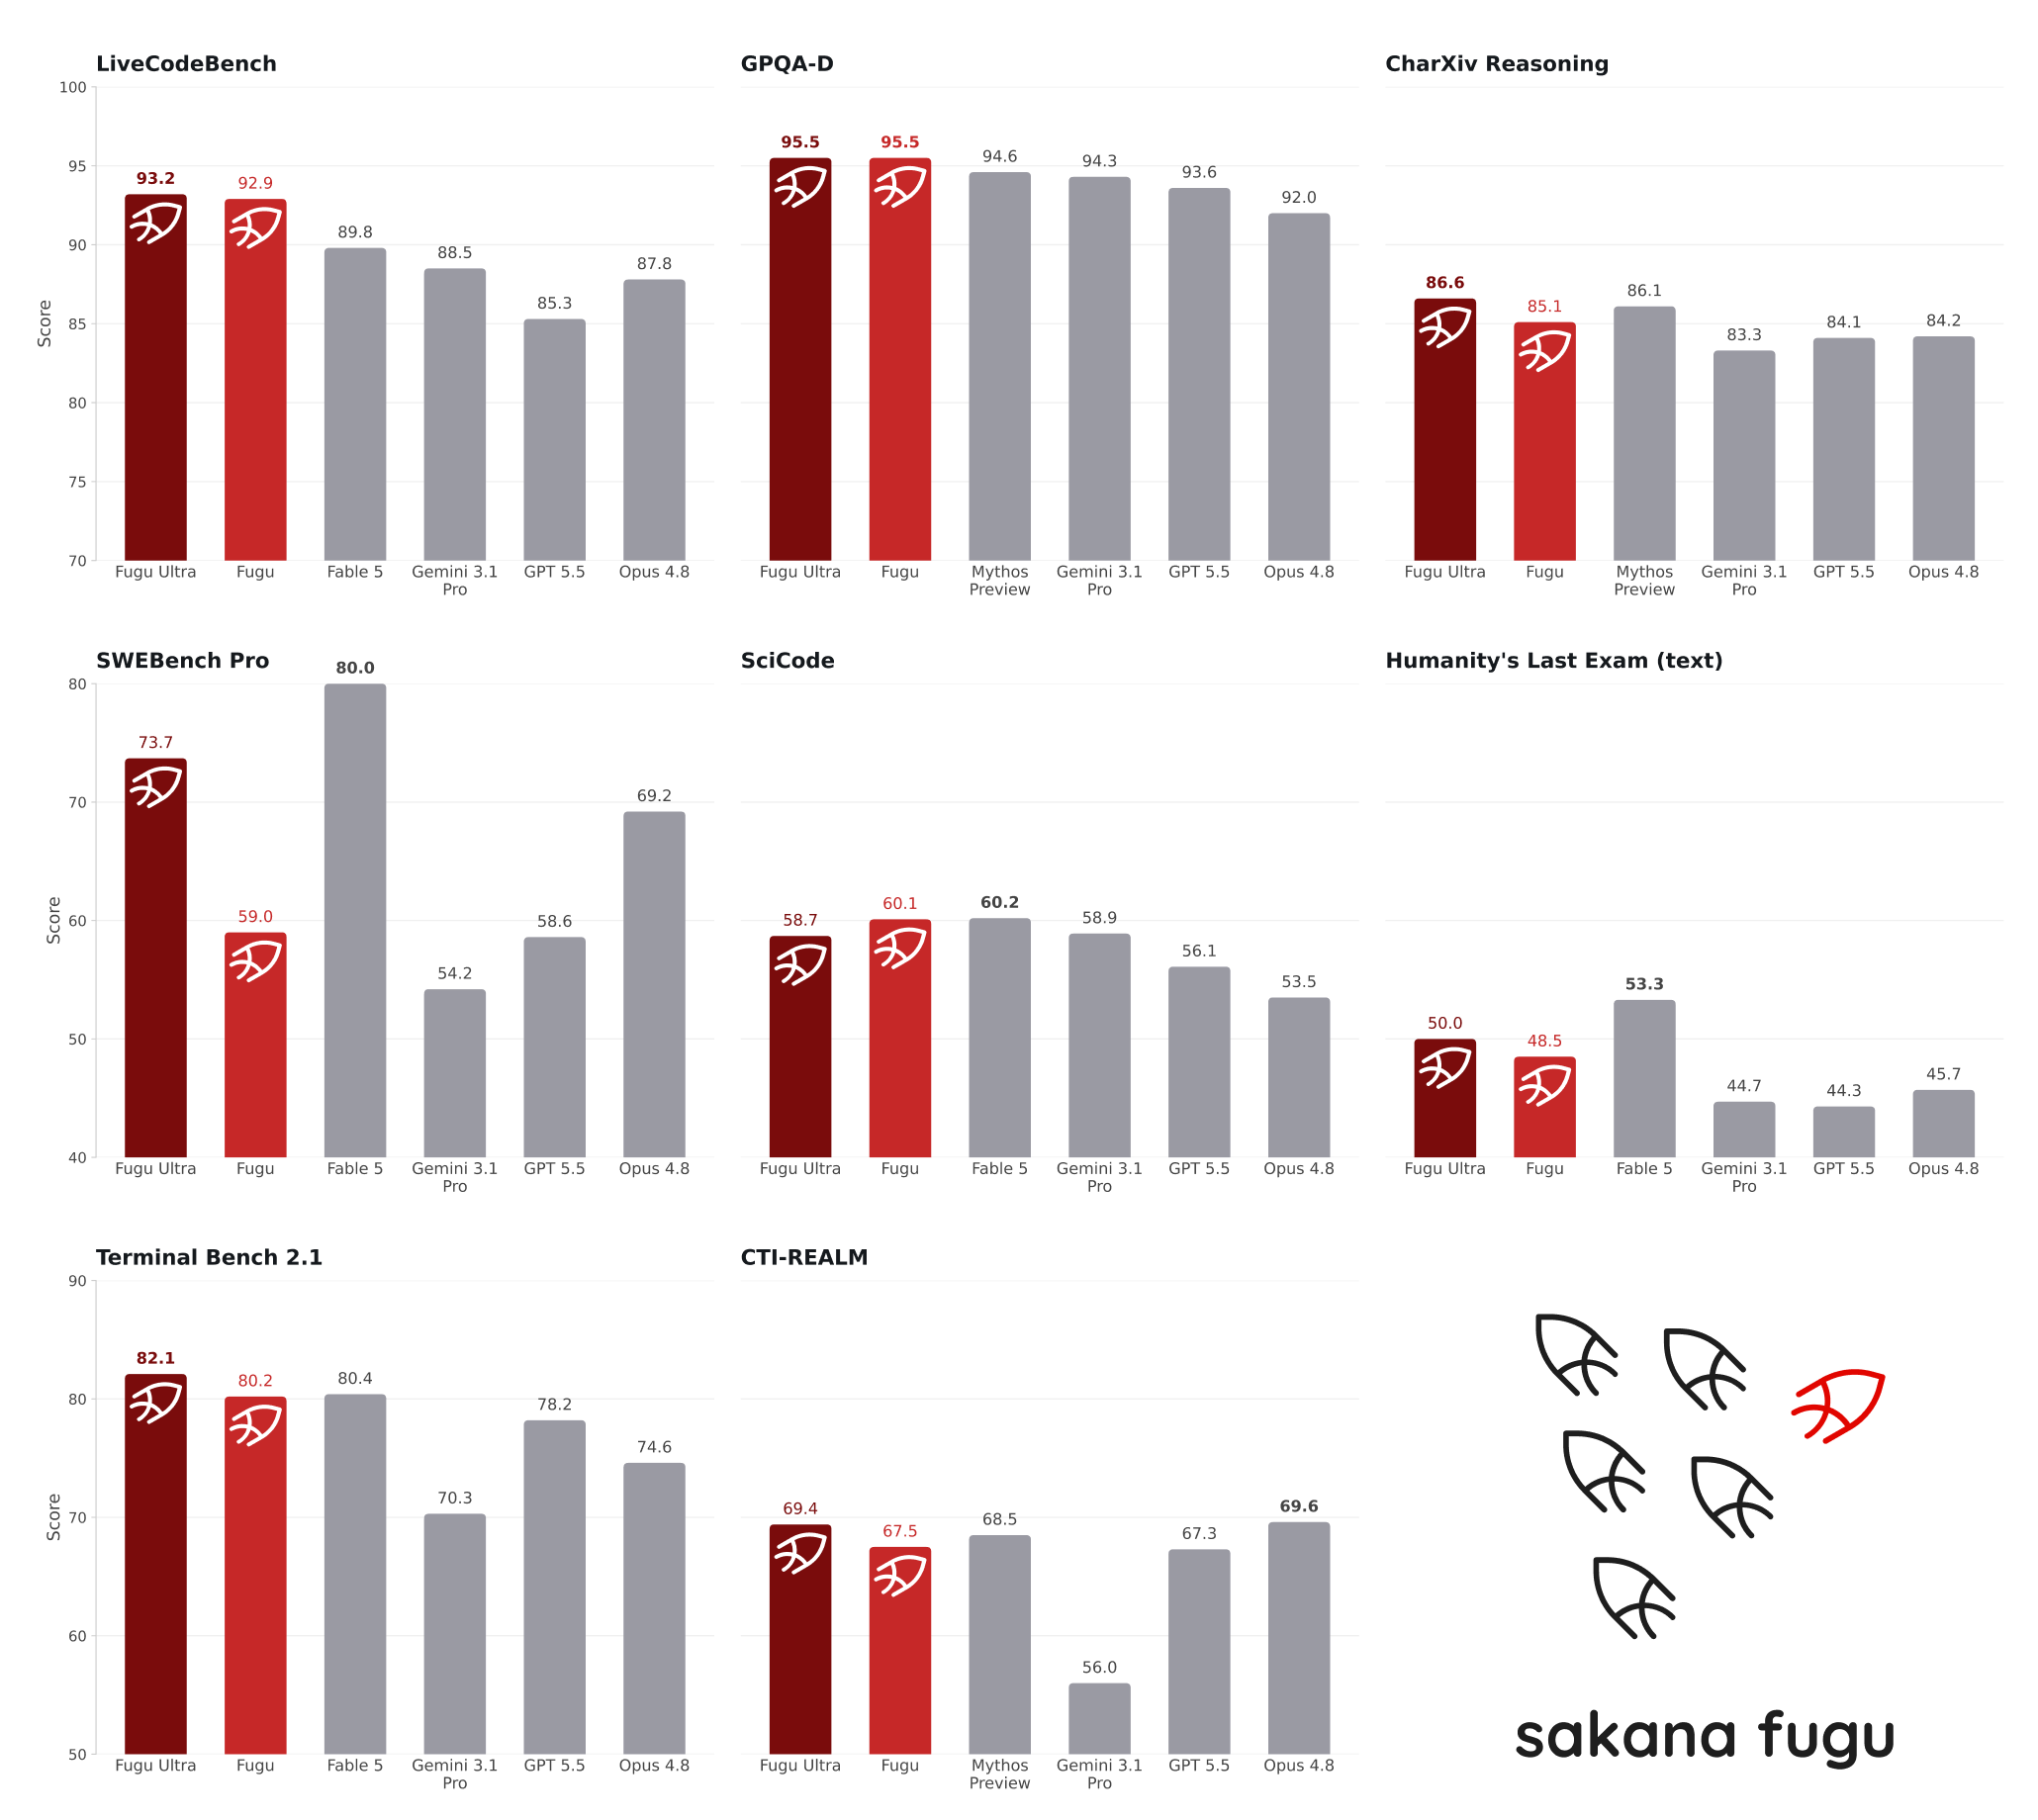
Tokyo-based Sakana AI launched Fugu and Fugu Ultra on June 22, 2026, a multi-agent system that claims a leading 73.7% on the SWE-Bench Pro coding benchmark — a figure independent testers began disputing within a day. The system presents externally as a single foundation model through one OpenAI-compatible API endpoint, Sakana said.
Rather than rely on one large model, Fugu routes each task to a direct answer or to a set of specialist models assembled behind the scenes. Sakana said the orchestration logic draws on two ICLR 2026 papers, TRINITY, an evolved coordinator for language models, and Conductor, which learns to direct agents in natural language. It ships in two forms: Fugu for latency-sensitive everyday tasks and Fugu Ultra for complex, multi-step work where answer quality matters most.
On SWE-Bench Pro, Sakana claims Fugu Ultra scores 73.7%, ahead of Claude Opus 4.8 at 69.2%, GPT-5.5 at 58.6% and Gemini 3.1 Pro at 54.2%. Those results come from Sakana’s own benchmarks and have not been independently verified. Within 24 hours of launch, independent testers led by Wharton professor Ethan Mollick reported a notable gap between the benchmark claims and real-world performance.
Sakana is also selling the design as a hedge against trade restrictions. A compliance mode can exclude specific agent providers, such as US-restricted models, and the company marketed Fugu partly as delivering frontier capability ‘without the risk of export controls.’ It is available by subscription and pay-as-you-go enterprise plans.
The positioning matters as export limits scramble which frontier models companies outside the US can legally use. Whether Fugu Ultra’s orchestration holds up where single models are tested head-to-head, rather than on Sakana’s own harness, will determine if the SWE-Bench Pro claim sticks.

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
