The latest Data Phoenix news tagged vision-language-action-models.
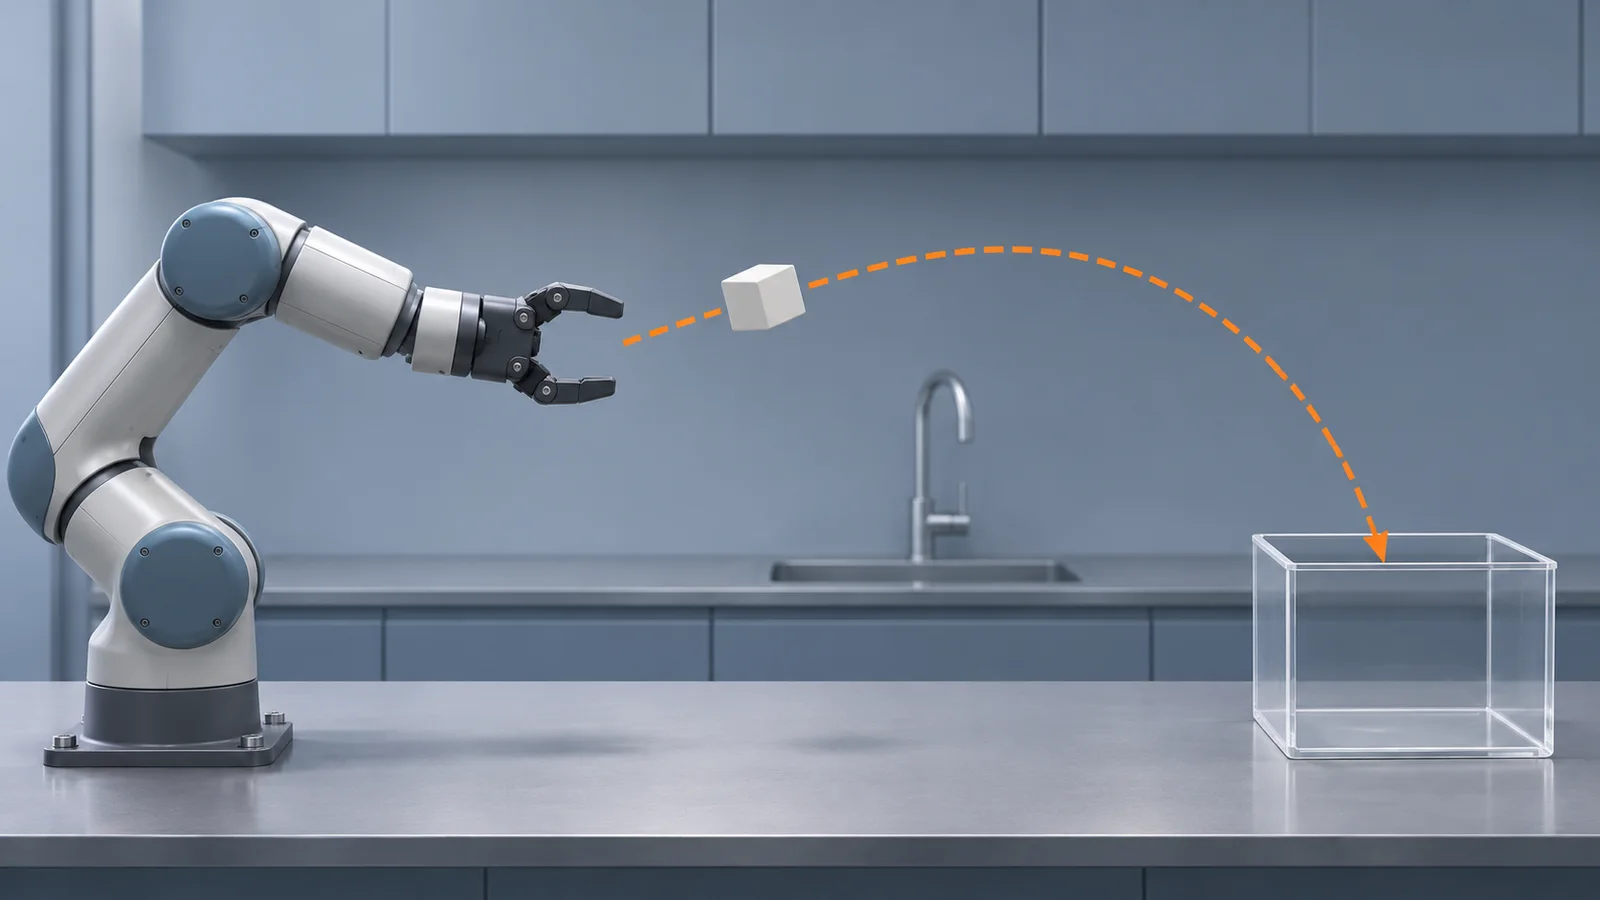
In the PhyDEX paper, three VLA models average less than 3% success on a 35,357-episode throwing benchmark built to test physical reasoning beyond a…
A new preprint introduces State-Aware Fallback Imitation, which trains VLA robot policies to keep holding an object when a prohibited task is…