From Prototype to Production: The Hidden Engineering of AI Inference
Production LLM inference is shaped by memory as much as compute. Roan Weigert explains token processing, KV caching, continuous batching, quantization, model FLOPs utilization, and the trade-offs among local inference, shared APIs, and dedicated GPUs for real workloads.
Efficient LLM serving requires teams to reason about memory pressure, request scheduling, and workload goals together. Roan Weigert follows an inference request from tokenization through generation, then explains how KV caching avoids repeated computation while consuming per-request memory. He compares static and continuous batching, outlines quantization trade-offs, and separates latency and throughput from headline GPU utilization by introducing model FLOPs utilization. There is no universal infrastructure choice: local models, shared APIs, dedicated GPUs, and hybrid workflows suit different volumes, response-time needs, and operating constraints.
More from the studio
 1:02:51Tech Talks
Operationalizing LLMs: From Prototype to Production
Yogiraj Awati shares how Instacart moves LLM applications beyond prototypes through retrieval, offline and online evaluation, guardrails, observability, and provider fallbacks. Two case studies cover recipe ingestion and Carebot support workflows with API-backed actions and human handoff.
 Yogiraj Awati·Sep 17, 2026
 1:17:55Tech Talks
Beyond the DAG: Building Agentic Workflows That Loop, Branch, and Scale
Agentic workflows loop, branch, retry, and trigger new work instead of following a fixed DAG. Santosh Kumar Radha explains how AgentField uses typed functions, structured outputs, stopping and escalation patterns, event triggers, and controls for scaling, identity, and authorization.
 Santosh Kumar Radha·Sep 17, 2026
 48:04Tech Talks
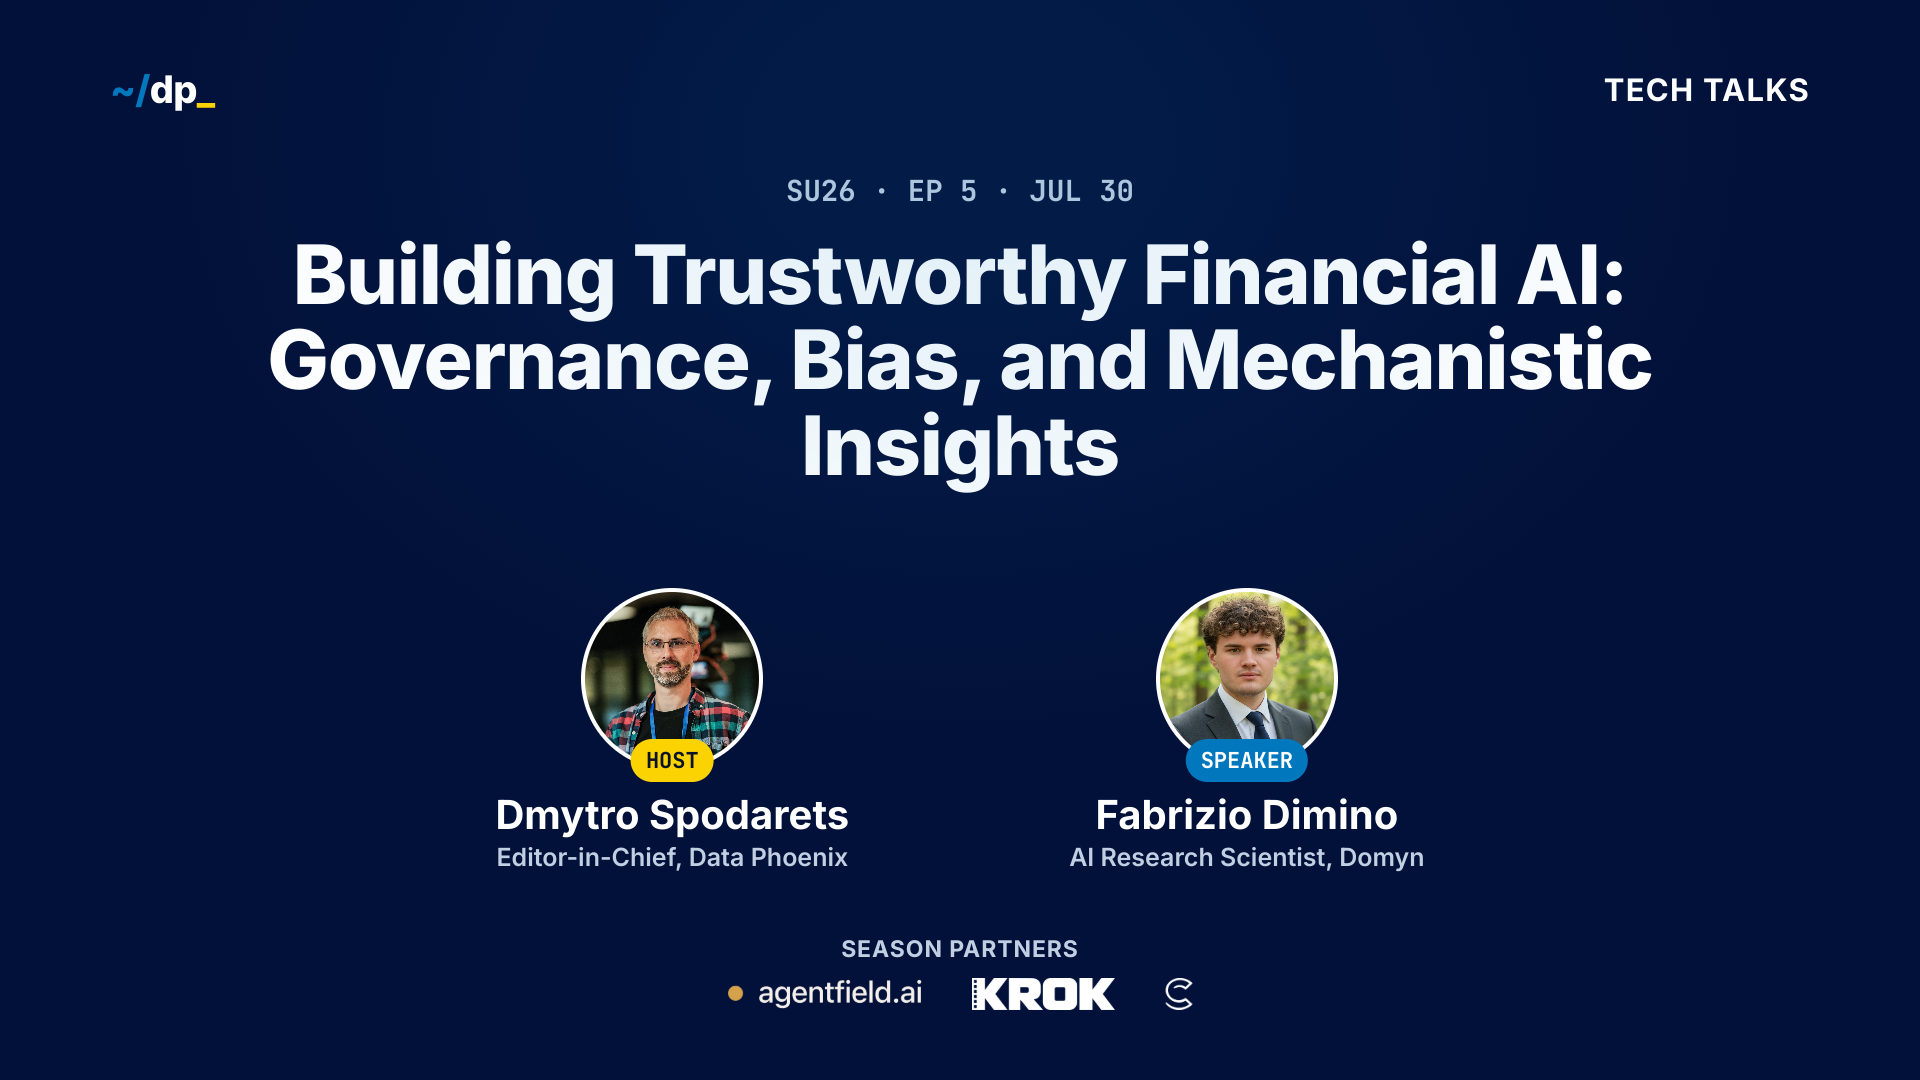
Building Trustworthy Financial AI: Governance, Bias, and Mechanistic Insights
Fabrizio Dimino examines why financial LLM recommendations can change when option order changes. He connects positional-bias tests and mechanistic interpretability with finance-specific red teaming, risk-sensitive scoring, model validation, and AI governance.
 Fabrizio Dimino·Sep 17, 2026