AWS adds distributed KV caching to ElastiCache for self-hosted LLMs
Amazon ElastiCache for Valkey now offers a managed shared cache for reusable prompt state across GPU servers, with integrations through LMCache and availability in 13 AWS regions.
AWS has made distributed key-value caching generally available for Amazon ElastiCache for Valkey, giving operators of self-hosted large language models a managed shared cache for prompt state across GPU servers. The new capability is available in 13 AWS regions.
The cache is meant to reduce repeated prefill work, the stage in which an inference engine processes a prompt and computes the attention state needed to generate tokens. When the same prompt content appears again, AWS says an engine can retrieve that key-value state from the shared cache and process only the new tokens instead of recomputing the cached portion on a GPU.
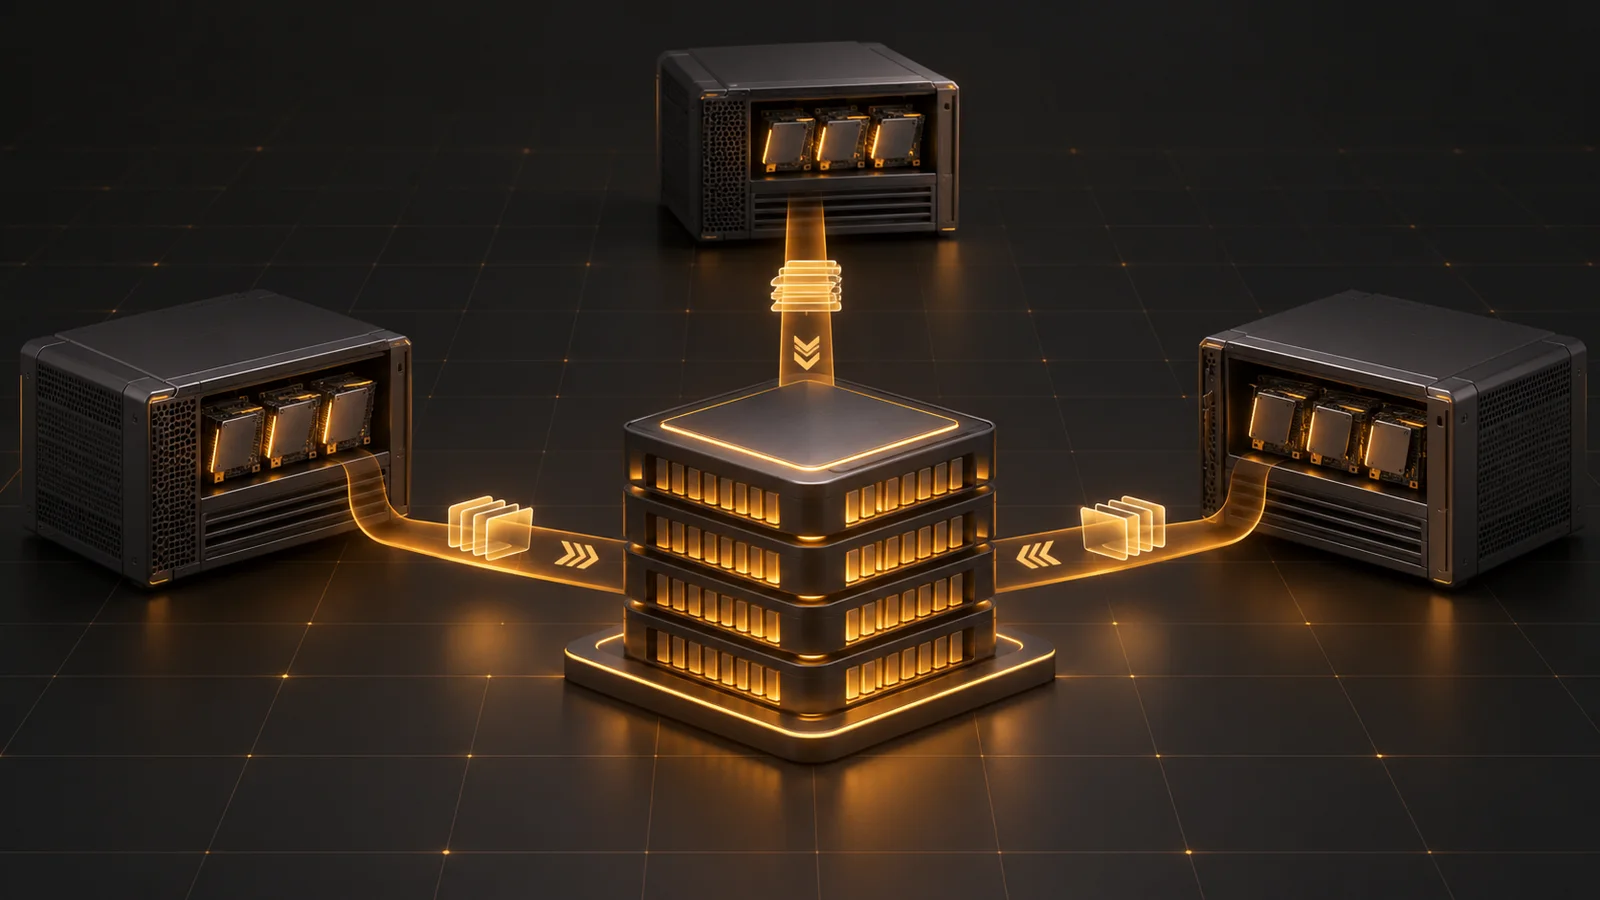
AWS describes the service as an L2 tier behind GPU-memory L0 storage and host memory or local NVMe L1 storage. Under the documented architecture, an open-source LMCache server runs on each GPU host and manages the host’s L1 cache along with the ElastiCache L2 tier through a Valkey adapter. vLLM and SGLang connect to the local LMCache server, allowing cache entries to be reused even when a later request lands on a different inference server.
The launch announcement also names TensorRT-LLM, but the integration carried an availability caveat when AWS published the release. AWS and LMCache documentation said TensorRT-LLM support required LMCache’s development branch or a source build and had not reached a stable release. AWS documentation also said the RDMA and blob-over-TCP transports required LMCache 0.5.8rc1 or later, while the stable release supported TCP transport.
The service requirements narrow the initial deployment options. Customers need a node-based ElastiCache cluster running Valkey 9.1 or later on cache.i8ge.48xlarge nodes; the feature is not available on ElastiCache Serverless. All clients must be in the cluster’s VPC. Clients using RDMA over Elastic Fabric Adapter must also be in the same Availability Zone, while TCP clients can connect across zones.
AWS says its tests showed workload-dependent reductions of up to 40% in inference cost and up to 80% in time to first token. Those figures are AWS benchmark claims, not independently validated results. The company tested selected coding-agent, assistant and long-context question-answering traces with five 2026 models on two to six P6 servers, each containing eight GPUs, and compared local caching with configurations that added one cache.i8ge.48xlarge node through LMCache. AWS says the benefit depends on cache-hit rate and workload behavior, and is limited for short or never-repeated prompts, output-generation-heavy work and diffusion models.
The cache is not durable storage. AWS says it does not persist or replicate cached data and cannot be backed up or restored. A reboot, replacement, patch or failure removes the objects on the affected node, leaving applications to recompute or reload missing state. Each cache.i8ge.48xlarge node offers up to 120 TB of local NVMe instance storage, although some capacity is reserved for the module and filesystem.
AWS lists the feature in US East (N. Virginia and Ohio), US West (Oregon), Europe (Ireland, Frankfurt and Stockholm), and Asia Pacific (Mumbai, Tokyo, Singapore, Sydney, Hong Kong, Malaysia and Thailand).
More news
NVIDIA updates DAQIRI for real-time scientific instruments
AWS turns on continuous SageMaker inference monitoring by default
NVIDIA and Microsoft expand AI stack across Azure, edge systems and Windows PCs