AWS adds managed NVIDIA Dynamo support to SageMaker HyperPod Inference
AWS has brought NVIDIA Dynamo to SageMaker HyperPod Inference, giving users managed paths for multi-node and disaggregated serving alongside HyperPod’s cluster operations.
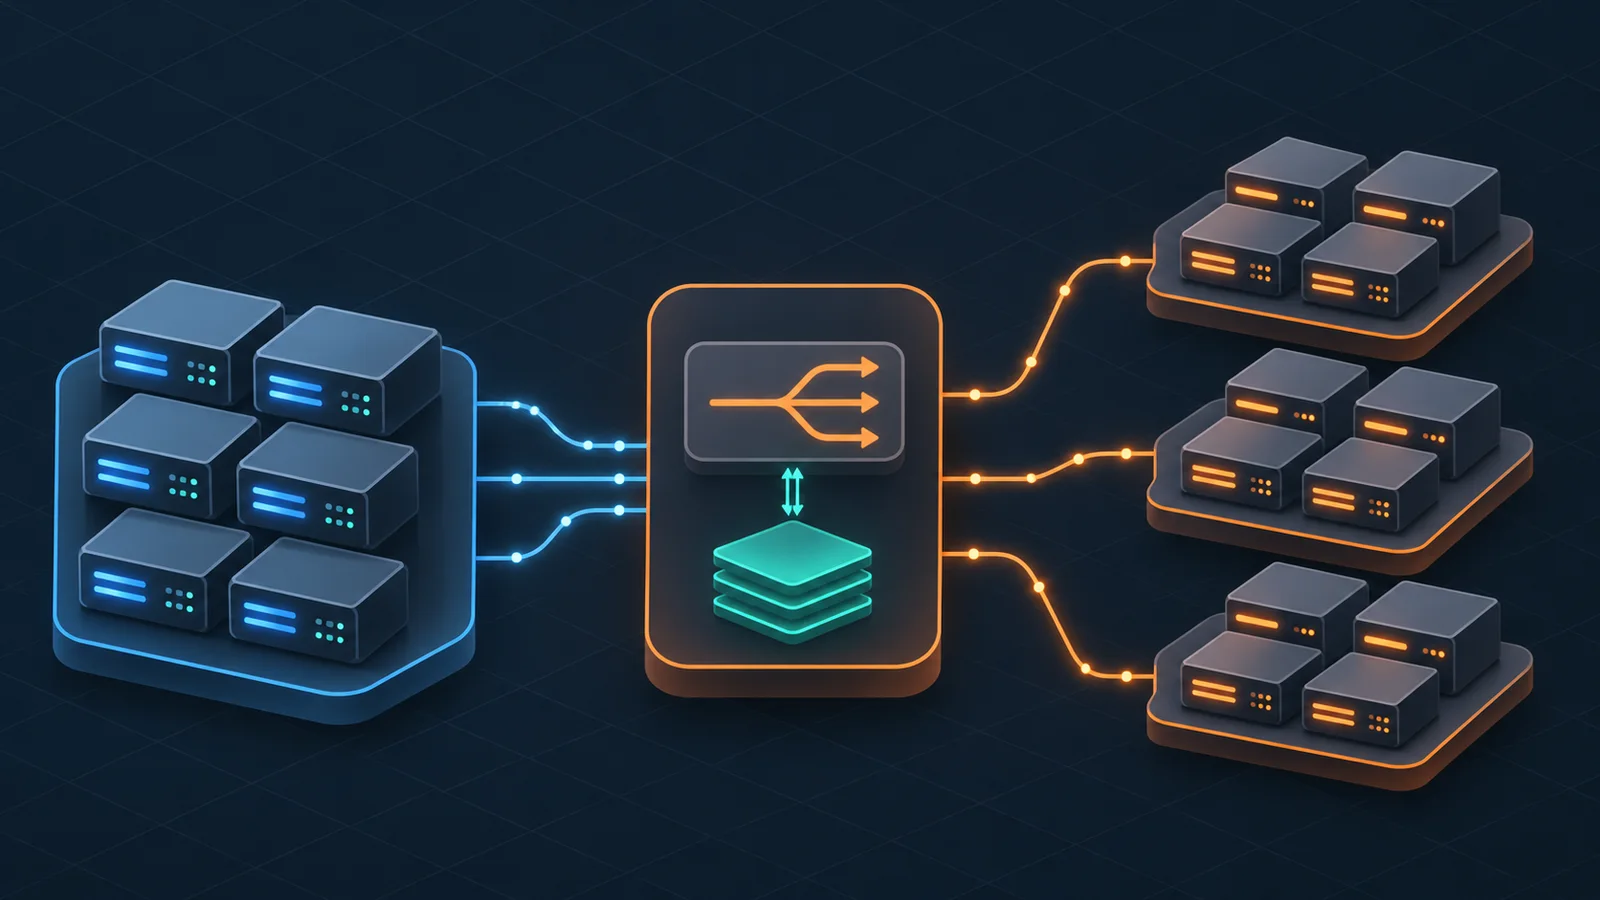
AWS has added managed NVIDIA Dynamo support to Amazon SageMaker HyperPod Inference, pairing Dynamo’s distributed model-serving software with HyperPod’s managed cluster operations. The integration supports workers across Kubernetes nodes and deployments that split prompt processing, or prefill, from token generation, or decode.
For HyperPod users, the result is a managed path to NVIDIA Dynamo for models and workloads that cannot be handled efficiently on one inference node. Dynamo supports vLLM, SGLang and TensorRT-LLM backends. AWS says the HyperPod Inference add-on installs Dynamo’s custom resource definitions and integrated serving and scheduling components. AWS Deep Learning Containers supply the runtime, while the add-on manages compatible component versions.
The add-on gives teams two configuration paths. They can supply a DynamoGraphDeployment manifest for direct control over the frontend, workers and request flow, or use HyperPod’s InferenceEndpointConfig with a dynamoSpec section for managed endpoint setup. AWS says the second path can stage model weights from Amazon S3 or Amazon FSx, manage endpoint registration and TLS, expose an OpenAI-compatible request format through the SageMaker Runtime API, and use KEDA autoscaling for aggregated or disaggregated deployments.
Dynamo’s KV-aware router weighs reusable key-value cache state against projected worker load. A request can go to a worker that already holds part of its prompt state without overloading a cache-rich worker that is already busy. In disaggregated deployments, the router chooses from separate prefill and decode pools, while transfer systems such as NIXL move cache state between them.
AWS also published results from two internal tests. For Qwen3-235B-A22B-FP8 on two p5en.48xlarge instances with 16 H200 GPUs, AWS said qualifying disaggregated-serving runs reached 207 output tokens per second per GPU, compared with 101 for aggregated serving. The retained runs had P90 time to first token below one second and median generation speed of at least 50 tokens per second per user. In a separate Qwen3.5-397B-A17B-FP8 test, AWS said a two-node setup delivered 126.4 output tokens per second per GPU and retained 99.1% of single-node throughput. The opened evidence does not include an independent reproduction of either result.
The announcement did not state pricing for the Dynamo integration or provide a capability-specific regional availability list.
More news
NVIDIA unveils Nemotron science stack and Nsight porting agent
NVIDIA Introduces Four-Node DGX Spark HPC Developer Kit
NVIDIA Specifies 192-CPU Vera Rack for Scientific Computing