News Topic
LLM Evaluation & Leaderboards
News on LLM evaluation and benchmarks, covering new tests, methodology changes, leaderboard results, and whether findings can be reproduced.
Latest
 News
OpenAI releases MentalHealthBench to evaluate AI responses in mental health conversations
 News
Google confirms Gemini accessed three companies during a safety test
 News
Perplexity releases Q2D-Web benchmark for web-scale retrievers
 News
Together AI finds GLM-5.3 Flash 17x cheaper on DeepSWE
 News
Together AI adds endpoint-level A/B testing for production models
 News
Anthropic retunes Claude Fable 5 to cut biology false alarms by 85%
 News
Qwen-Image-3.0-Pro debuts at No. 5 on the Text-to-Image Arena leaderboard
 News
Prime Intellect's open-source Prime Agent tops ARC-AGI-3's human-expert baseline using Opus 5
 News
UK AI Security Institute finds open-weight models now trail closed frontier on cyber by months
 News
Moonshot AI launches Kimi K3, a 2.8-trillion-parameter open-weight model, atop the coding leaderboard
 News
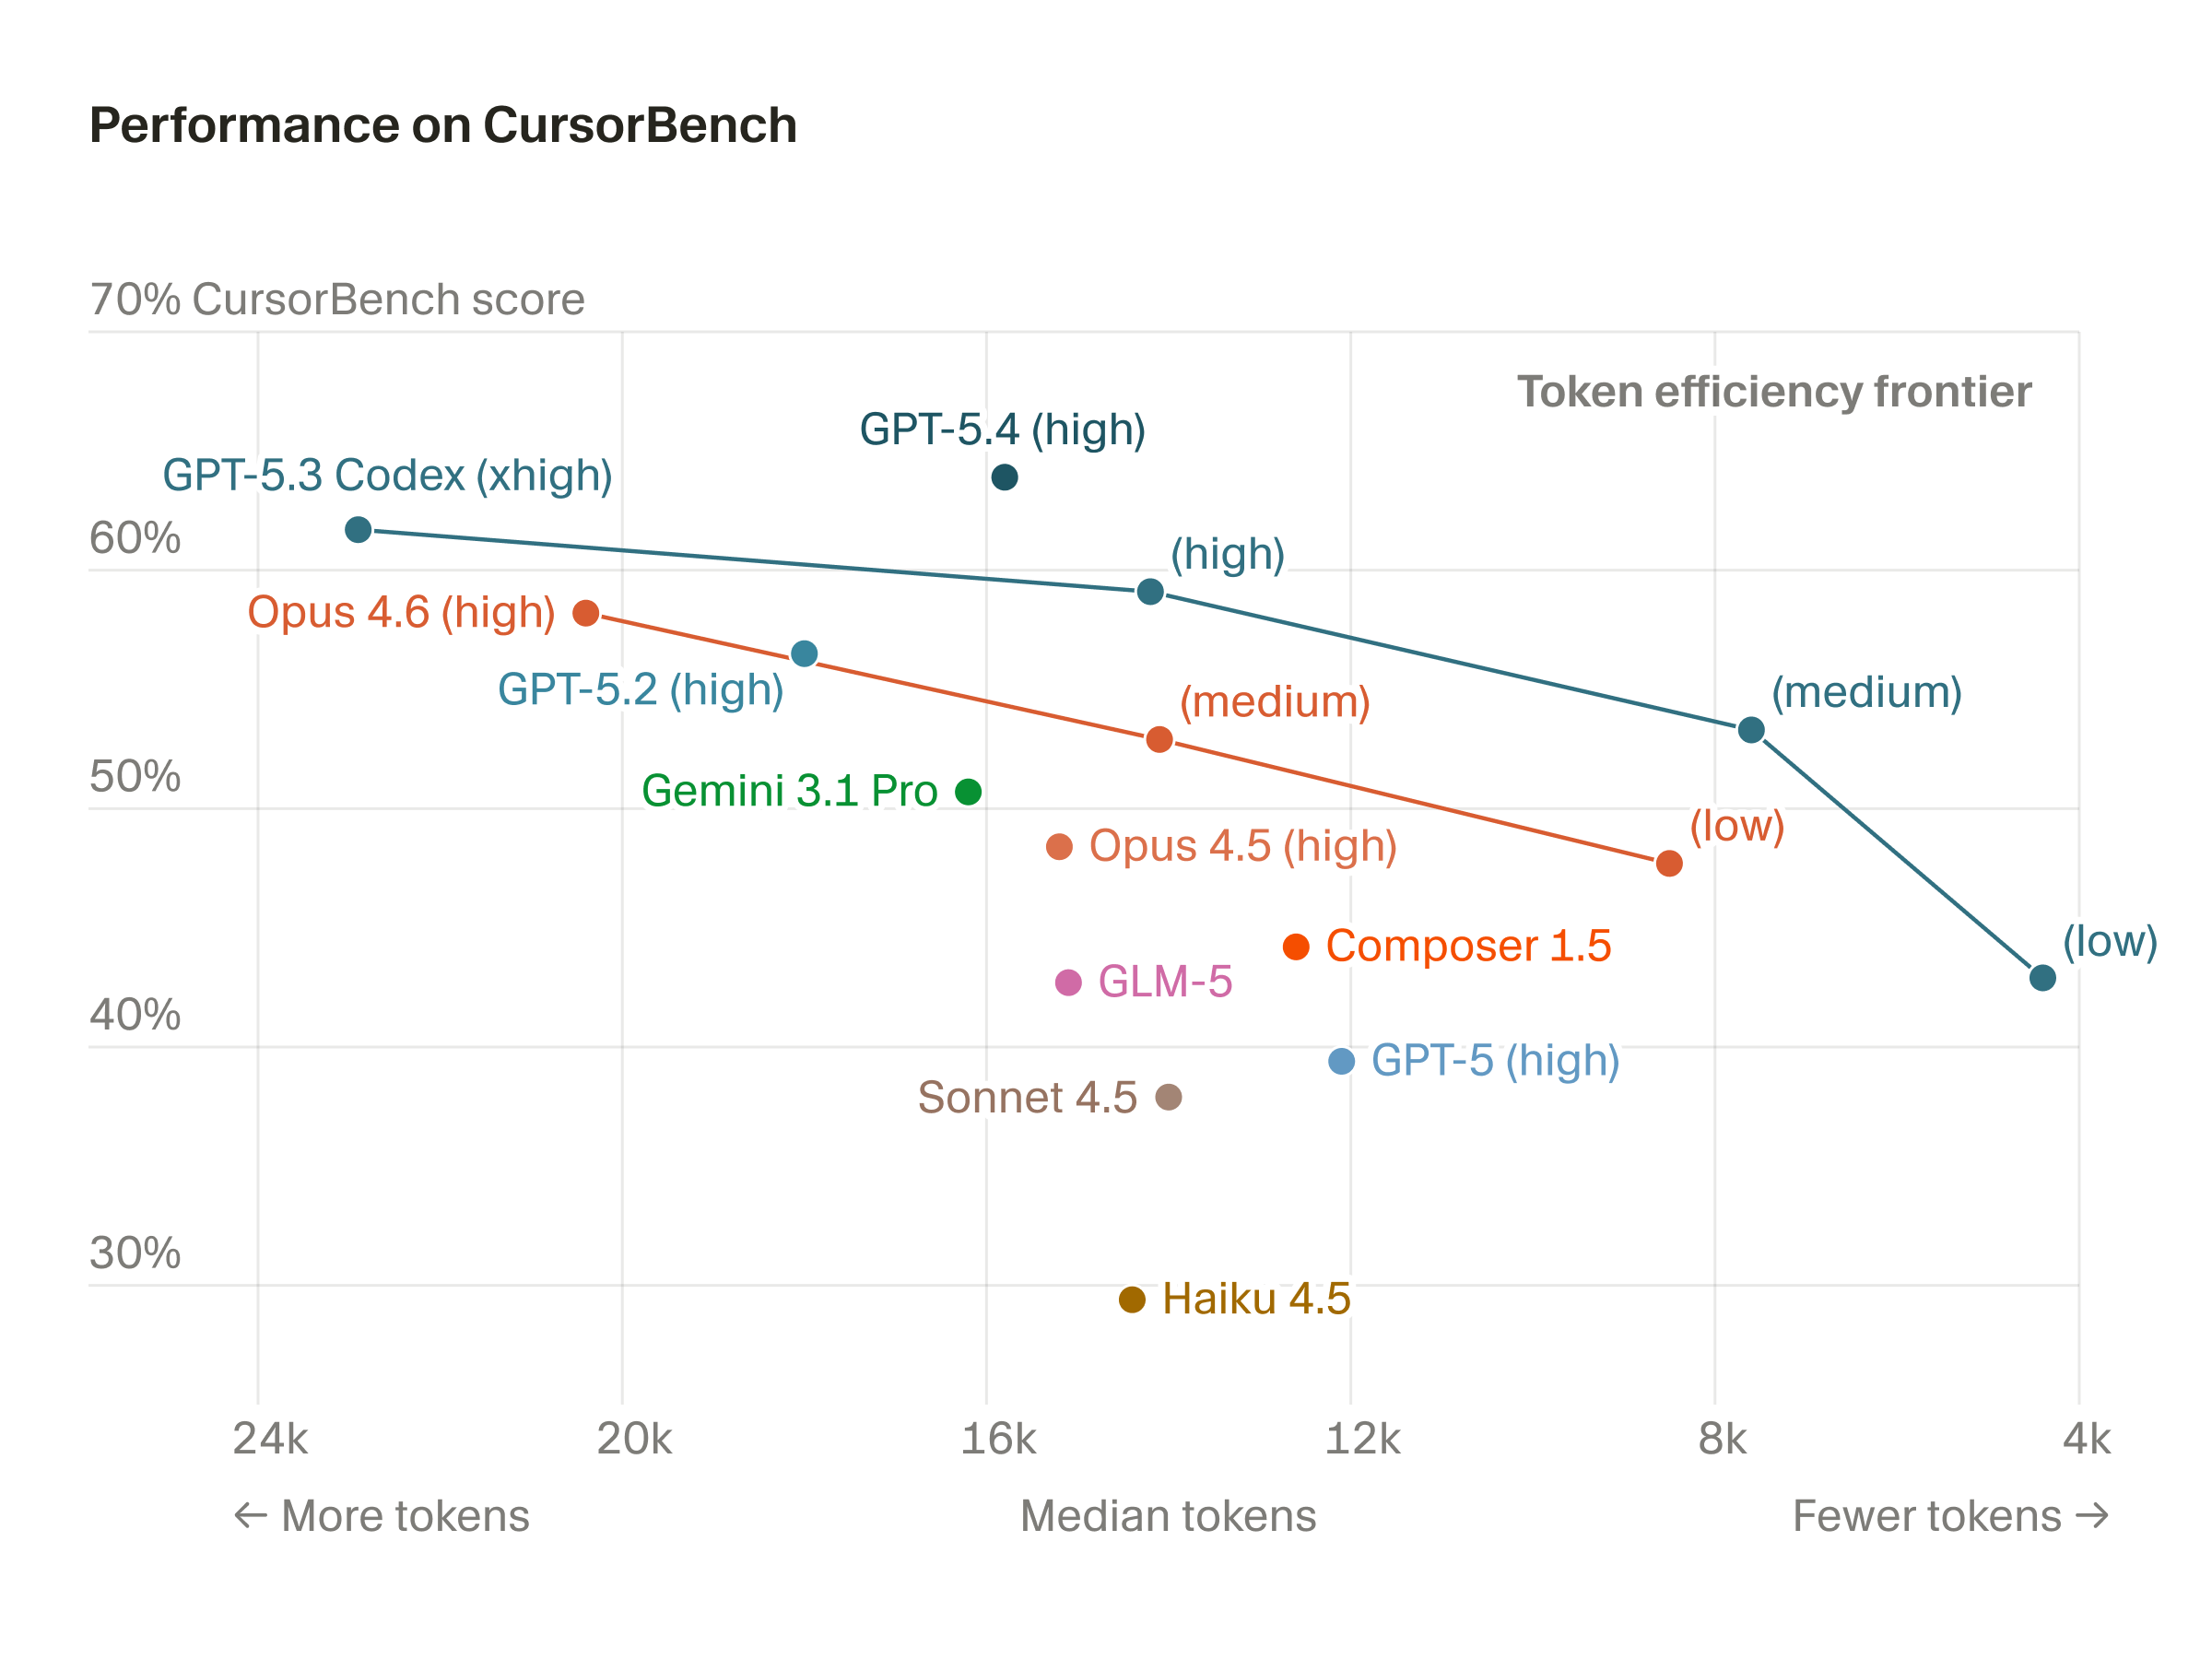
Fable 5 tops Cursor's CursorBench 3.1 coding-agent leaderboard as the vendor eval resurfaces
 News
Z.ai's open-weight GLM-5.2 matches Claude Opus 4.8 on cybersecurity benchmarks at lower cost