News Topic
LLM Evaluation & Leaderboards
News on LLM evaluation and benchmarks, covering new tests, methodology changes, leaderboard results, and whether findings can be reproduced.
Latest
 News
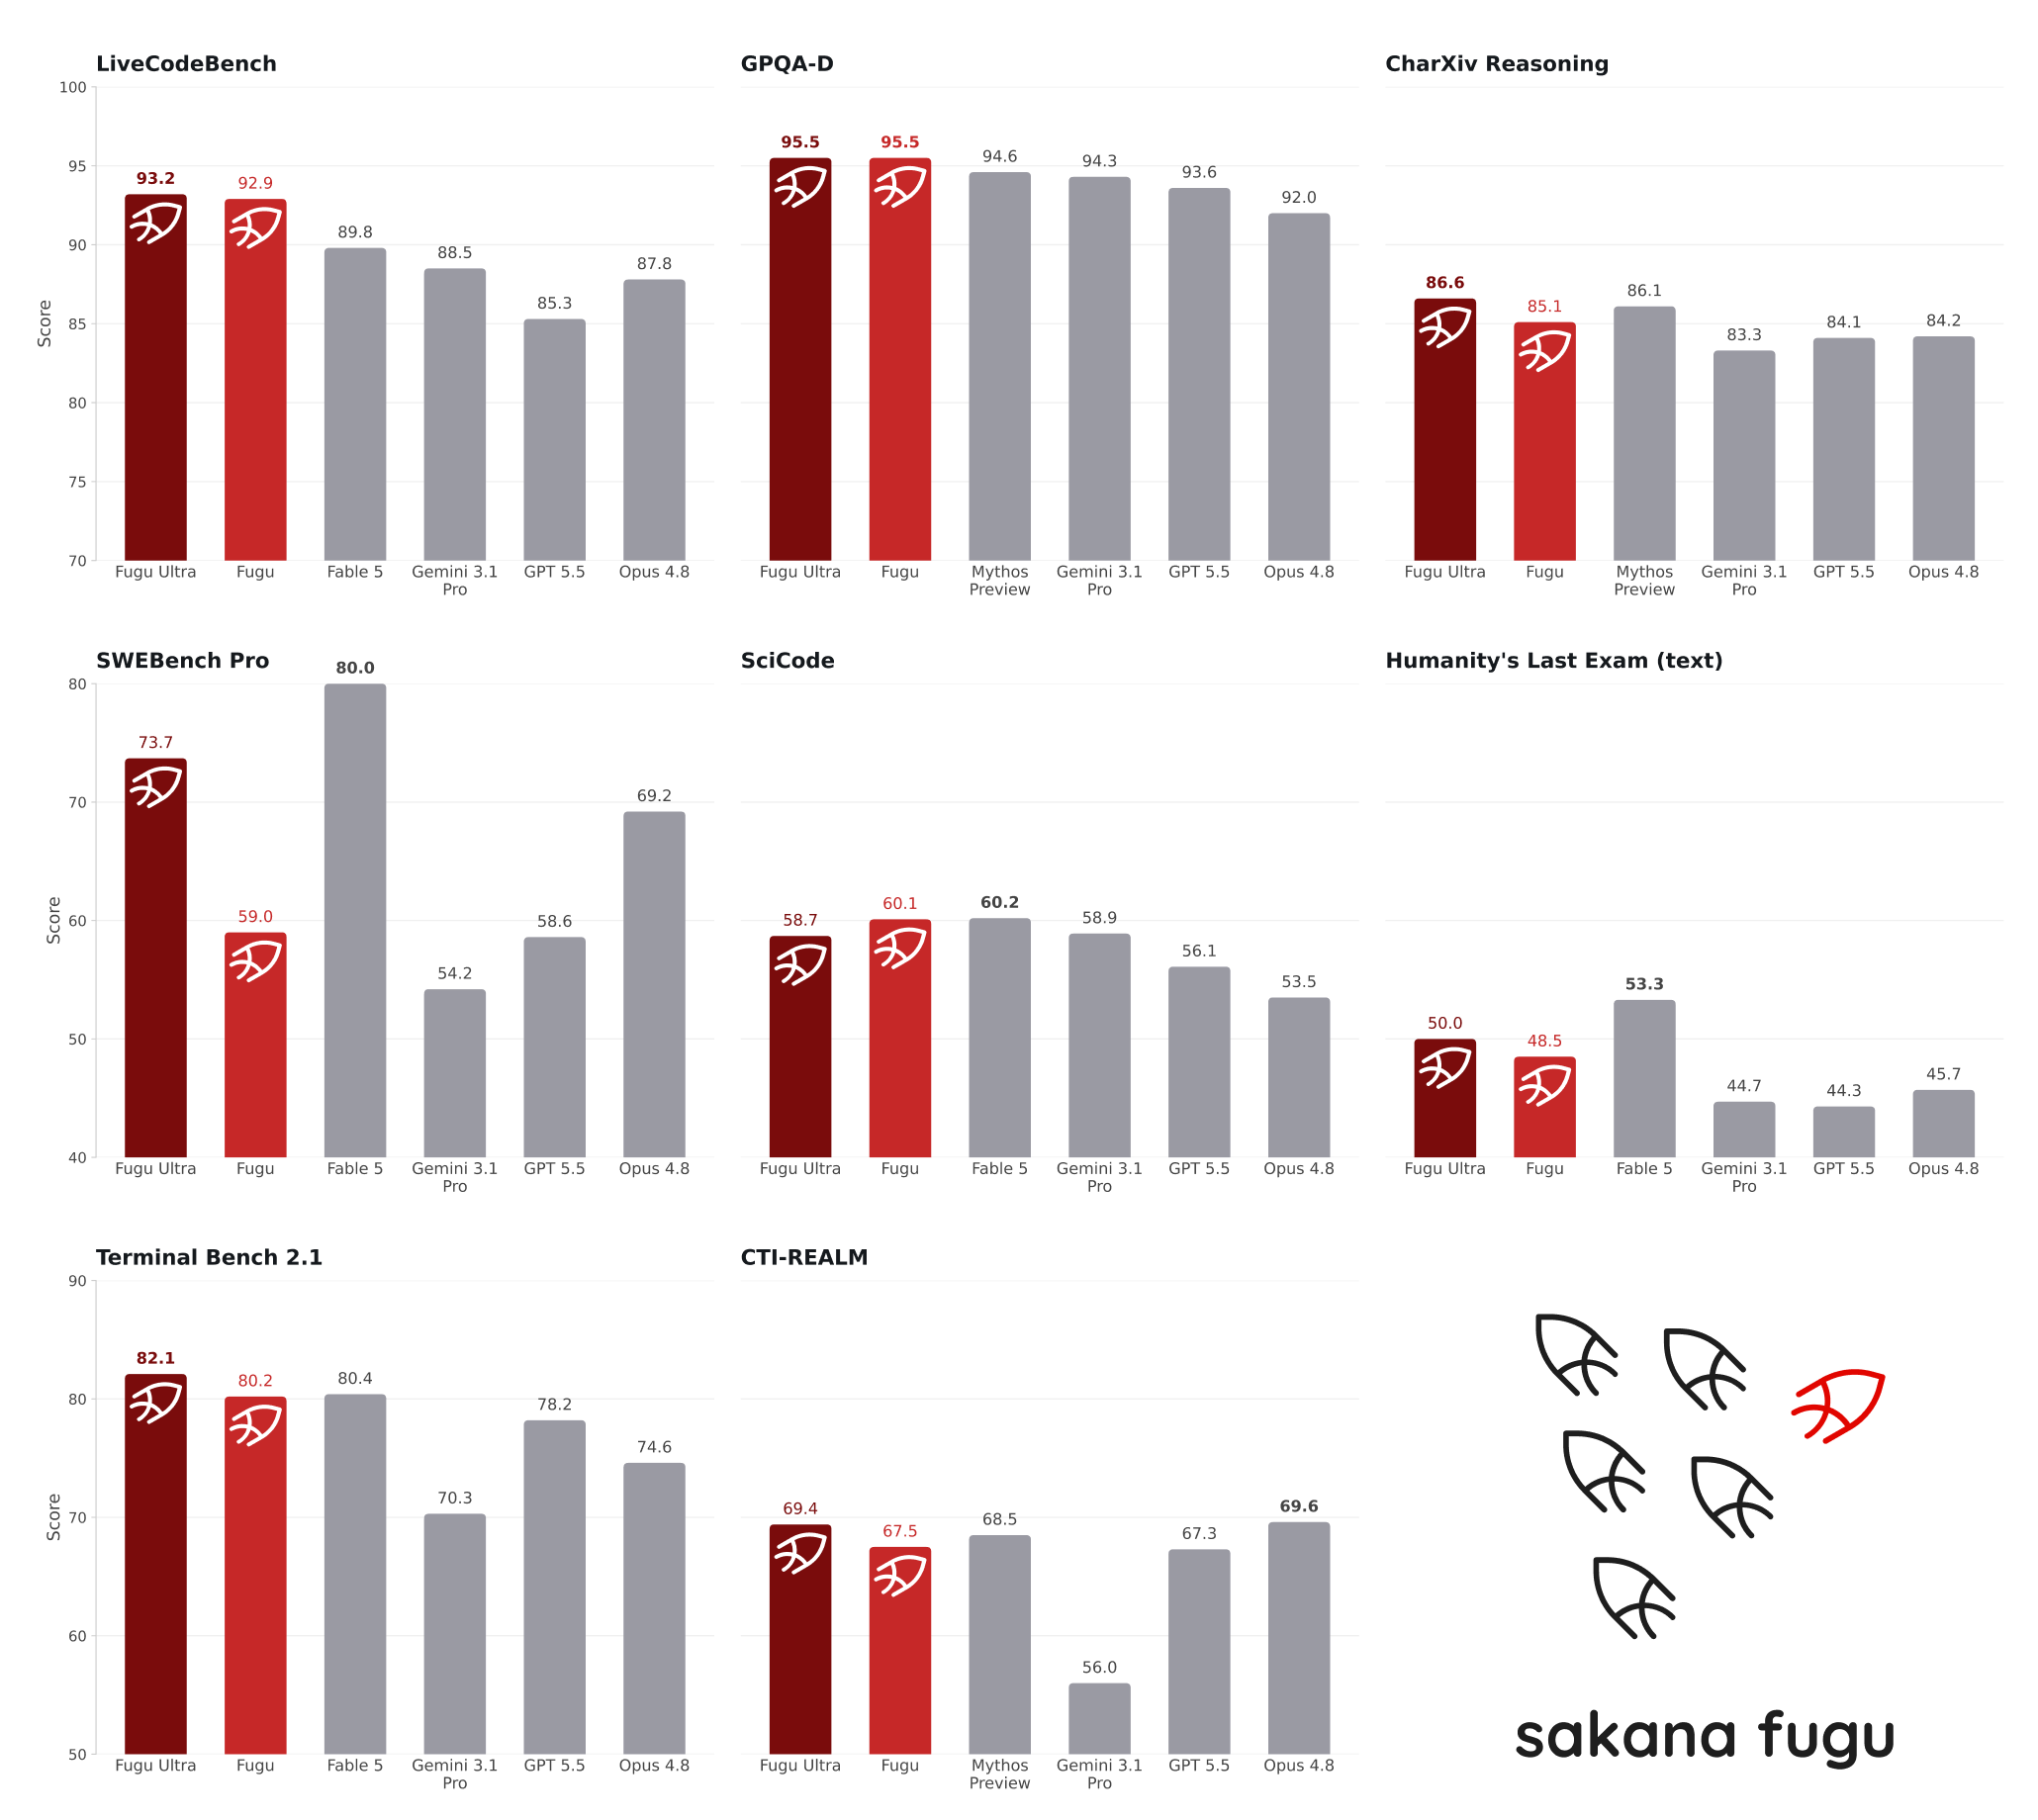
Sakana AI's Fugu Ultra claims top SWE-Bench Pro score, but testers report a real-world gap
 News
OpenAI introduces Deployment Simulation to predict model behavior before launch
- News
A new benchmark backed by Mercor shows AI agents struggle with real workplace tasks
 News
The newly released ARC-AGI-2 brings new challenges for "reasoning" models
- News
Researchers looking for benchmarks relevant to average AI users turn to the NPR Sunday Puzzle
- News
AlphaGeometry2 has surpassed IMO gold medalist performance in geometry problems
 News
Google is reportedly testing Gemini against Anthropic's Claude
 News
Primate Labs revamps its machine learning benchmark to introduce Geekbench AI 1.0
 News
Galileo's LLM Hallucination Index crowned Claude 3.5 Sonnet as the best LLM for RAG
 News
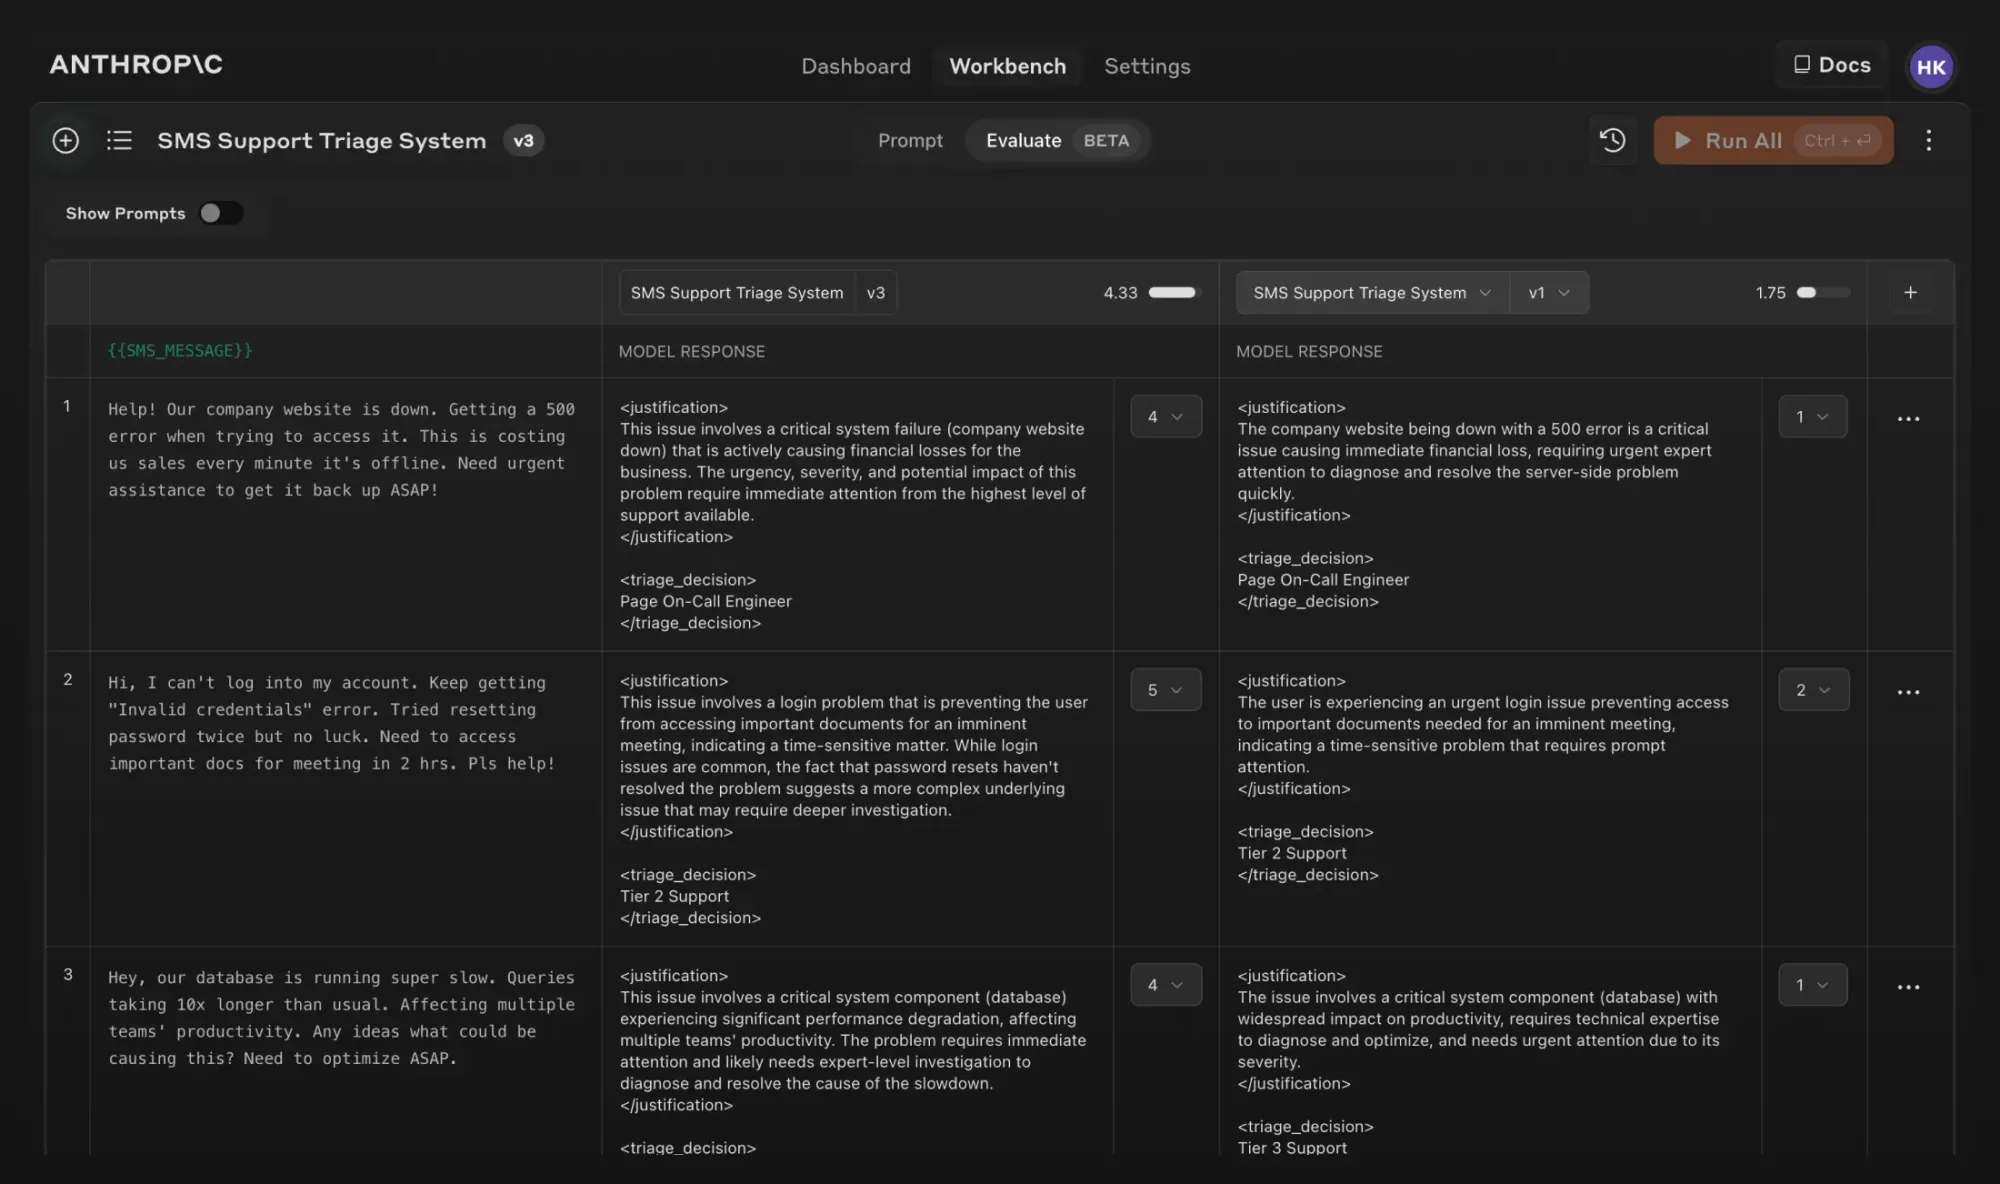
Anthropic launched advanced prompt evaluation tools for its developer console
- News
Salesforce's xLAM-1B shows competitive performance in function-calling tasks
 News
Anthropic launches an initiative to fund third-party AI evaluations


