LLM Evaluation & Leaderboards
News on LLM evaluation and benchmarks, covering new tests, methodology changes, leaderboard results, and whether findings can be reproduced.
Explore how researchers and engineering teams test language models before and after deployment. Coverage looks at benchmark design, meaningful comparisons, leaderboard changes, and which results teams can reproduce.
Latest coverage
Articles
 News
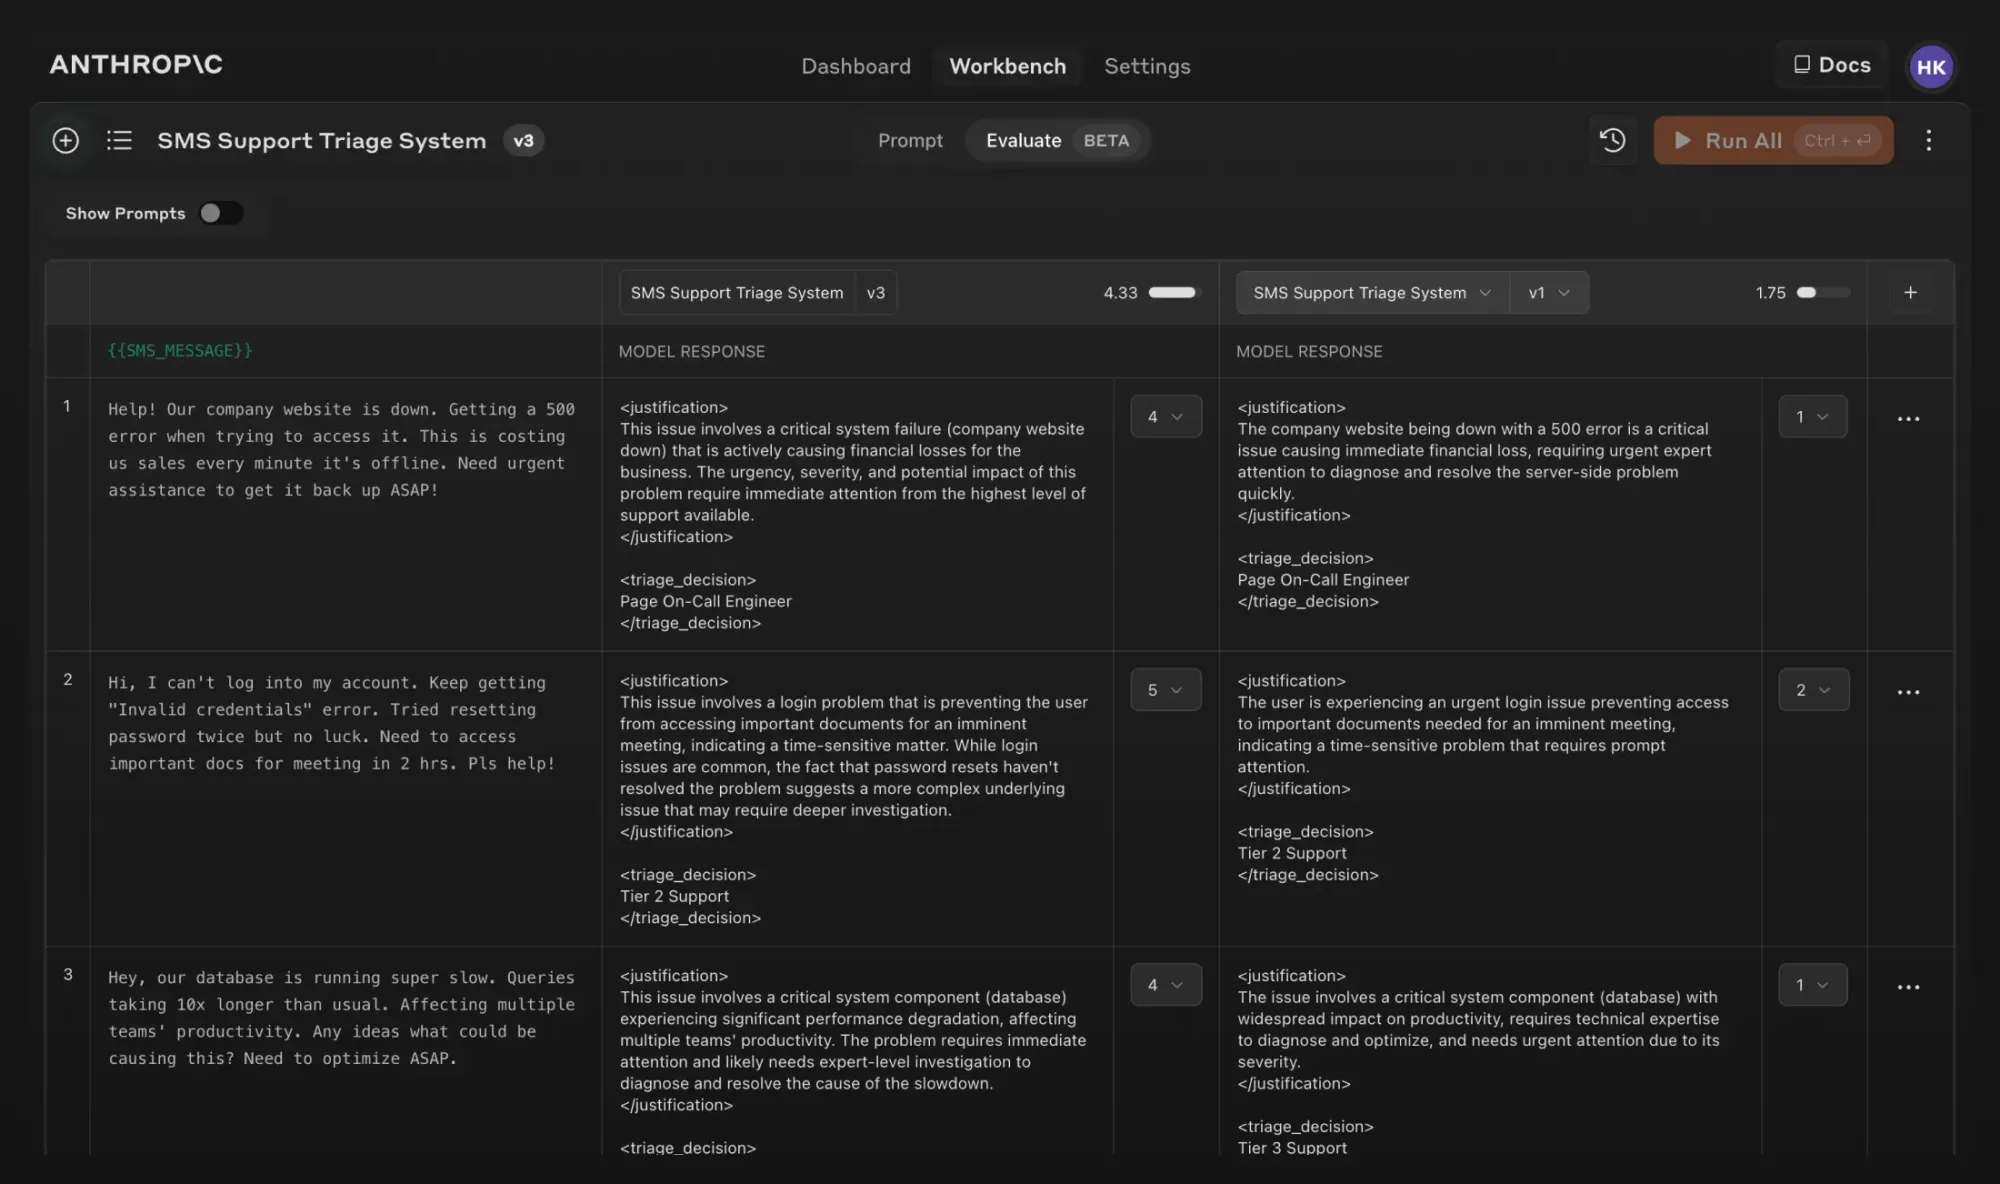
Anthropic launched advanced prompt evaluation tools for its developer console
- News
Salesforce's xLAM-1B shows competitive performance in function-calling tasks
 News
Anthropic launches an initiative to fund third-party AI evaluations
 News
Hugging Face's Open LLM Leaderboard v2 increases difficulty and delivers fairer scores
 News
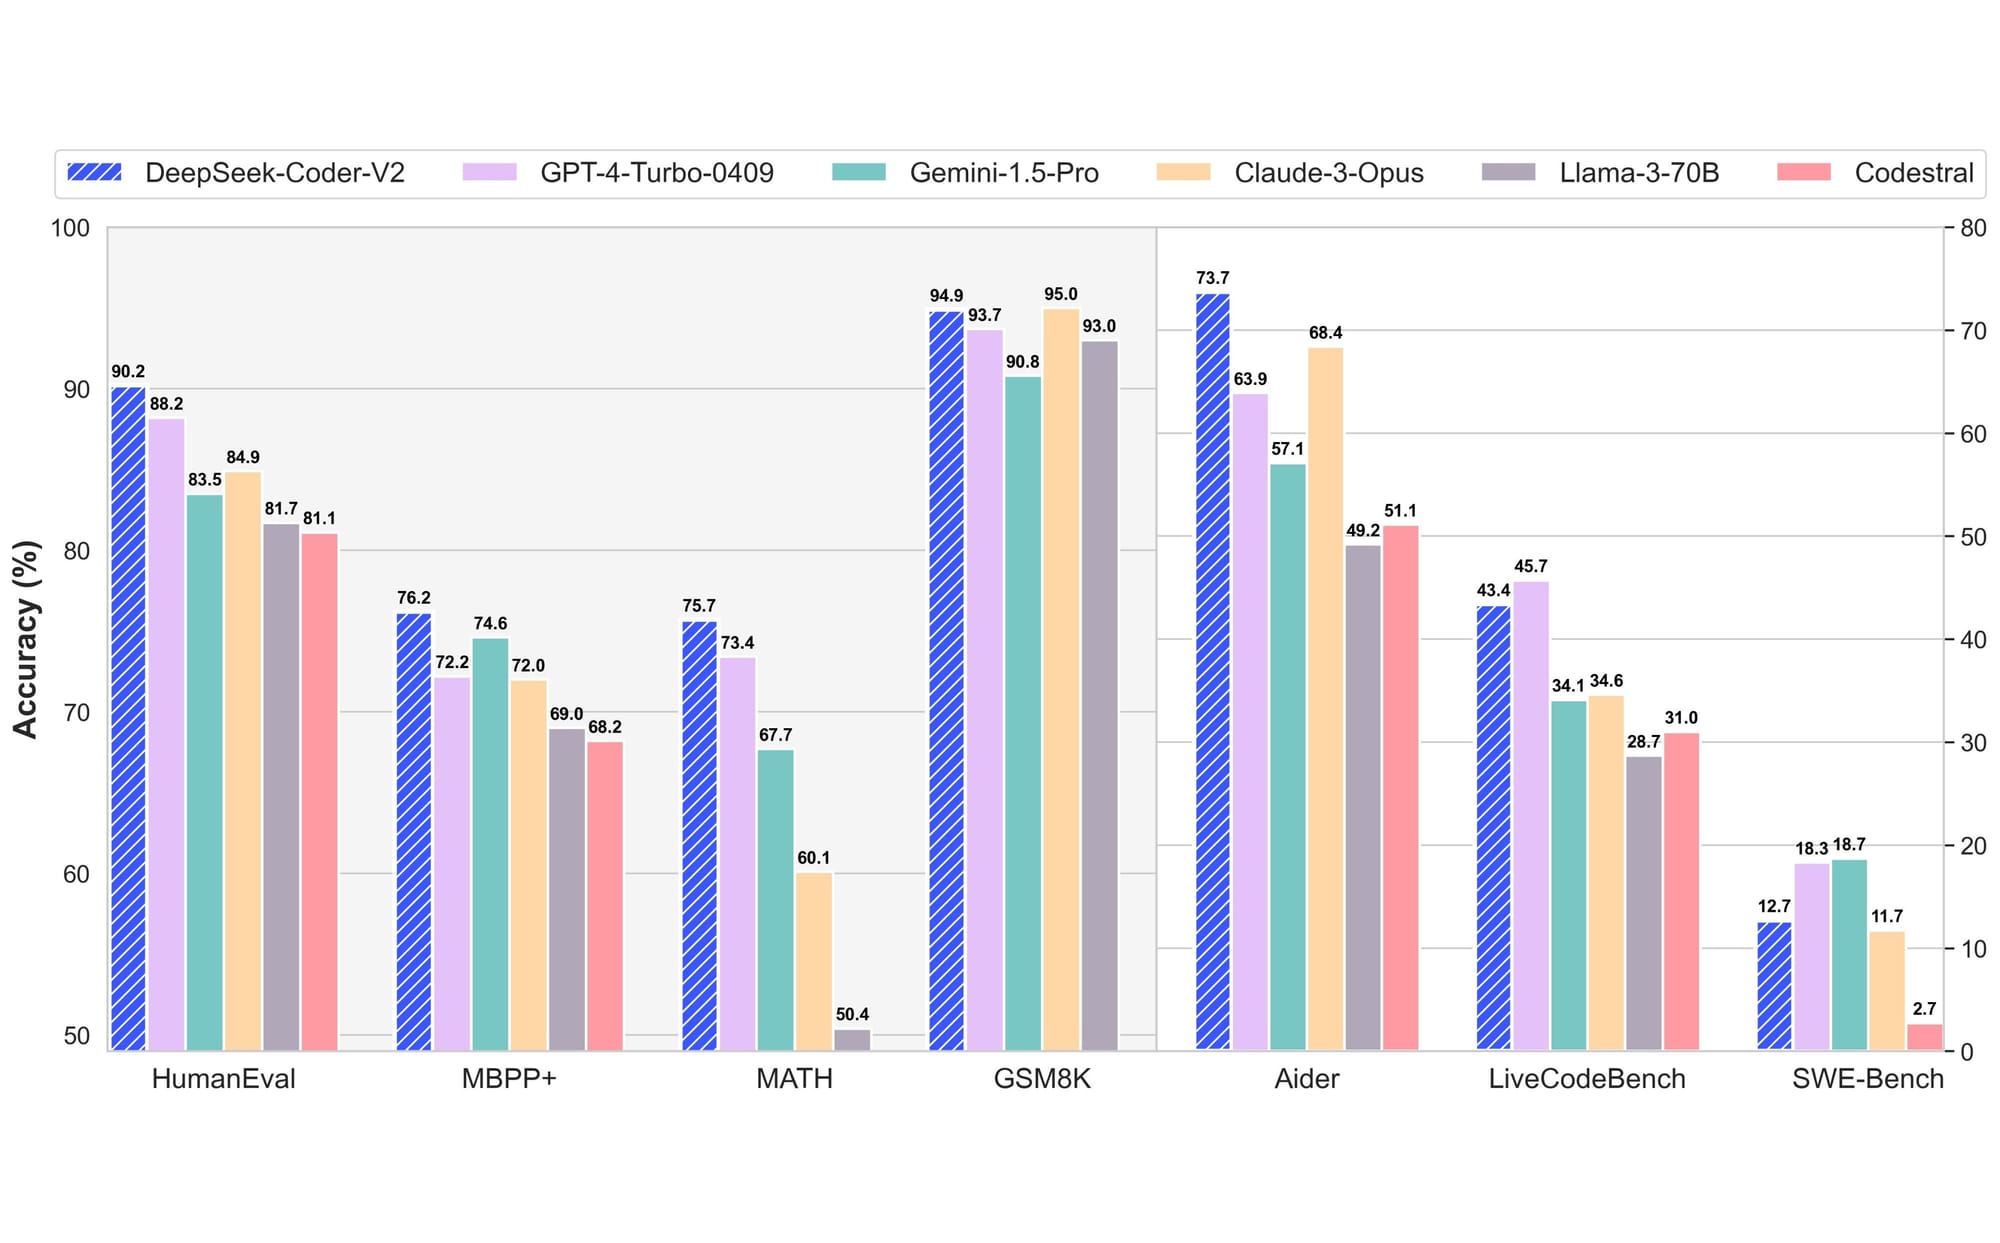
DeepSeek Coder V2 beats GPT-4, Claude 3 Opus, and Gemini 1.5 Pro in popular coding and math benchmarks
 News
MLCommons releases MLPerf Training 4.0 results and unveils two new benchmarks
 News
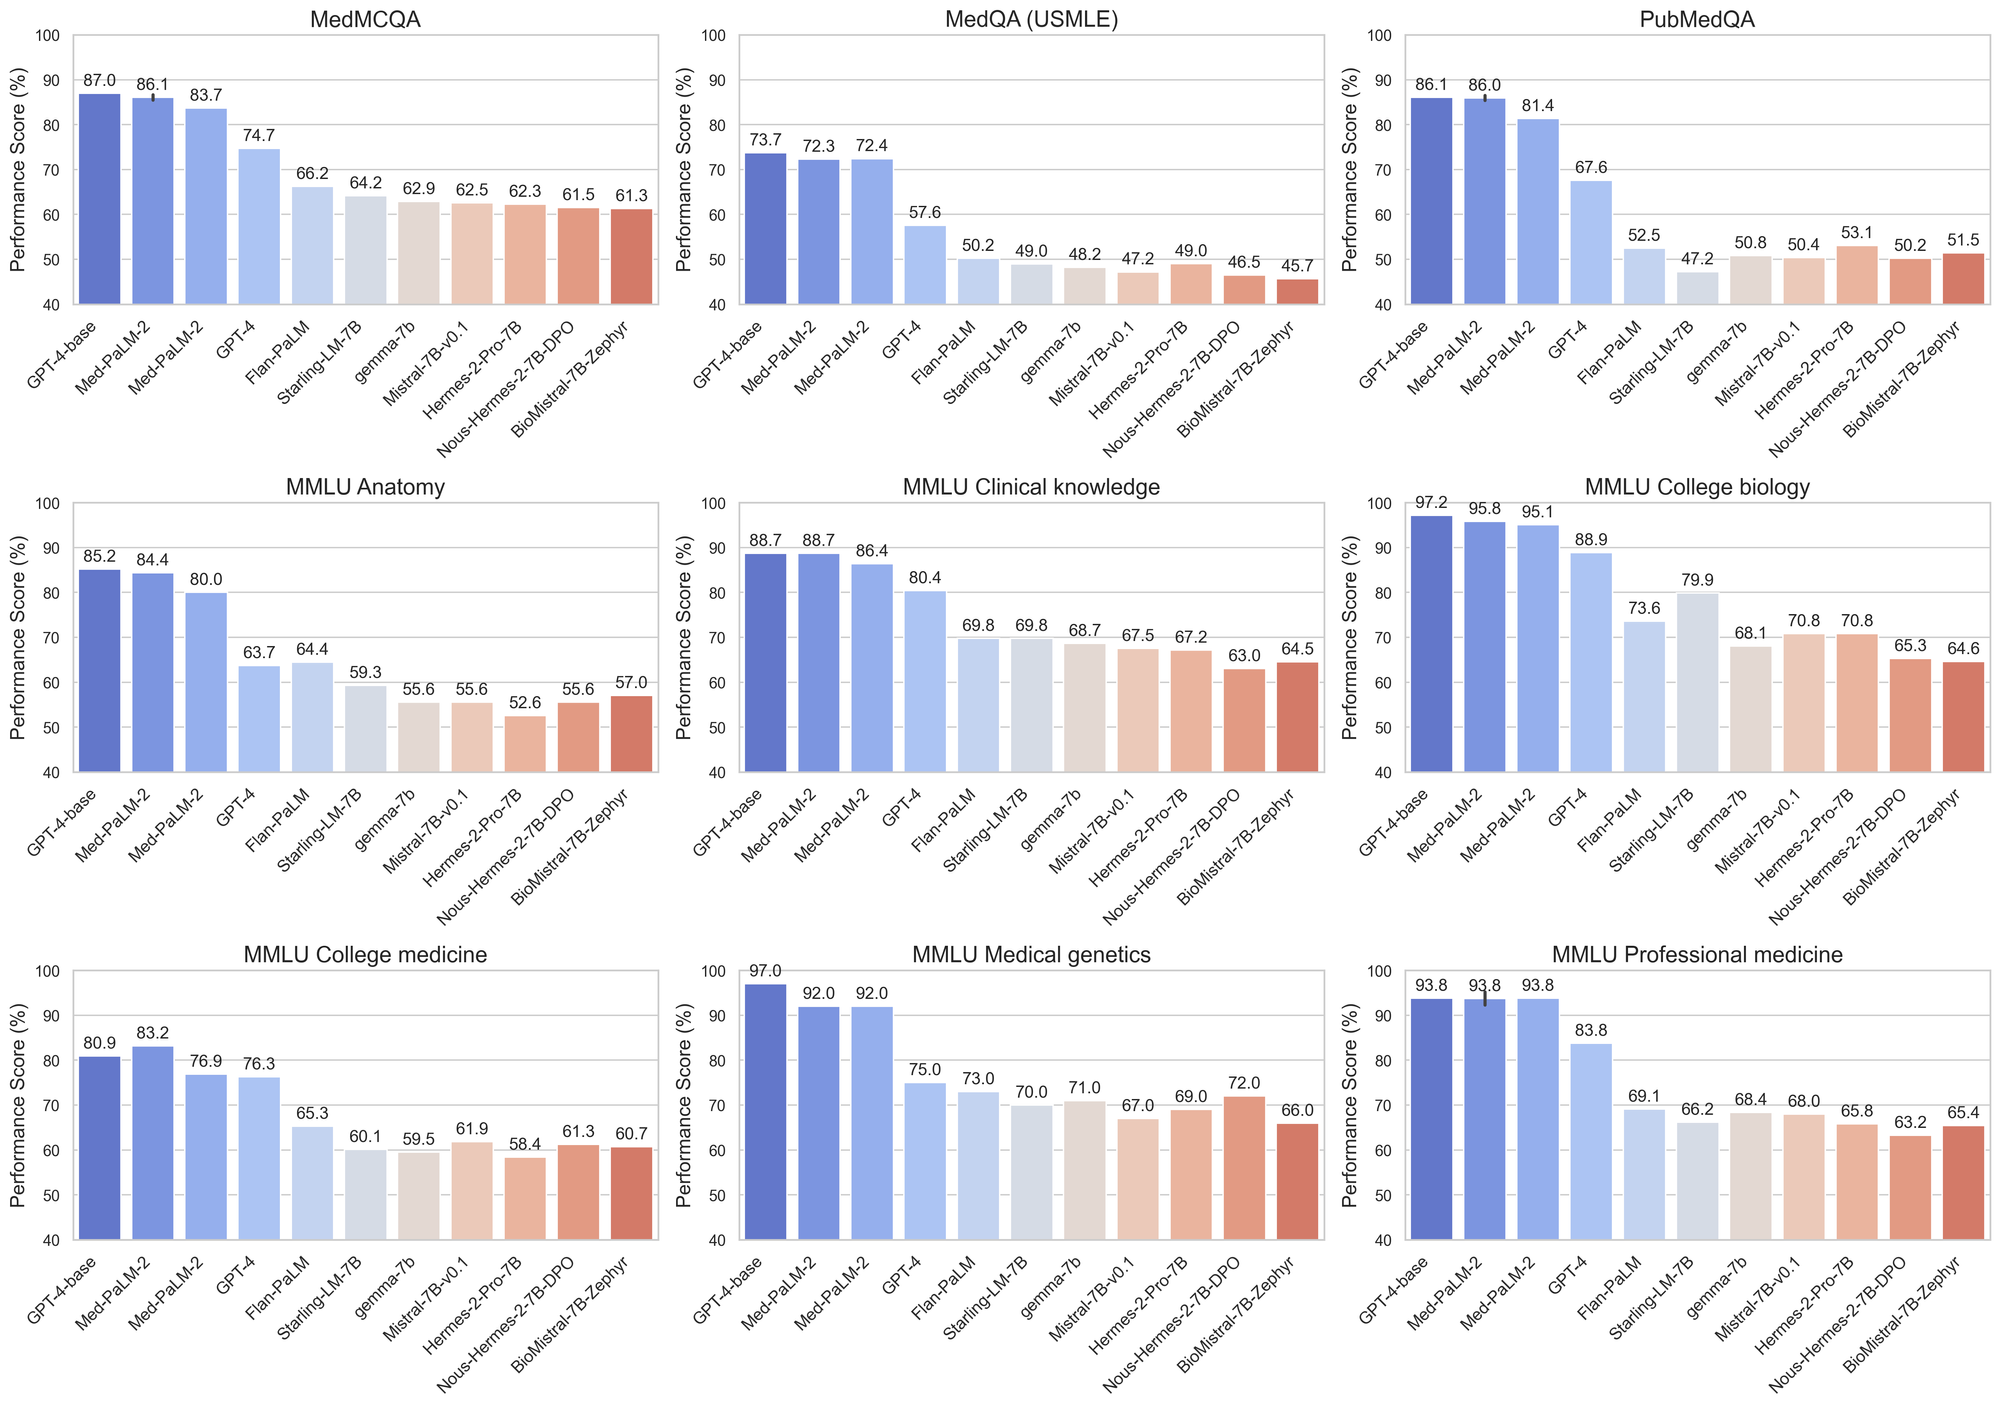
The Open Medical-LLM Leaderboard enables the objective evaluation of LLMs for the medical sector
 News
AlphaGeometry is as precise at solving geometry problems as an Olympiad gold medalist
 News
Giskard's collaborative open-source platform helps developers build better AI products
 News
Studio LLM is Galileo’s smarter solution for building and evaluating LLM apps
