Stanford and Nvidia researchers release CLM-8B for cached agent decisions
Researchers associated with Stanford and Nvidia released CLM-8B, an open model for scoring bounded agent actions. Cached action embeddings can cut repeated inference work, though one reported tool-calling test showed lower accuracy than Jev.
Researchers associated with Stanford and Nvidia have released CLM-8B, an open model and toolkit that selects among supplied actions by matching them to an agent’s current state. The architecture lets a deployment compute representations of recurring actions once and reuse them, reducing repeated inference work when an agent chooses from a mostly fixed set of tools or other options.
Across their zero-shot computer-use, gaming and tool-calling comparisons, the developers report up to ninefold lower latency than TypeSafe’s Jev. The claim has not been independently reproduced, and the speed advantage did not preserve equal accuracy in every test. In the team’s reported BFCL v4 comparison, CLM-8B scored 95.2%, versus 99.2% for Jev. CLM also completed 26 of 30 WikiRacing tasks, while Jev completed all 30. The two systems matched success rates on two game tasks.
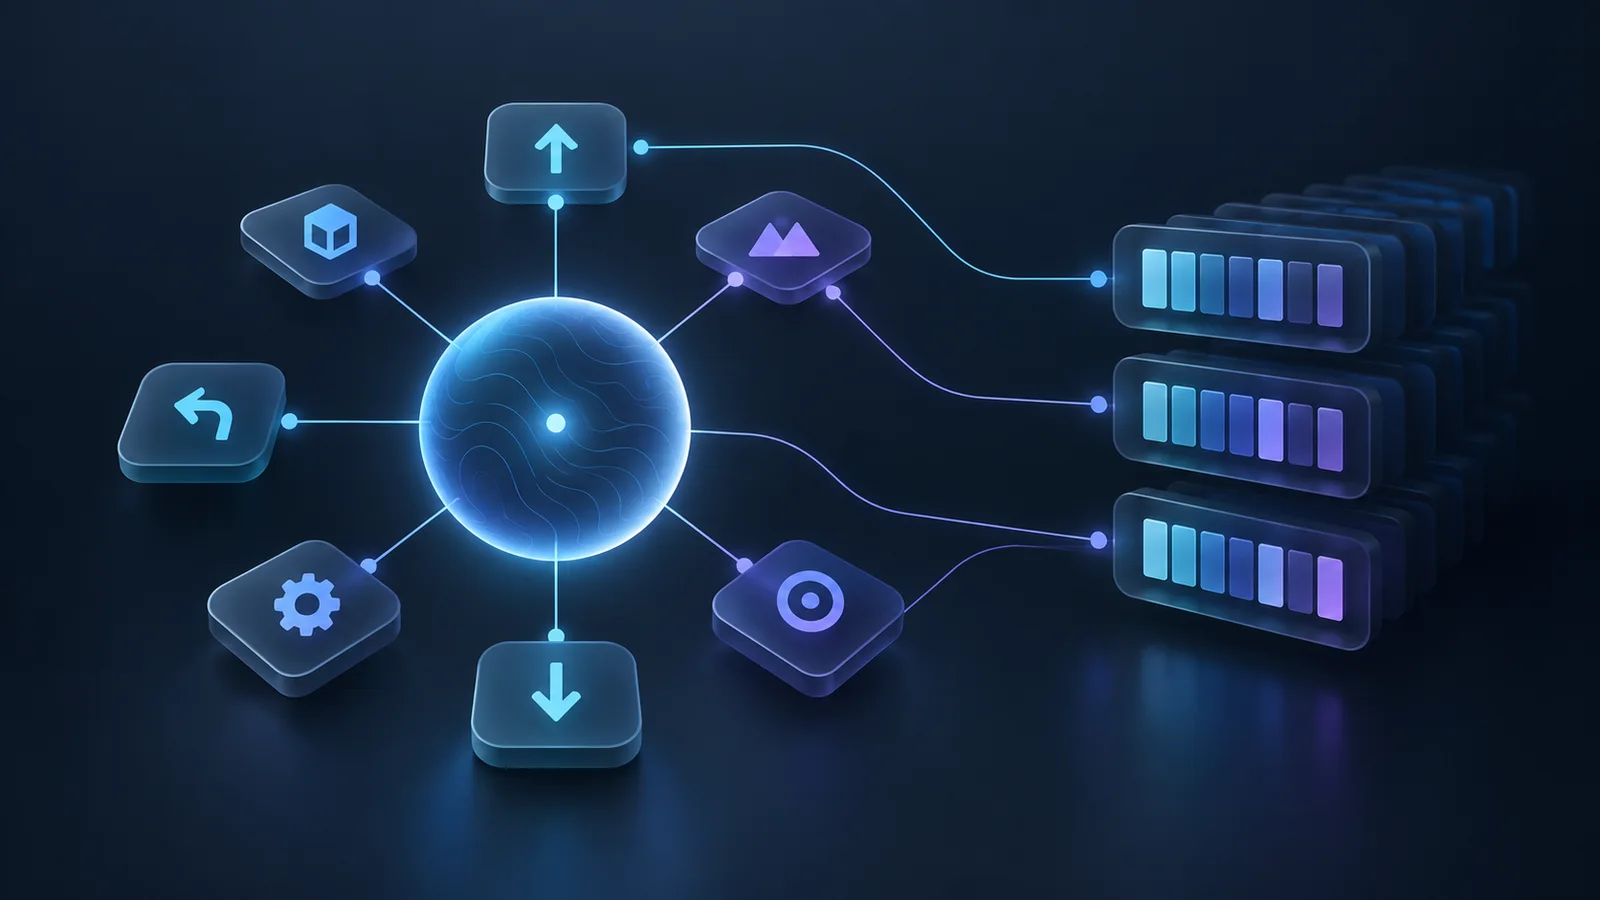
CLM-8B is designed for bounded decisions rather than open-ended generation. A deployment supplies a state — the context the agent currently has — and a set of candidate actions. The model uses separate encoders for the state and actions, places their representations in a shared embedding space, then chooses the action whose embedding scores highest against the state embedding. Its probabilities are relative to the candidates it receives, so it cannot create a missing option or establish that every supplied action is valid.
The team trained the model with a bidirectional InfoNCE objective, which pulls matched state-action pairs closer together and pushes mismatched pairs apart. The released system uses a frozen Qwen3-8B encoder with separate trainable state and action projection heads of about 20 million parameters each. The developers say training proceeded through roughly 60 million Nemotron question-answer pairs, about 30 million synthetic hard negatives and about 1 million agent trajectories.
That separation is what makes action reuse possible. An agent whose approved tool list changes infrequently can encode those tool descriptions ahead of time, then encode each new state as requests arrive. According to the project’s measurements on one RTX 4090, a cache hit skips the encoder call, the host-to-device copy and the projection-head pass.
The benefit depends on the workload. In the project’s server-side median measurements with a fixed action set, revisited states improved from 1.7 milliseconds to 0.6 milliseconds for three actions and from 2.0 milliseconds to 0.7 milliseconds for 50 actions. Requests with a fresh state each time changed only from 28.6 milliseconds to 28.0 milliseconds for three actions and from 28.8 milliseconds to 28.1 milliseconds for 50. The largest measured reductions therefore came on cache hits; the fresh-state timings moved by less than one millisecond.
The model can also rank candidate solutions produced elsewhere, but the published coding results used task-specific fine-tuning. In the team’s tests, fine-tuned CLM heads selected among solutions generated by larger models and reached 81.6% on 38 held-out DeepSWE tasks and 87.6% on 30 held-out Terminal-Bench 2.1 tasks. Those figures do not show CLM solving the tasks from scratch, and none of the latency or benchmark results in the opened evidence has been independently reproduced.
The CLM-8B weights and inference code are available under Apache 2.0. The release also includes a TypeSafe-compatible API, fine-tuning tools and a playground for testing typed questions and candidate rankings.
More news
Google Research lays out unresolved privacy and security risks for AI agents
Apple researchers turn failed agent attempts into training insights with RLTL;DR
Strands opens Decider 2B for bounded agent decisions