Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
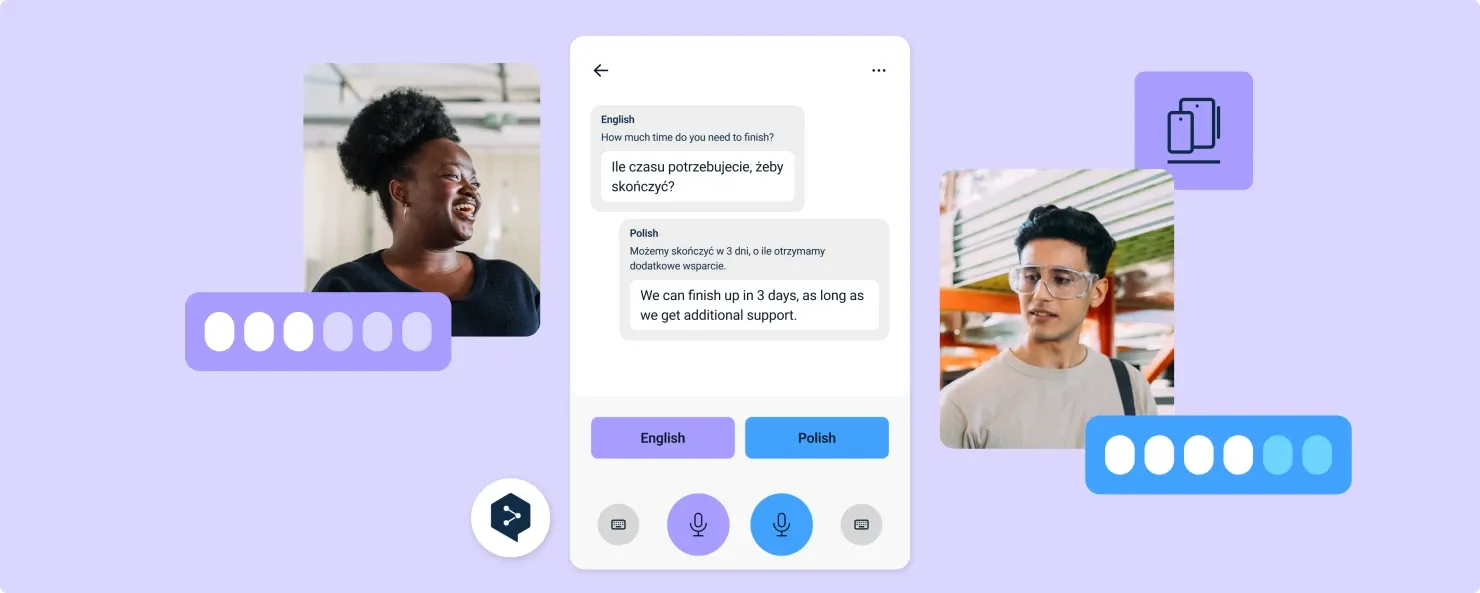
DeepL Voice can instantly provide translated captions for live or virtual conversations
- News
The Beatles' final AI-produced song snagged two Grammy nominations
 News
Panjaya's BodyTalk is a dubbing platform that synchronizes speakers voices, lips, and bodies
 News
Gladia's latest product offers real-time AI audio processing and transcription
 News
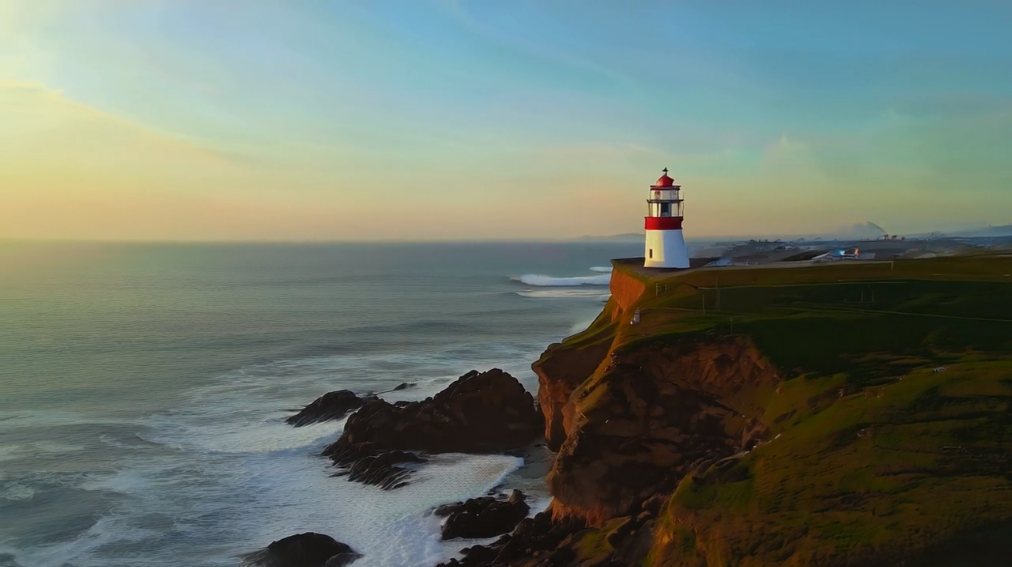
The open-source Pyramid Flow model demonstrates a new approach to video generation
 News
Movie Gen is Meta's latest contribution to AI-powered media generation research
 News
Runware has launched blazing-fast Stable Diffusion and FLUX-based image generation APIs
 News
Pika 1.5's new surreal special effects let users create videos that bend the laws of physics
 News
Google keeps building on NotebookLM's features with YouTube and audio files support
 News
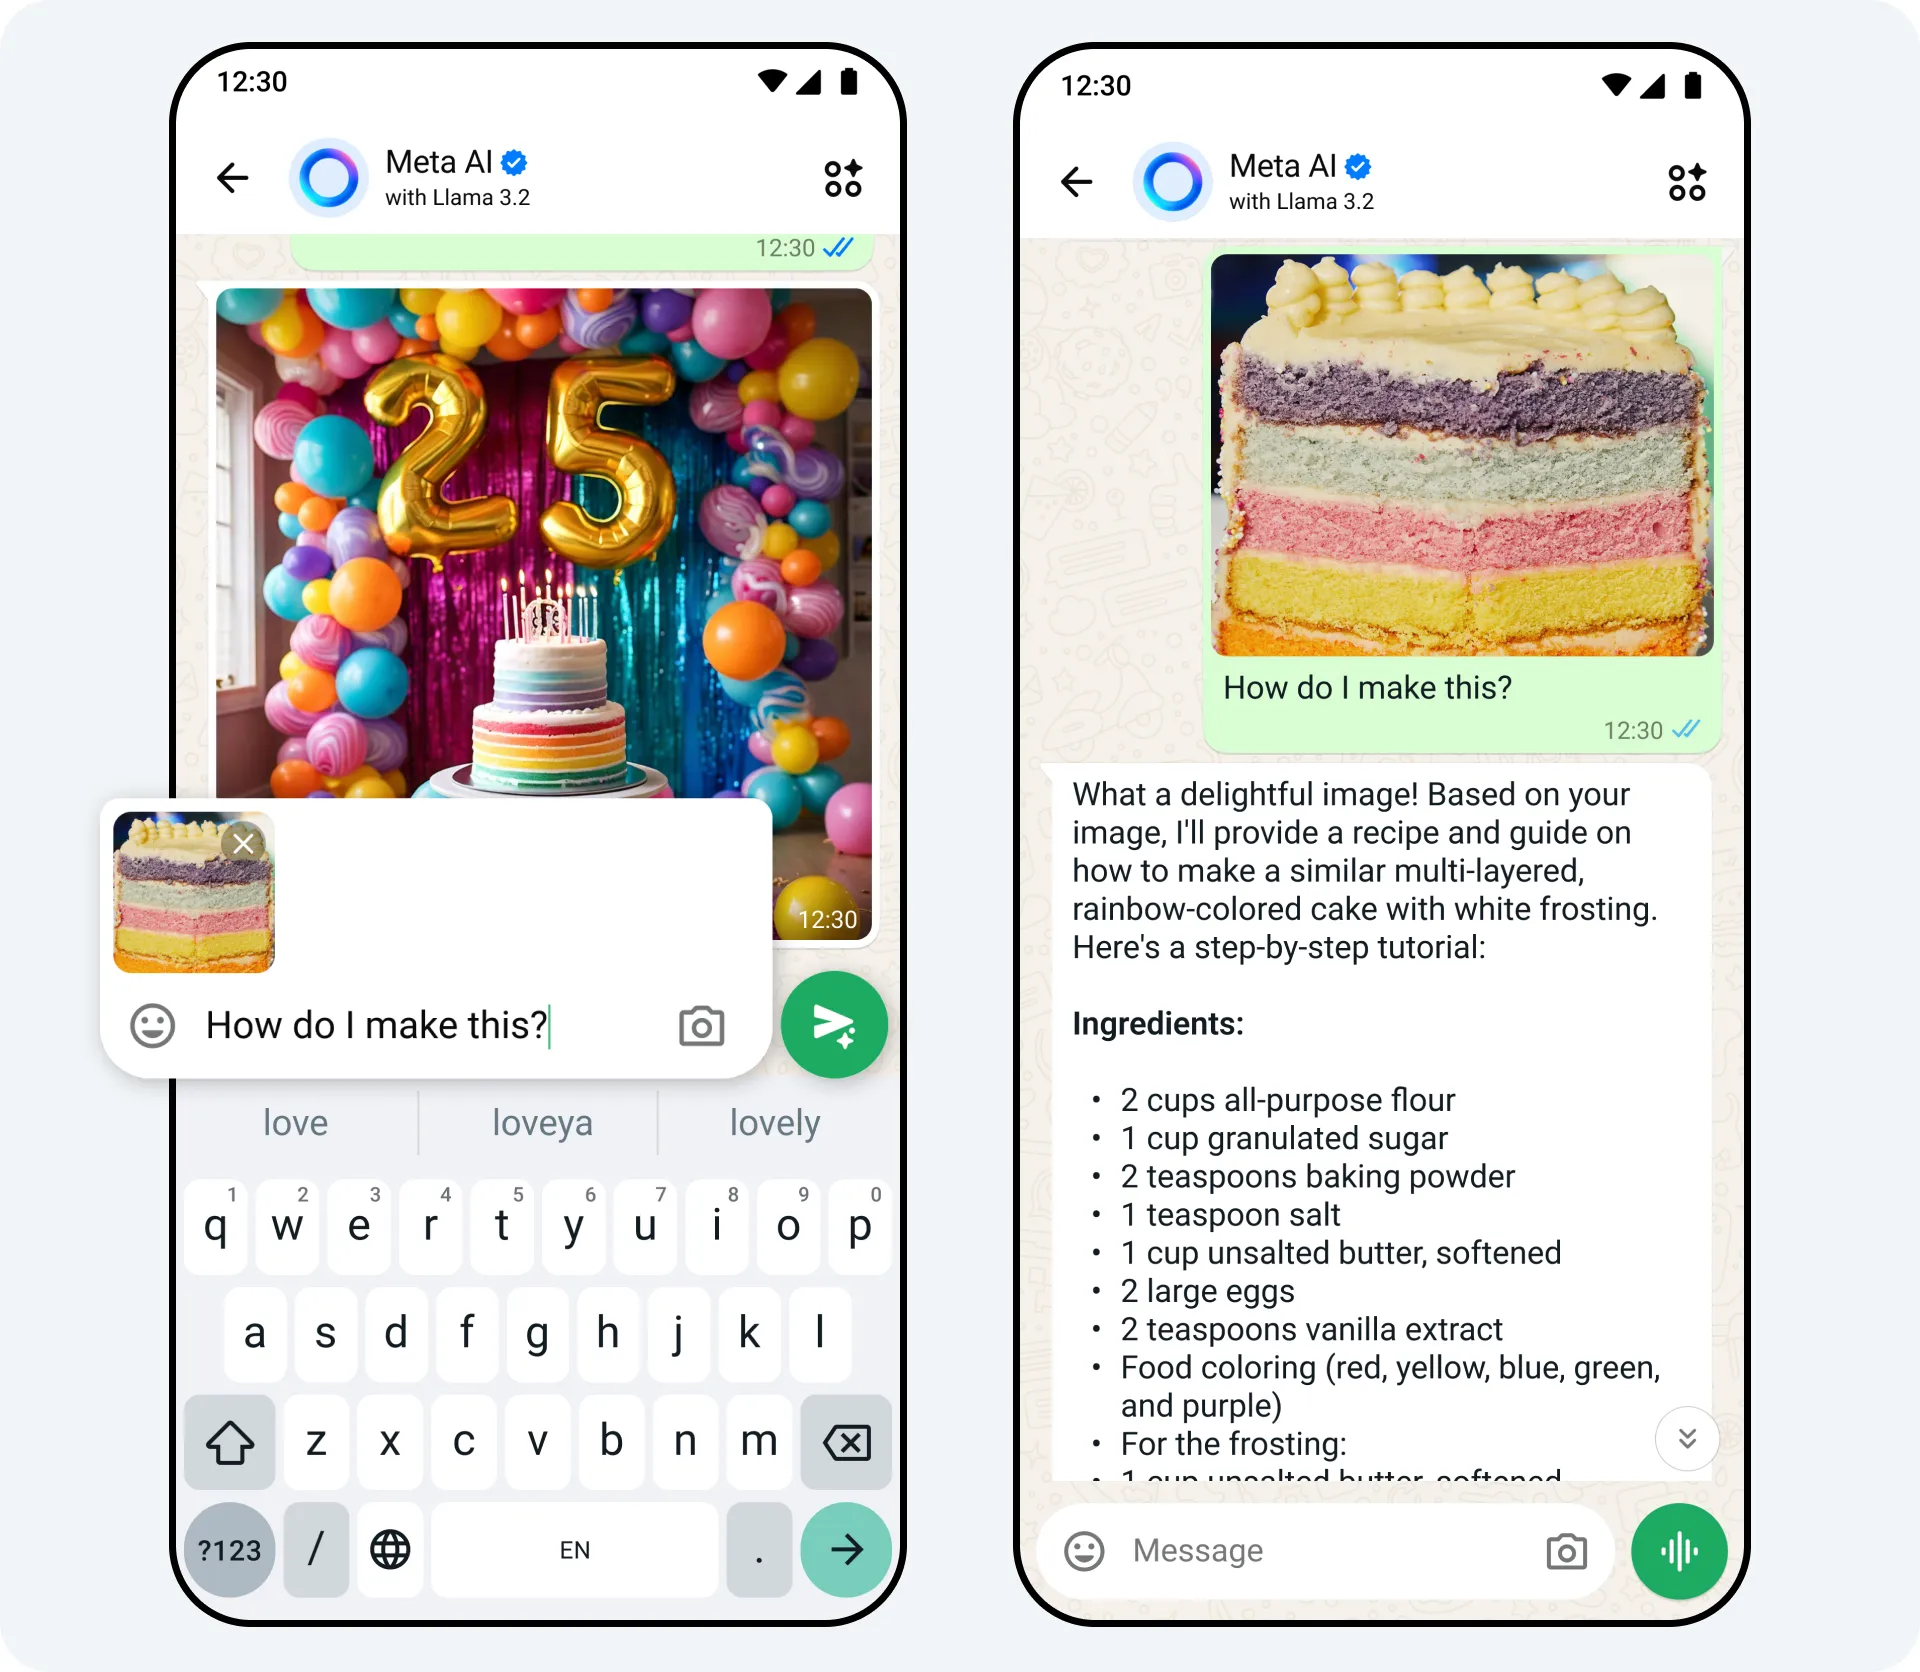
Meta Connect 2024: Meta AI's voice mode, visual search, and automated content generation
 News
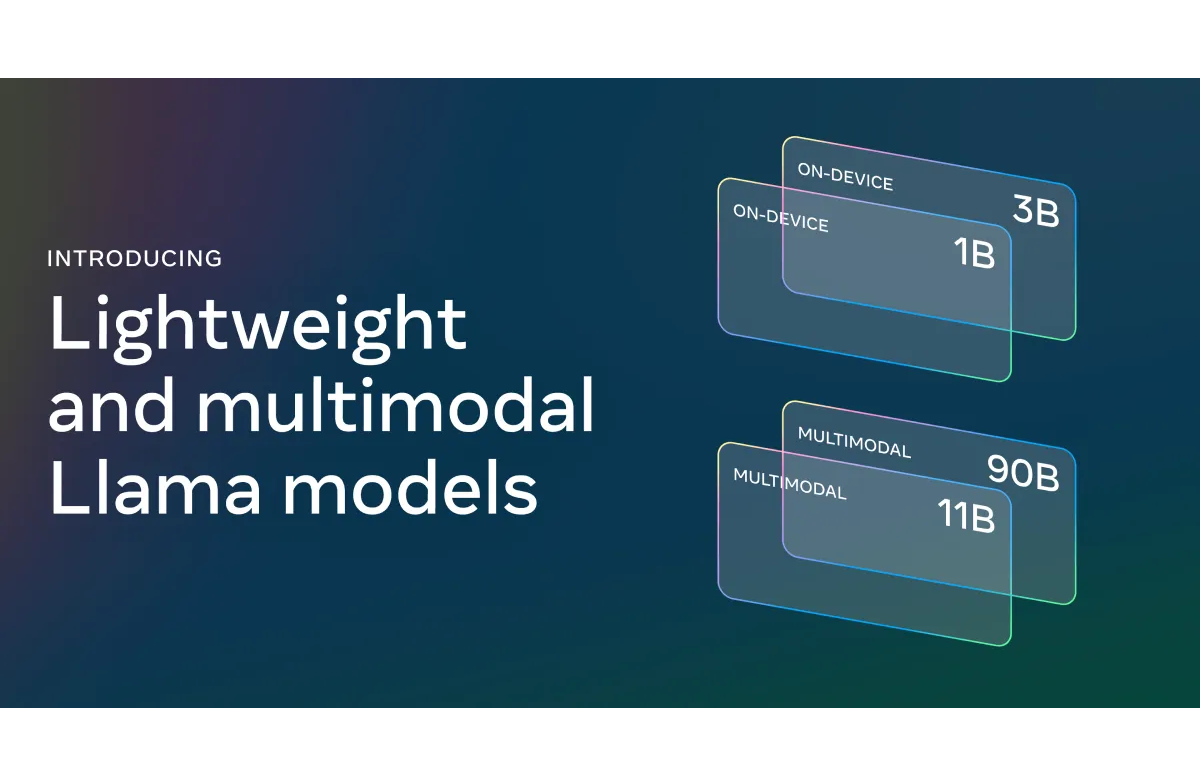
Meta Connect 2024: Llama 3.2 brings open multimodal 11B and 90B to the race
 News
OpenAI's Advanced Voice Mode is finally available for ChatGPT Plus and Team users
