Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
ElevenLabs launches an AI music generator that creates full songs from text prompts
 News
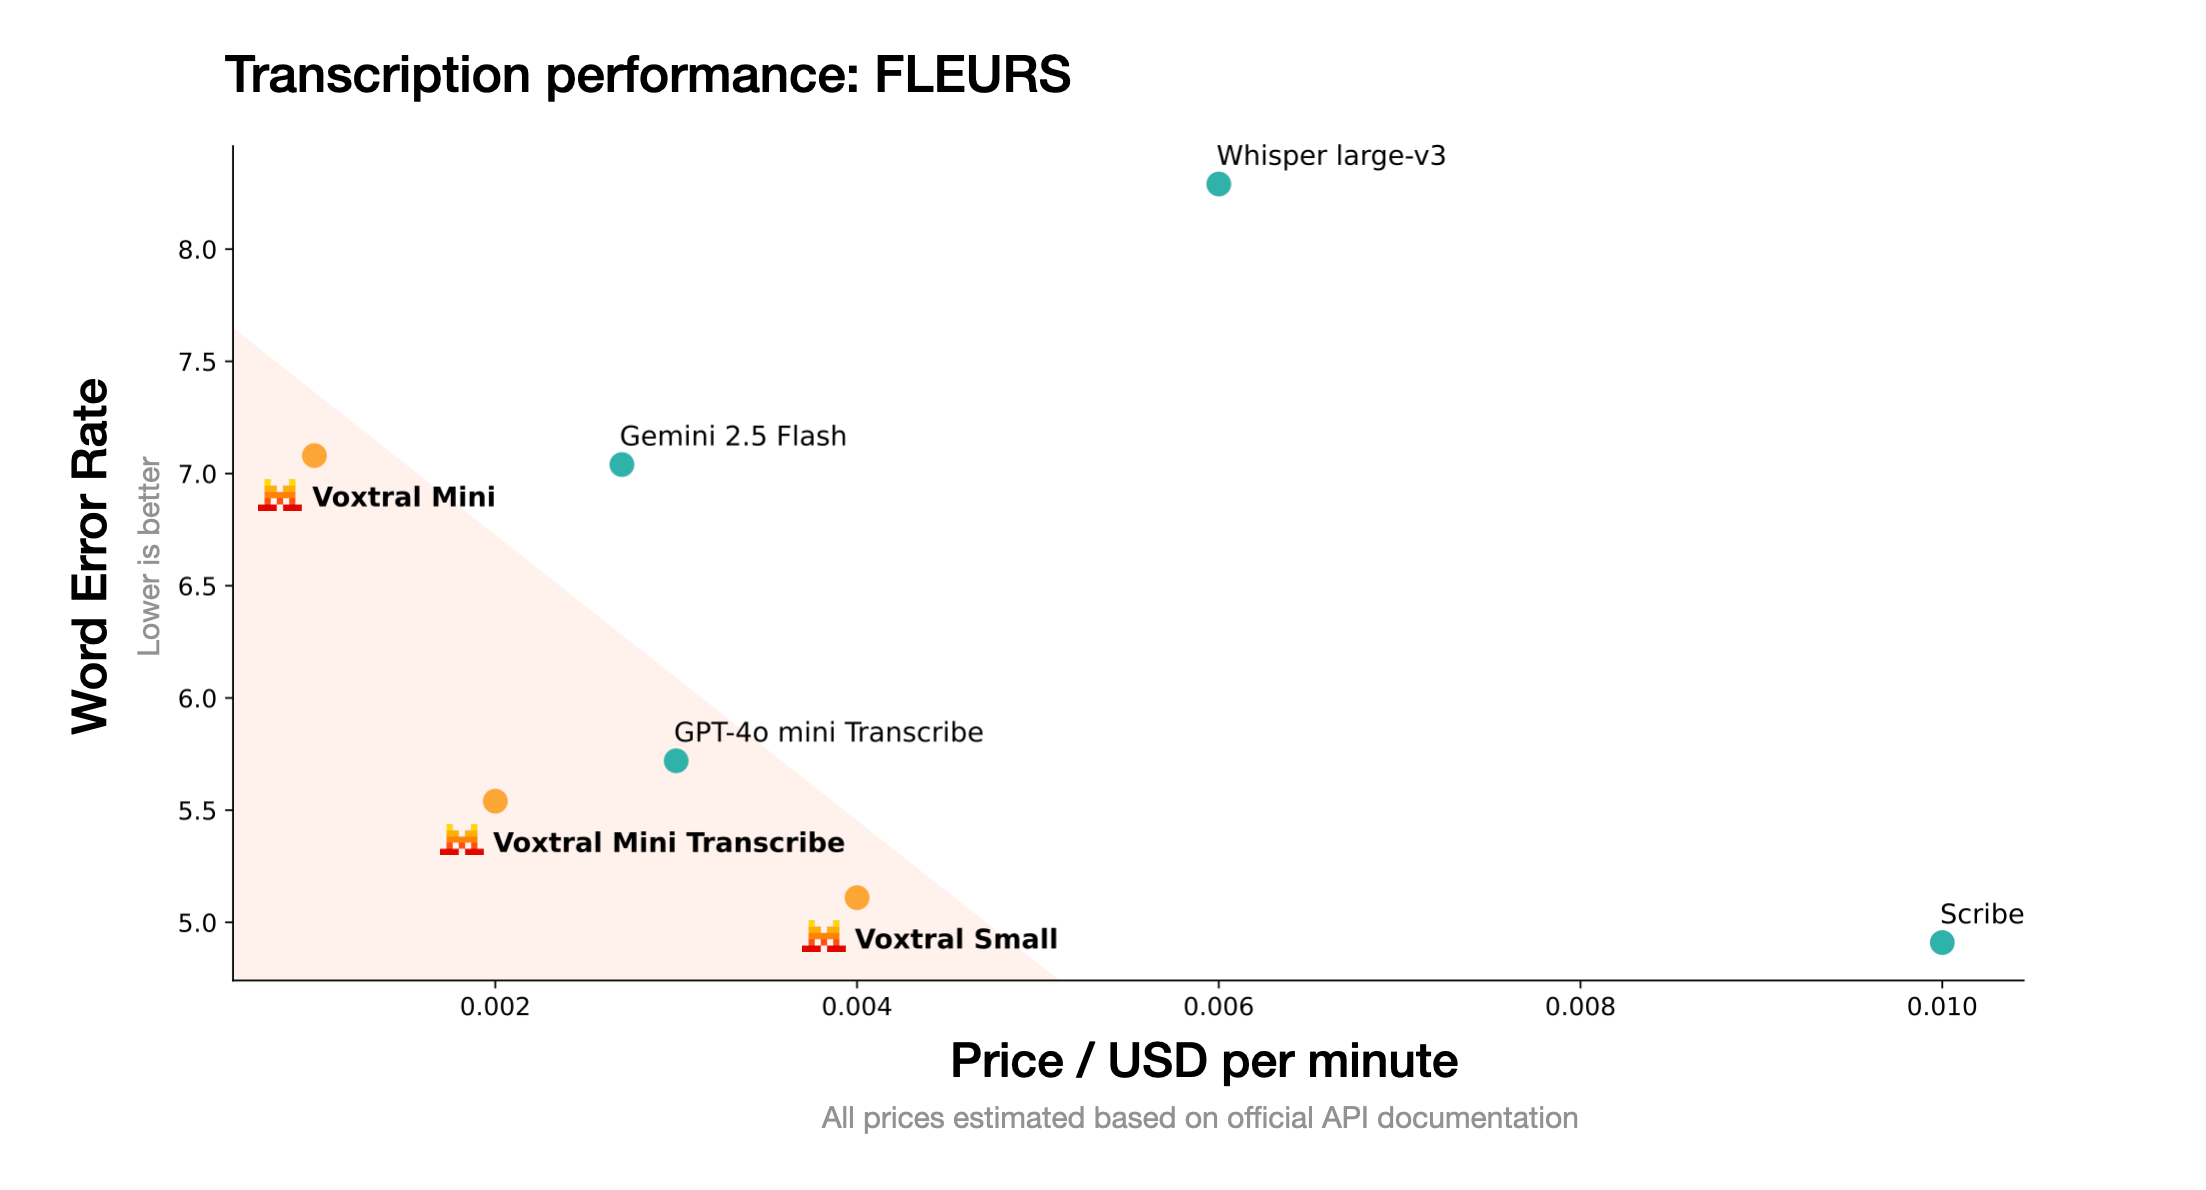
Mistral Launches Voxtral: First Open-Source AI Audio Models Challenge Closed Systems
 News
Moonvalley launches Marey, a video generation model trained entirely on open data
 News
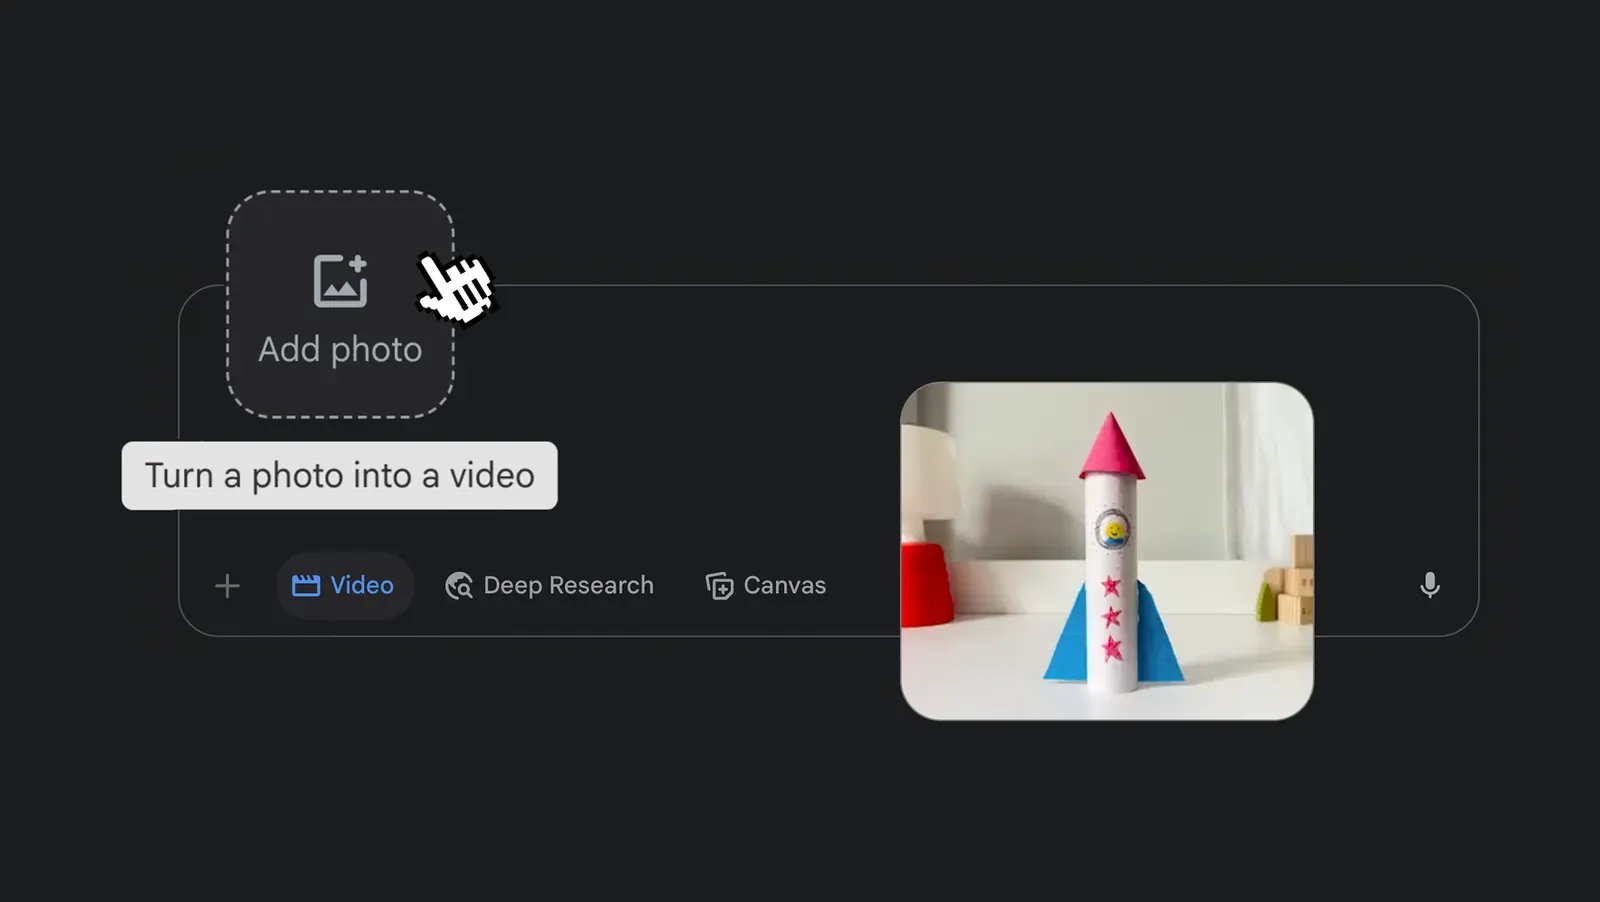
Google now offers a photo-to-video feature for Veo 3 through the Gemini app
 News
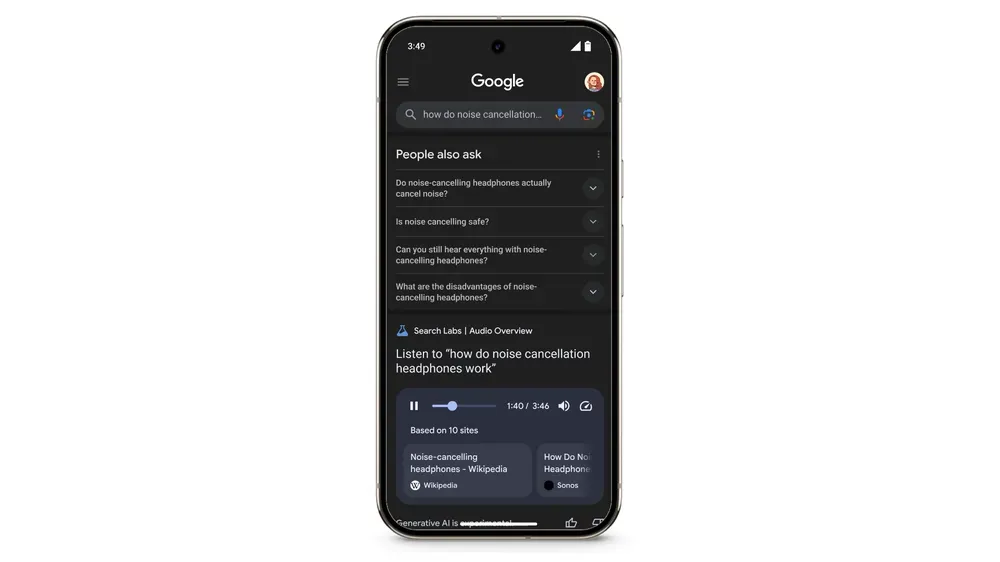
Google's newest experiment brings short audio overviews to some Search queries
 News
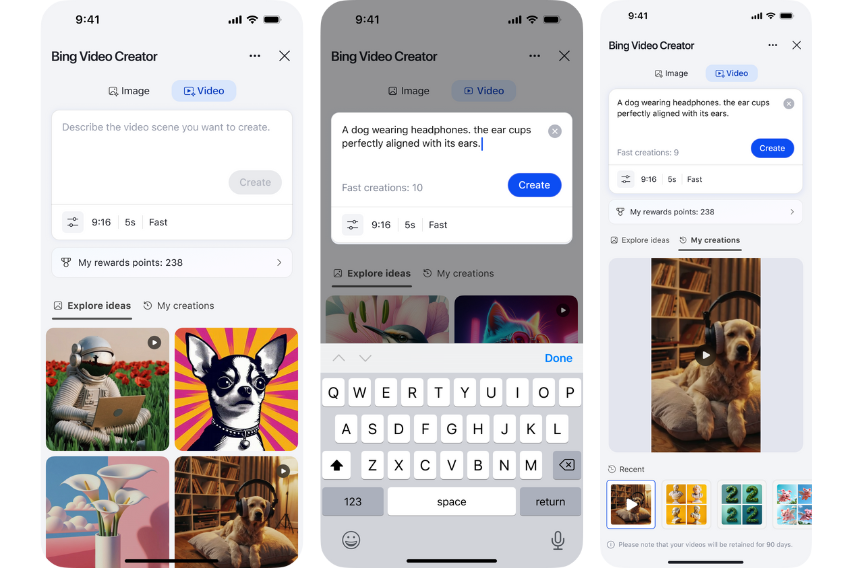
Microsoft launches the Sora-powered Bing Video Creator
 News
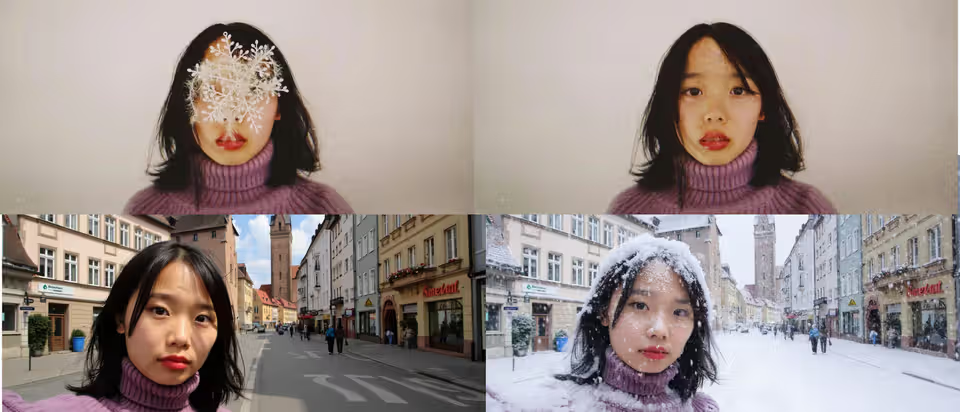
Black Forest Labs Unveils FLUX.1 Kontext: AI image generation meets real-time editing
 News
Google announced several updates across its media generation models
 News
Google announced updates to the Gemini app, including Imagen 4 and Veo 3 access
 News
Google introduces Veo 2 for video generation in Gemini and Whisk
 News
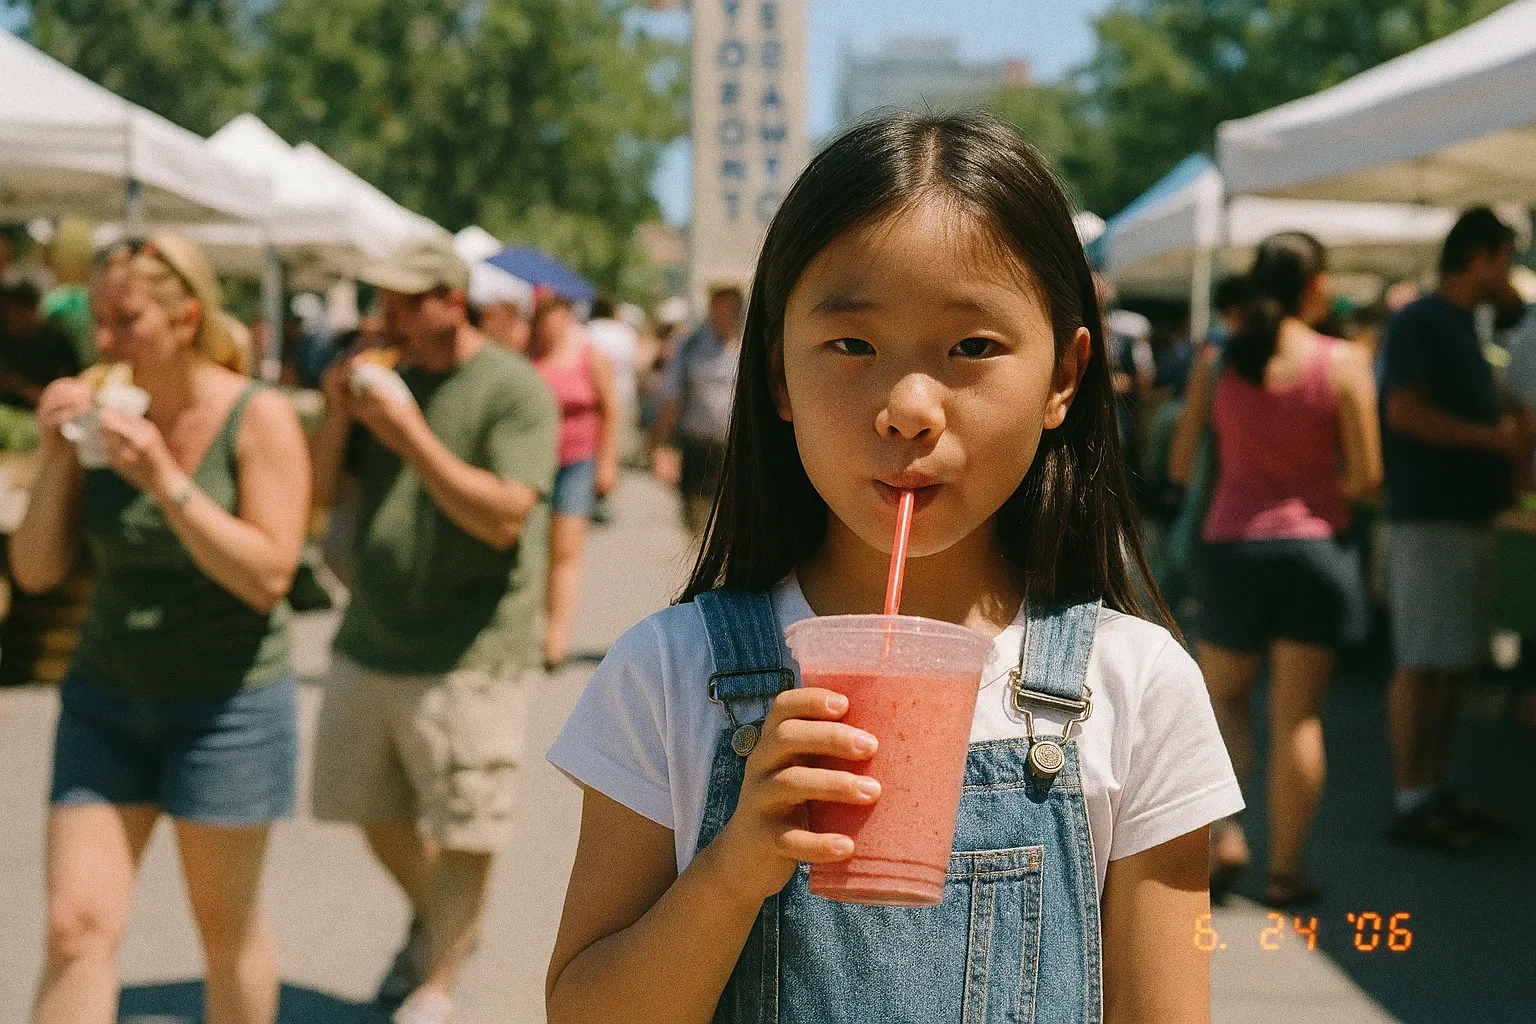
Llama 4: Meta's first natively multimodal mixture-of-experts (MoE) architecture models
 News
OpenAI delays the new GPT-4o image generation feature for free users due to high demand