Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
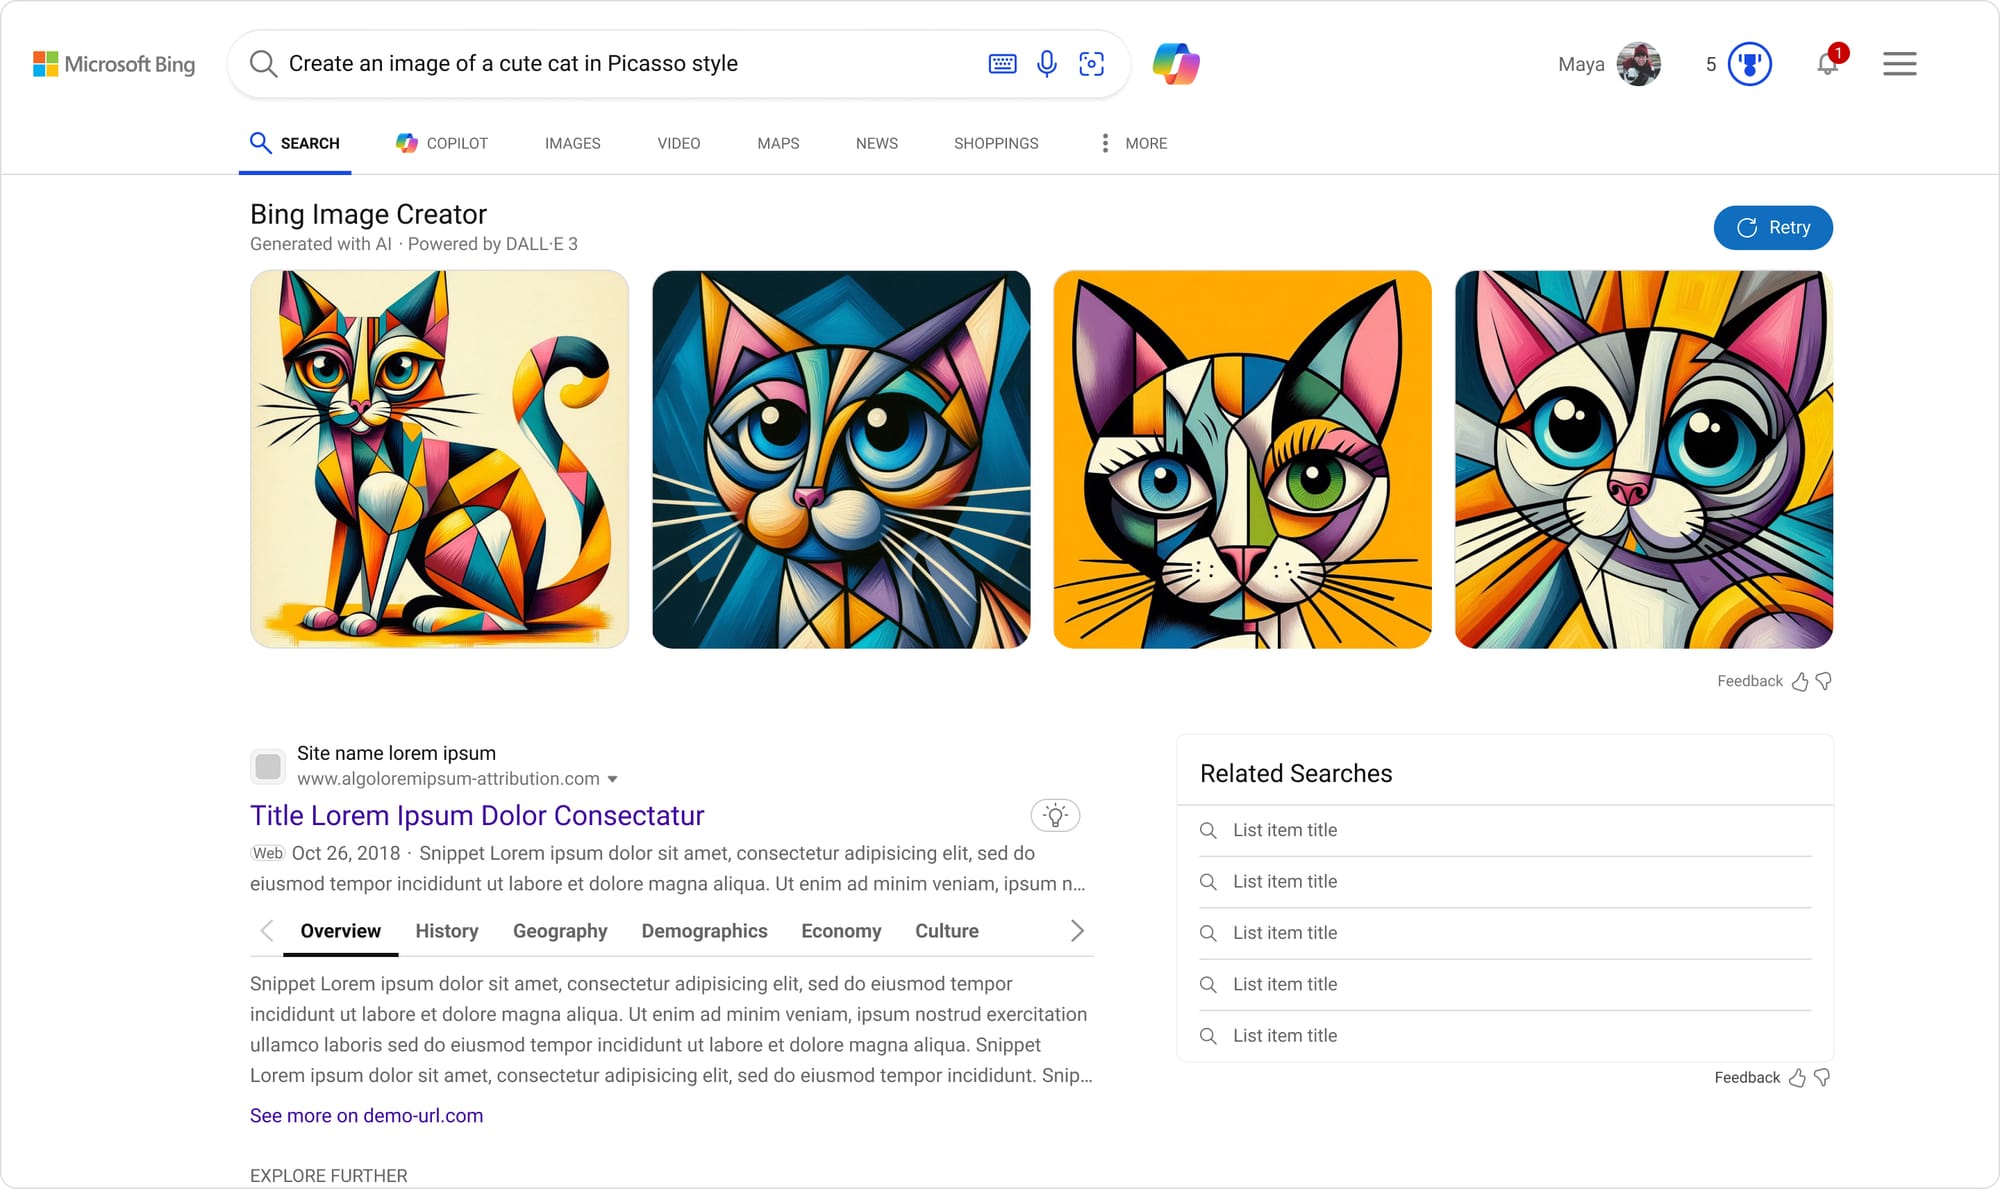
Microsoft Reverses Changes to Bing Image Creator Amid User Backlash
 News
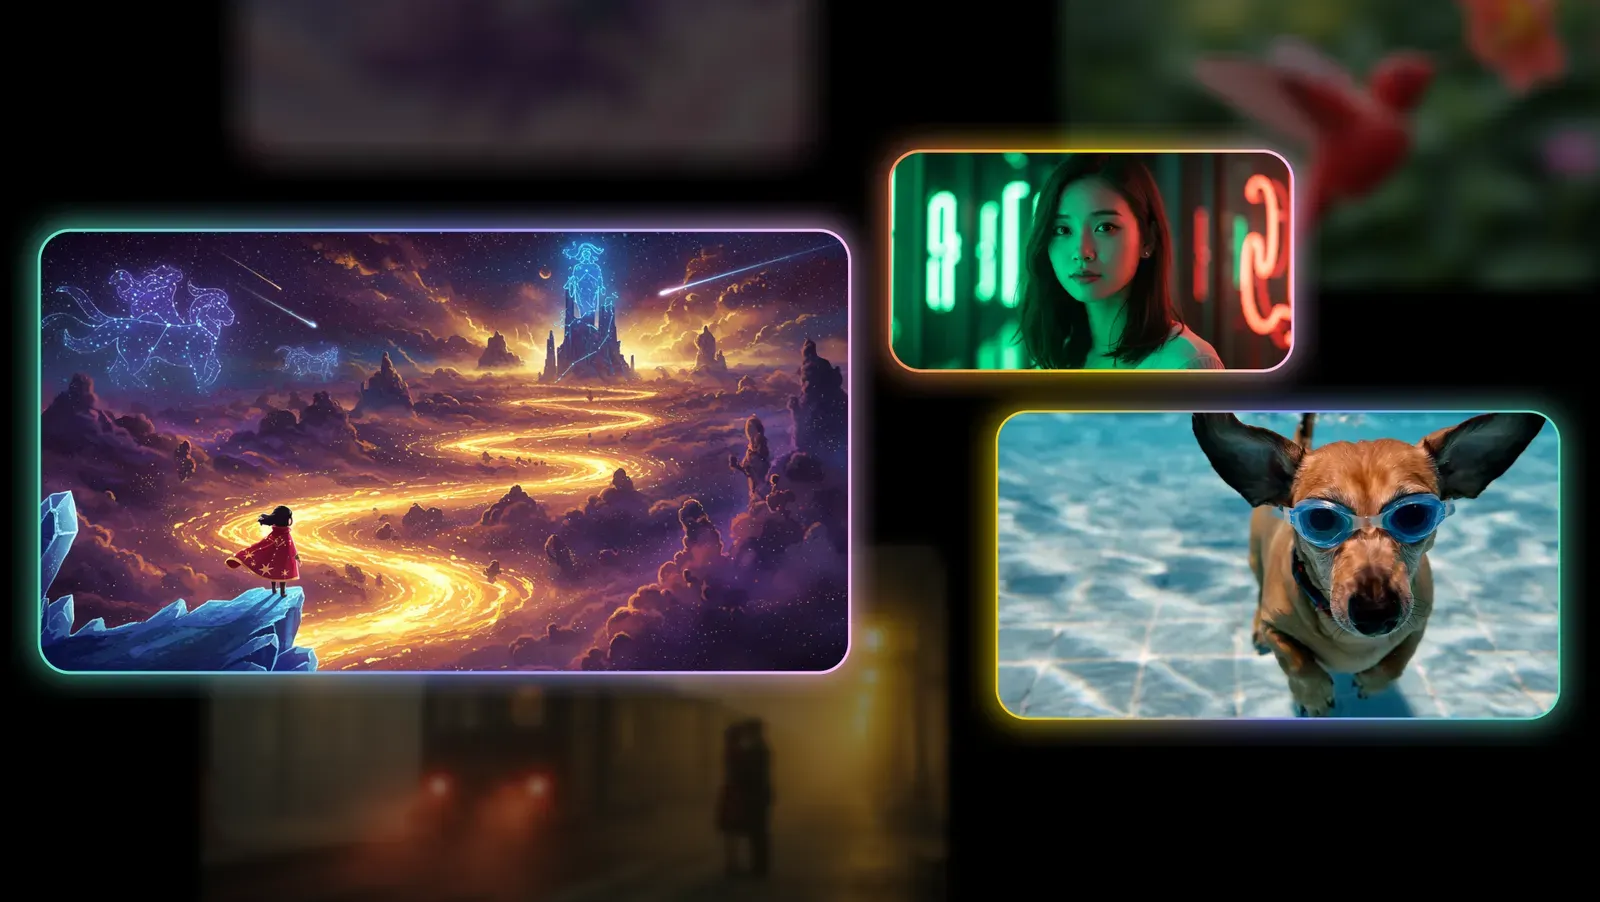
Google DeepMind's Veo 2 is here to steal the spotlight from OpenAI's Sora
 News
The redesigned NotebookLM lets users interact with its AI hosts and has a paid tier
 News
Grok just got a new image generator and a free usage tier
 News
Microsoft cautiously launched a Copilot Vision preview in the US
 News
Google DeepMind's Genie 2 creates minute-long playable 3D environments
 News
World Labs showcased a preview of its interactive 3D scene generator
 News
Nova is Amazon's new family of multimodal foundation models
 News
Bertelsmann and ElevenLabs announce partnership to boost creativity and productivity
 News
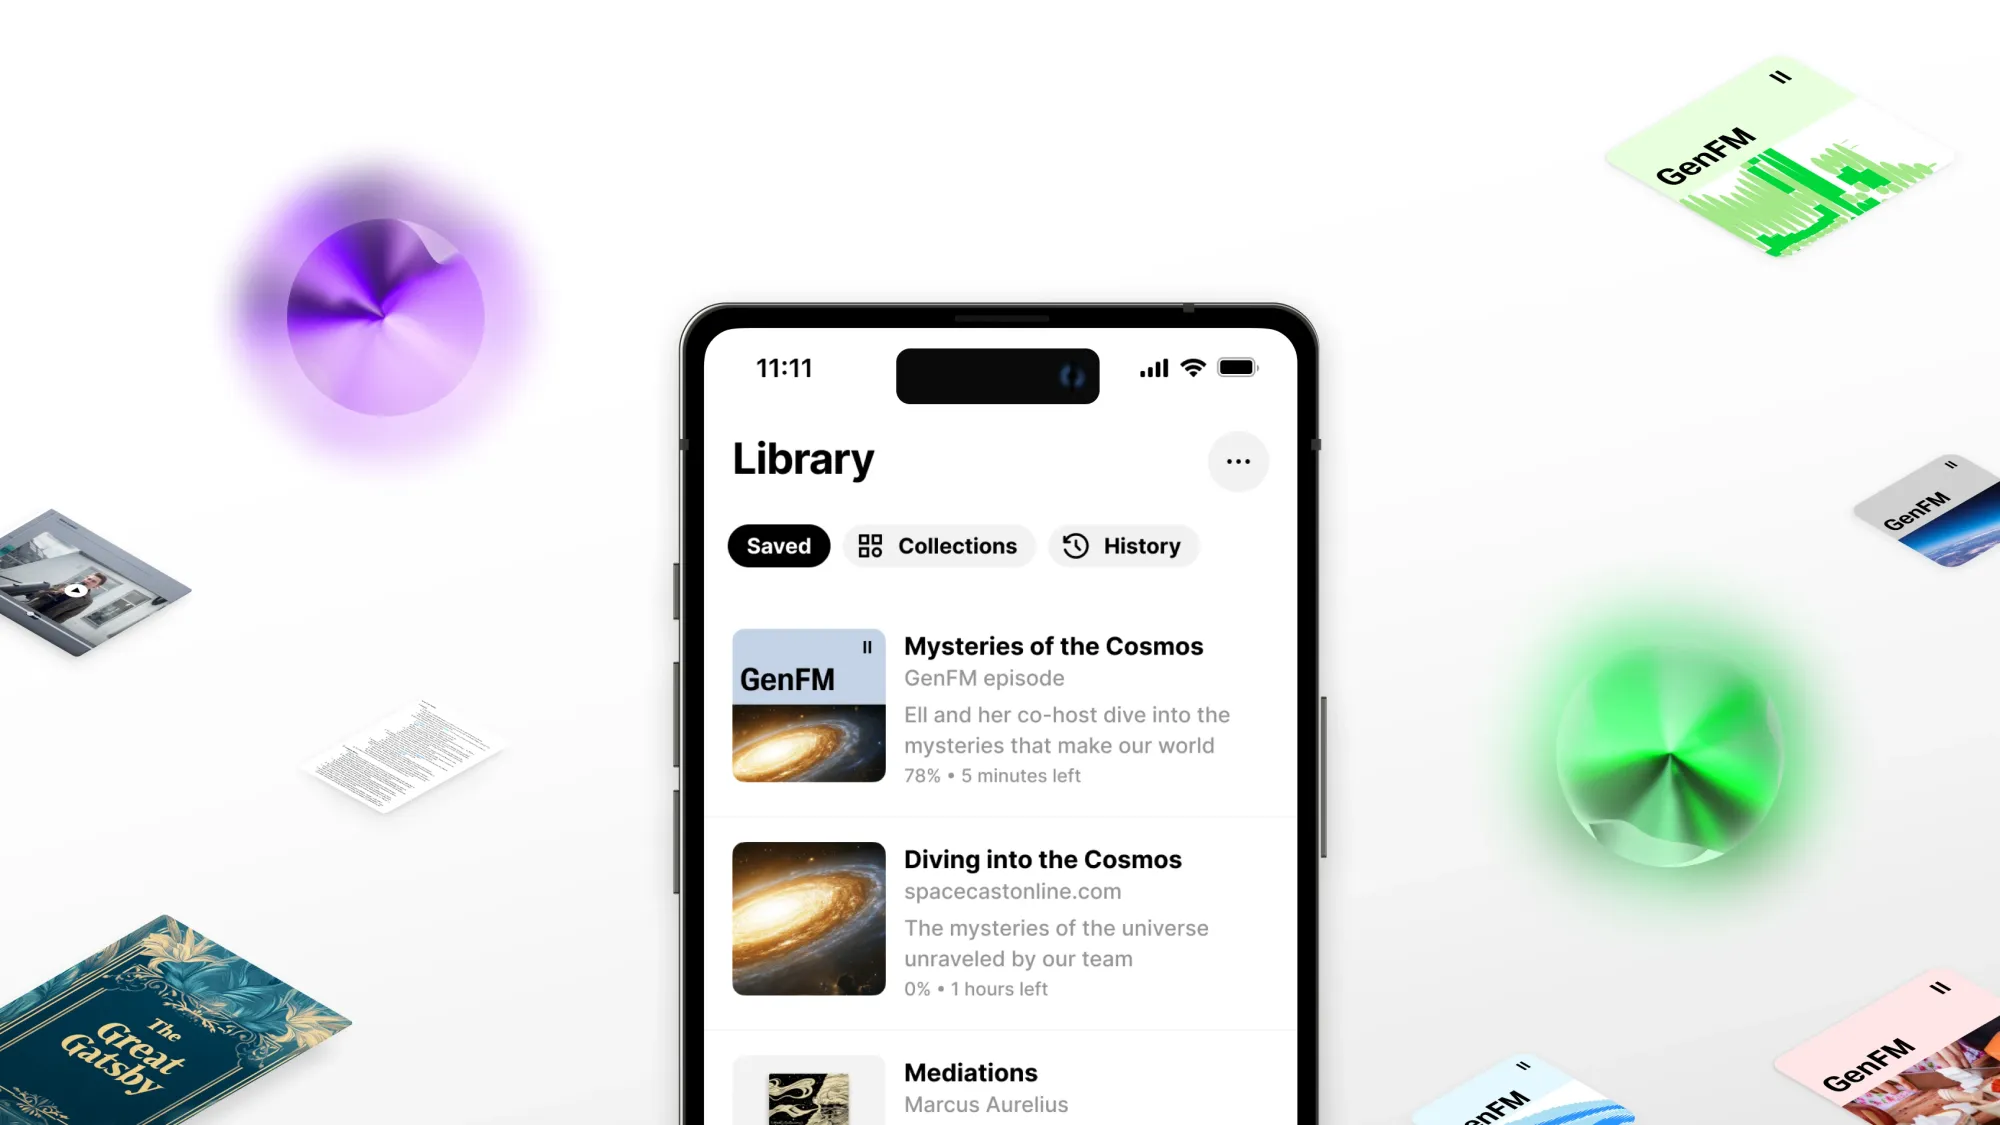
ElevenLabs has added a podcast generation feature to its Reader app
- News
IMAX is testing Camb.ai's AI-powered localization services to reach new audiences
 News
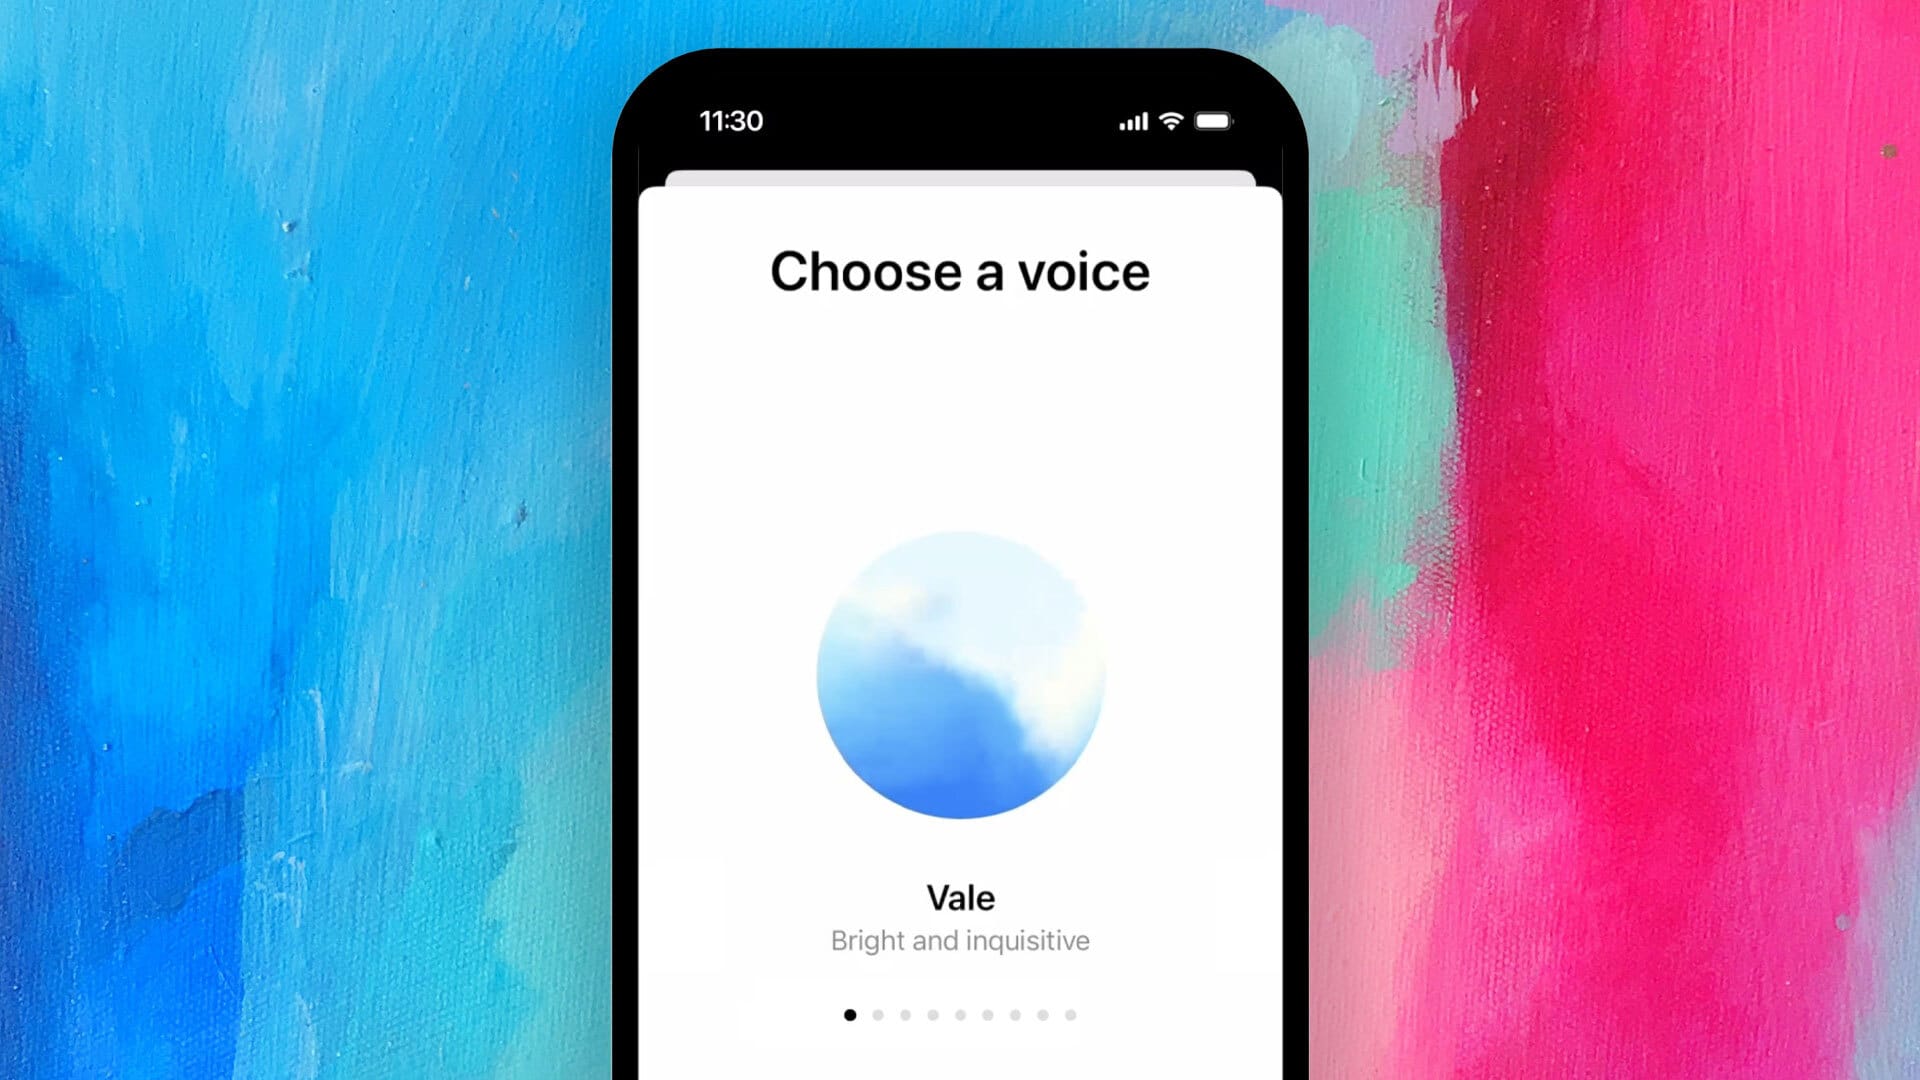
OpenAI launched Advanced Voice Mode on the web
