Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
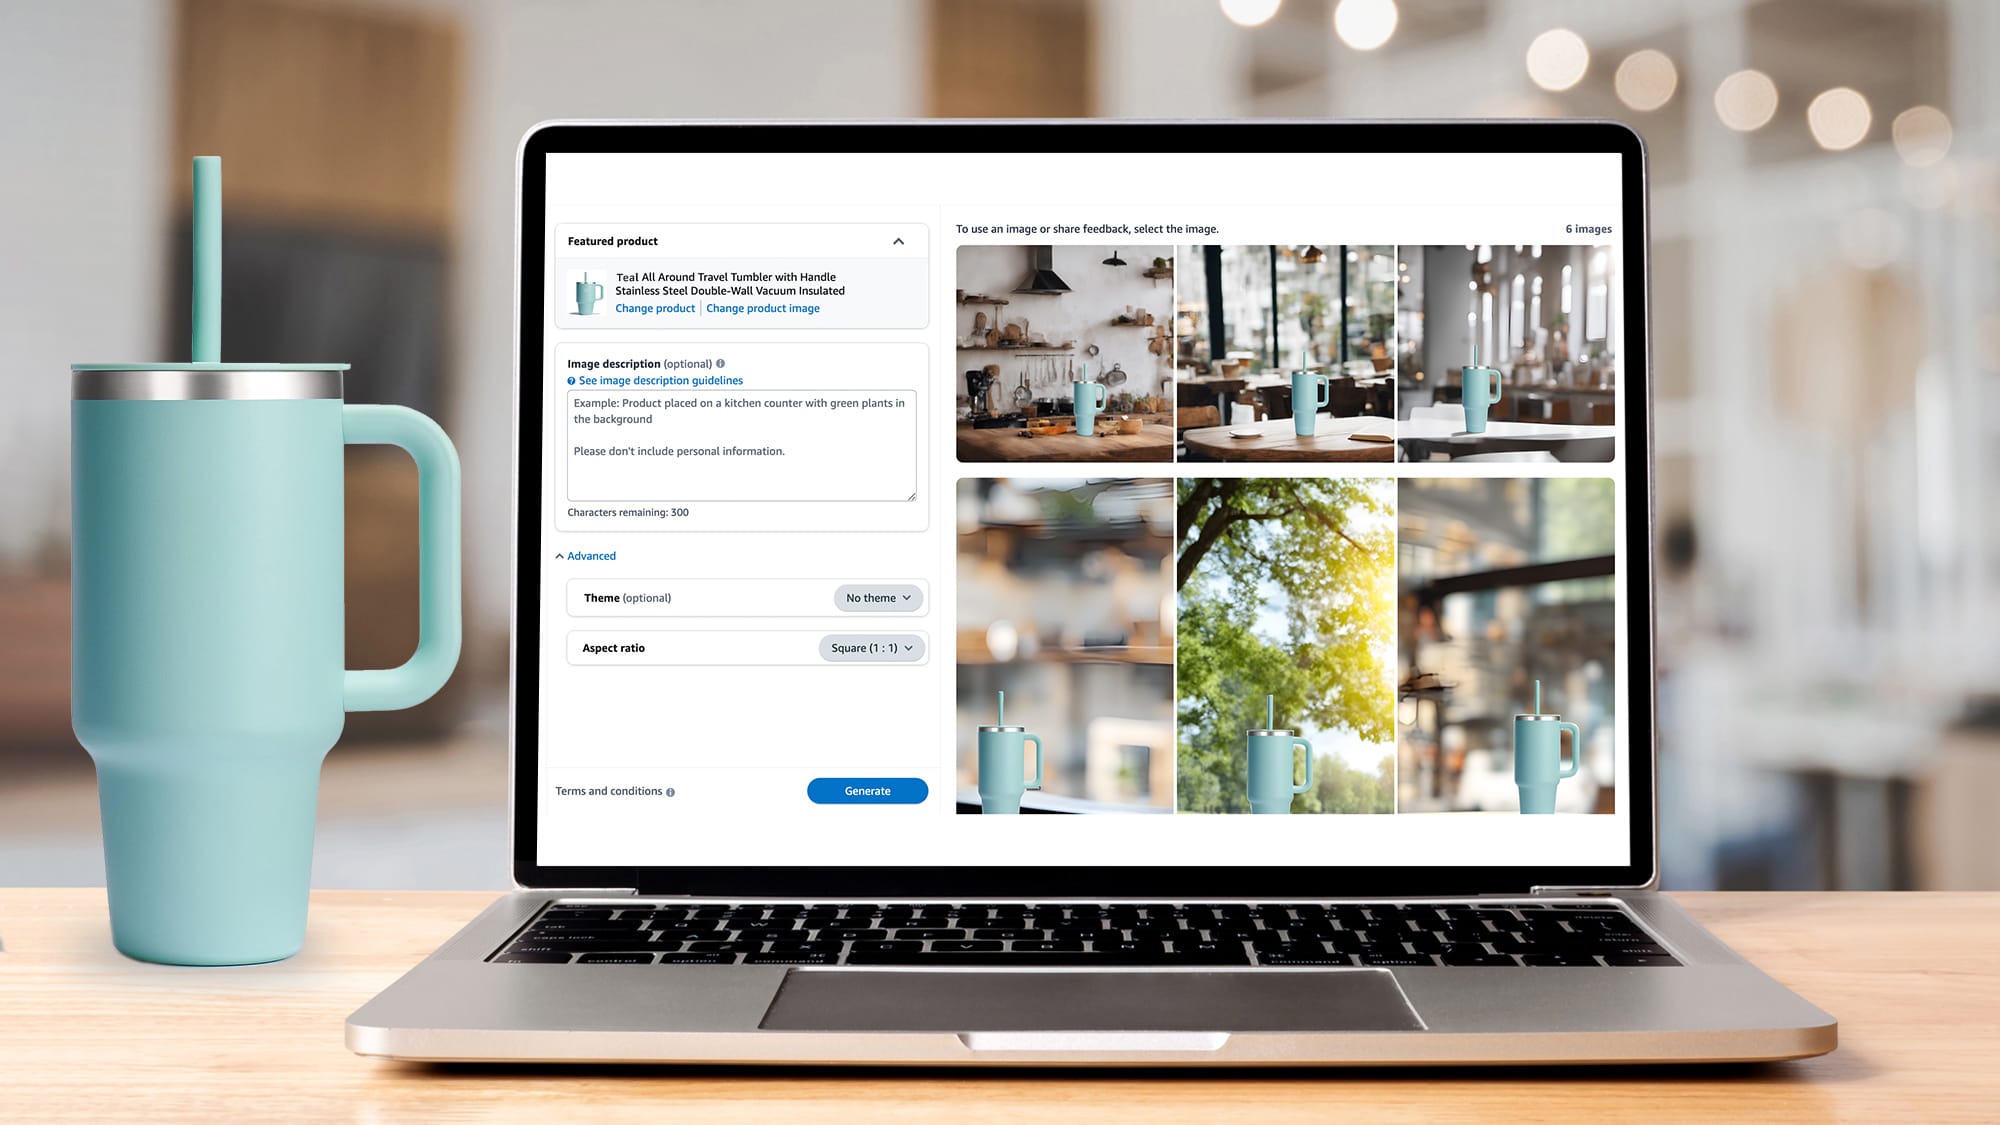
Amazon launched a video generator for its Amazon Ads service
 News
YouTube launched new AI features at its 'Made on YouTube' event
 News
Runway and Lionsgate announce partnership to create a custom cinematic video model
 News
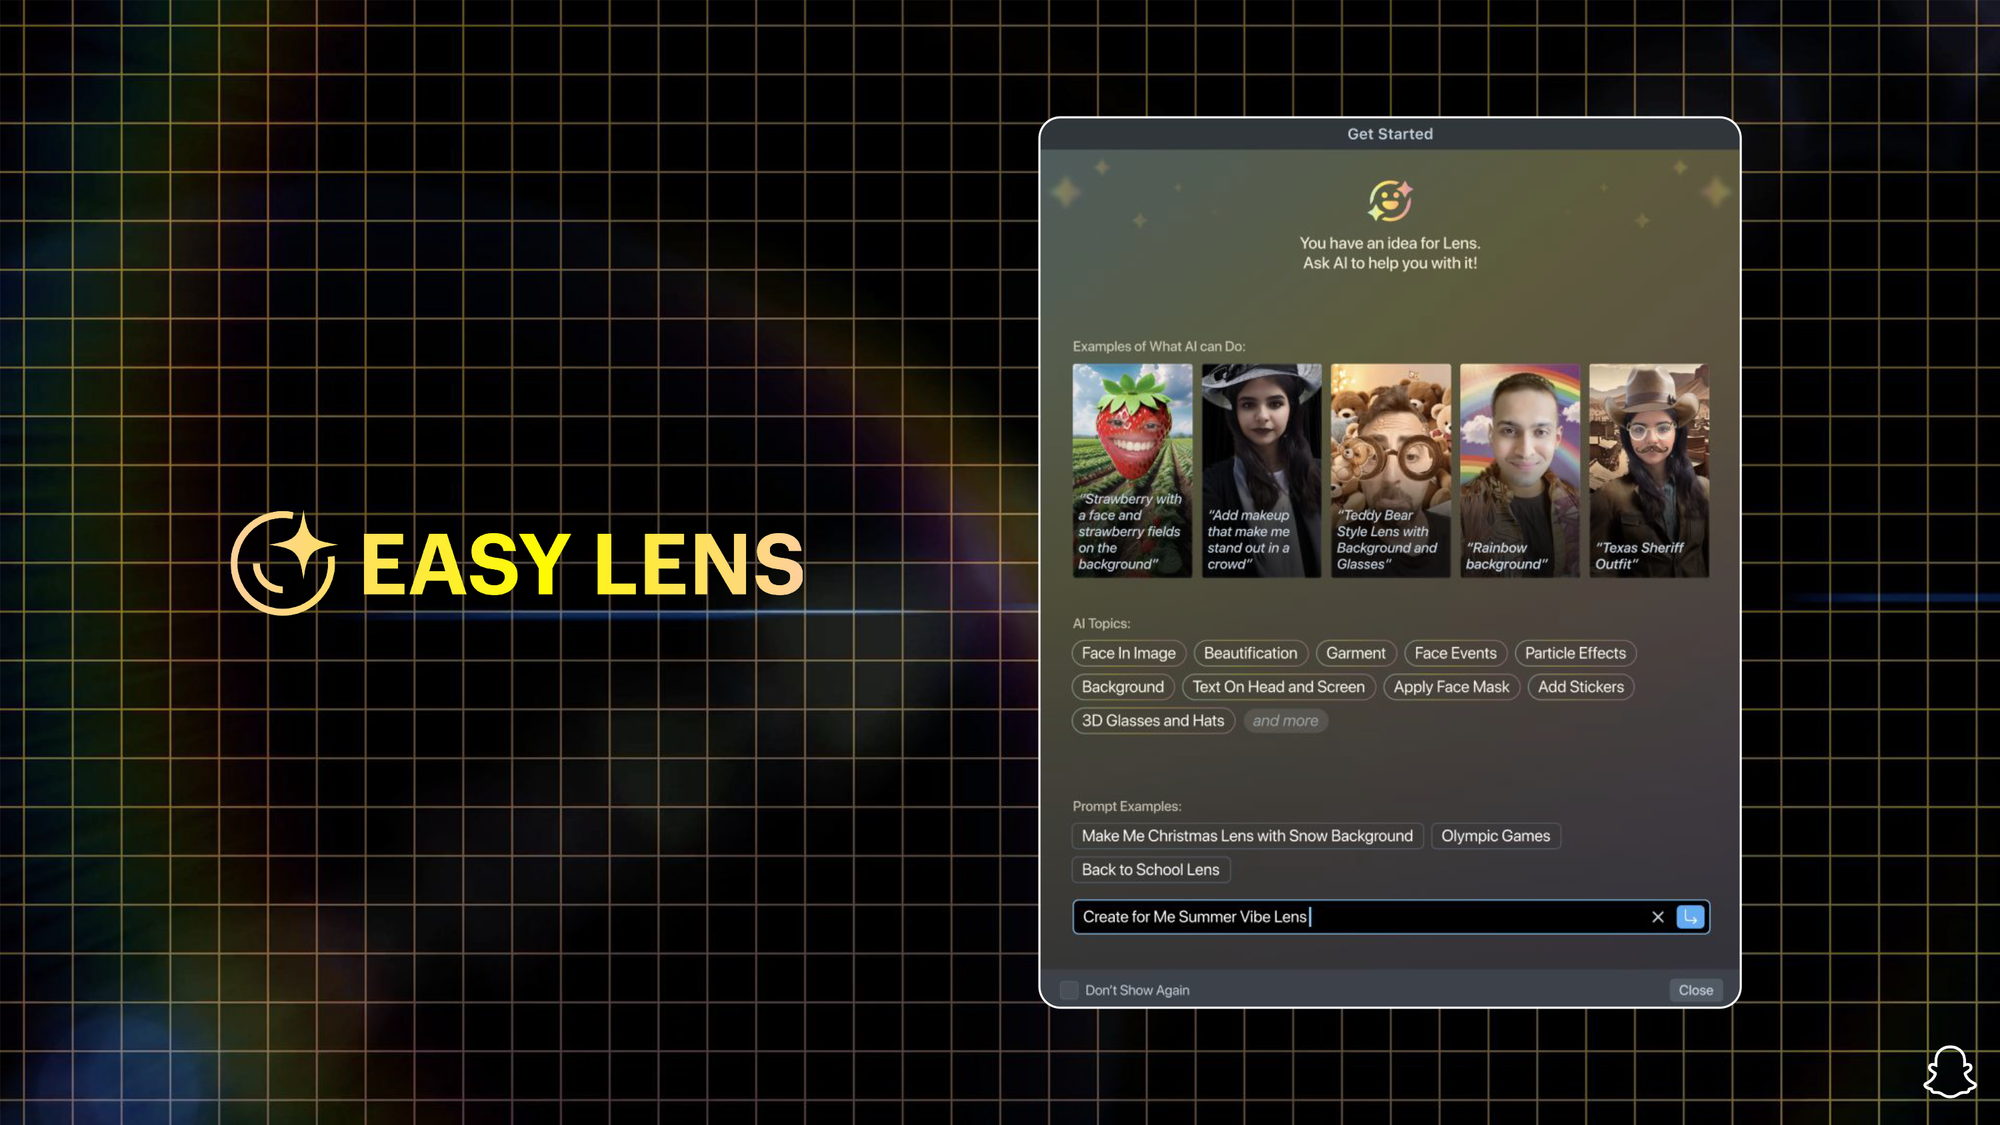
Snap announced new generative AI features at Snap Partner Summit 2024
 News
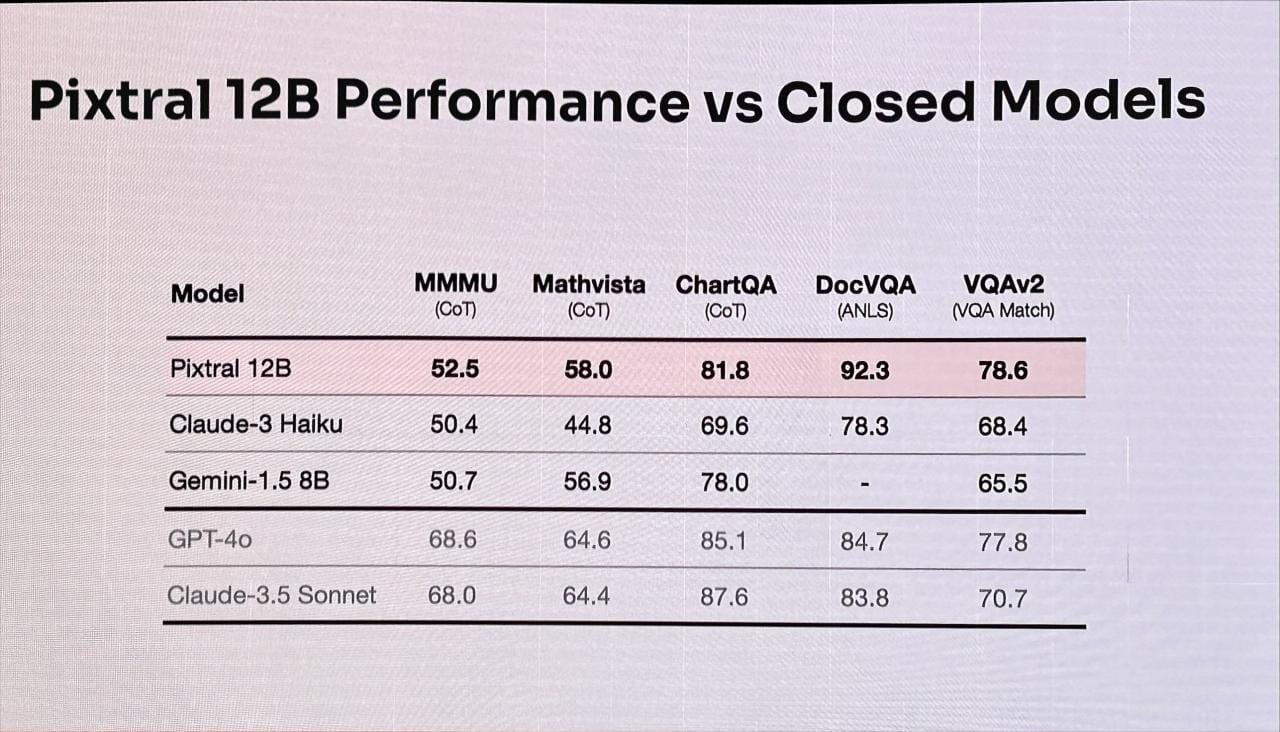
Pixtral 12B is Mistral AI's first open-source multimodal model
 News
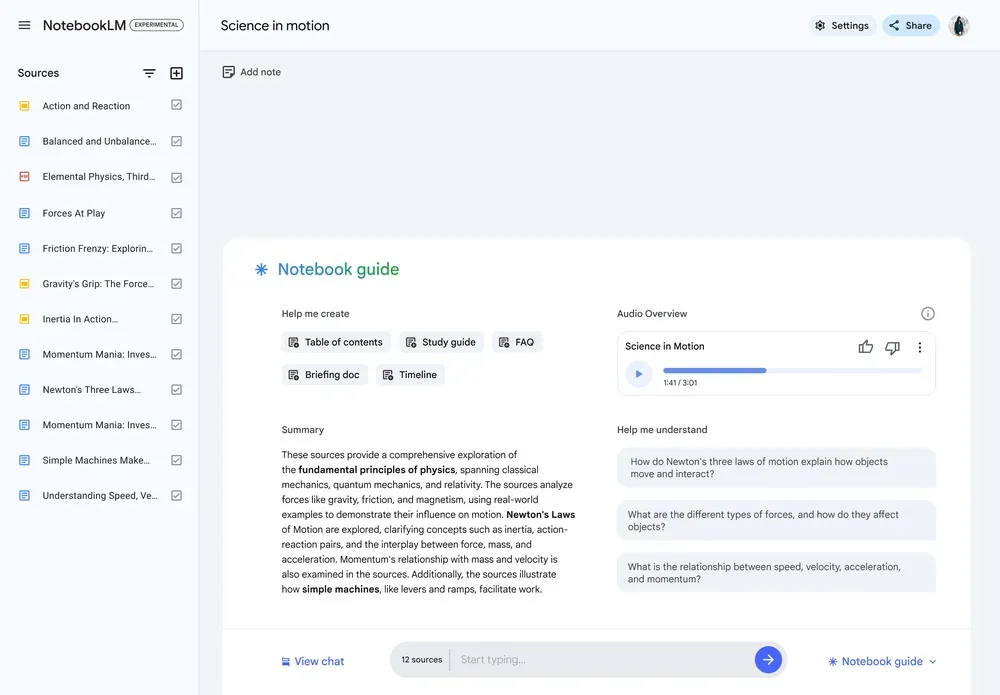
A new NotebookLM feature lets users listen to conversations based on their sources
 News
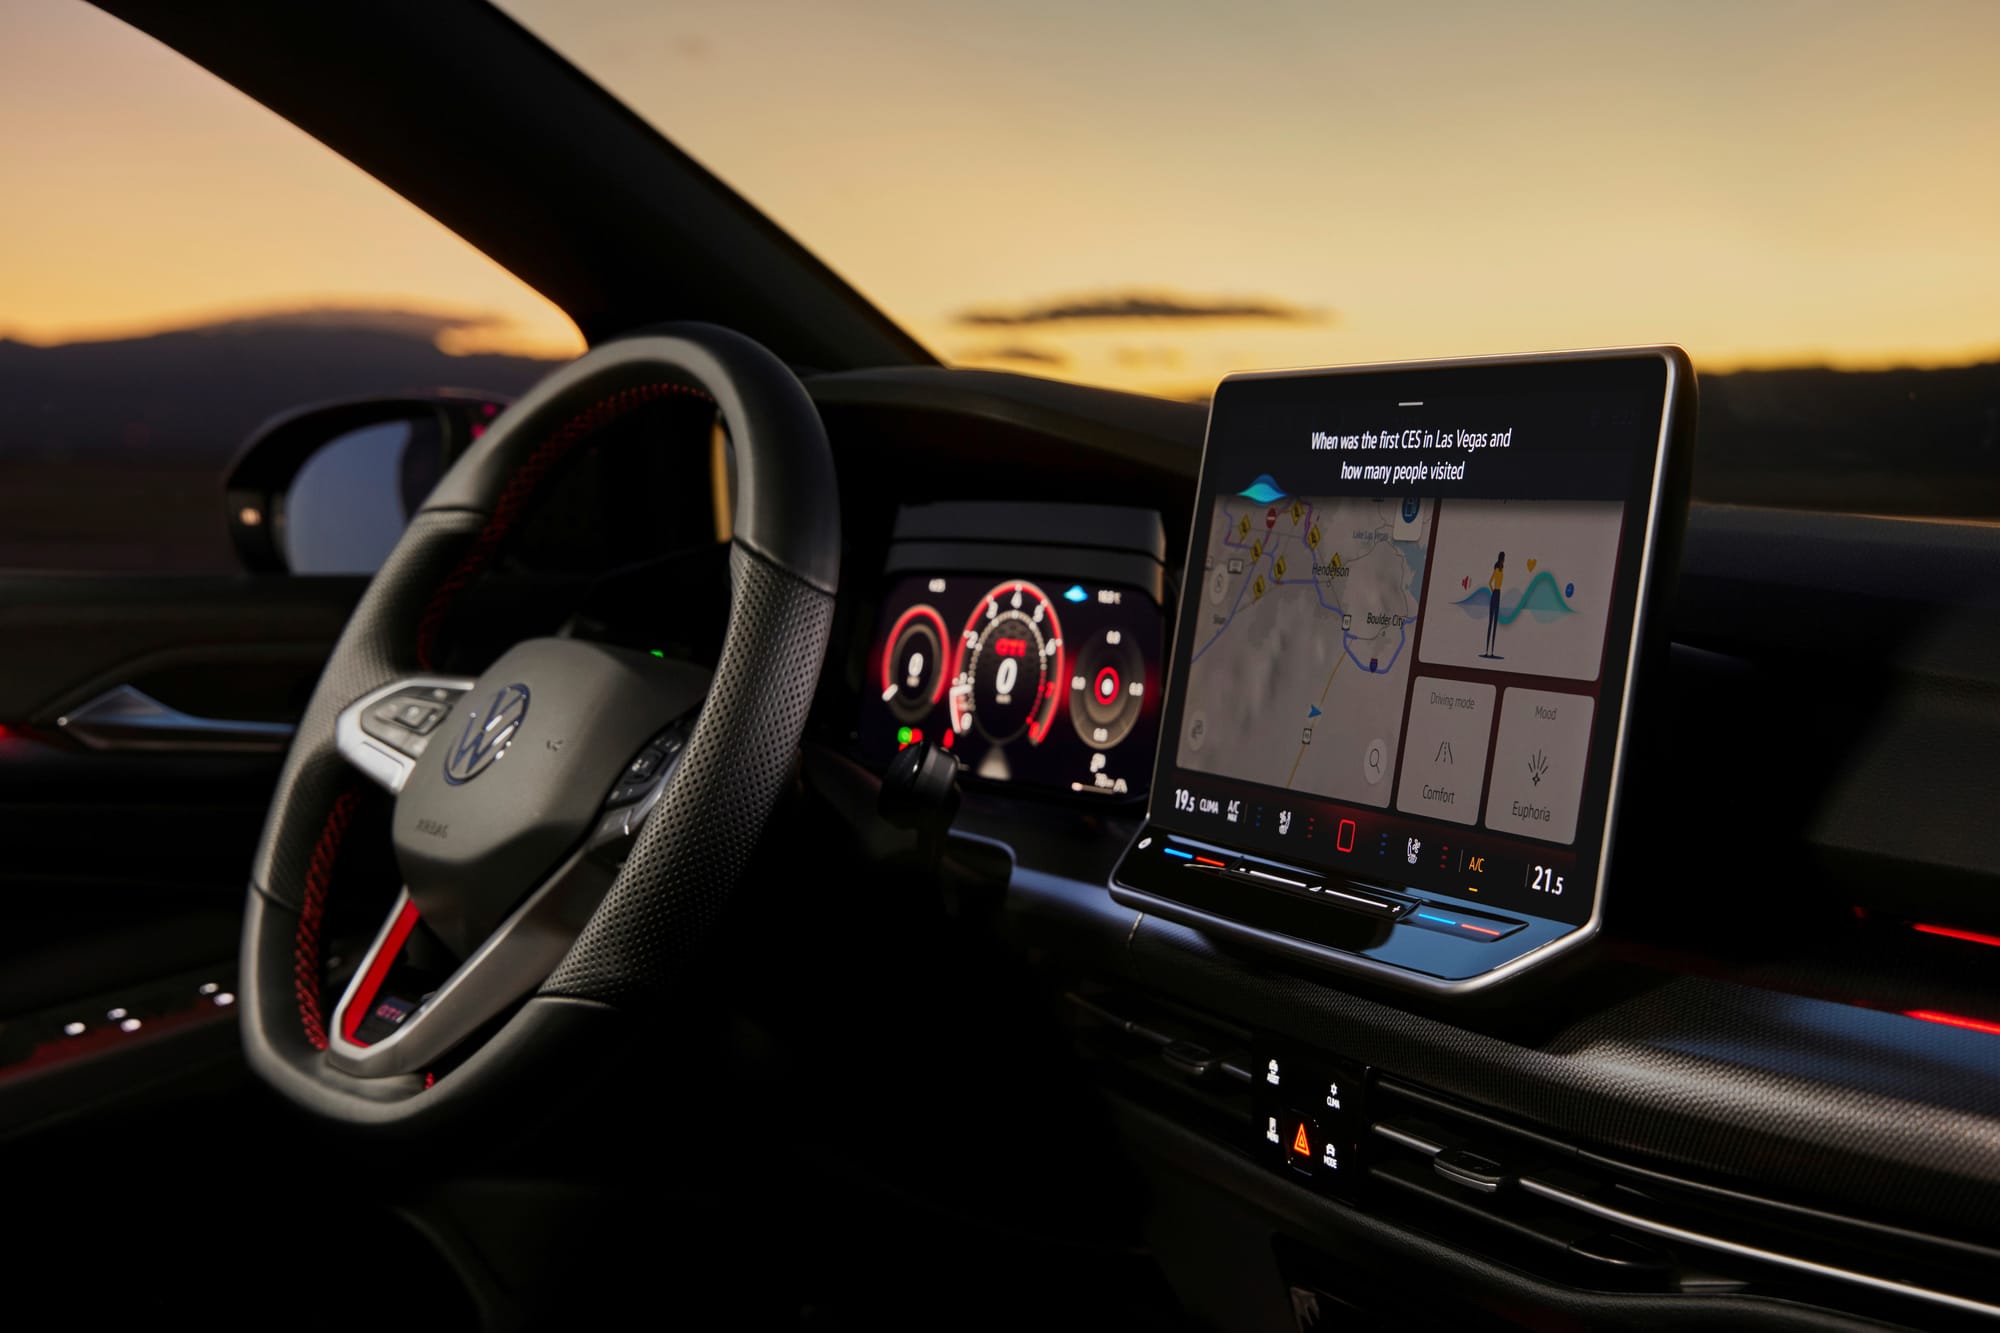
ChatGPT-powered voice assist is coming to some Volkswagen models in the US market
 News
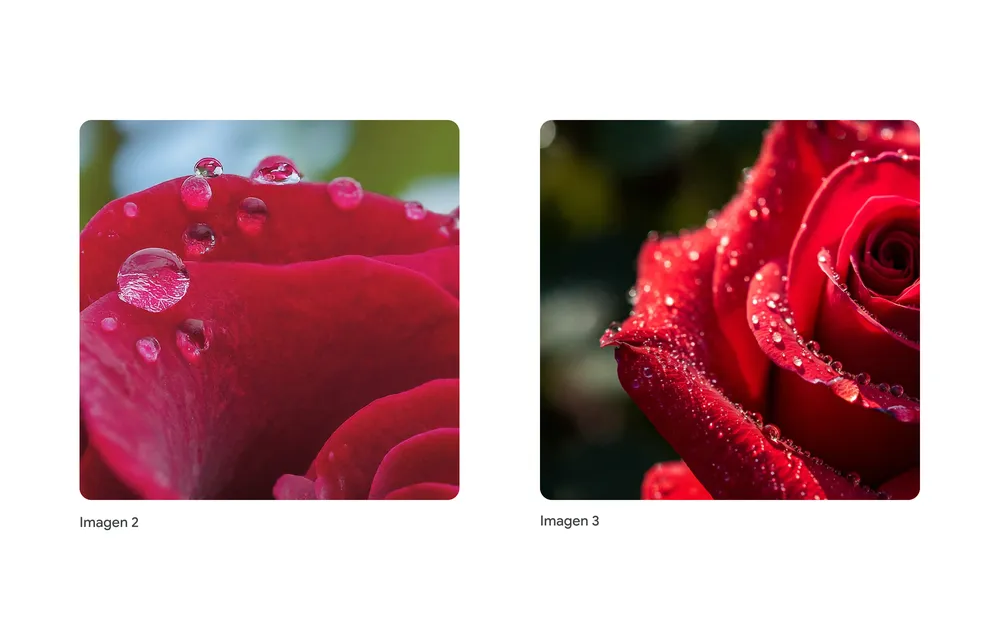
Google announces Gems, Imagen 3, and an early preview for improved people-generation capabilities
 News
The Weeknd teased an upcoming concert live stream using AI-generated visuals
 News
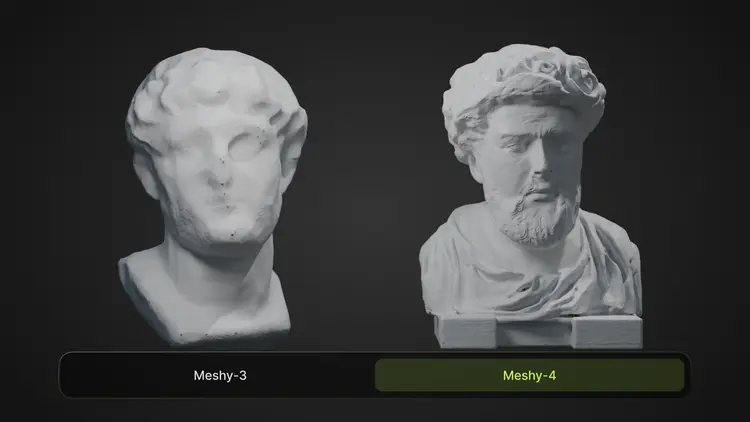
Meshy has launched Meshy-4, a model with improved 3D-generation capabilities
 News
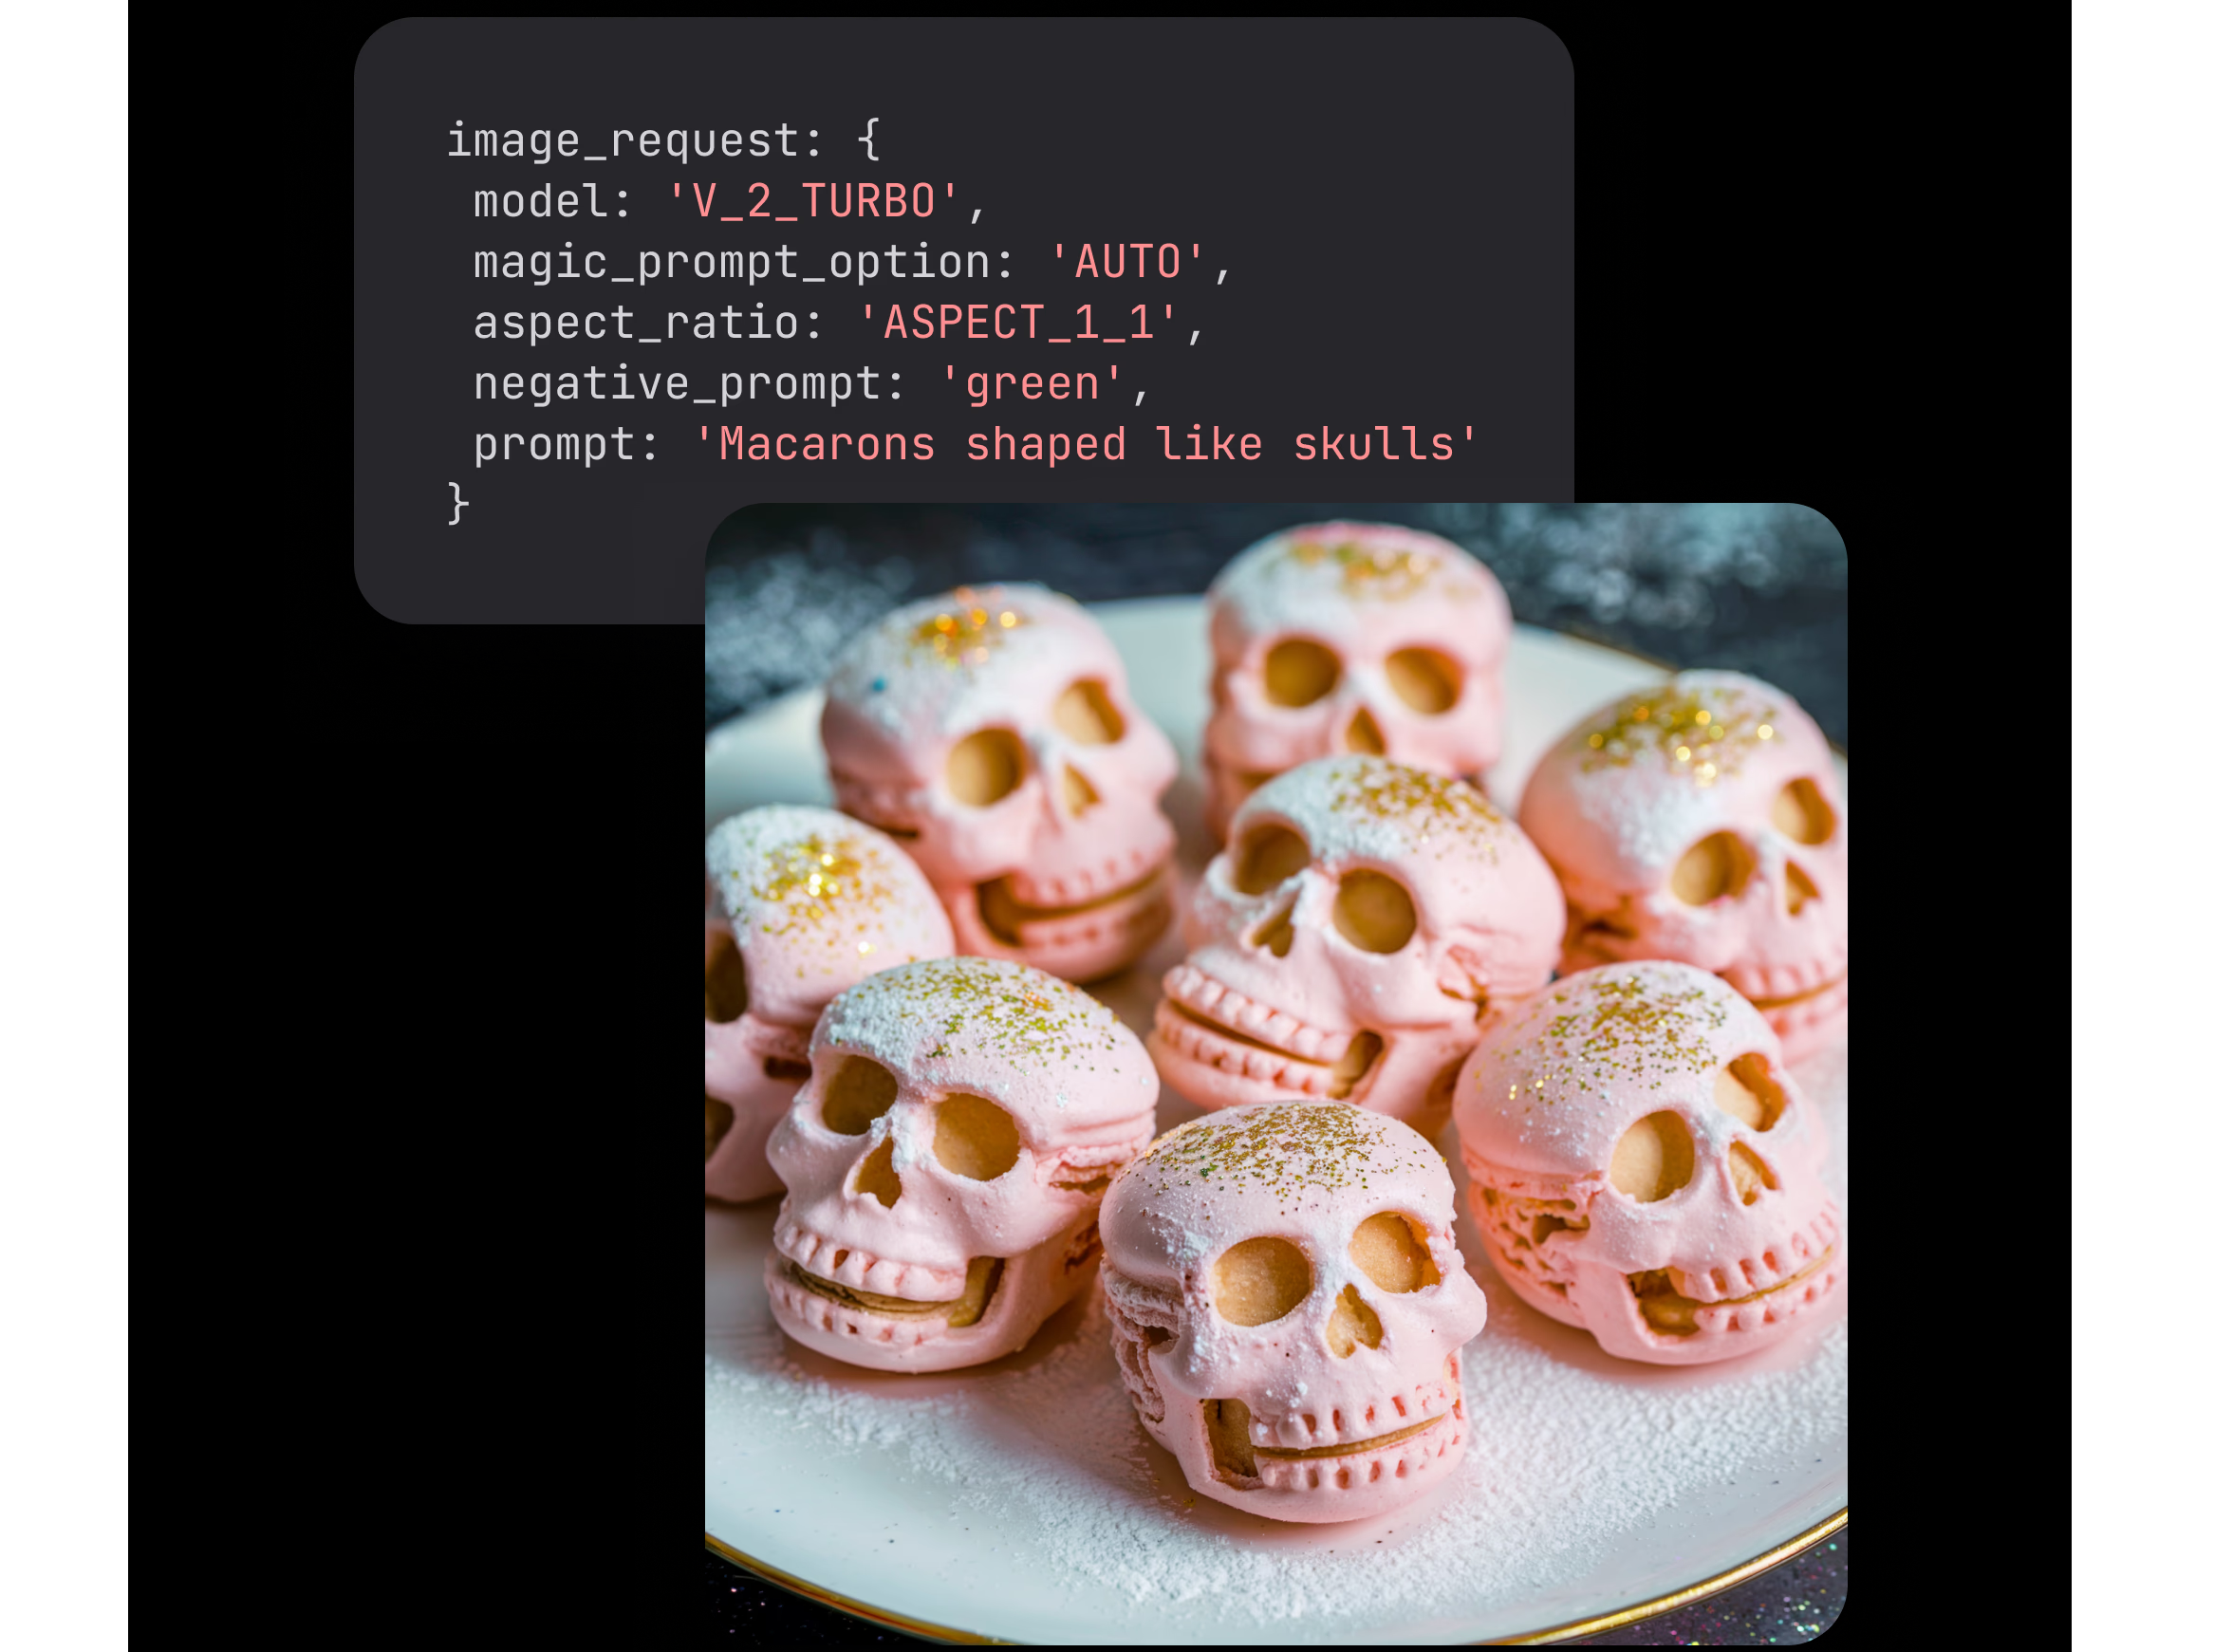
Ideogram 2.0 is the latest text-to-image model to boast its superior text rendering capability
 News
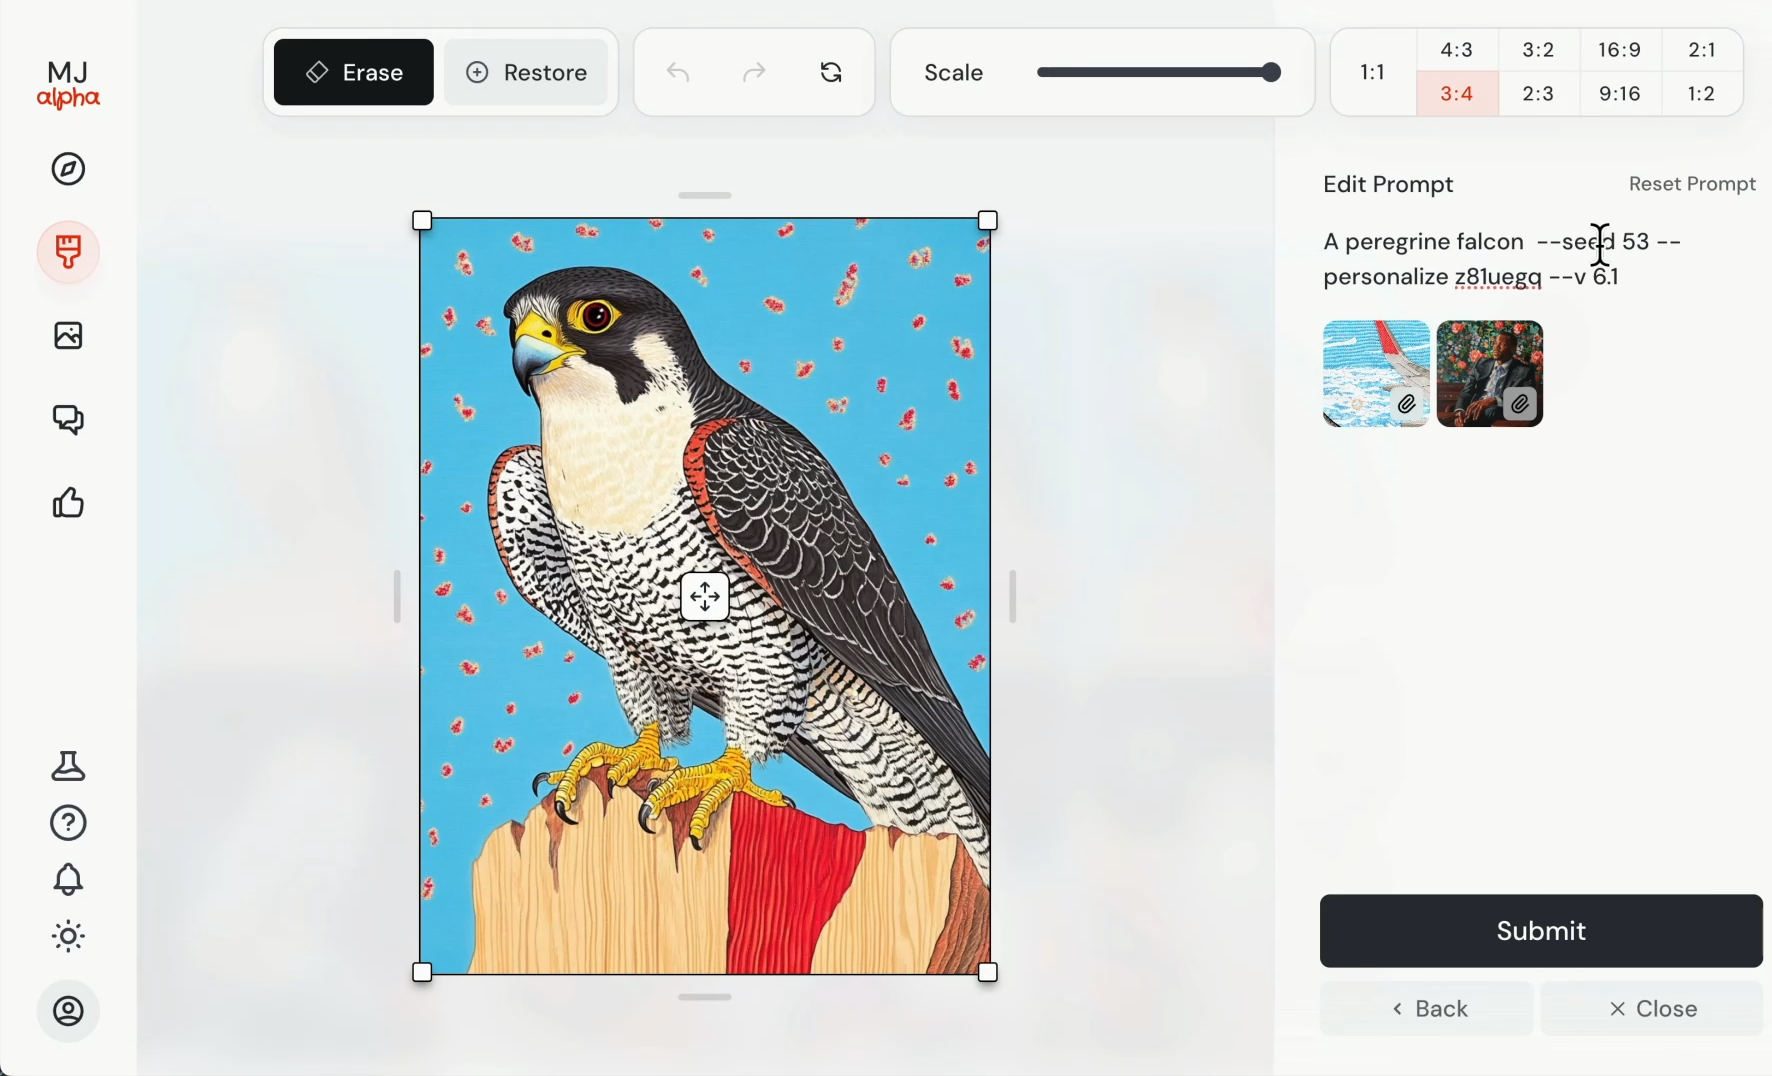
Midjourney launched a new web-based editor interface that brings its editing tools together