Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
ElevenLabs launched a text-to-sound effects AI audio model
- News
OpenAI shared more about how it cast ChatGPT's voices
- News
Mastering sarcasm is AI's latest frontier
 News
OpenAI launched several new tools for ChatGPT along with the new GPT-4o model
 News
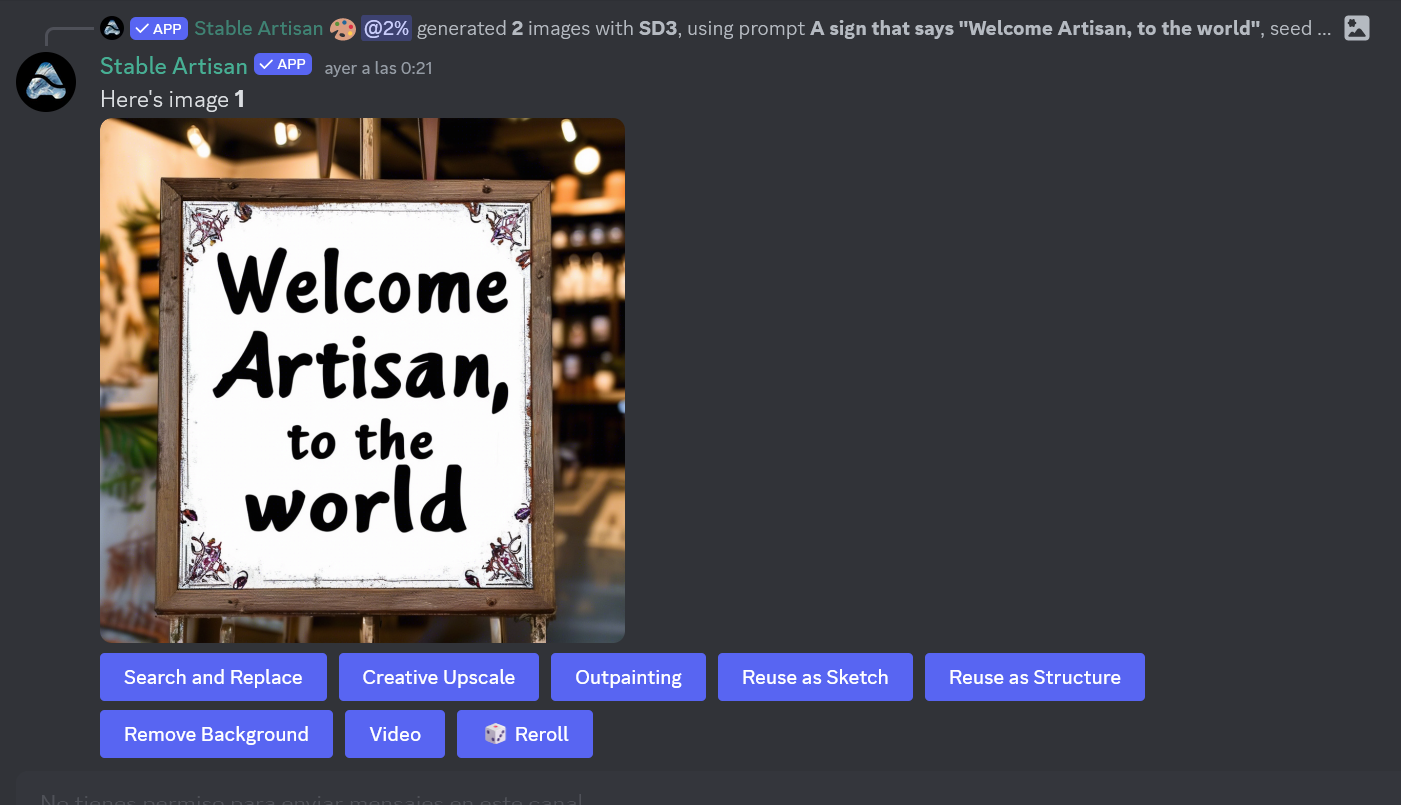
Stable Artisan brings media generation to Discord
 News
Adobe launched Firefly Image 3 to advance its image-generation services
 News
Hugging Face has released Idefics2, a multimodal model for the community
 News
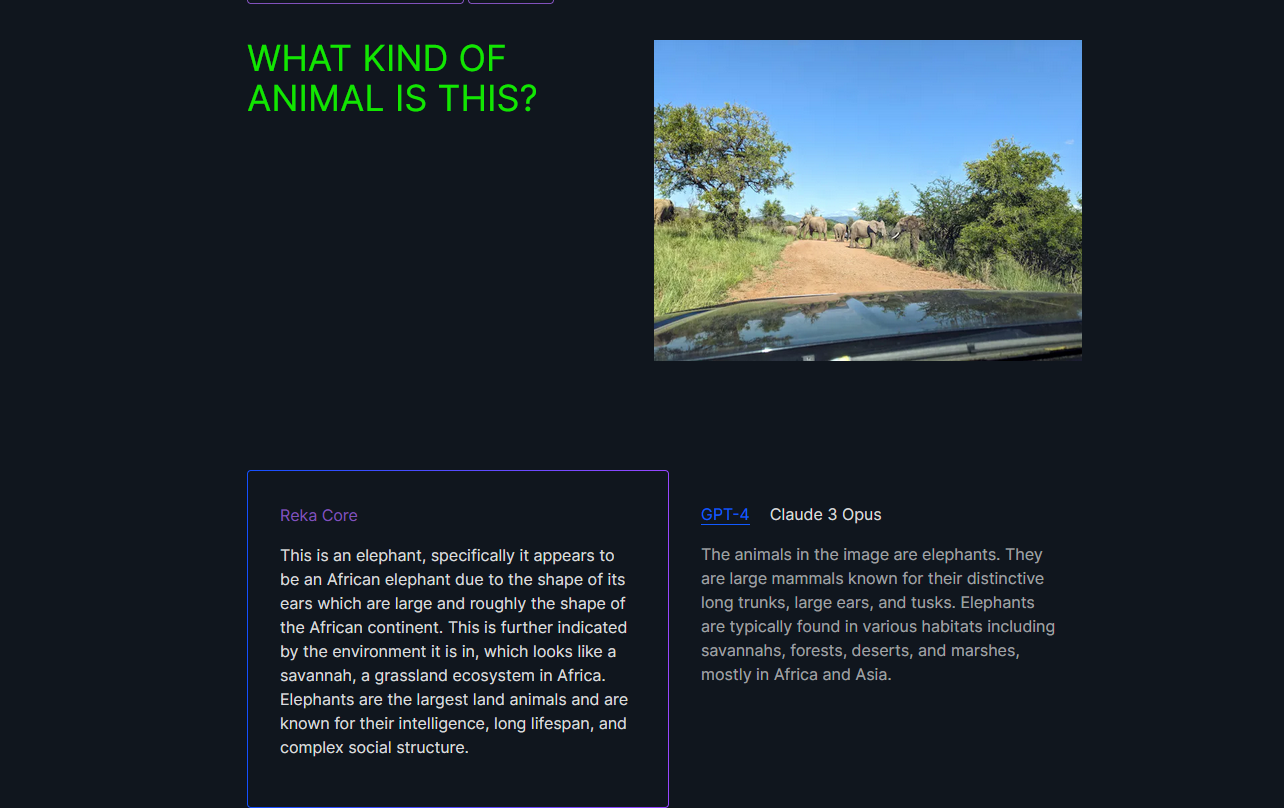
Reka Core is a competitive multimodal LLM accepting images, videos, and audio as input
 News
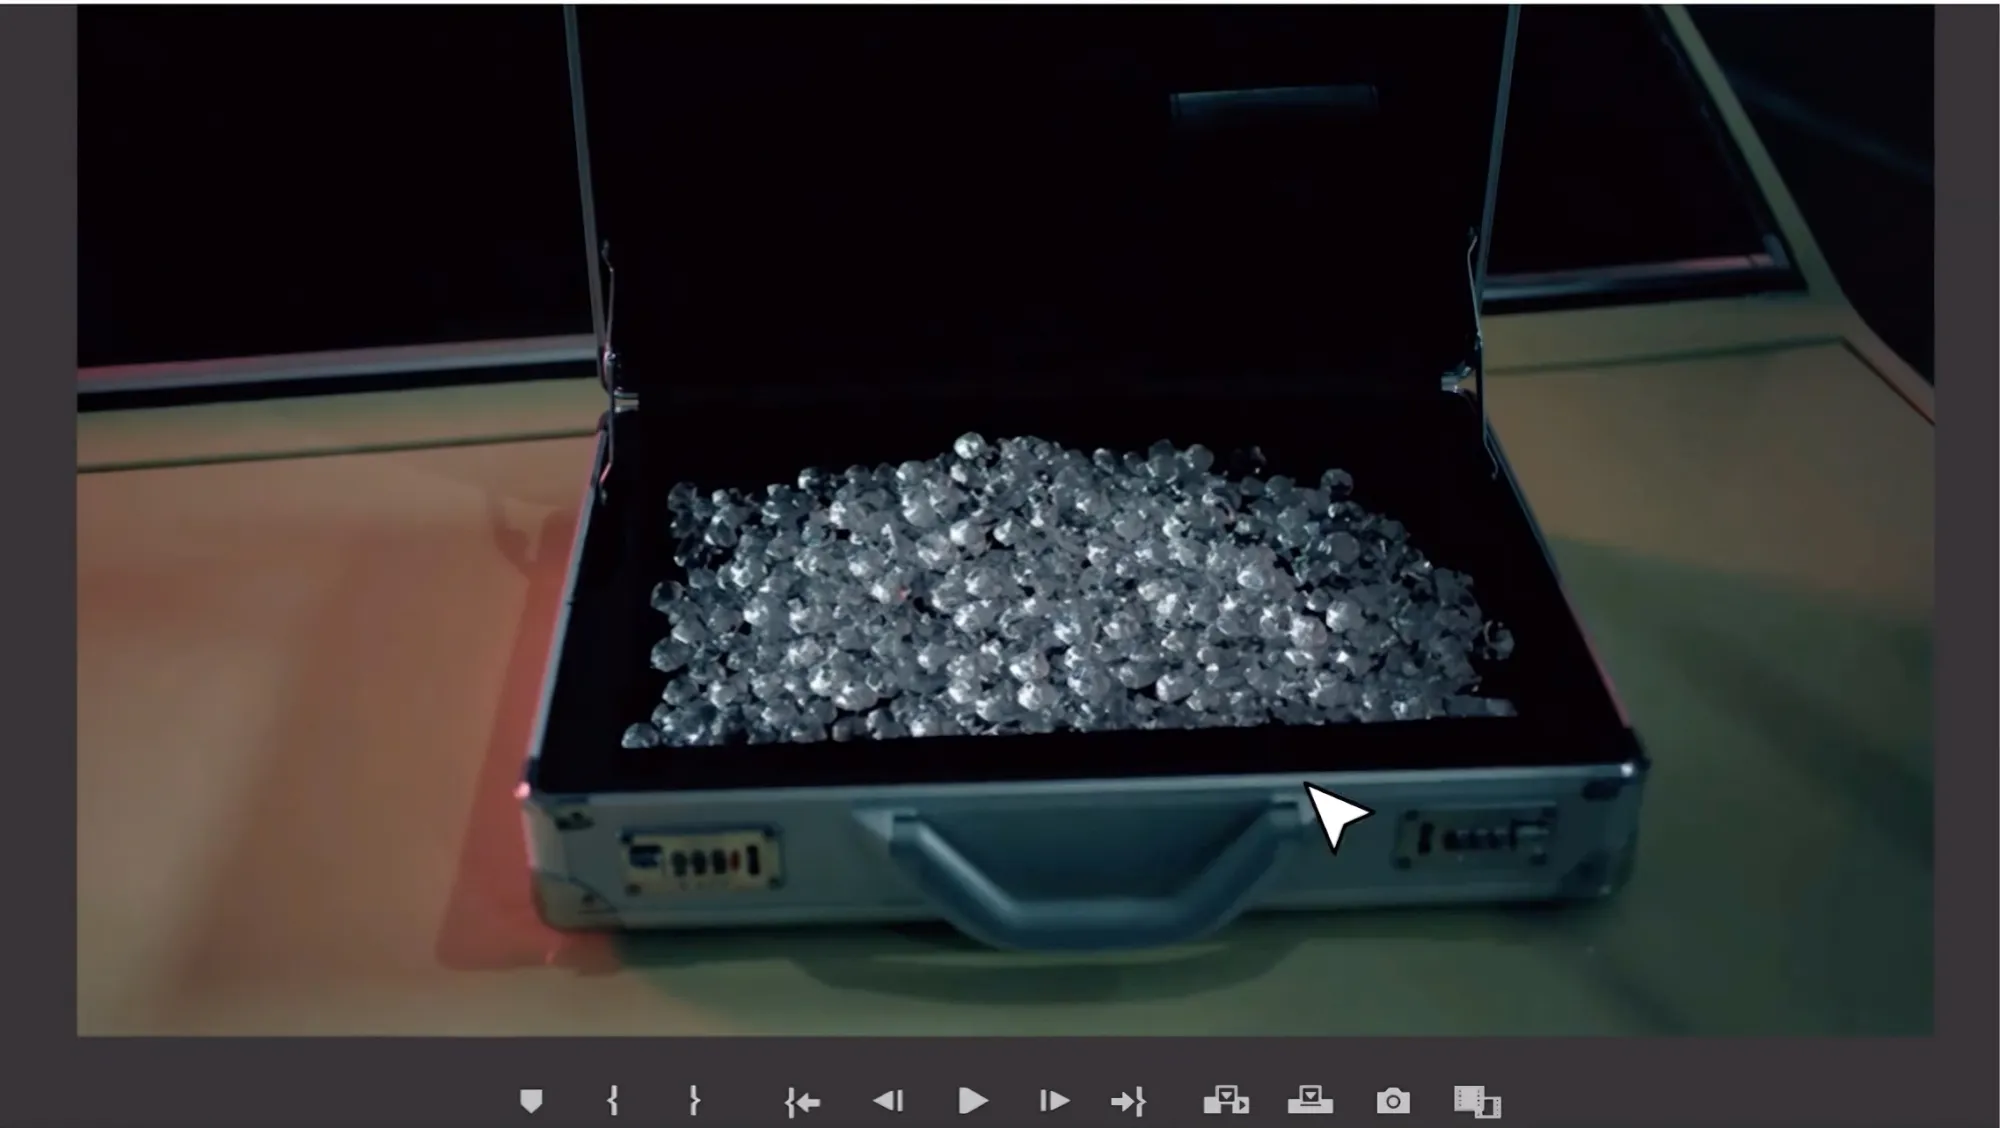
Adobe is planning to bring generative AI into Premiere Pro workloads
 News
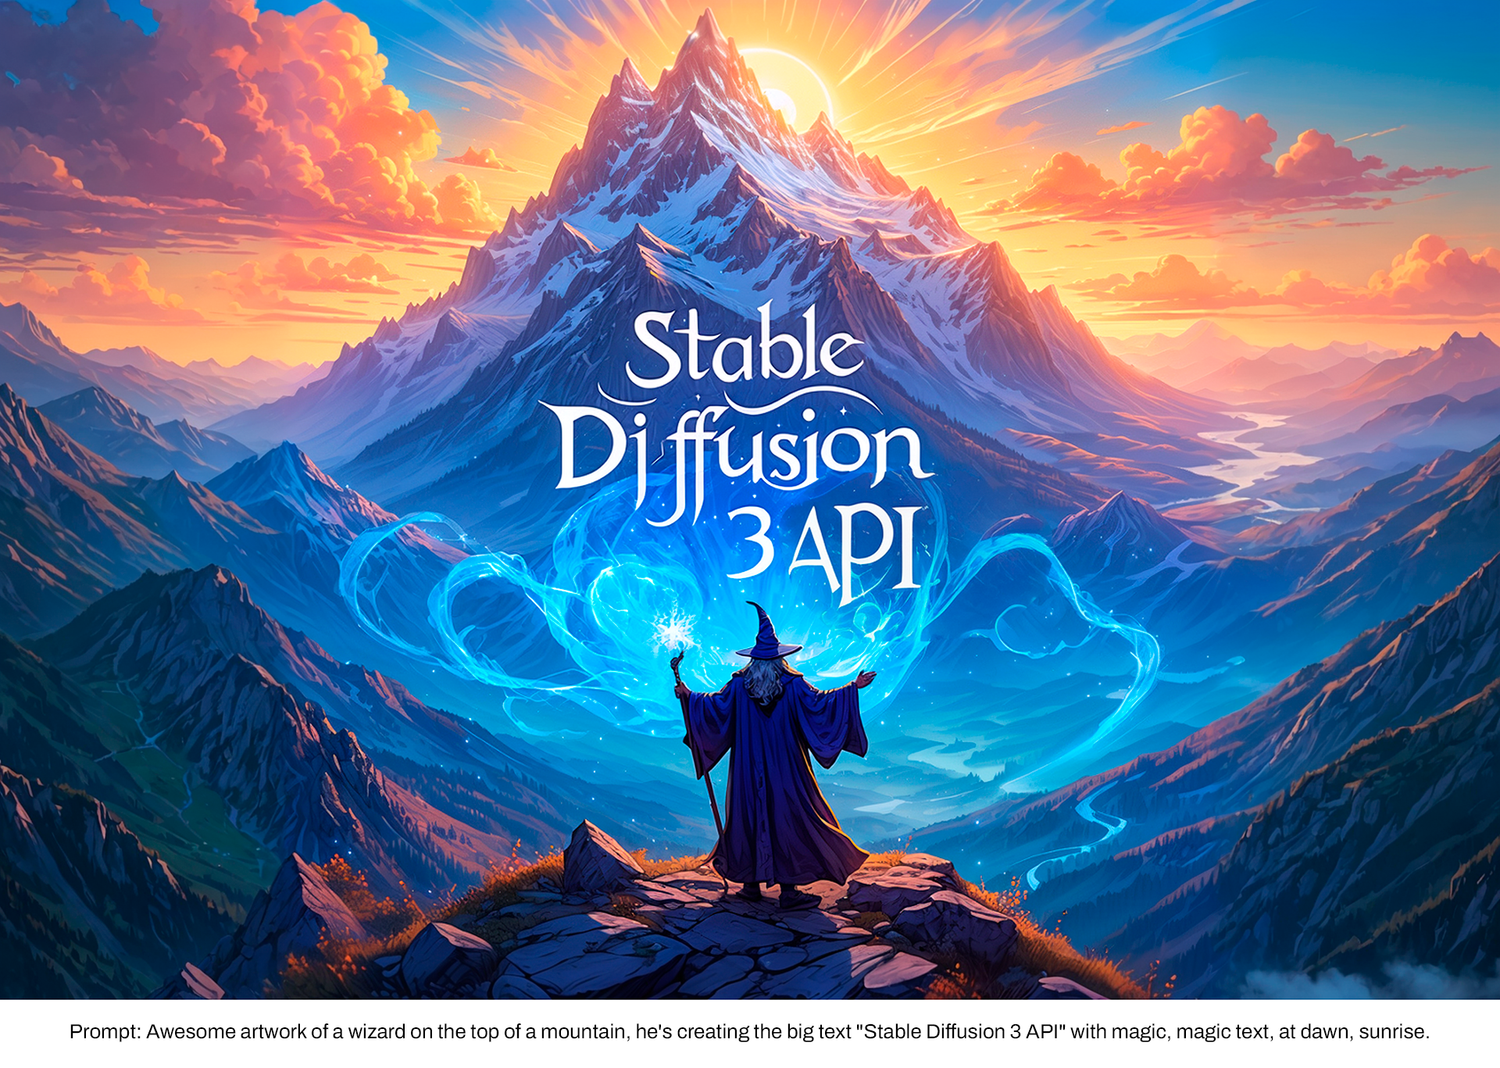
Stability AI partnered with Fireworks AI to launch the Stable Diffusion 3 API
 News
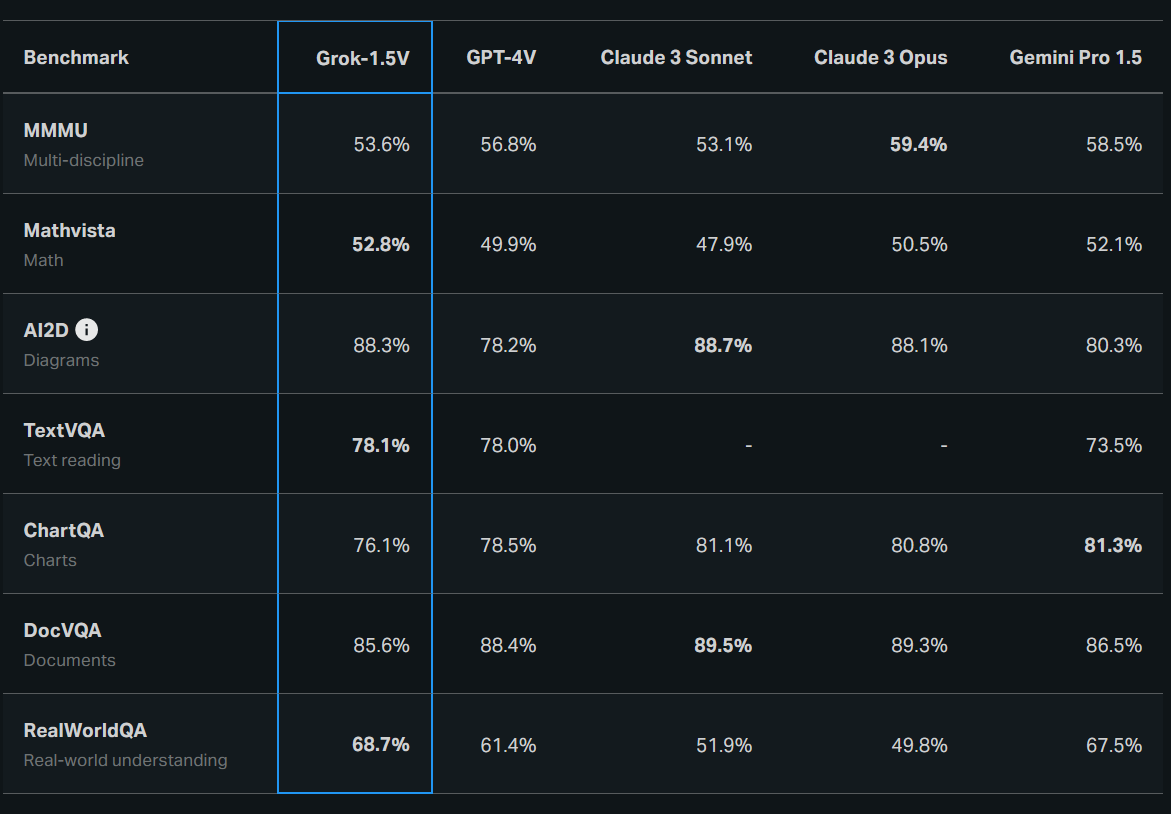
Grok just got vision: xAI announces Grok-1.5V preview
 News
Stable Diffusion 3 is now available via an early preview waitlist

