Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
DALL-E is now accessible via conversation for paying ChatGPT users
 News
Adept is open-sourcing its small multimodal model Fuyu-8B
 News
Generate visual media from text in Canva using its three AI apps
 News
Enterprise and Pro users can now show pictures and have voice conversations with ChatGPT
 News
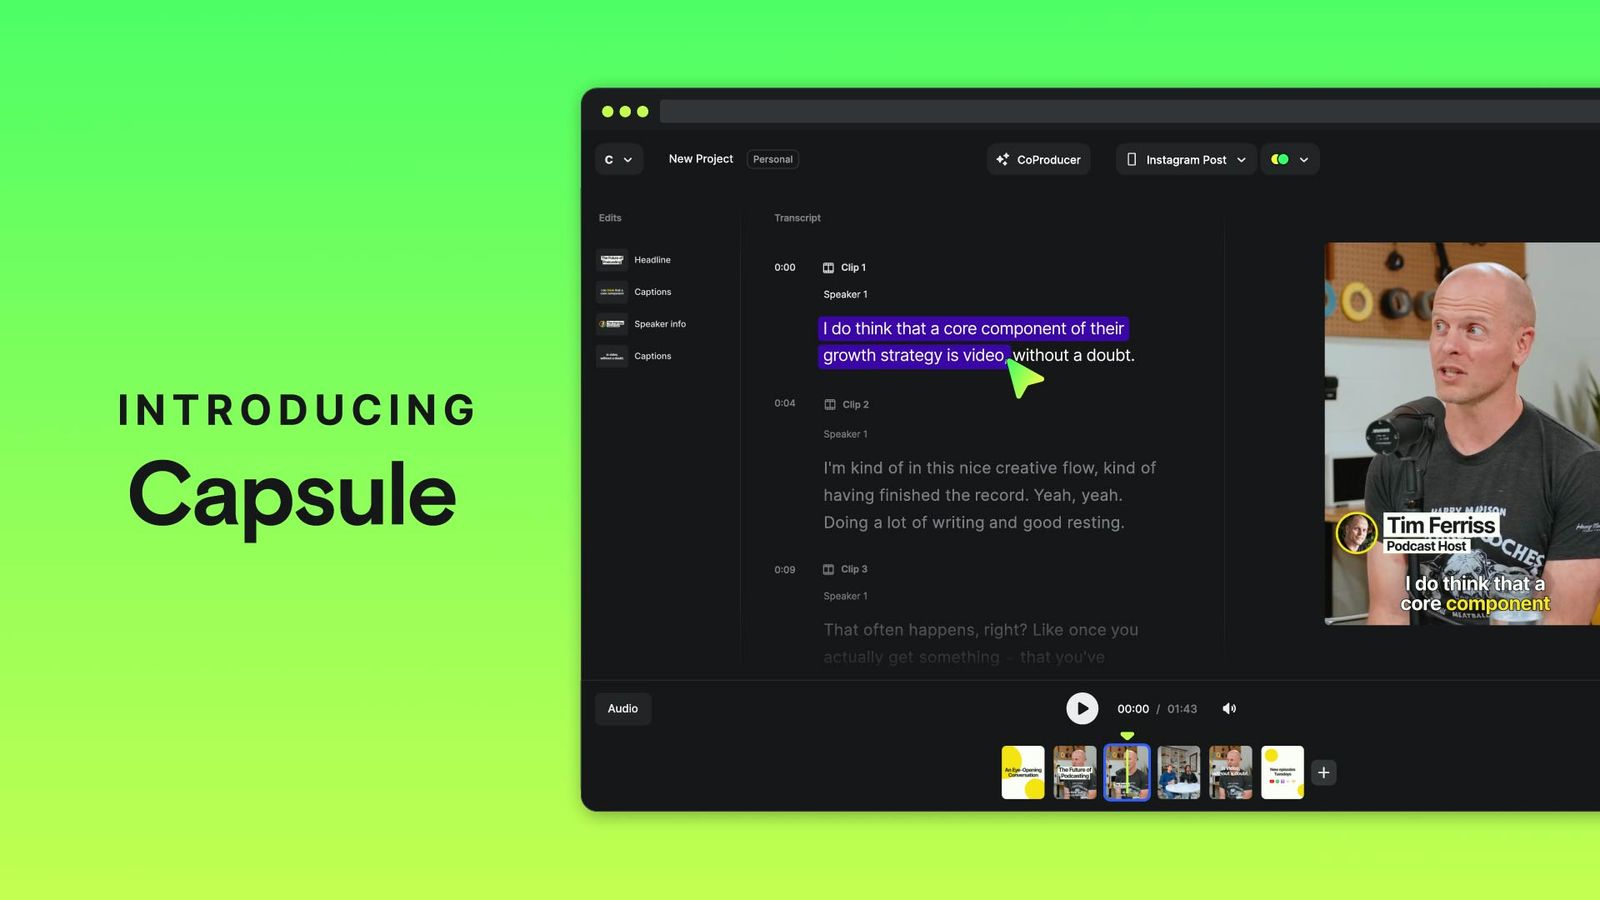
Capsule is making video editing less intimidating for professional teams everywhere
 News
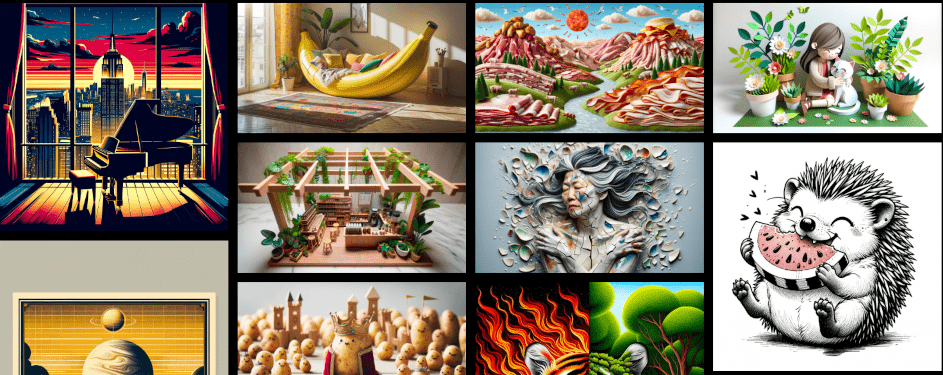
DALL-E 3 boasts increased accuracy and security, lets artists opt out of training
 News
Stability AI launched a first-of-its-kind audio and music generation AI product
 News
Segmind reveals a groundbreaking text-to-image open-source model
- News
Yasa is Reka's innovative multimodal enterprise-grade Al-powered assistant
 News
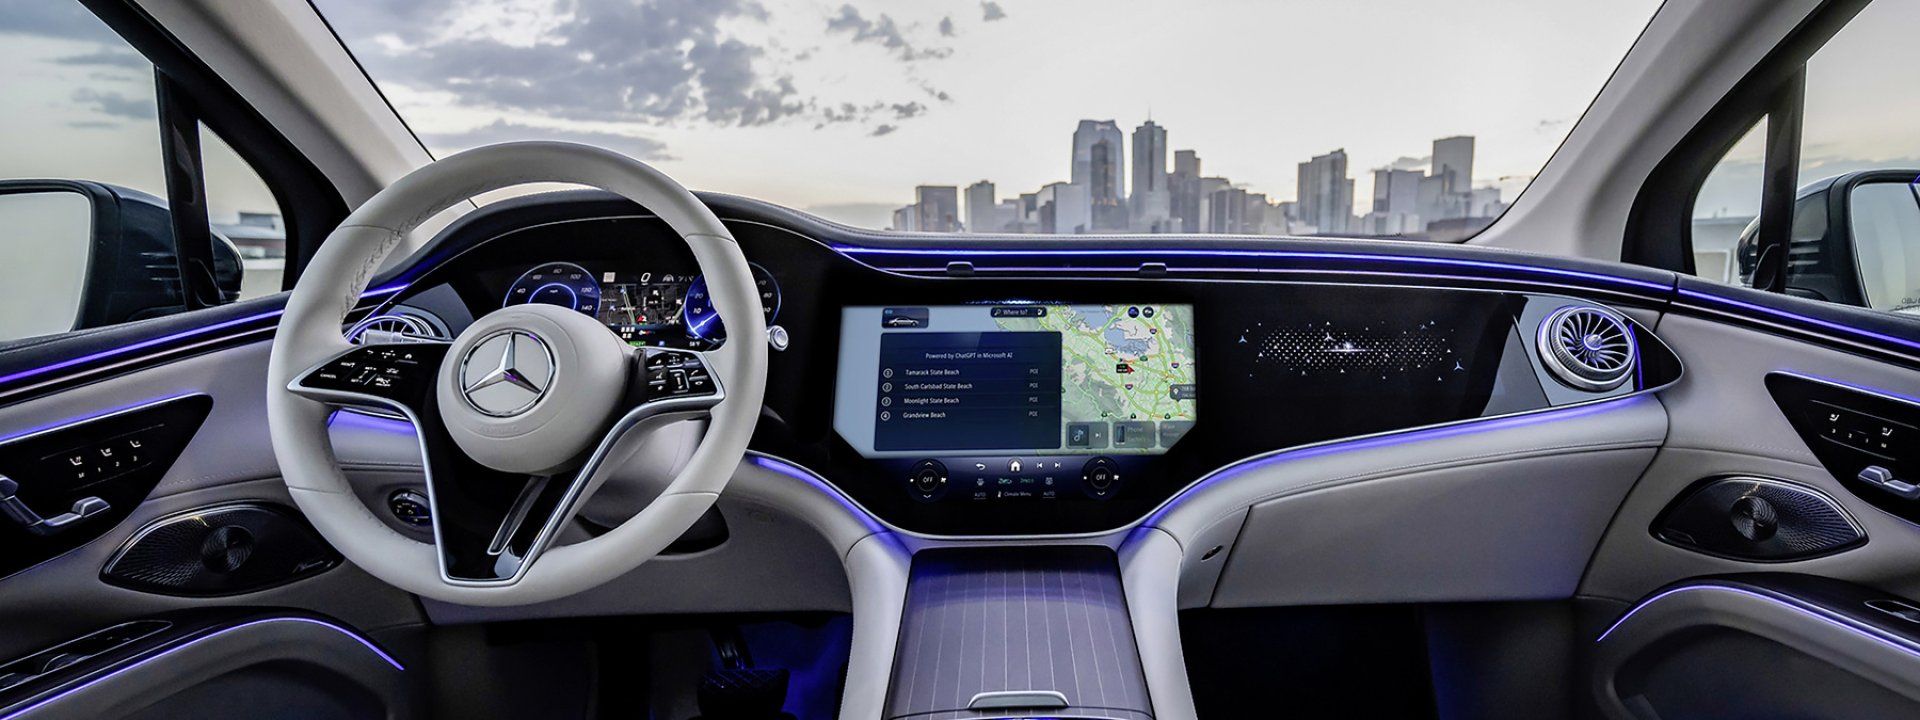
Mercedes-Benz takes in-car voice control to a new level with ChatGPT
 News
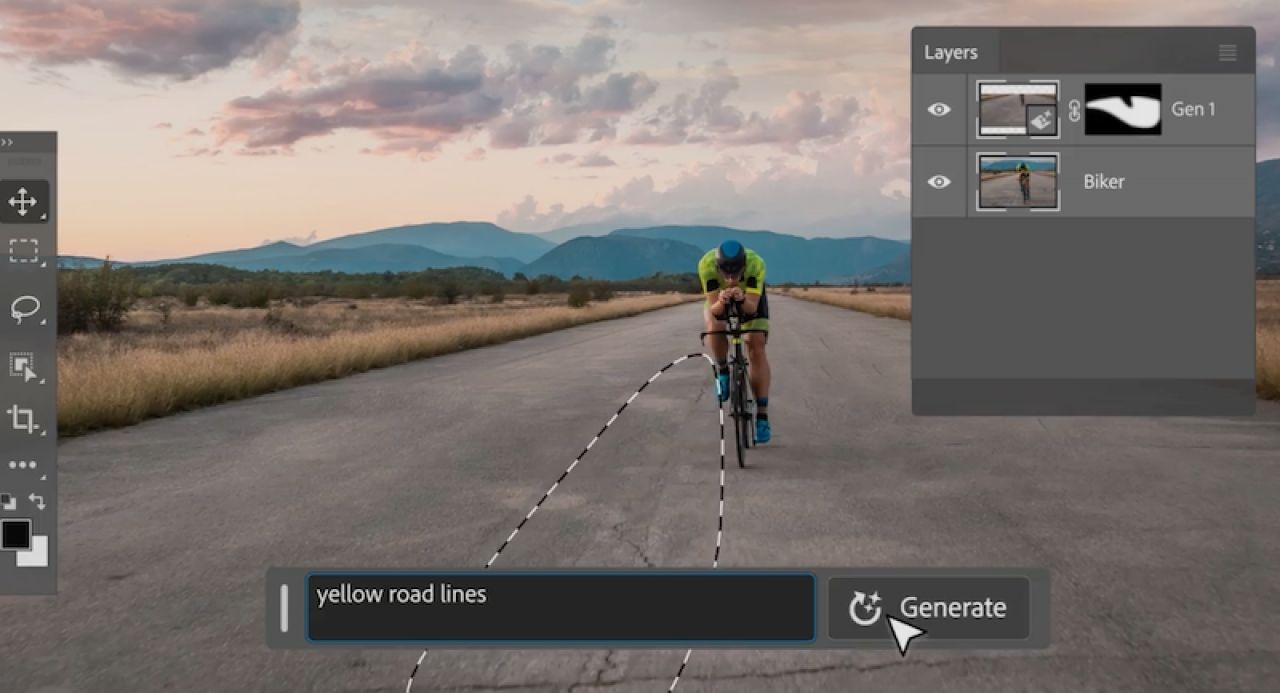
AI Boosts Photoshop Creativity
 Papers
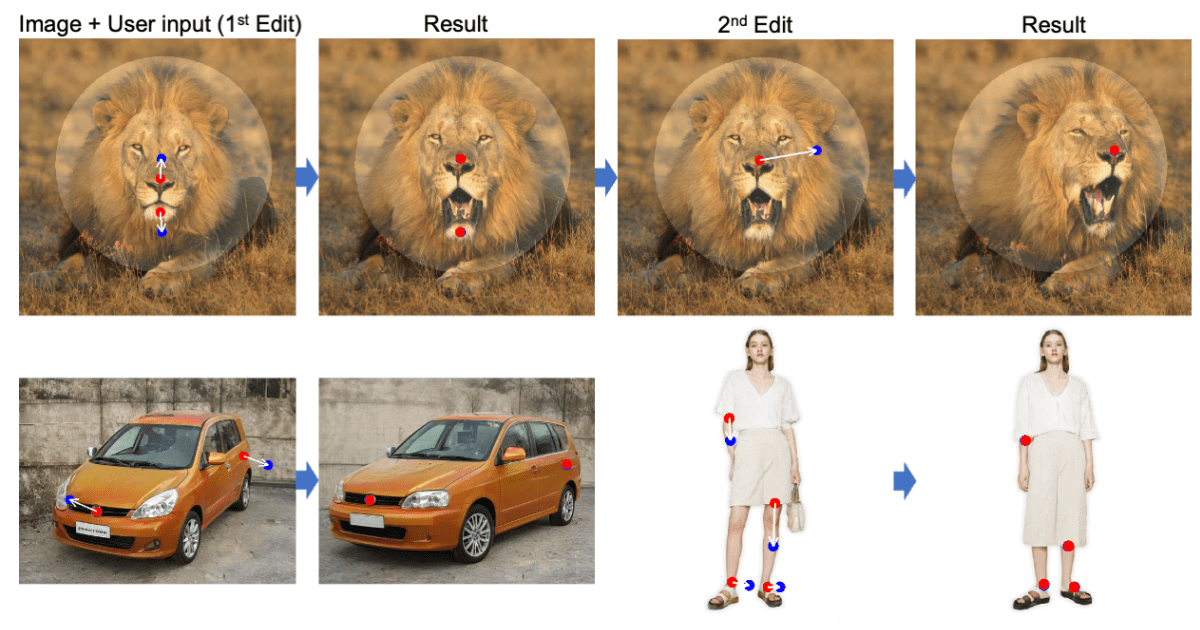
Drag Your GAN: Interactive Point-based Manipulation on the Generative Image Manifold