Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
OpenAI becomes the center of attention with the Sora early announcement
 Papers
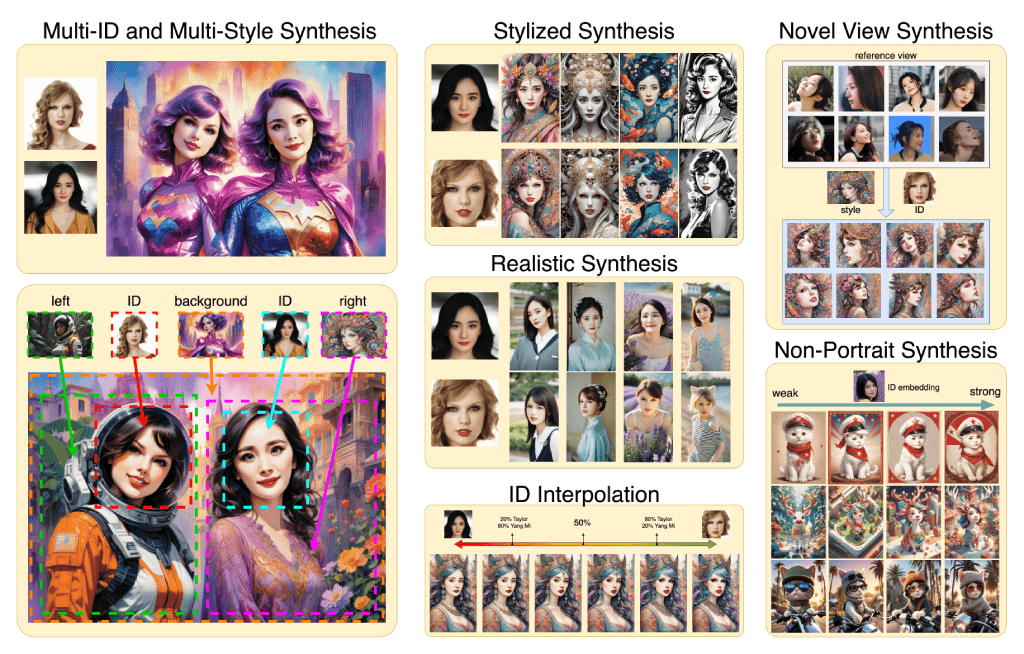
InstantID : Zero-shot Identity-Preserving Generation in Seconds
 Article
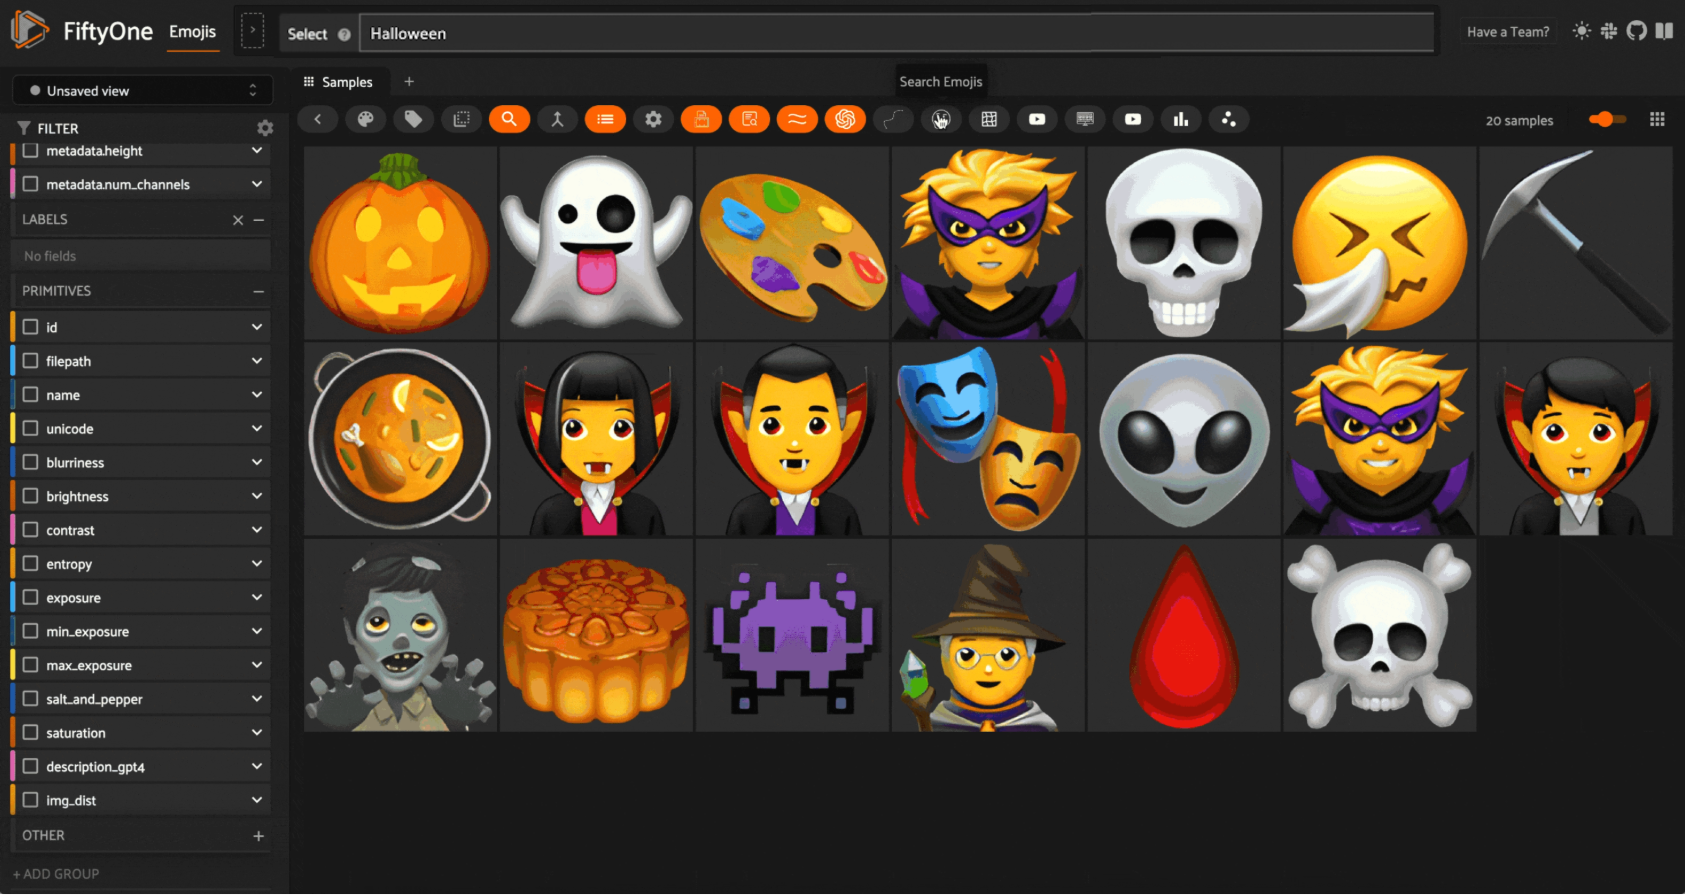
How to Build a Semantic Search Engine for Emojis
 News
The Stability AI Developer Platform API now includes Stable Video Diffusion
 News
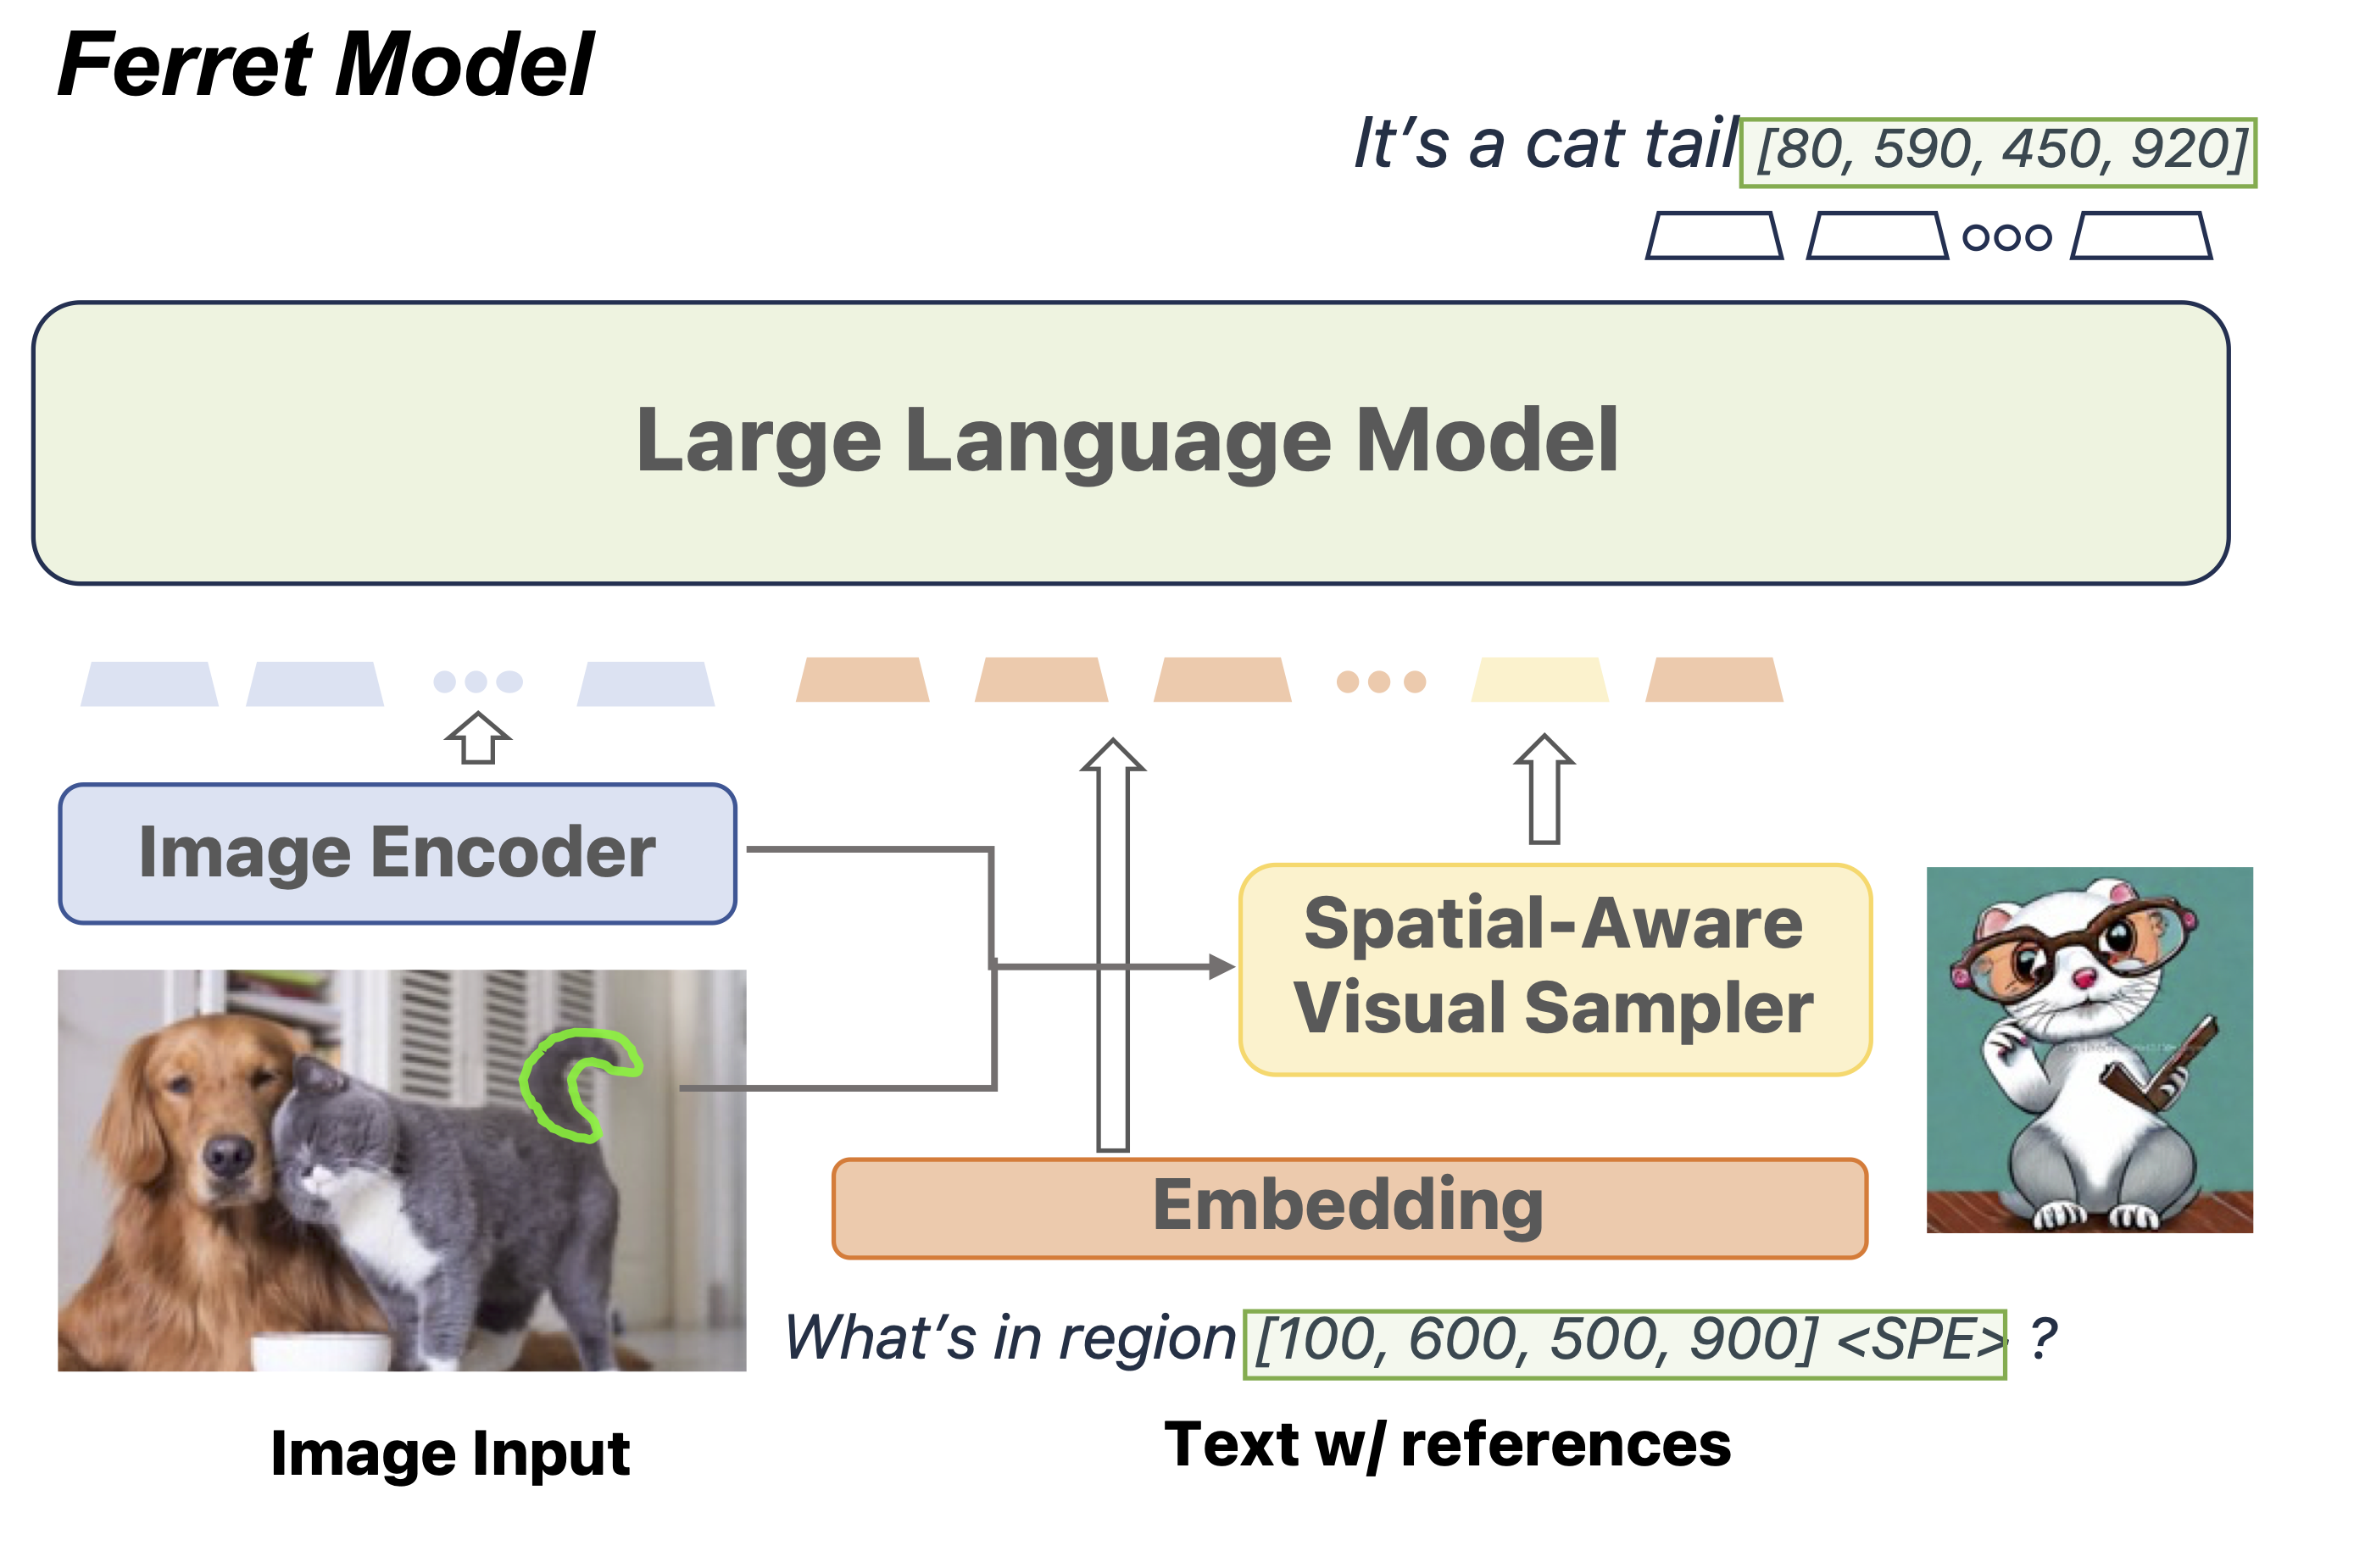
Apple and Columbia University researchers furtively released a multimodal LLM named 'Ferret'
 News
Microsoft partners with Suno to bring everyone's music ideas to life
 News
Ukrainian start-up Respeecher secures $1M to develop AI voice cloning responsibly
 News
Gemini: Google's largest and most proficient model yet is also natively multimodal
 News
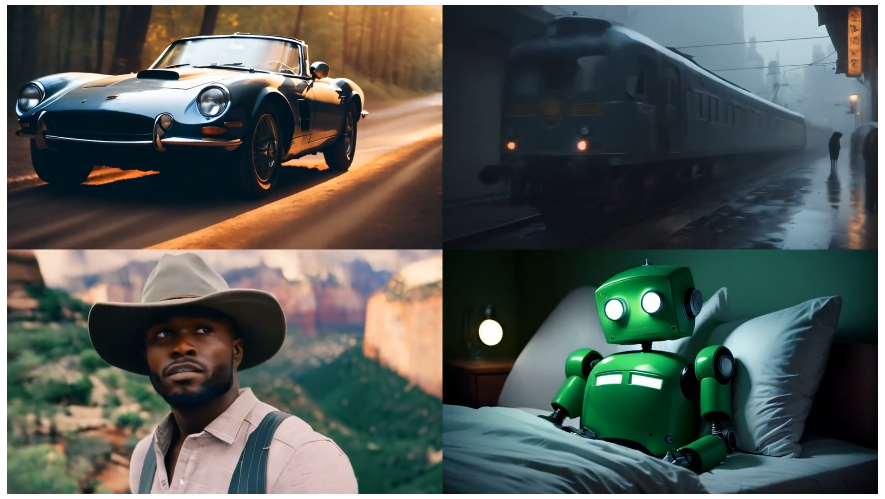
Stability AI releases Stable Video Diffusion, its open-source foundational model for video generation
 News
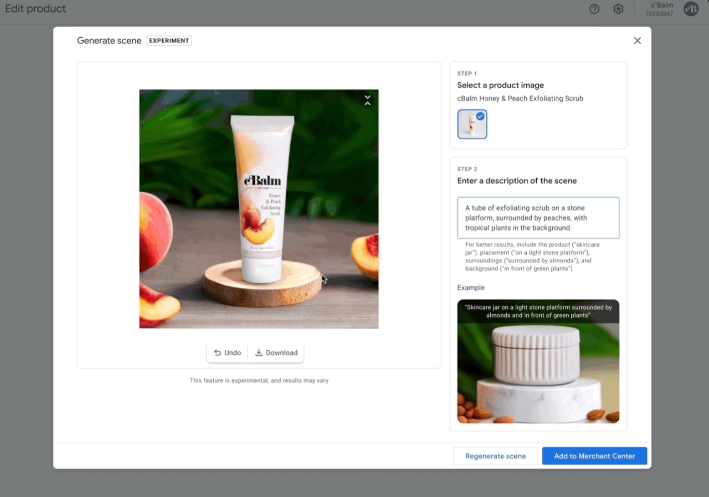
AI-generated imagery may be the next big thing in digital advertisement
 News
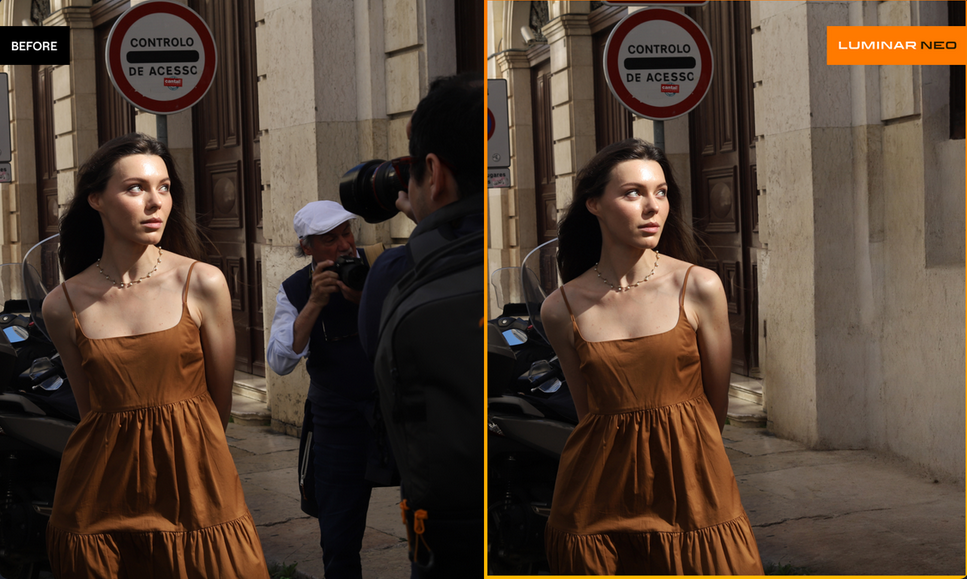
Skylum launches generative AI tools within the award-winning photo editor Luminar Neo
 News
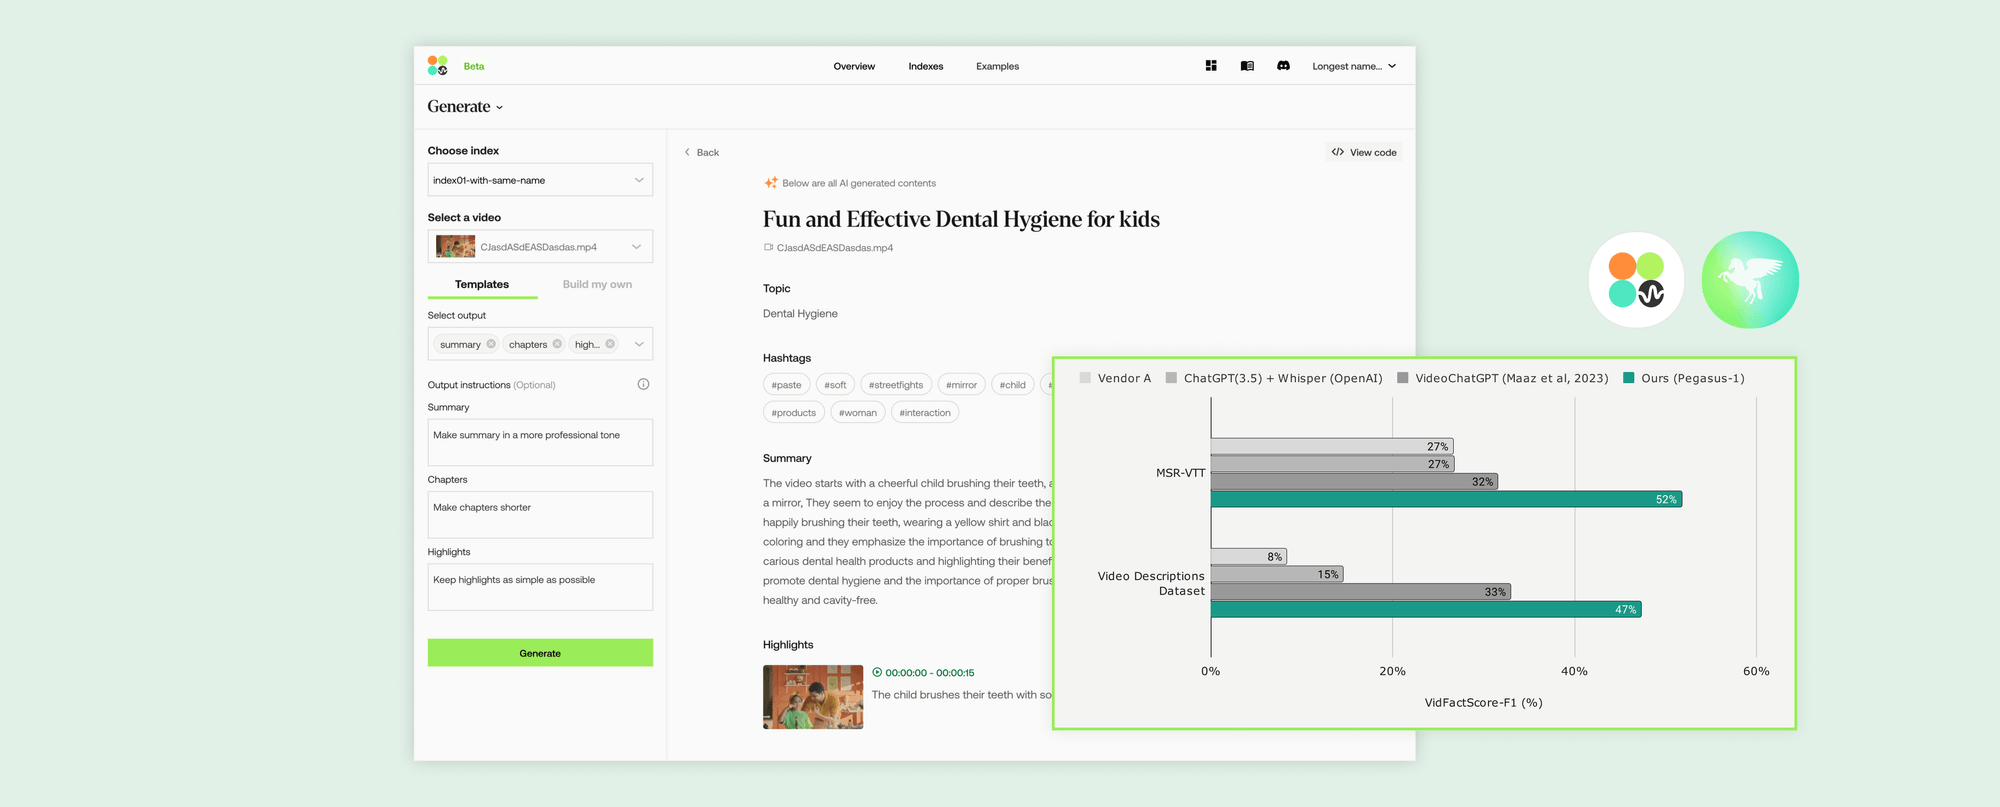
Twelve Labs announces Video-to-Text API and Pegasus-1 model