Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
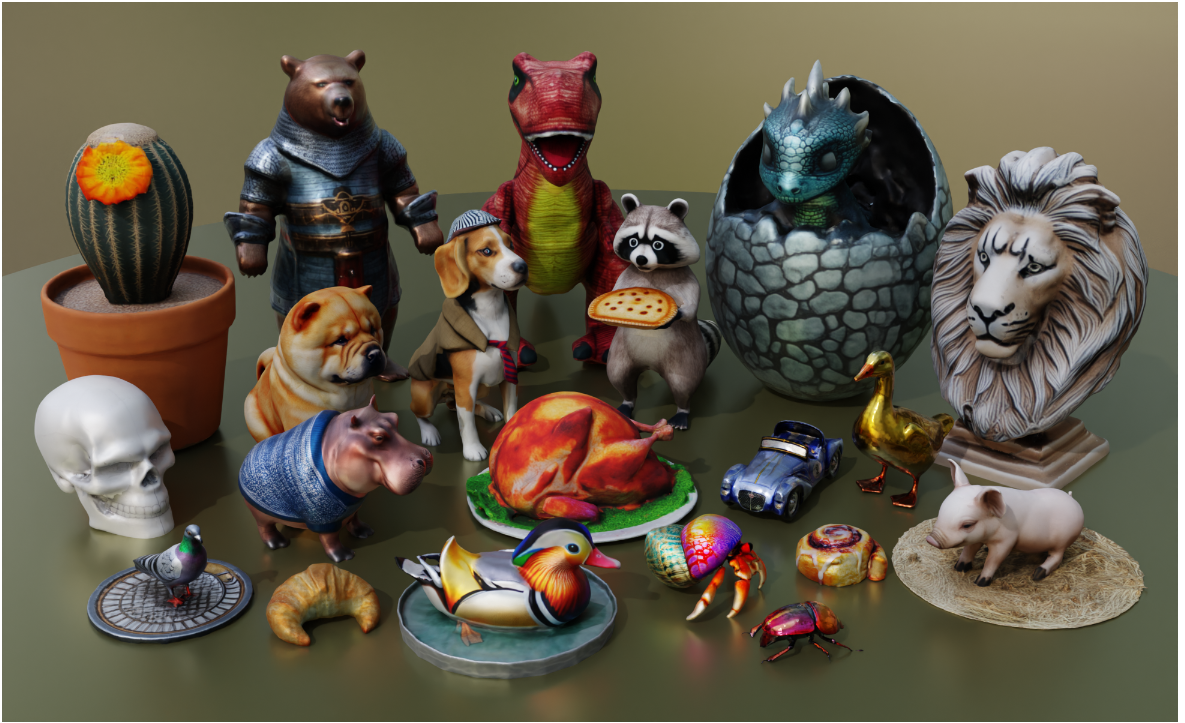
Meta showcased its research into 3D asset generation
- News
OpenAI has changed the release timeline for the revamped ChatGPT Voice Mode
 News
Synthesia platform upgrade brings full-body avatars, new AI Video Assistant features, and more
 News
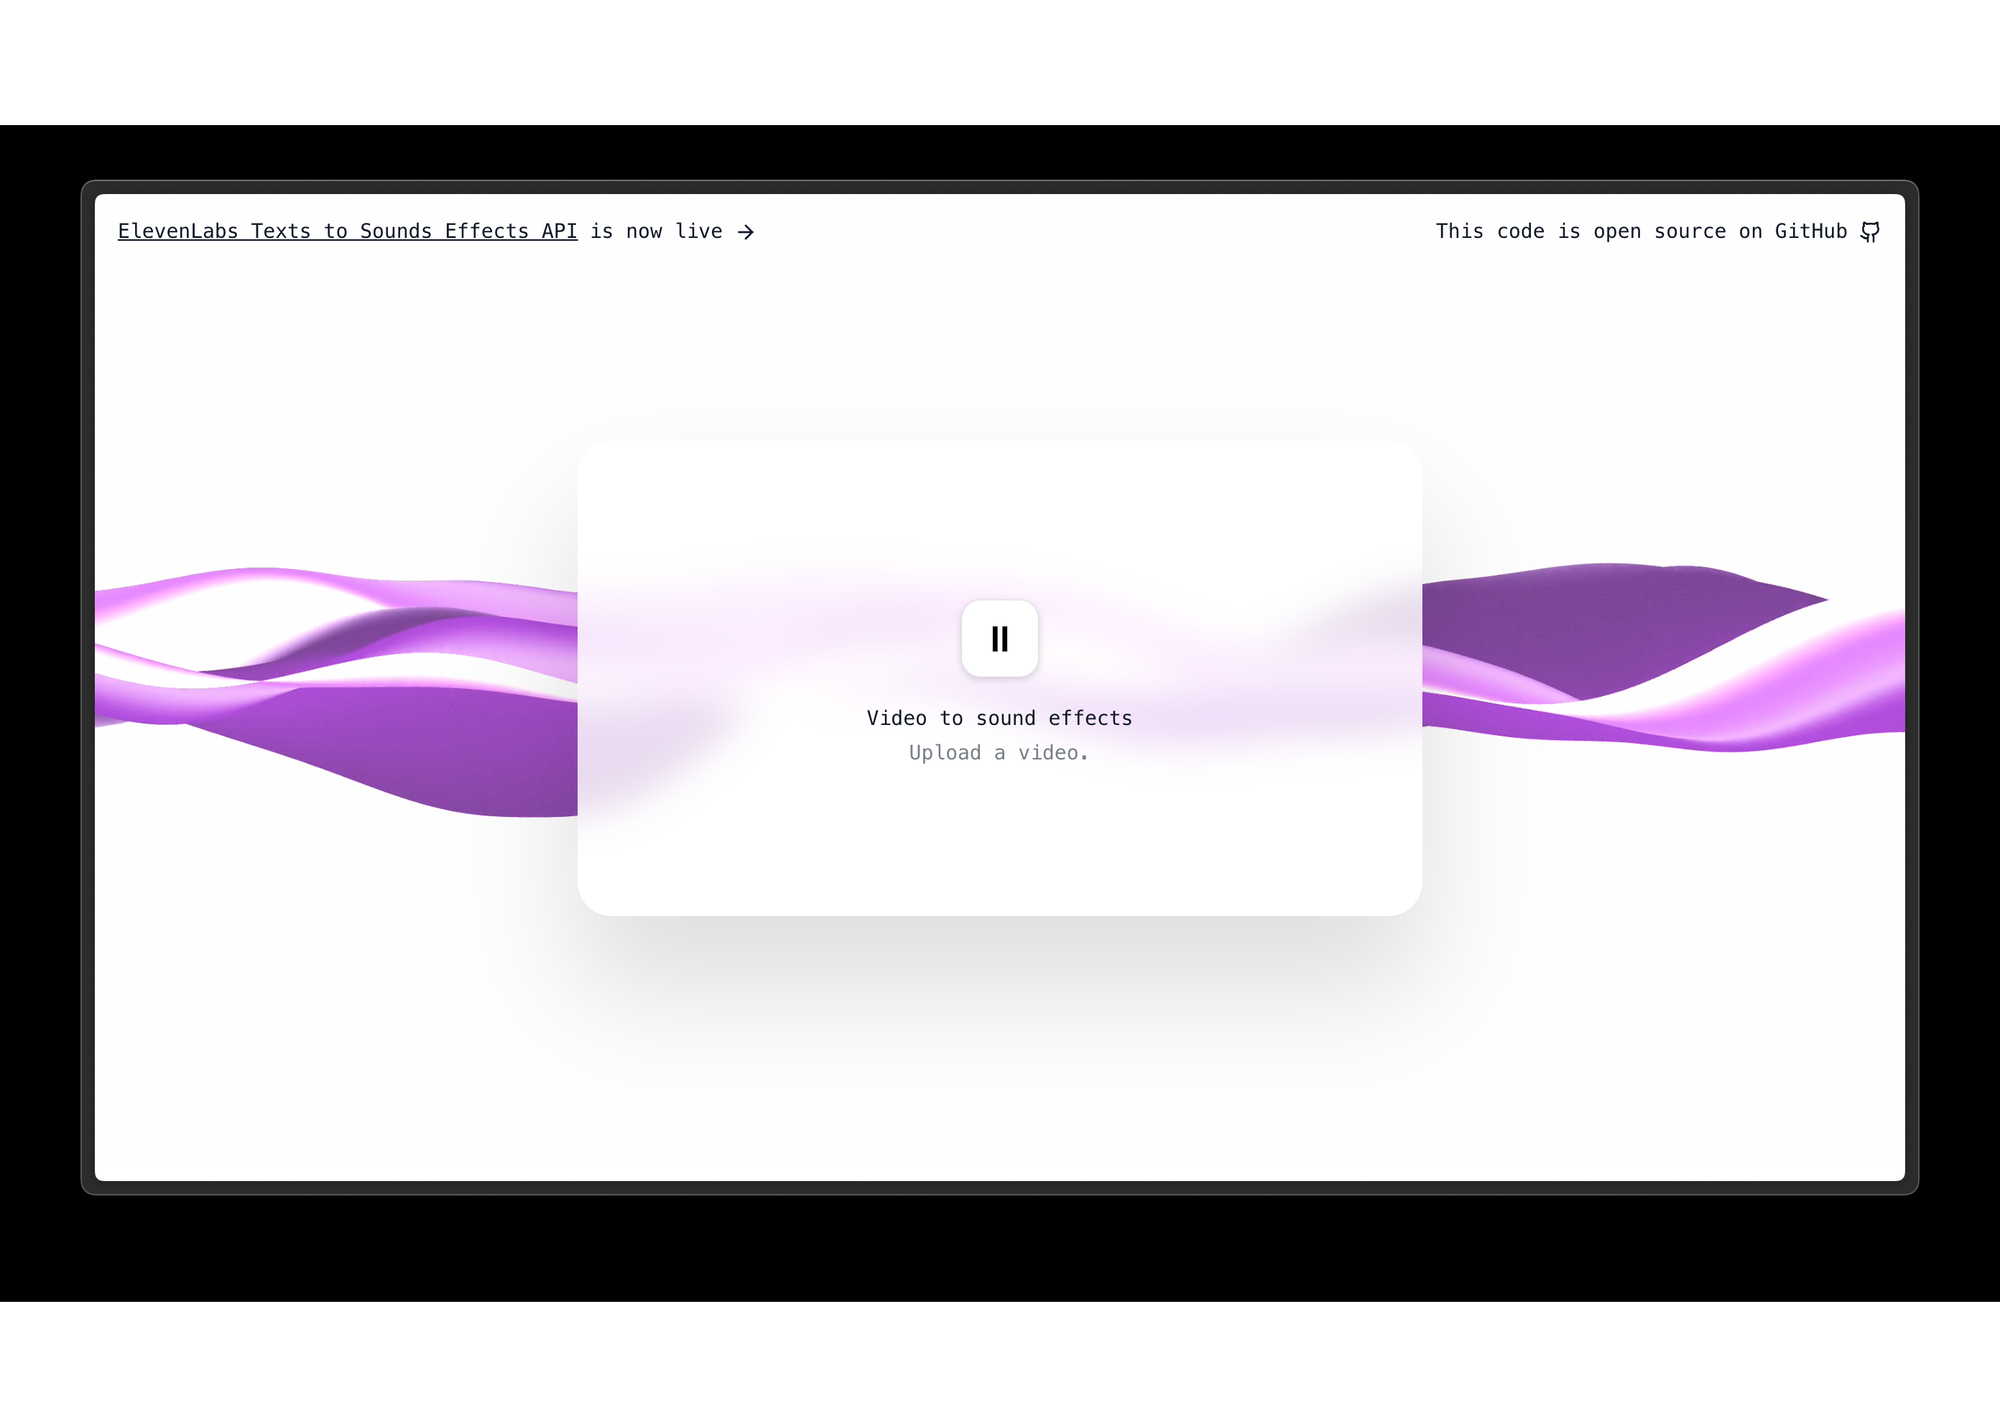
Elevenlabs releases an open-source demo to add sound effects for videos and announces new partnerships
 News
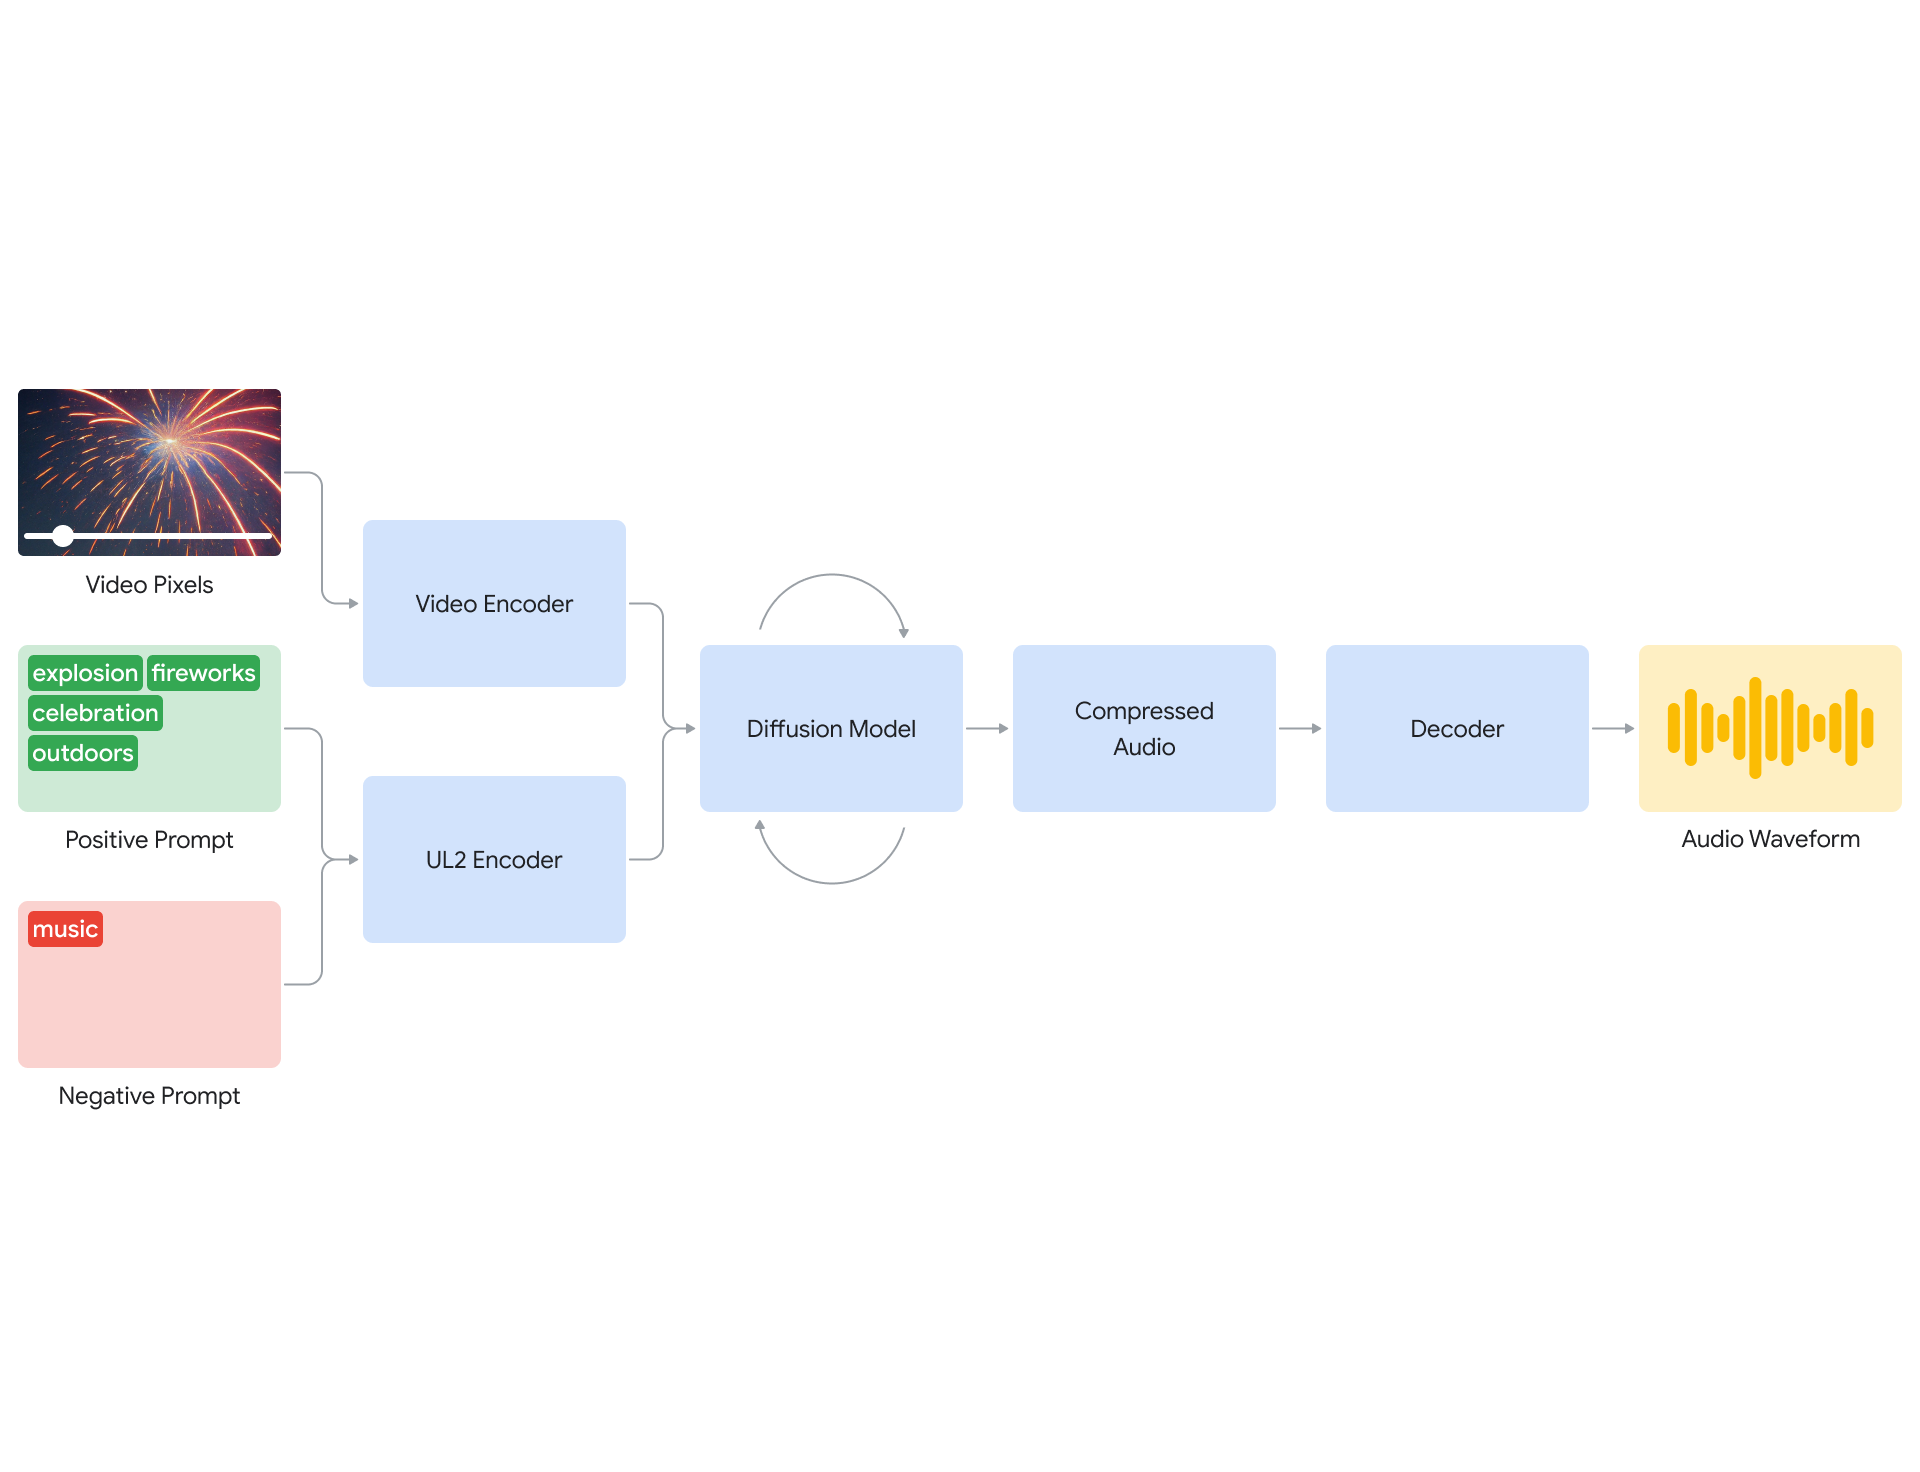
Google DeepMind previewed some advances of its video-to-audio research
 News
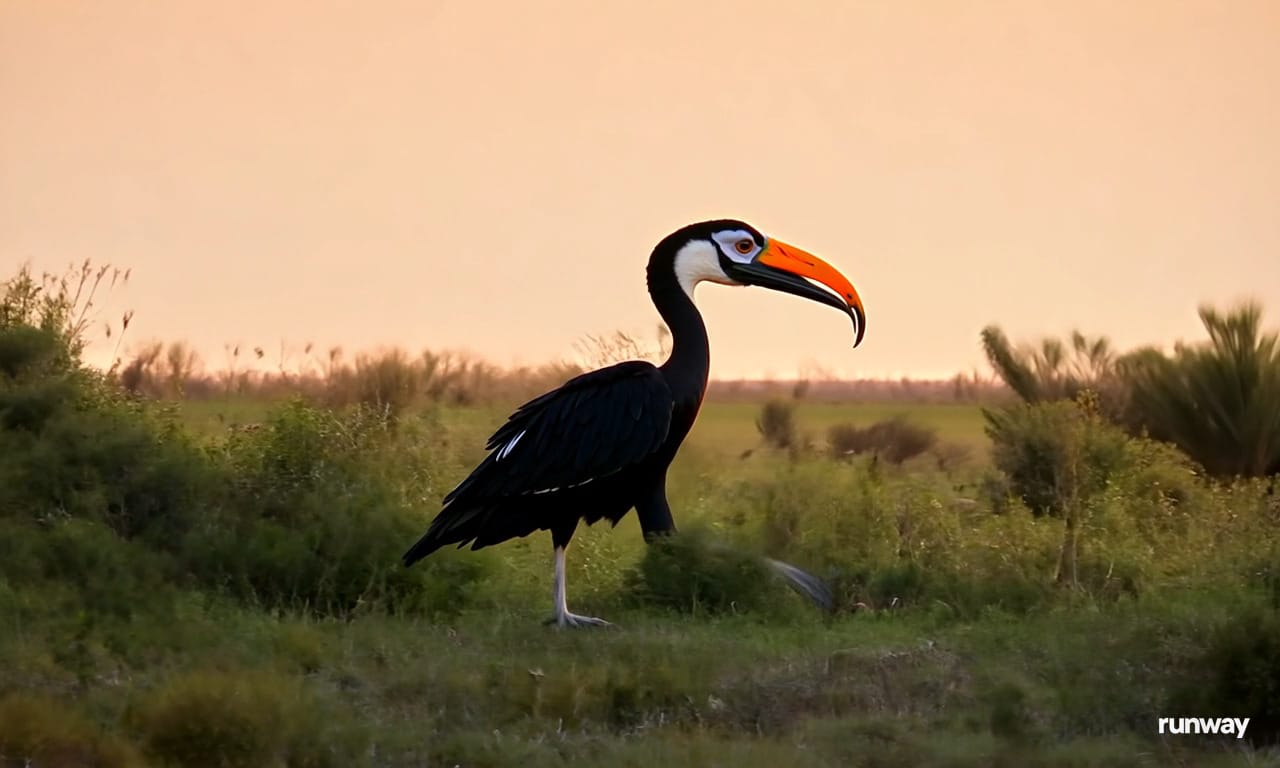
Runway catches up in the video generation race with Gen-3 Alpha
 News
TikTok launched Symphony Avatars, AI Dubbing, and the Symphony Collective
 News
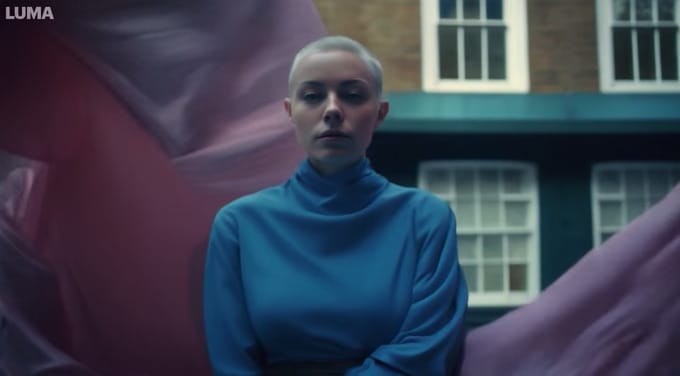
Luma AI launches Dream Machine as the video generation tools race intensifies
 News
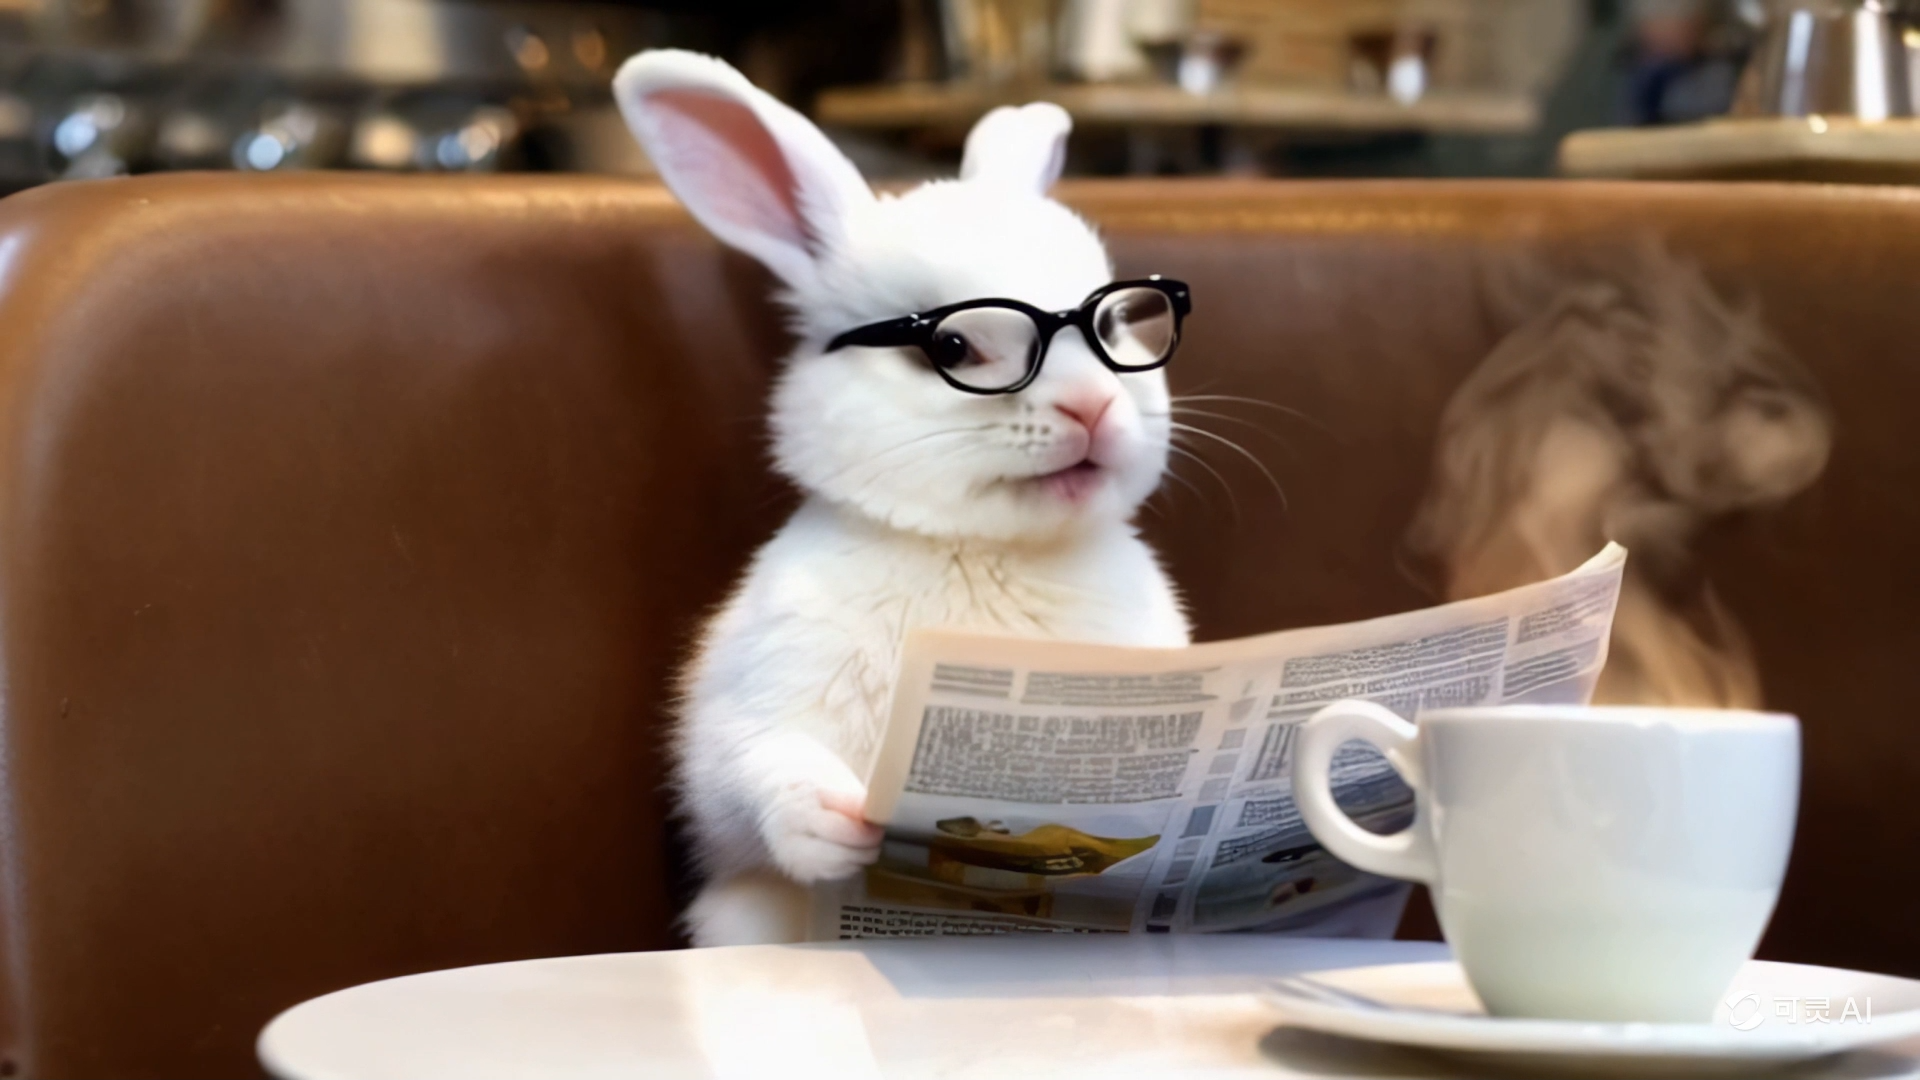
Sora competitor Kling caused the internet to go into a frenzy
 News
Stability AI calls Stable Diffusion 3 Medium its 'most advanced text-to-image open model'
 News
Stability AI unveiled the sound generator Stable Audio Open
 News
Leading voice cloning tools are alarmingly easy to manipulate to produce election disinformation
