Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 Papers
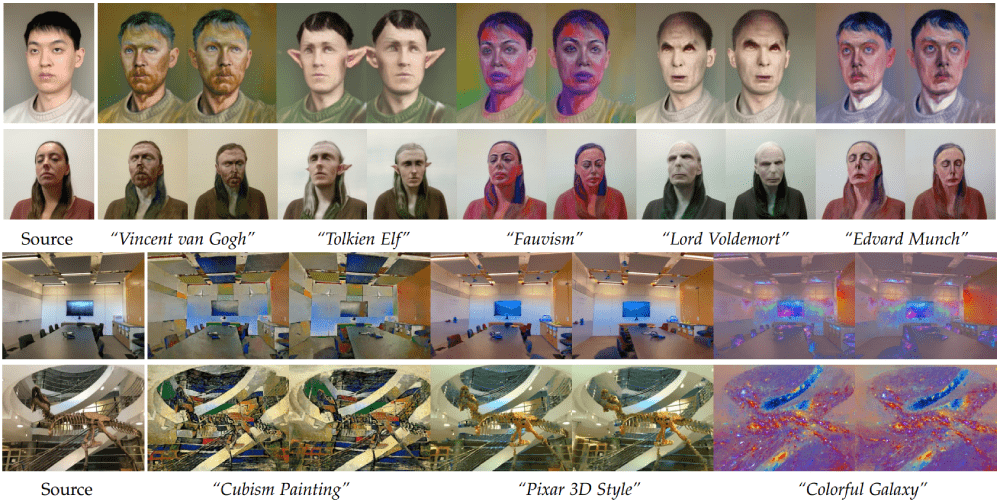
NeRF-Art: Text-Driven Neural Radiance Fields Stylization
 Papers
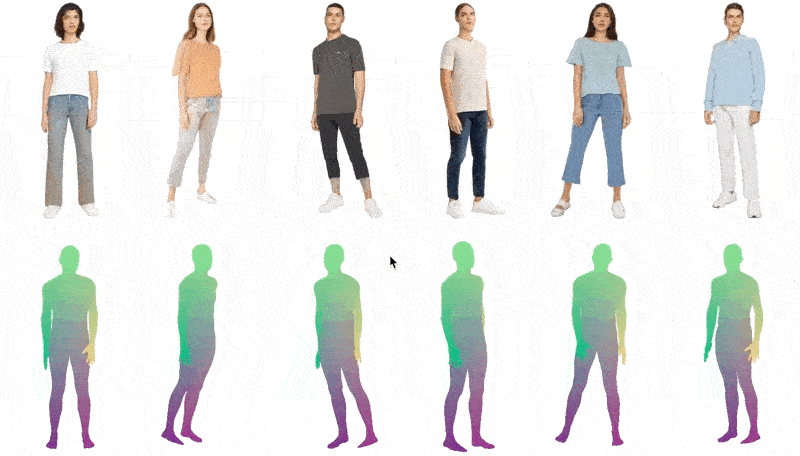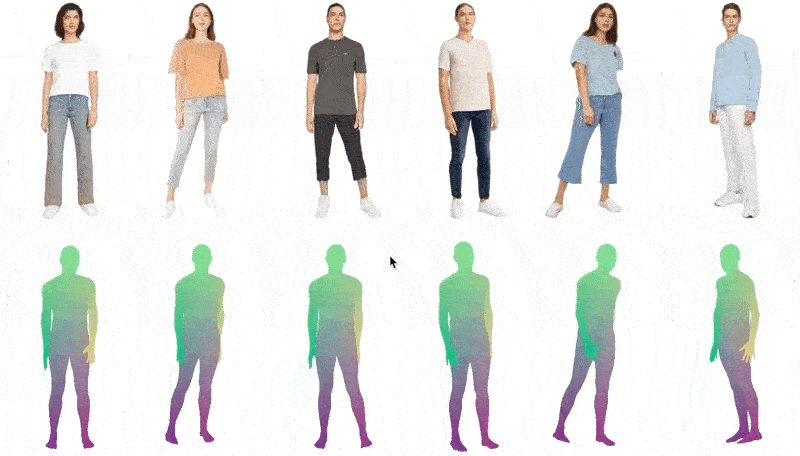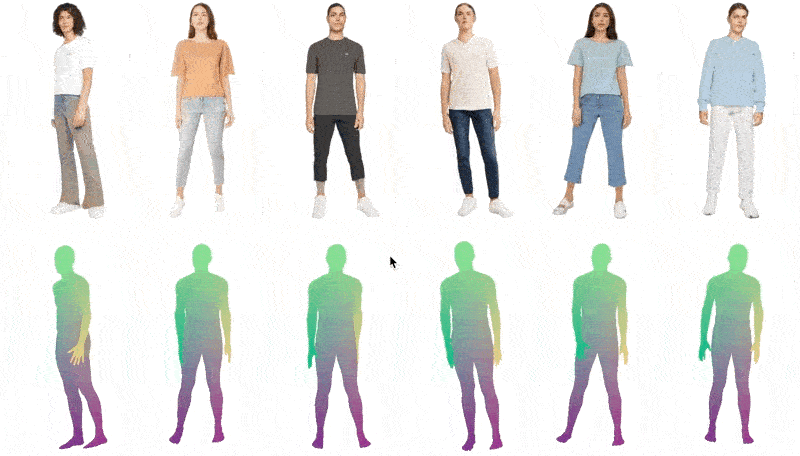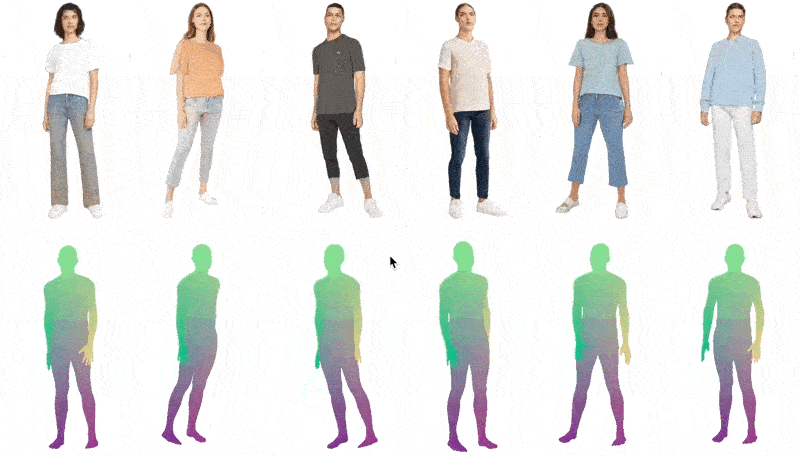
3DHumanGAN: Towards Photo-realistic 3D-Aware Human Image Generation
 Papers
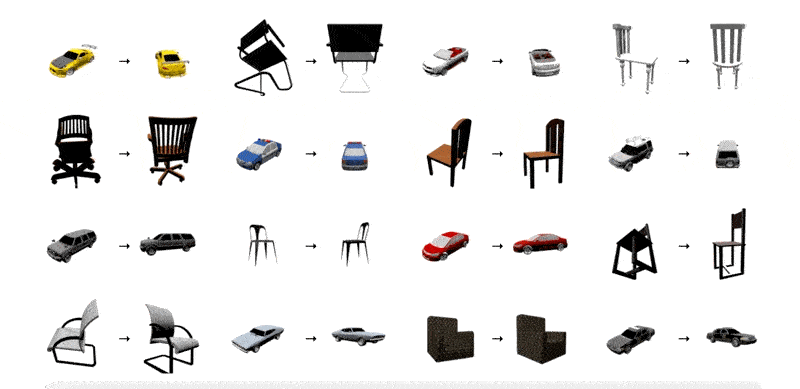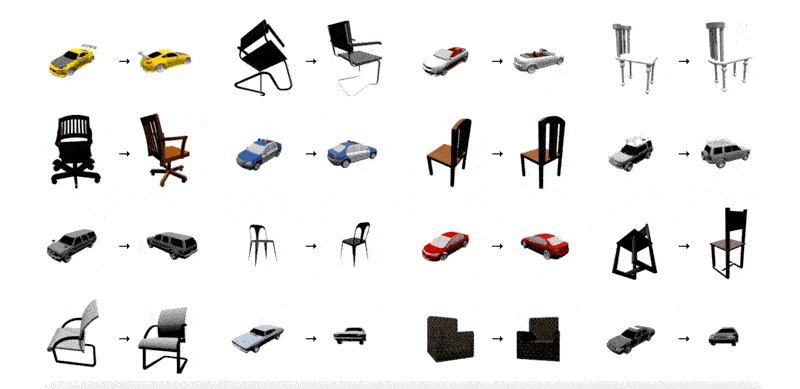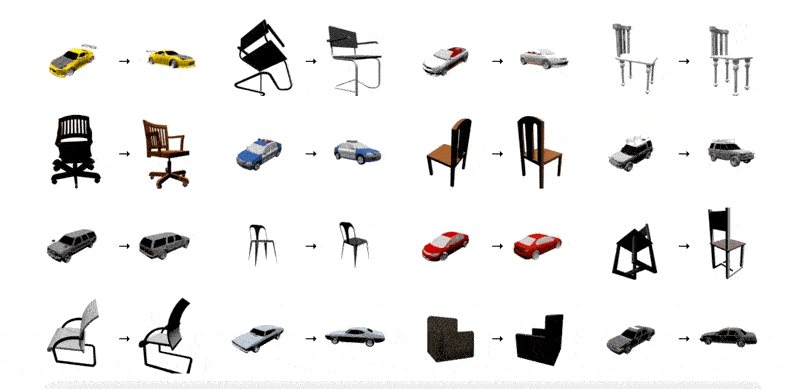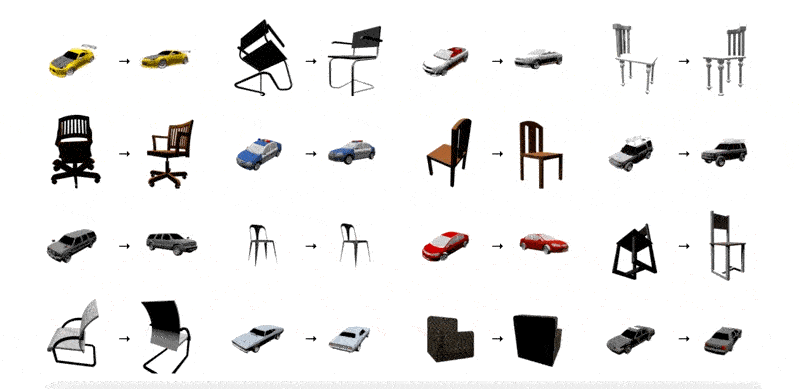
Novel View Synthesis with Diffusion Models
 Papers
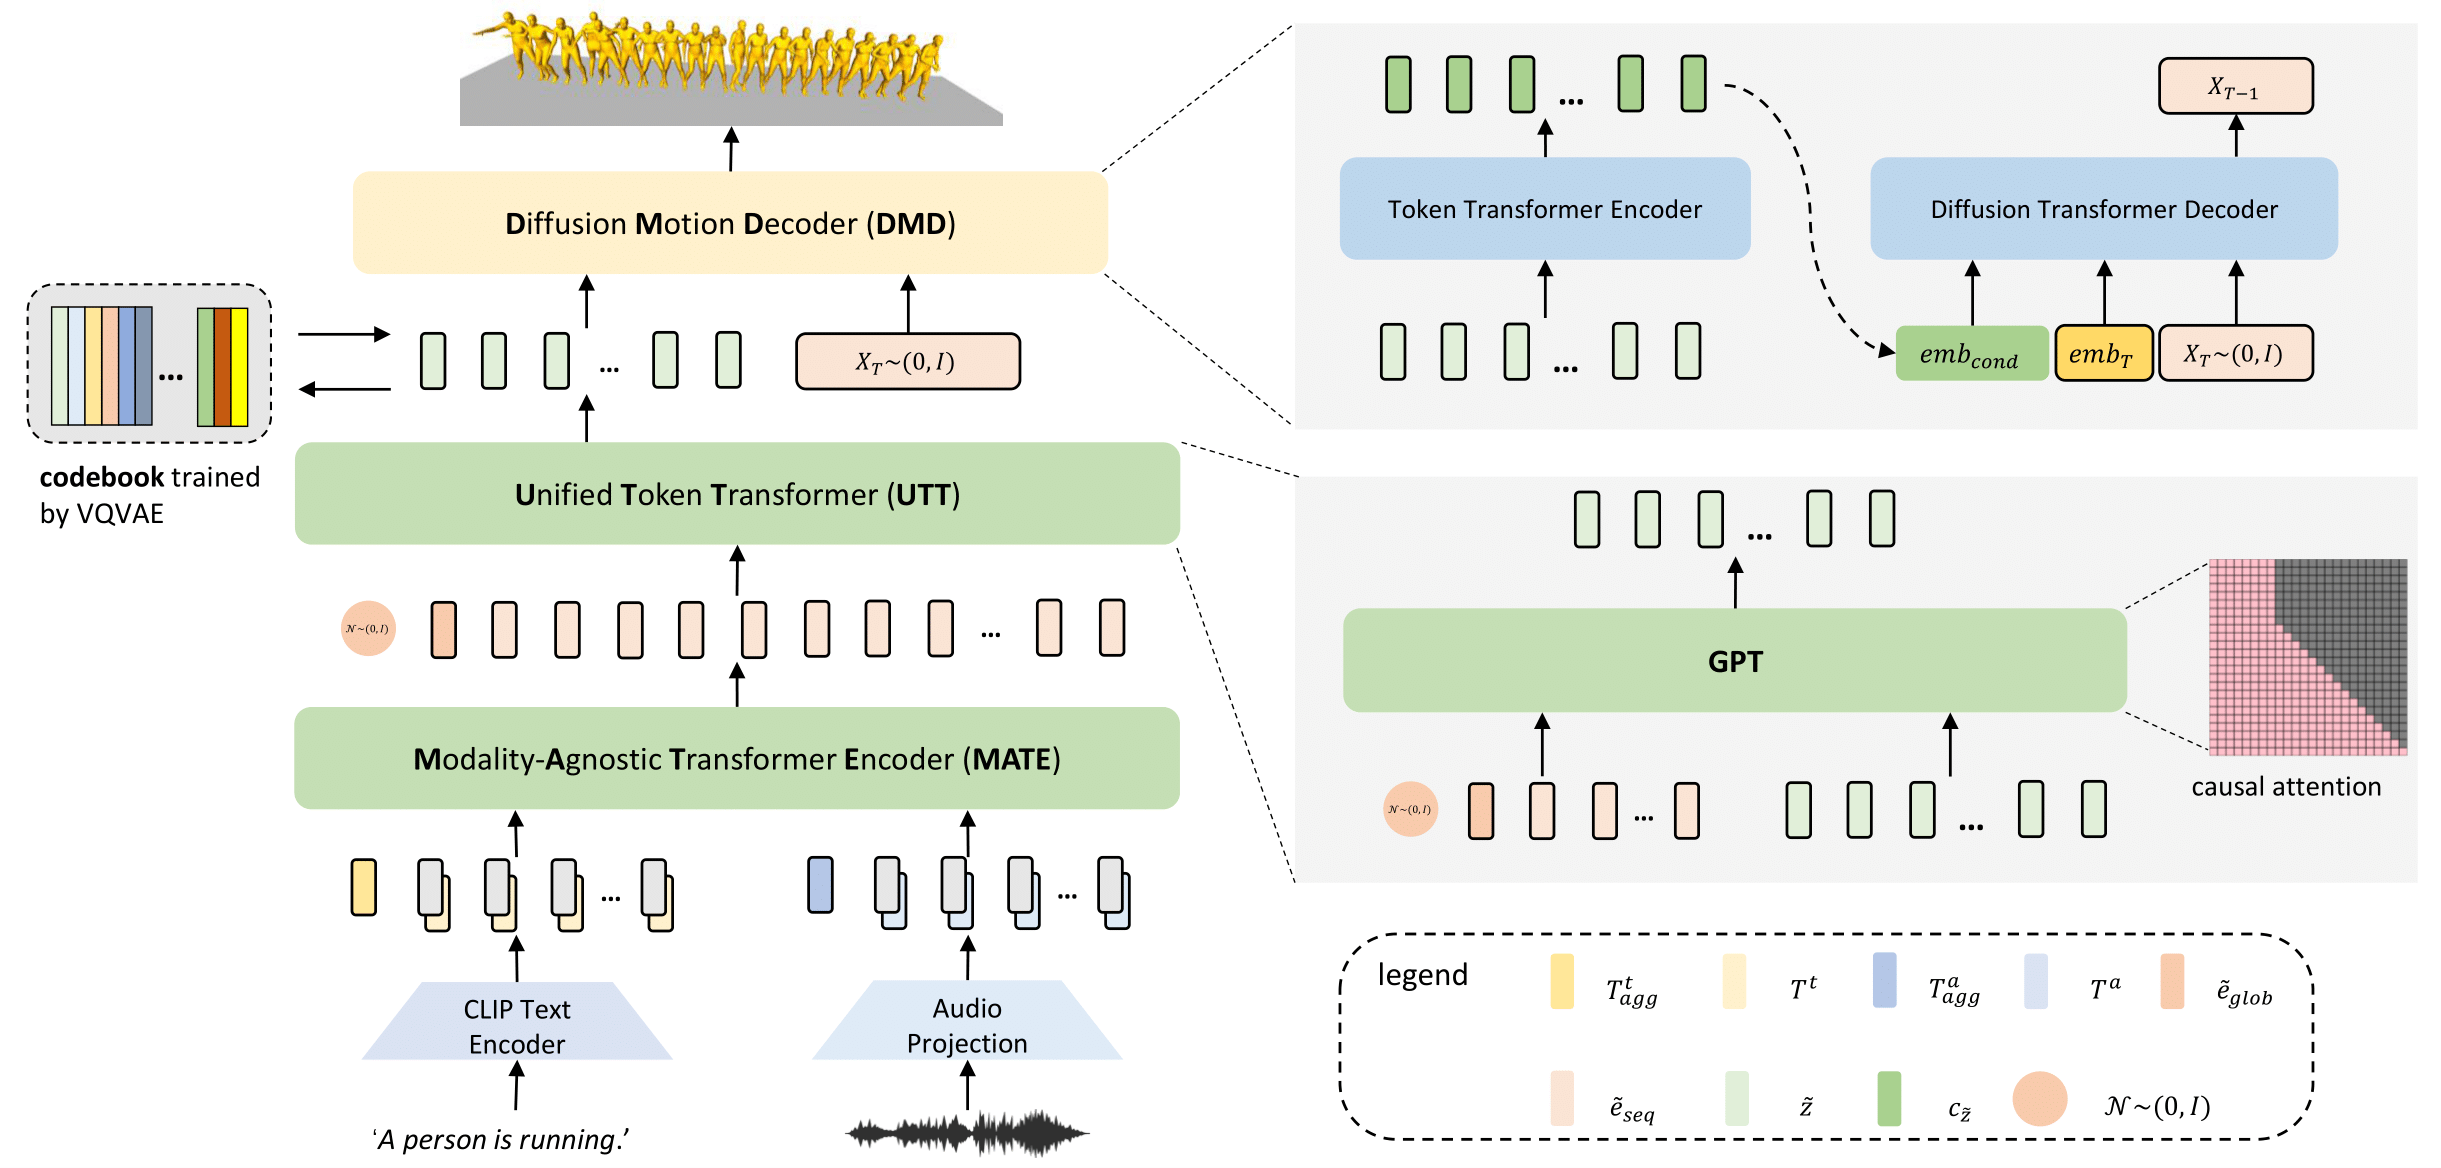
UDE: A Unified Driving Engine for Human Motion Generation
 Papers
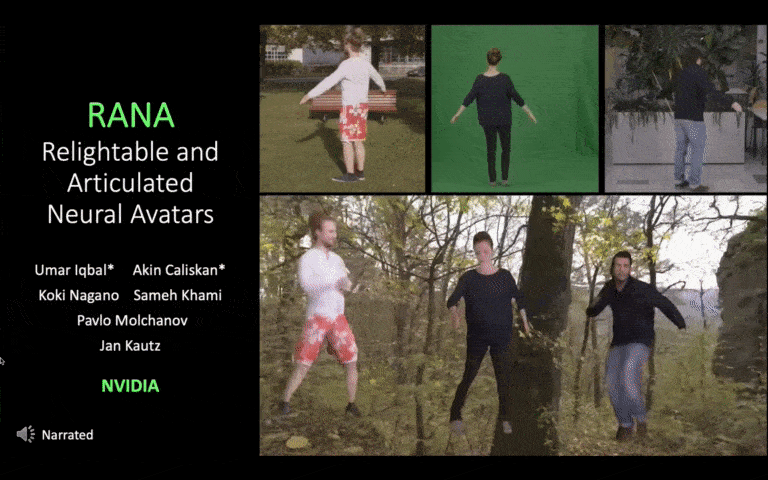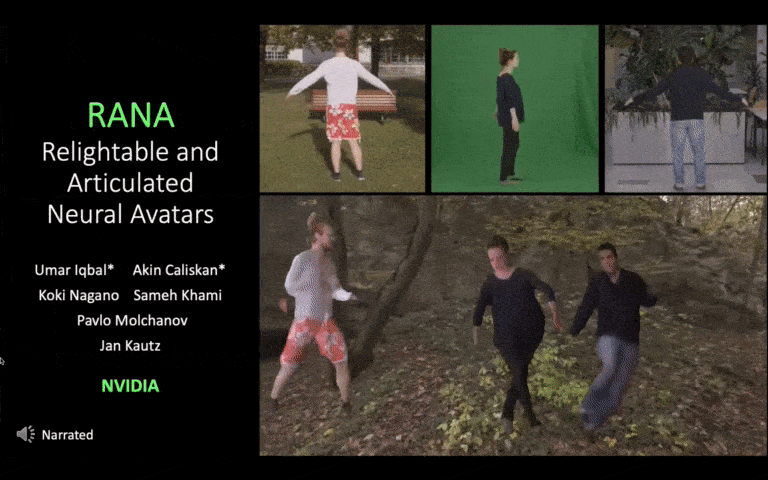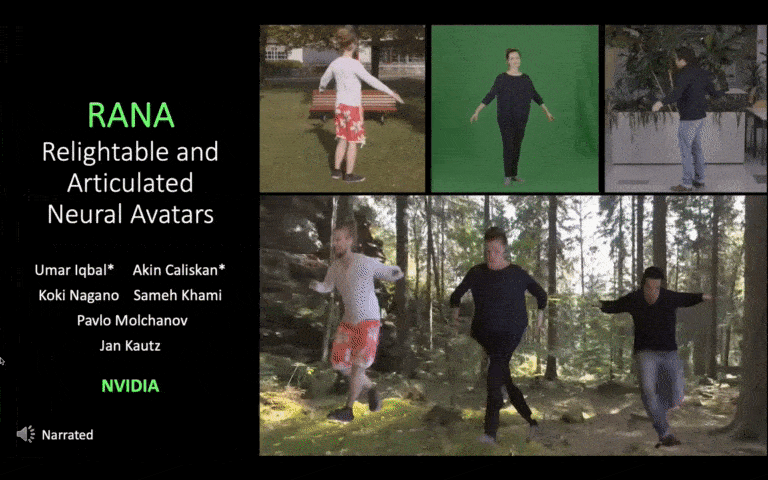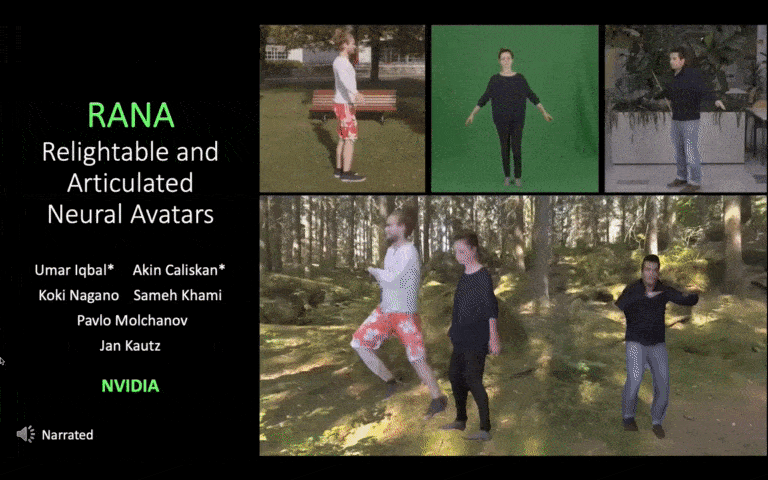
RANA: Relightable Articulated Neural Avatars
 Papers
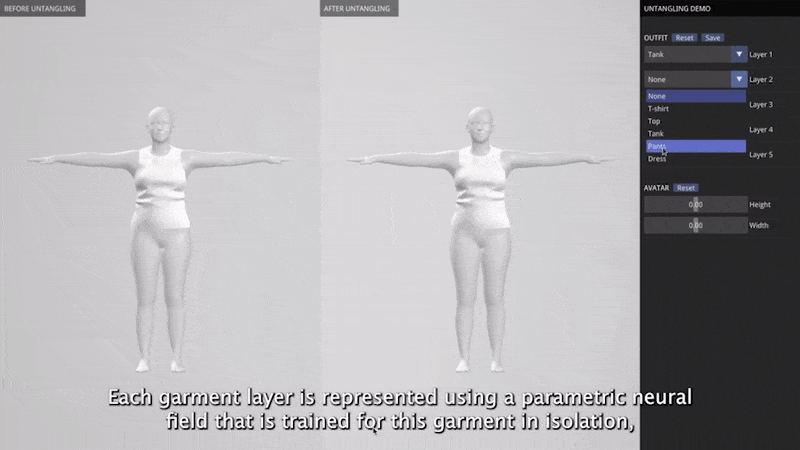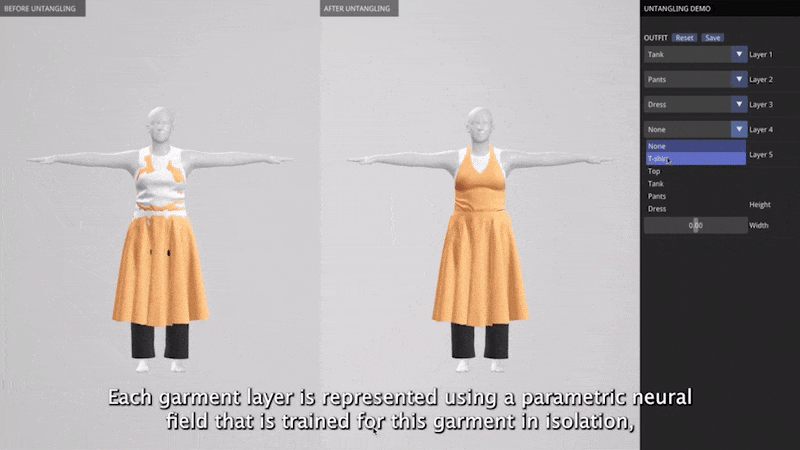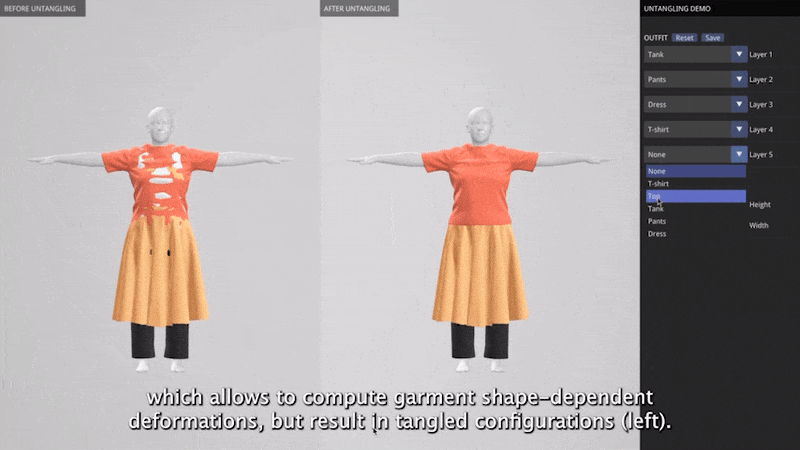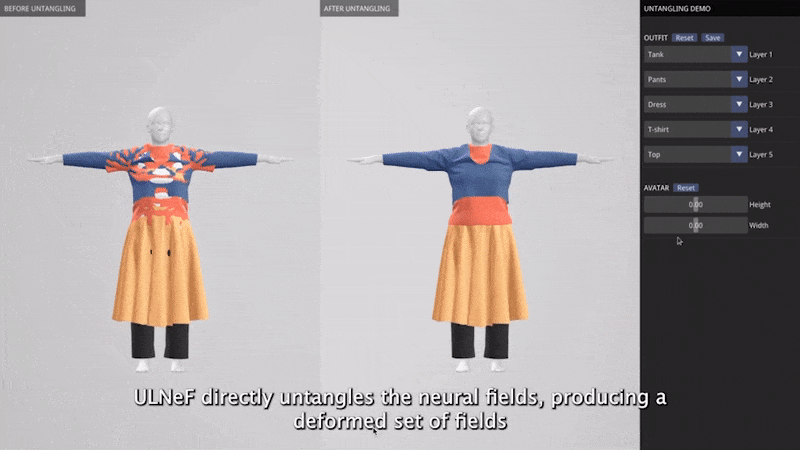
ULNeF: Untangled Layered Neural Fields for Mix-and-Match Virtual Try-On
 Papers
DiffusionDB: A Large-scale Prompt Gallery Dataset for Text-to-Image Generative Models
 Papers
eDiffi: Text-to-Image Diffusion Models with Ensemble of Expert Denoisers
 Papers
Musika! Fast Infinite Waveform Music Generation
 News
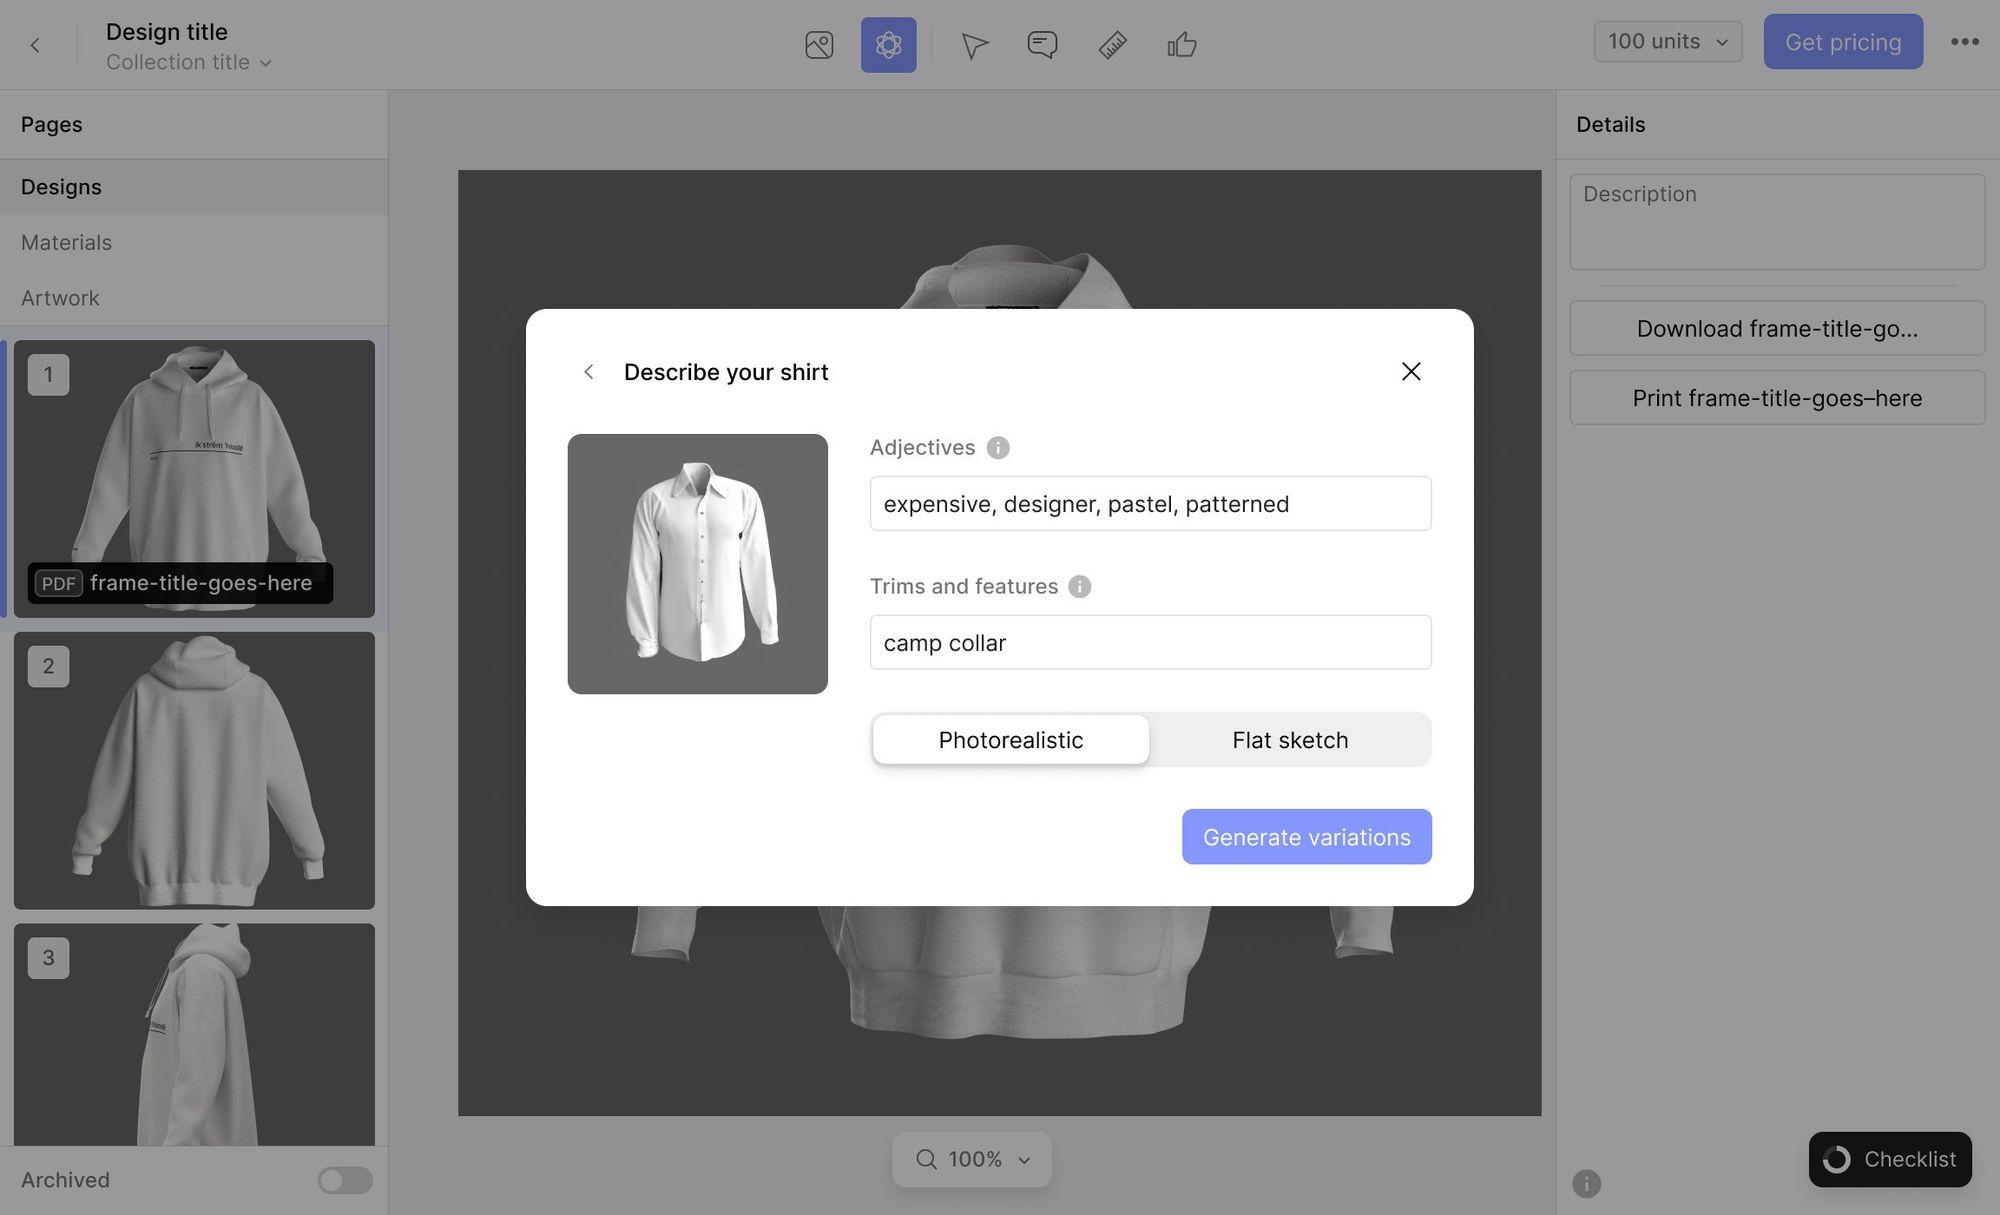
CALA uses DALL-E to generate designs for clothing, accessories, footwear, and lifestyle products
 Papers
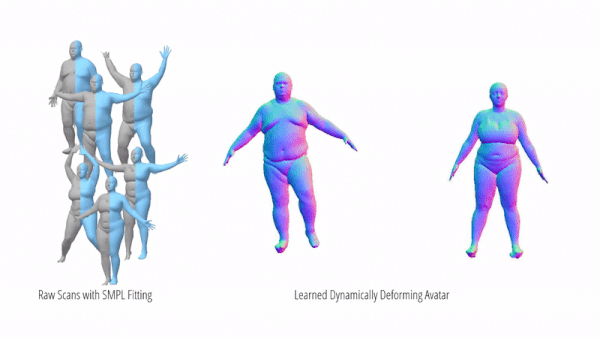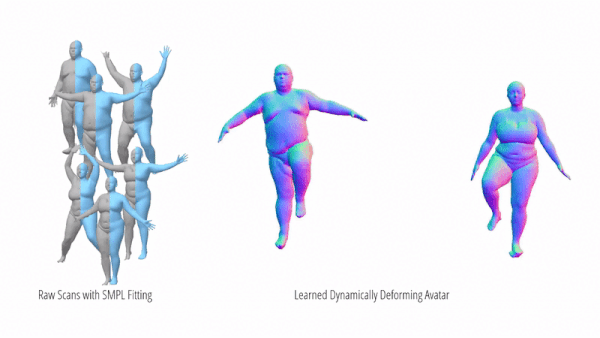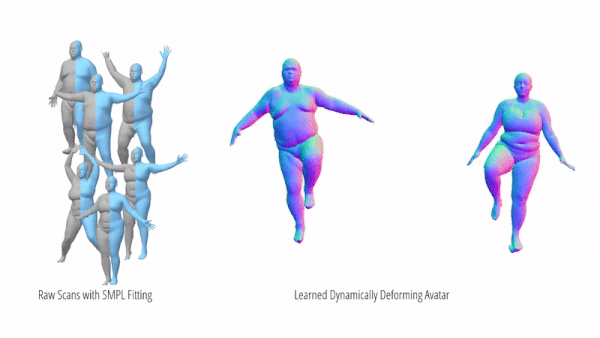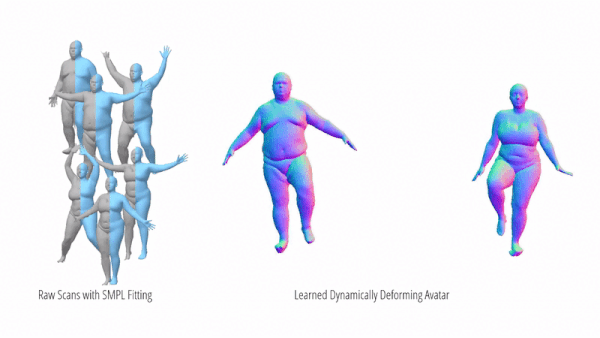
AutoAvatar: Autoregressive Neural Fields for Dynamic Avatar Modeling
 Papers
High Fidelity Neural Audio Compression