Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 Papers
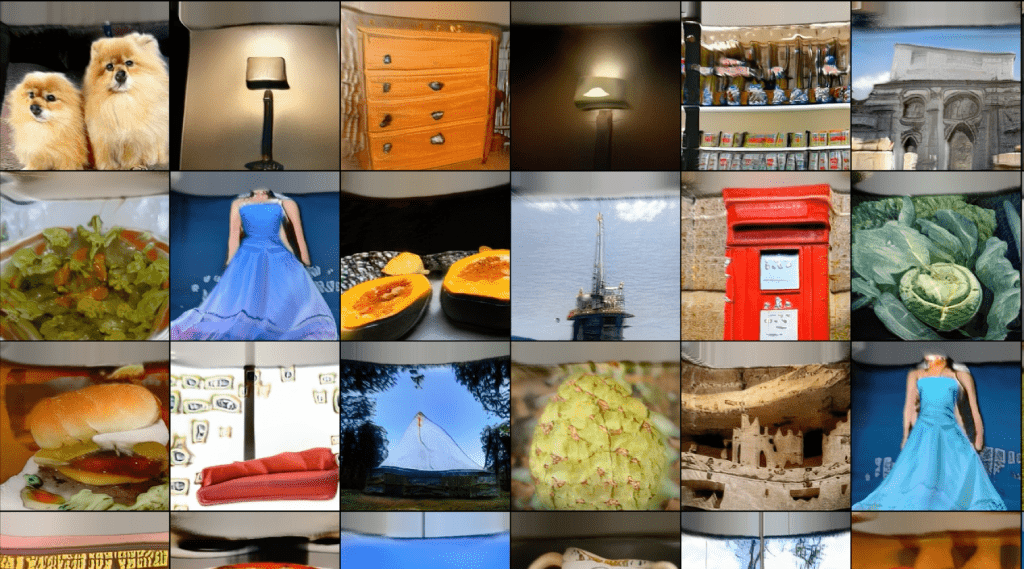
3D Generation on ImageNet
 Papers
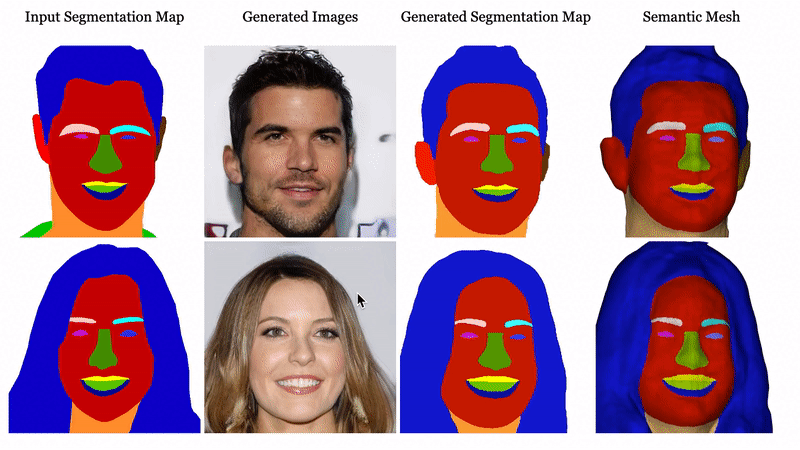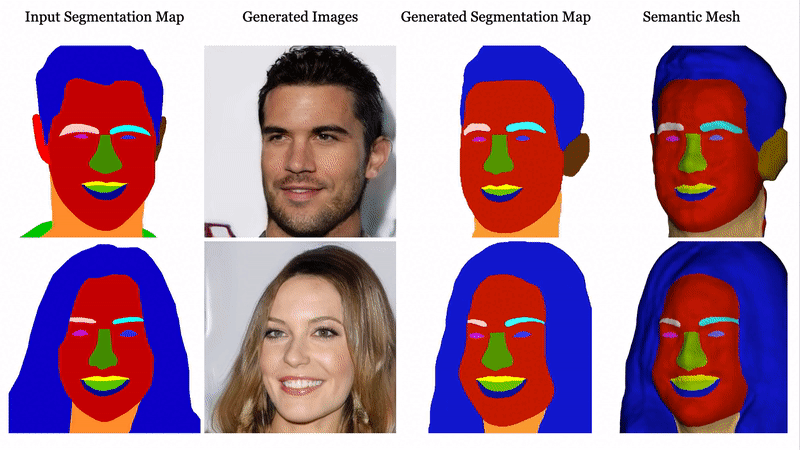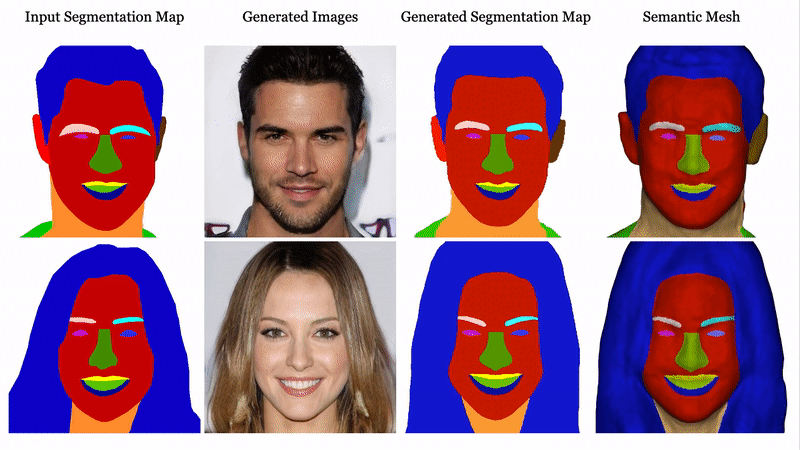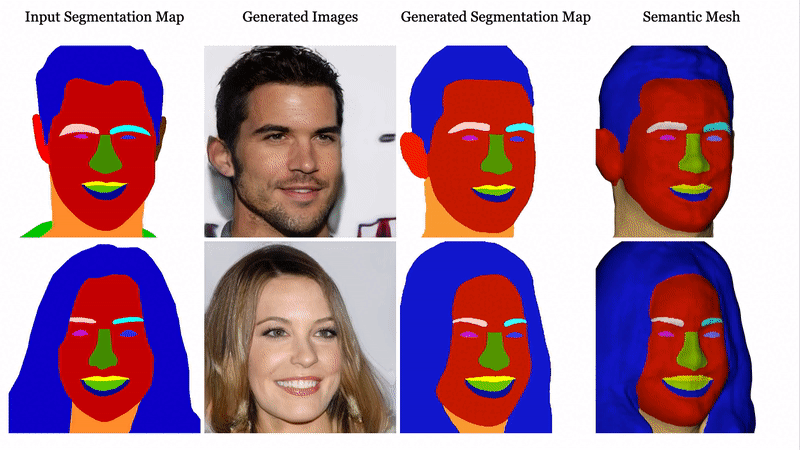
3D-aware Conditional Image Synthesis
 Papers
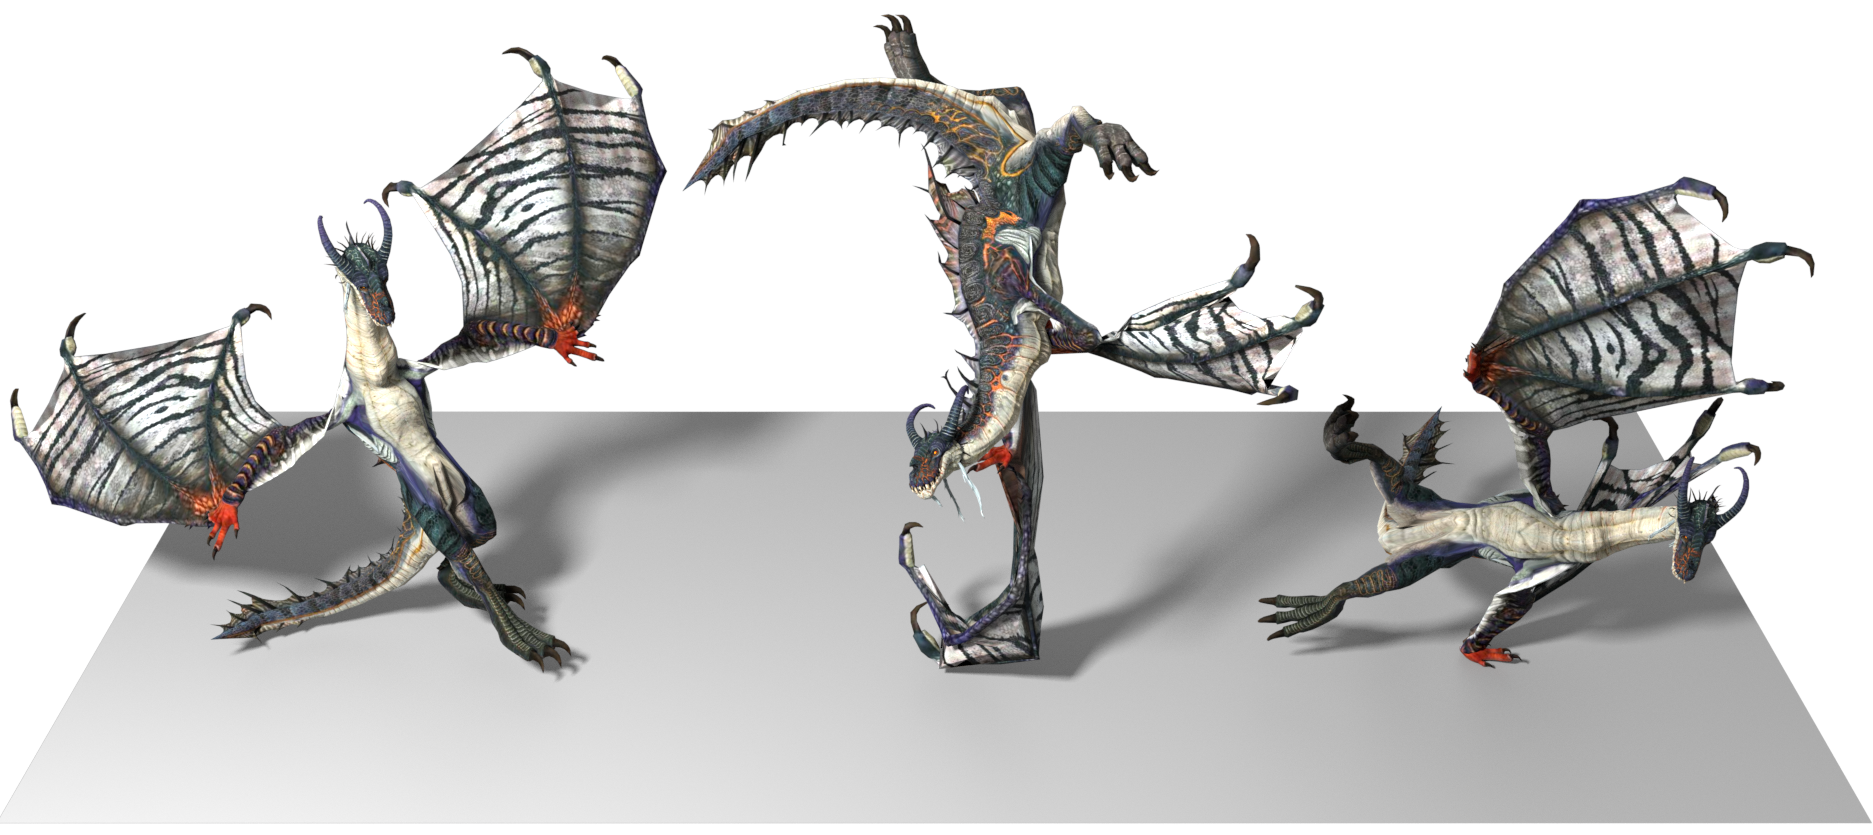
SinMDM: Single Motion Diffusion
 Papers
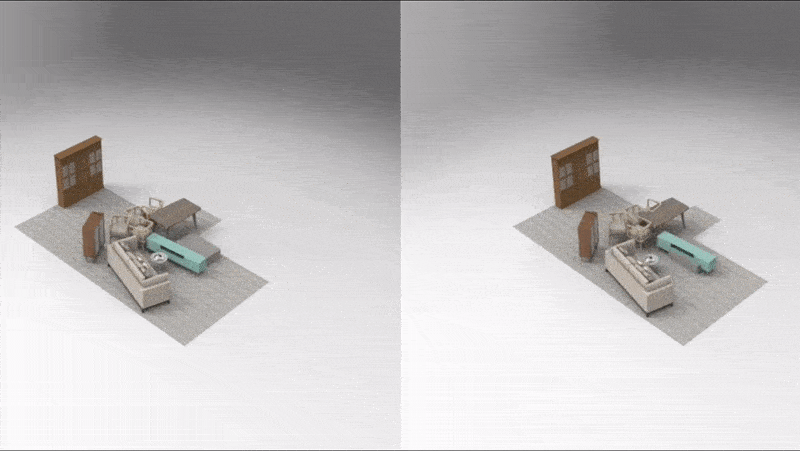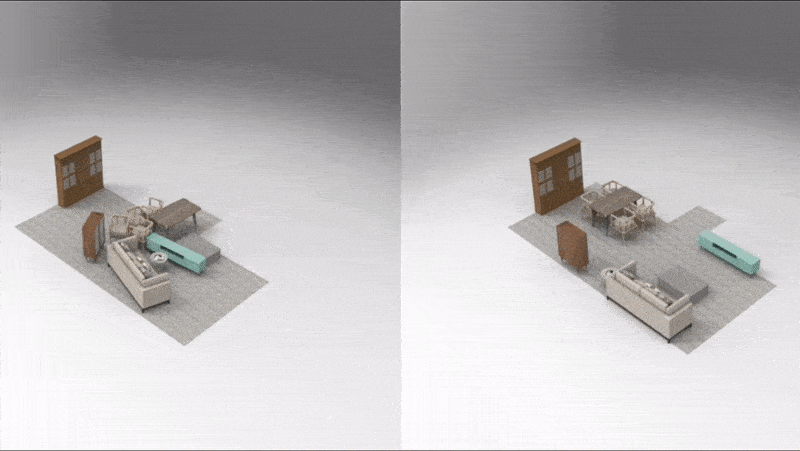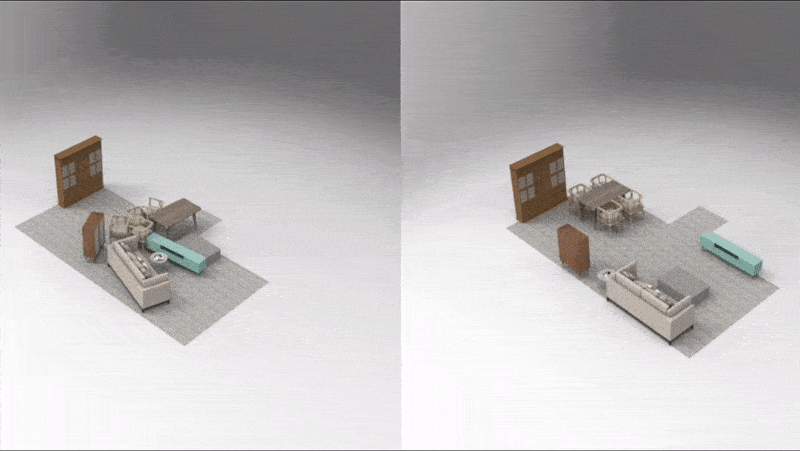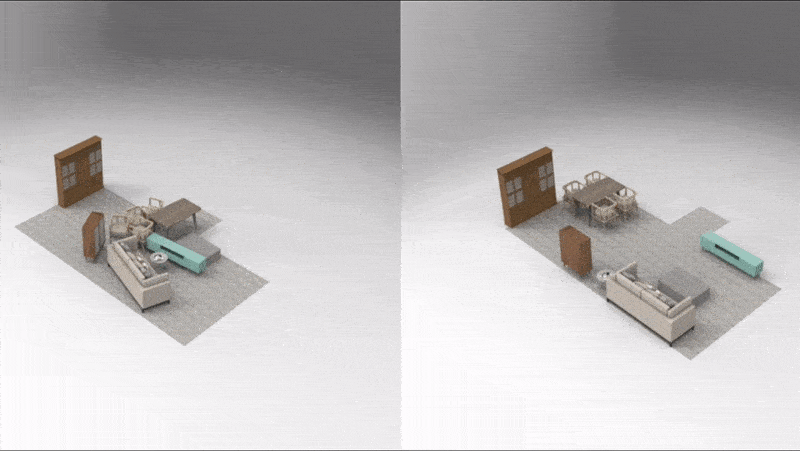
LEGO-Net: Learning Regular Rearrangements of Objects in Rooms
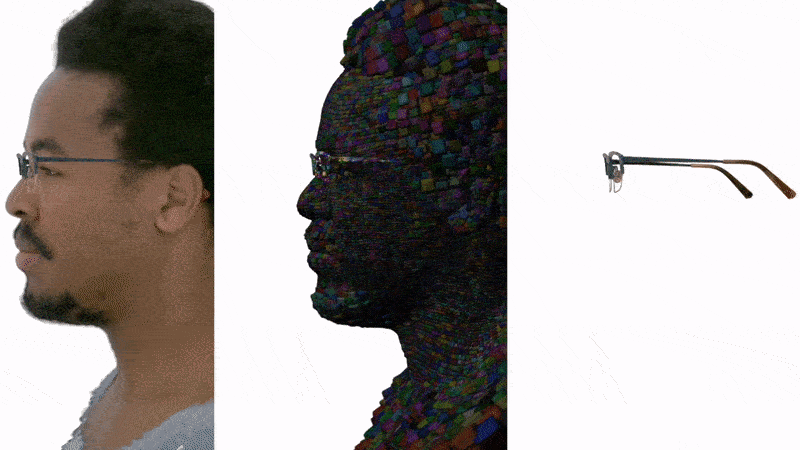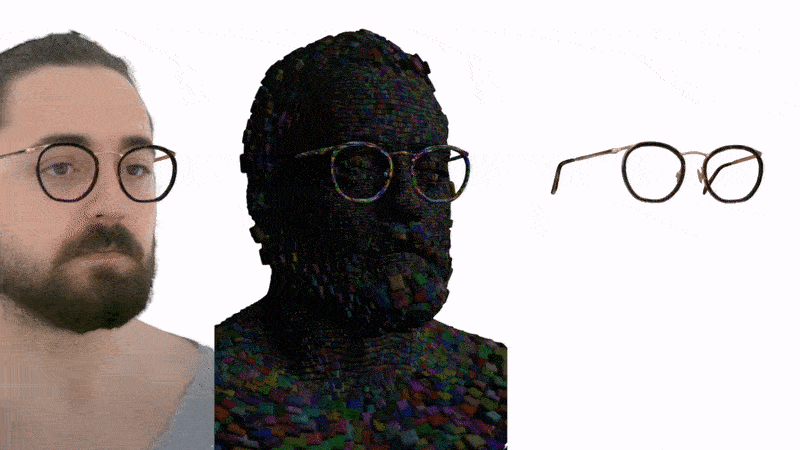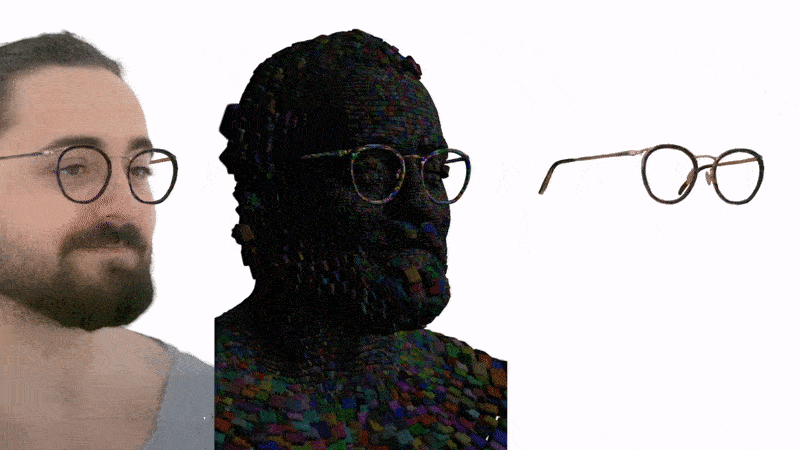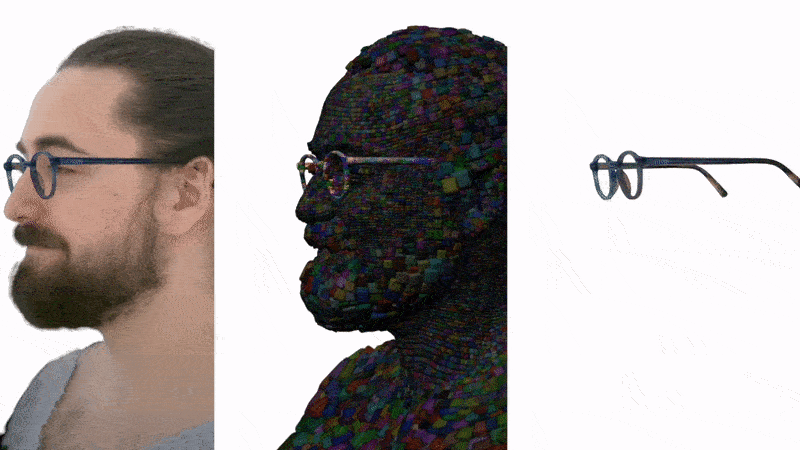 Papers
MEGANE: Morphable Eyeglass and Avatar Network
 Papers
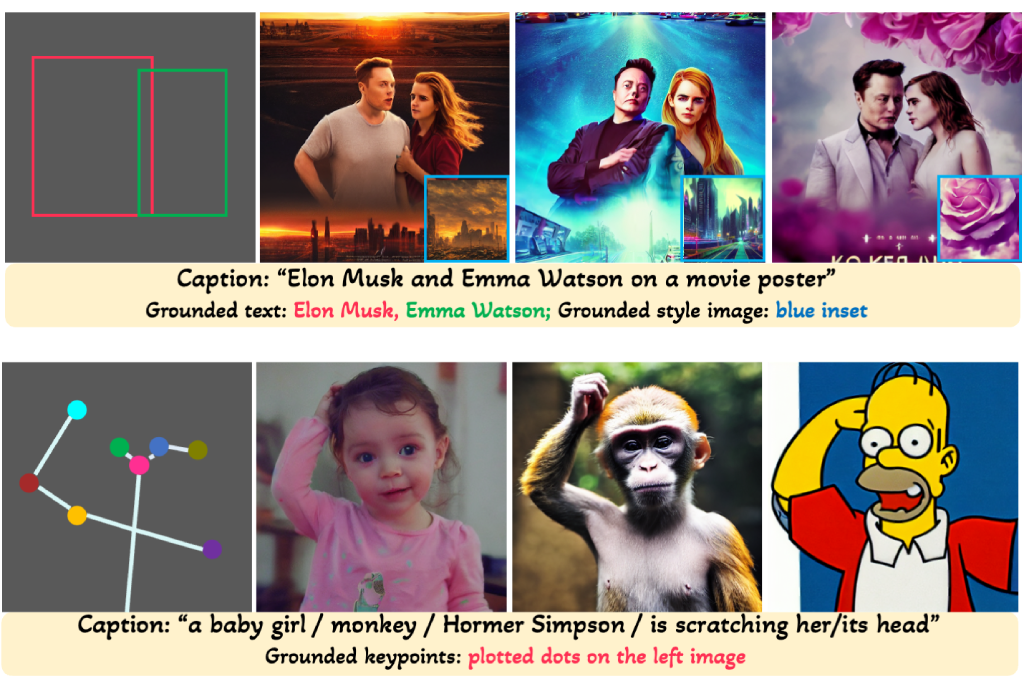
GLIGEN: Open-Set Grounded Text-to-Image Generation
 Papers
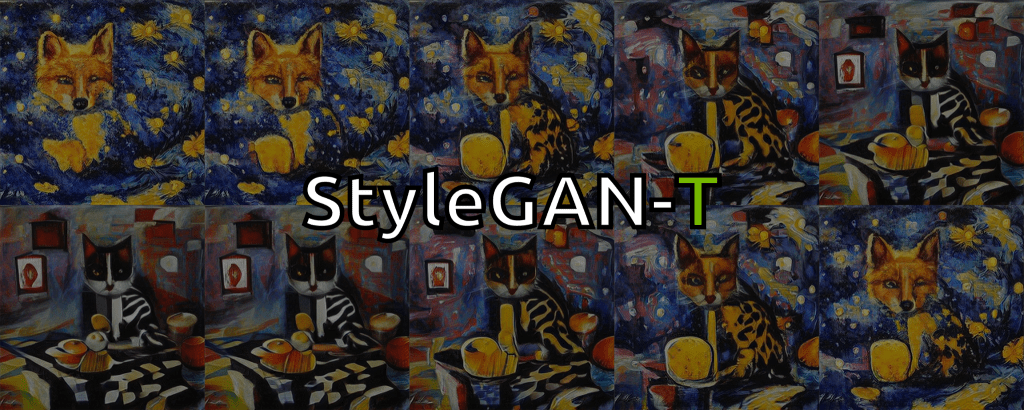
StyleGAN-T: Unlocking the Power of GANs for Fast Large-Scale Text-to-Image Synthesis
 Papers
HyperReel: High-Fidelity 6-DoF Video with Ray-Conditioned Sampling
 Papers
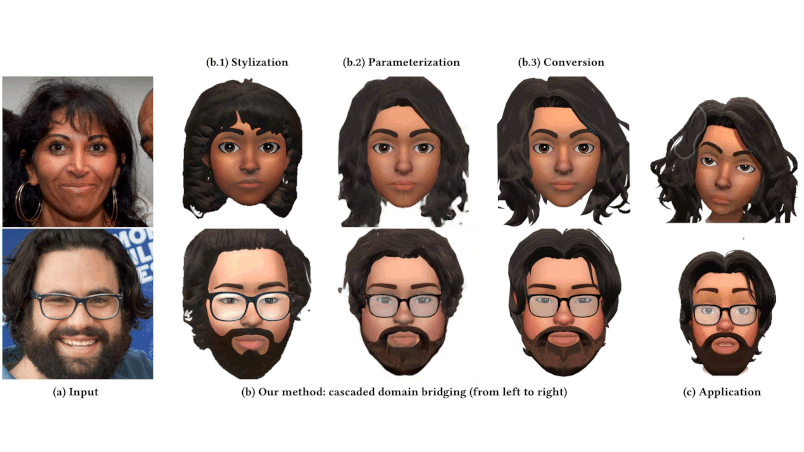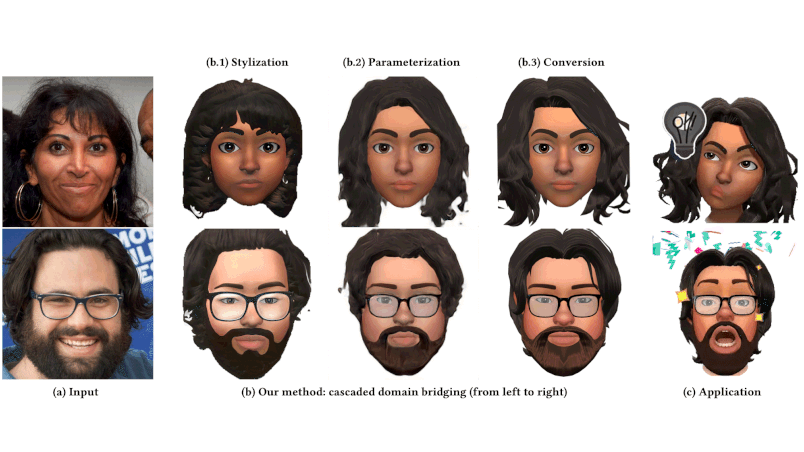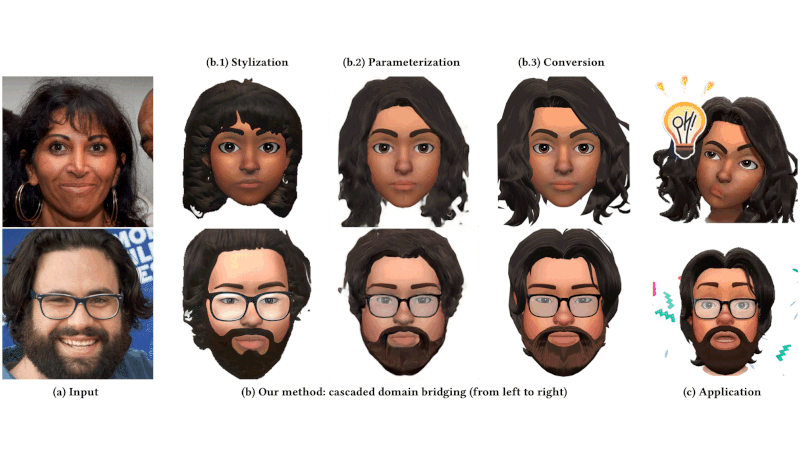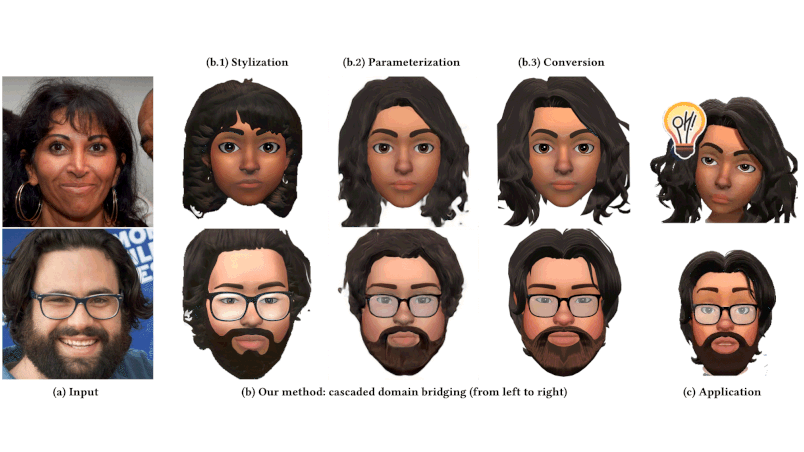
AgileAvatar: Stylized 3D Avatar Creation via Cascaded Domain Bridging
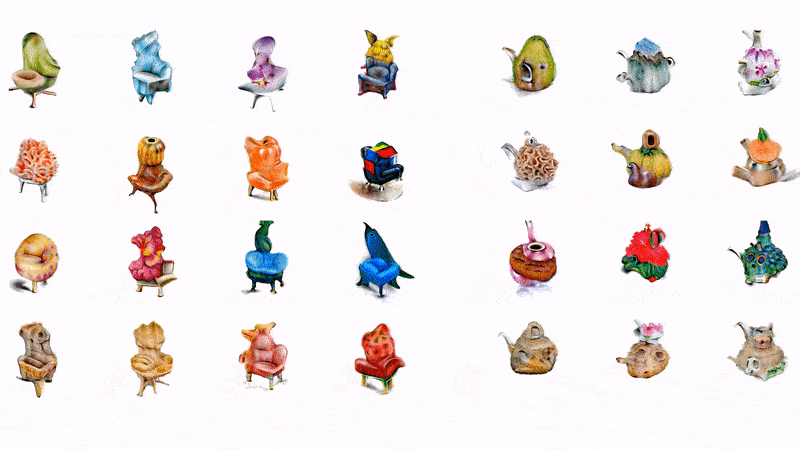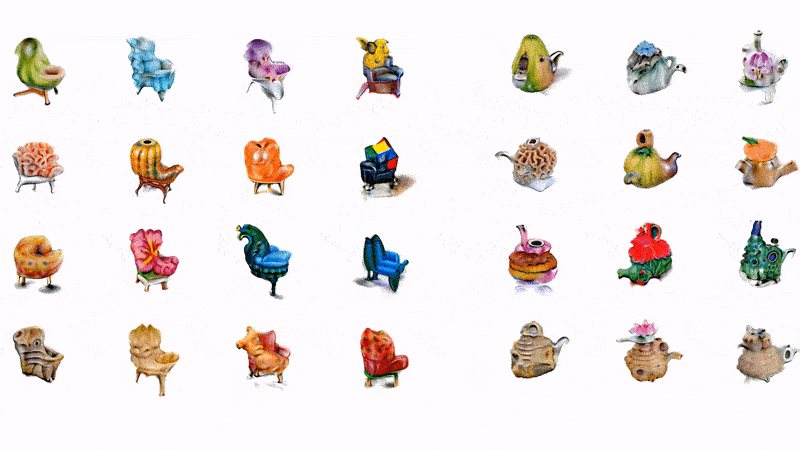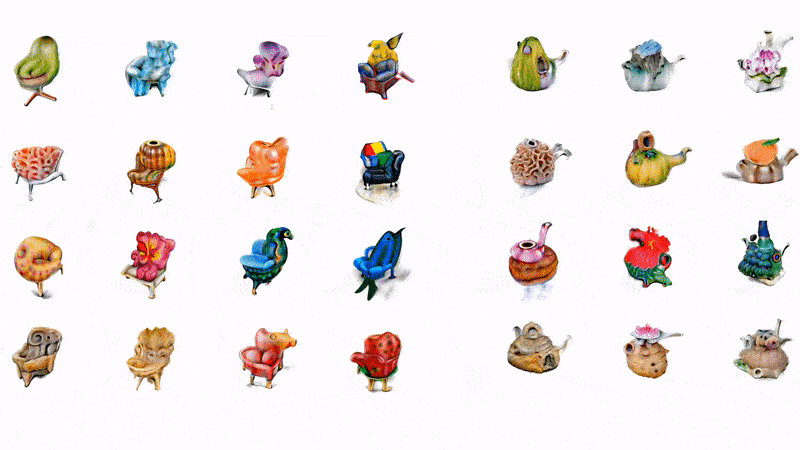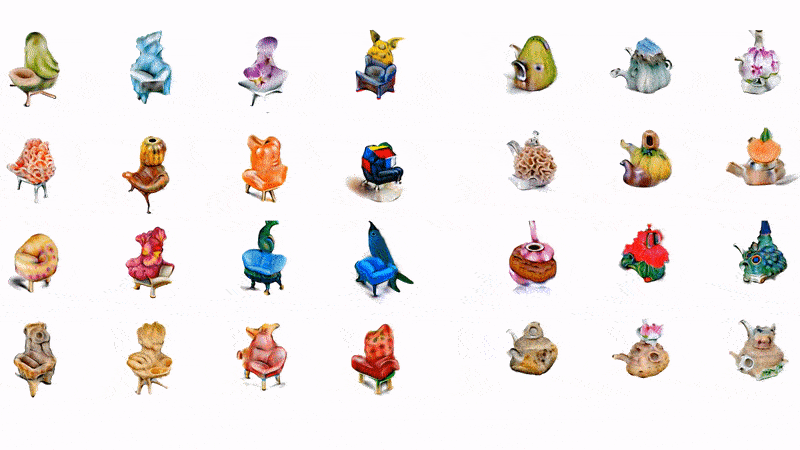 Papers
Zero-Shot Text-Guided Object Generation with Dream Fields
 Papers
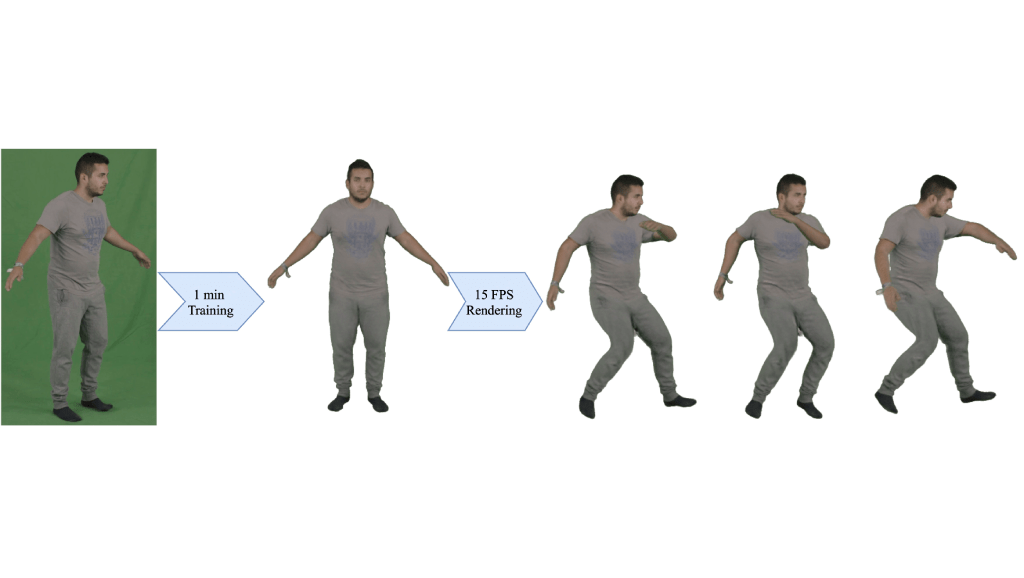
InstantAvatar: Learning Avatars from Monocular Video in 60 Seconds
 Papers
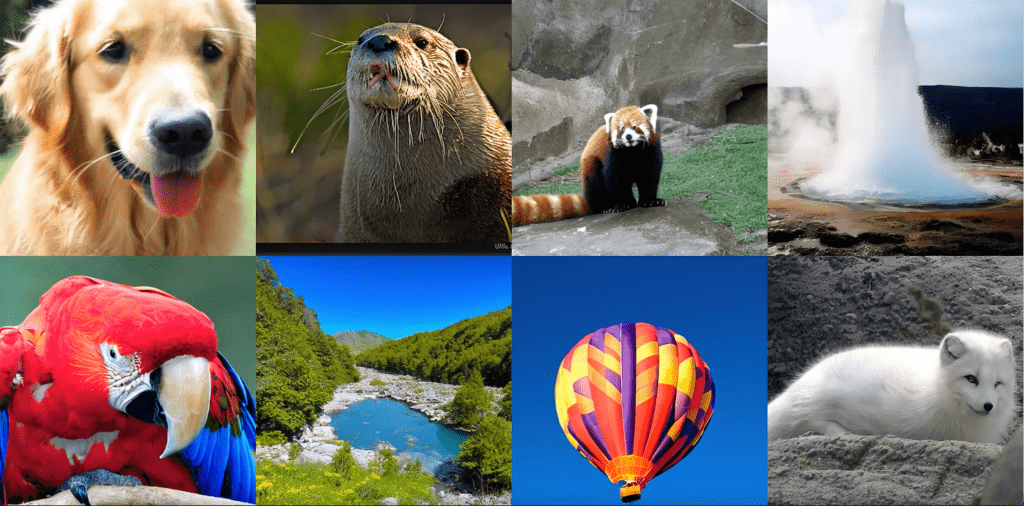
Scalable Diffusion Models with Transformers