Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
Shutterstock to integrate OpenAI’s DALL-E 2 and launch fund for contributor artists
 Papers
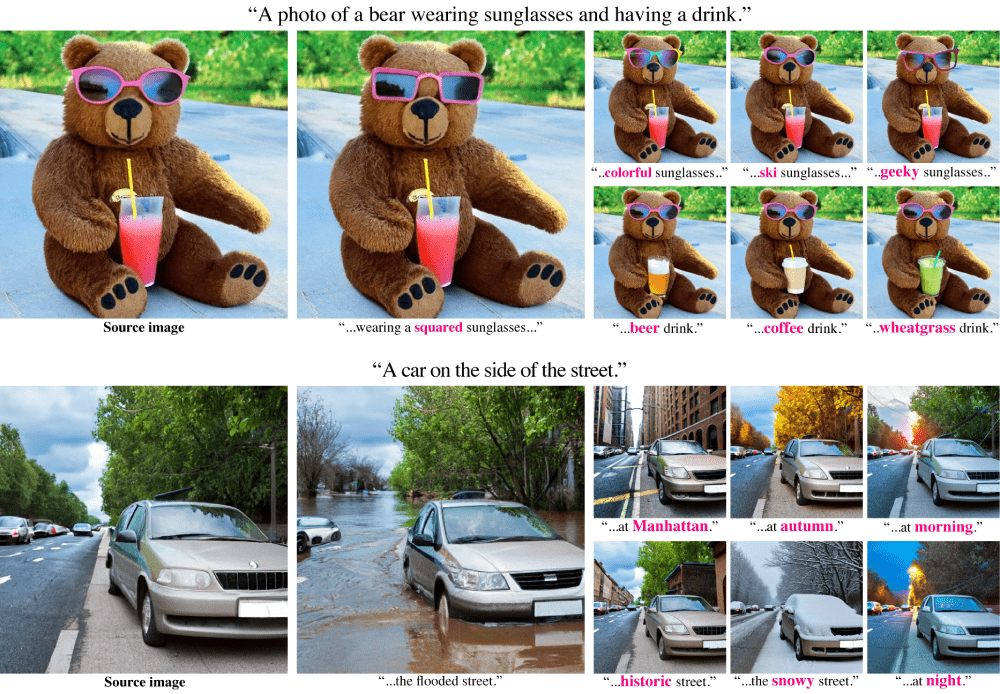
Prompt-to-Prompt Image Editing with Cross-Attention Control
 Papers
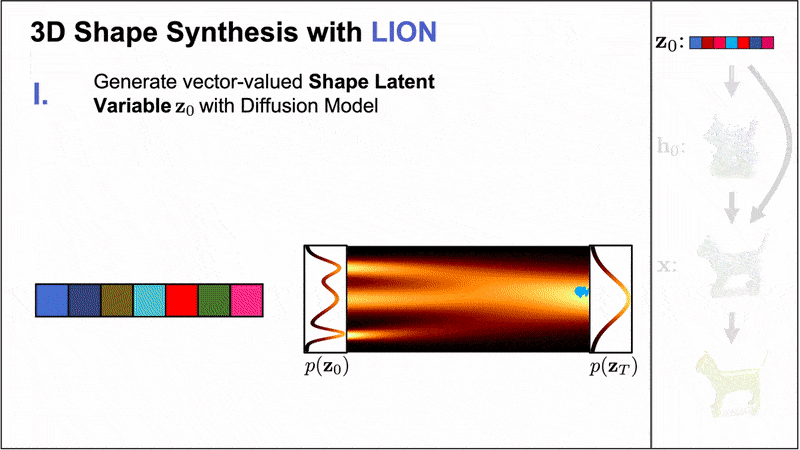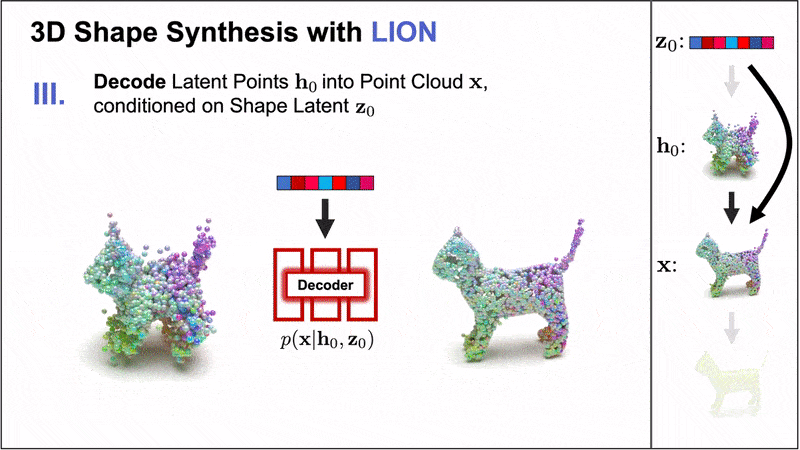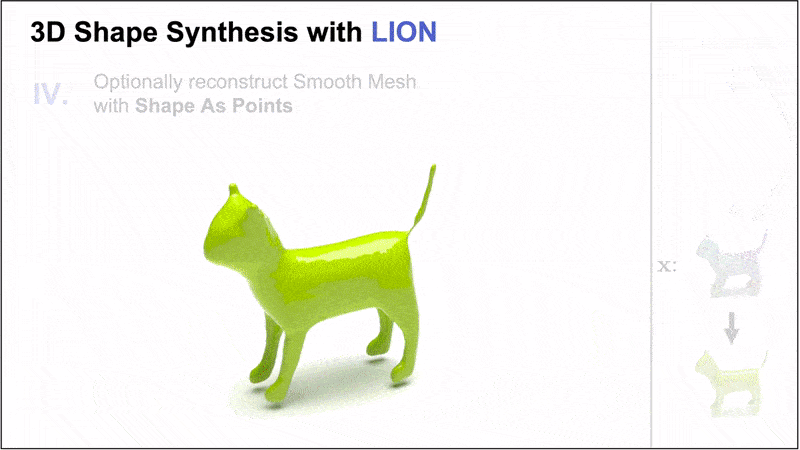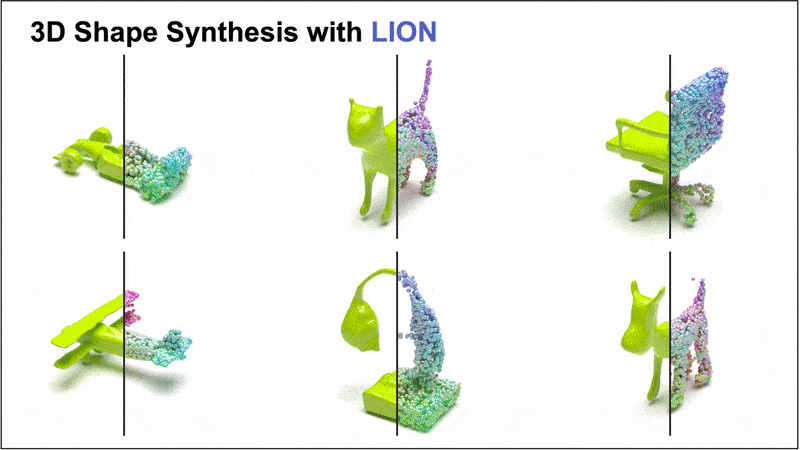
LION: Latent point diffusion models for generating 3D shapes
 News
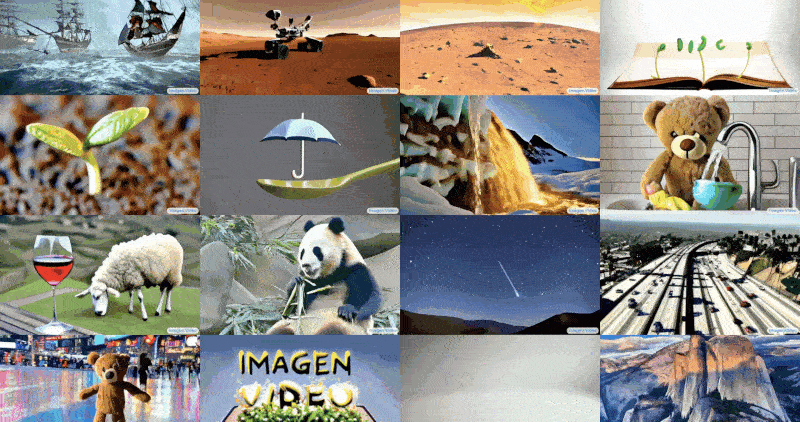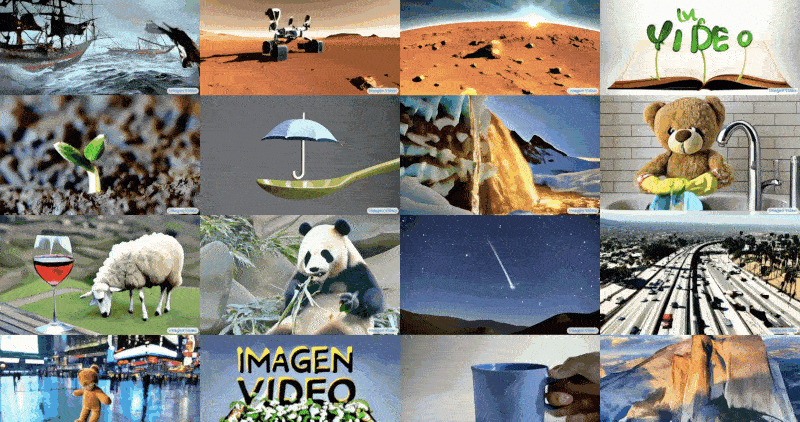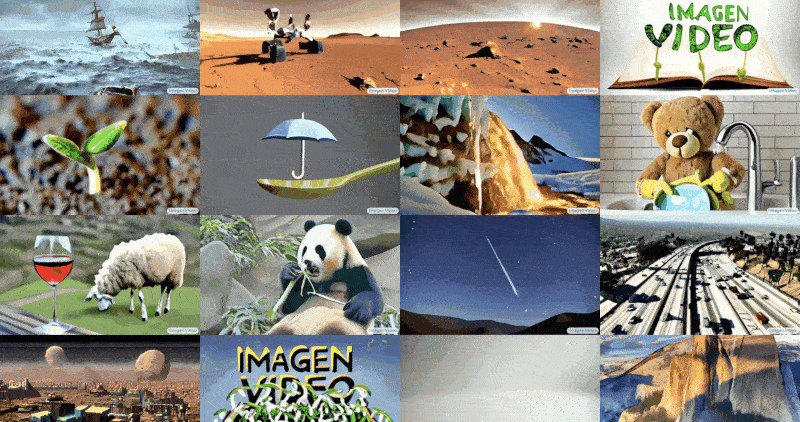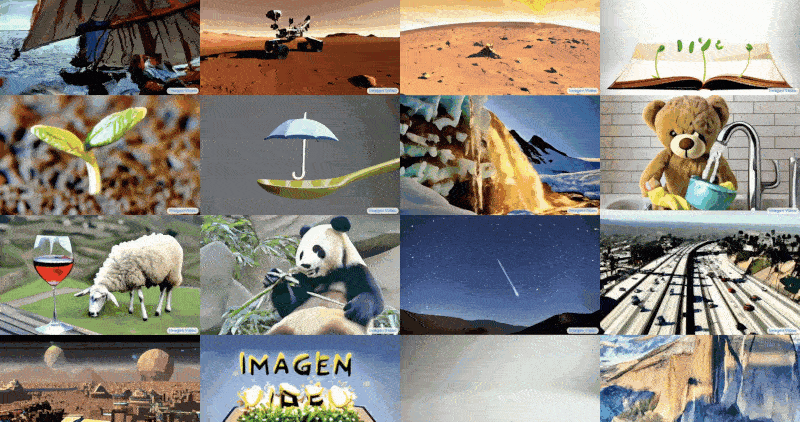
Uninterrupted diffusion with Imagen Video
 News
Make-A-Video artificial intelligence system - generating video from text
 News
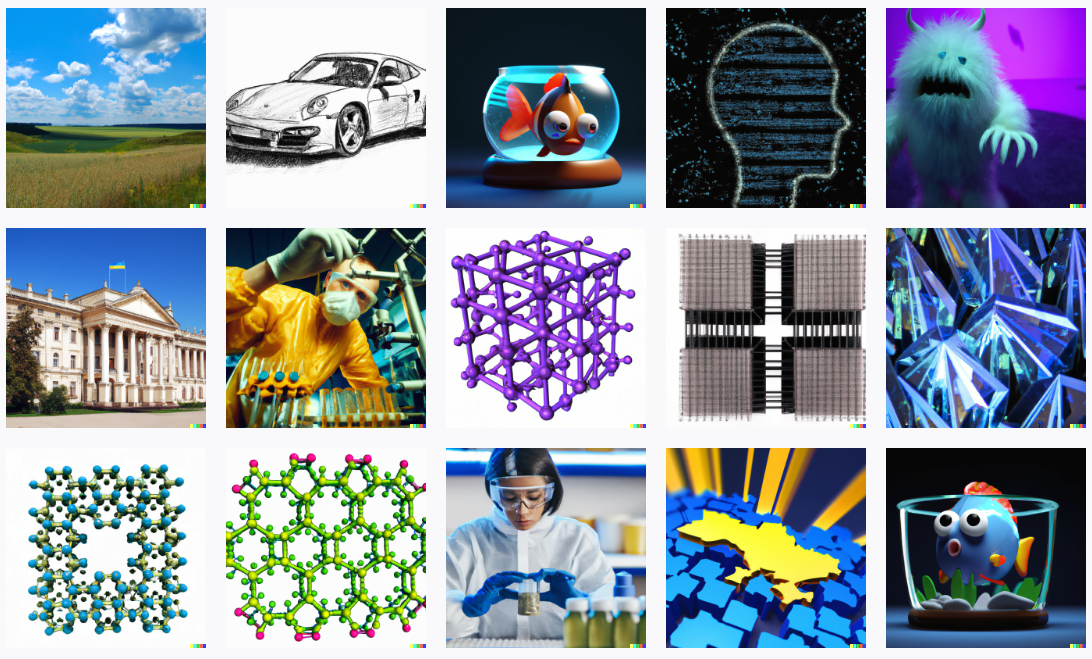
DALL-E is now available without a waiting list
 News
A film about the love story of a cockroach and artificial intelligence from GPT-3
 News
A new computer game with DALLE-2
 News
Stable Diffusion and crazy animations
 News
The DALL-E 2 Prompt Book
 News
DALL-E is now available in beta
 News
NVIDIA 3D MoMa: New Methods to Improvise with 3D Objects