Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
Apple opens iOS 27 public beta, giving Siri AI its first public test
- News
OpenAI launches full-duplex GPT-Live voice models as default across ChatGPT tiers
 News
Meta ships Muse Image and Muse Video, its first in-house generative media models
 News
Hugging Face and Cerebras open-source a speech-to-speech pipeline running Gemma 4 at 1,851 tokens per second
 News
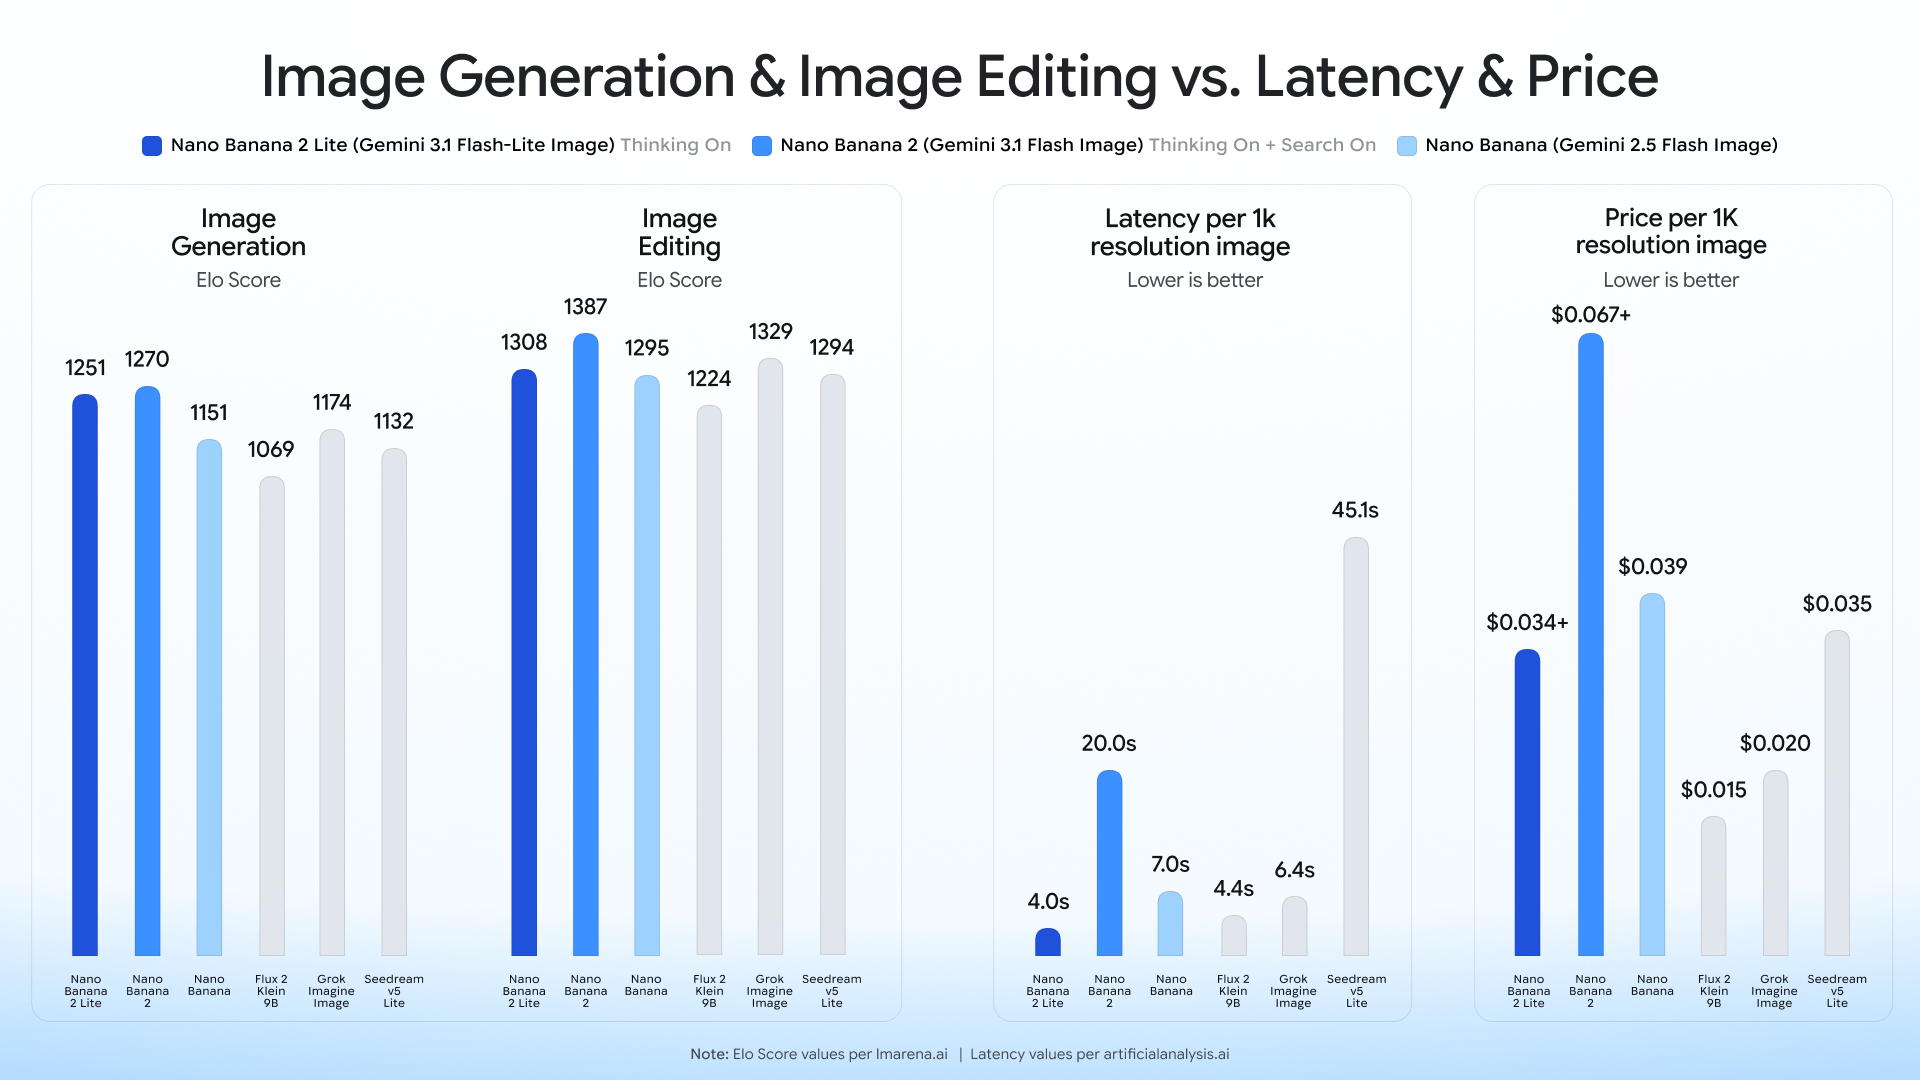
Google launches Gemini Omni Flash video model and Nano Banana 2 Lite for developers
 News
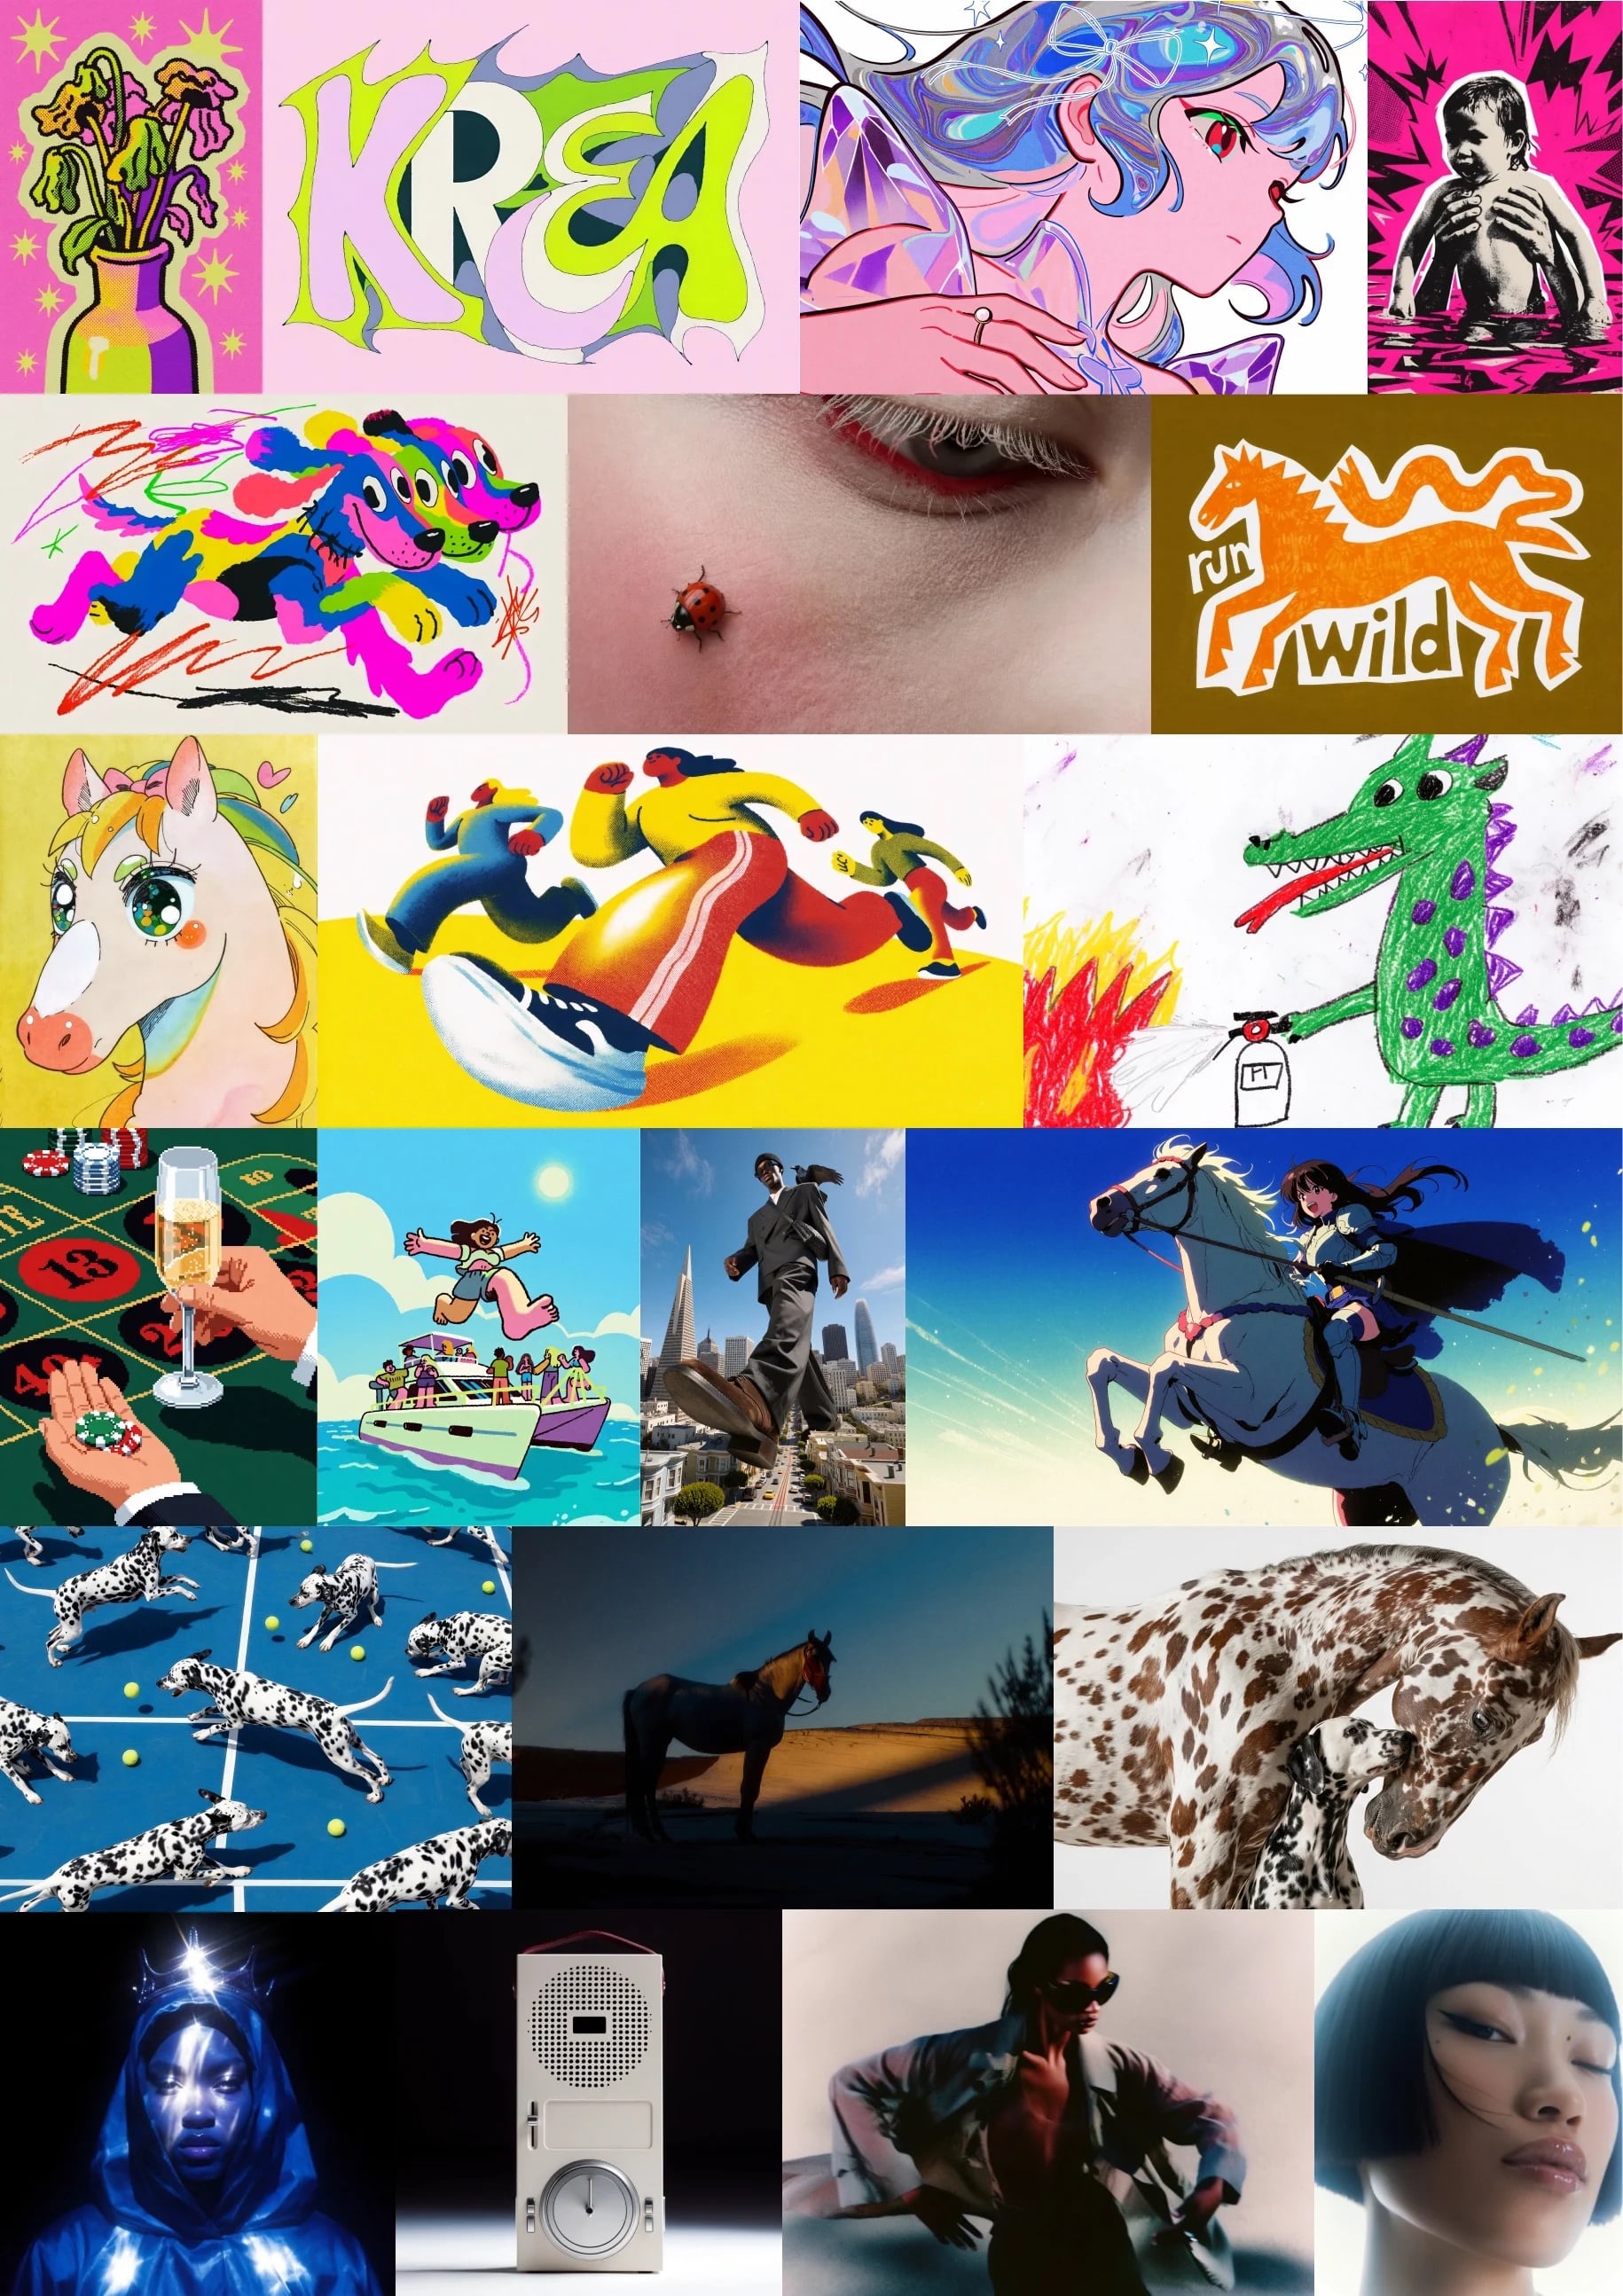
Krea AI releases Krea-2 open-weight image models with 2-second 2K generation
 News
Midjourney launches a whole-body ultrasound scanner it markets as 'Ultrasonic CT'
 News
Google's Gemini 3.5 Live Translate brings real-time voice translation to 70+ languages
 News
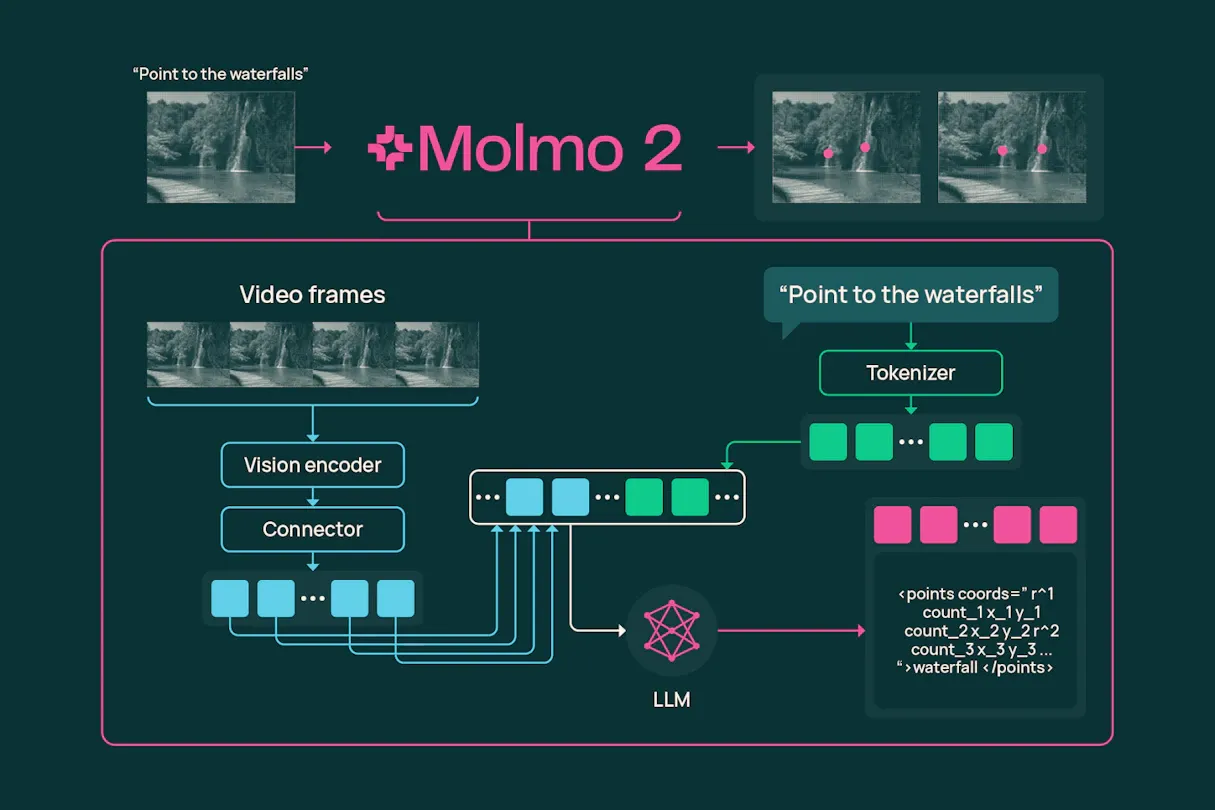
Ai2 launches Molmo 2, open-source multimodal models with advanced video understanding
 News
Kling VIDEO 2.6 introduces simultaneous video and audio generation
 News
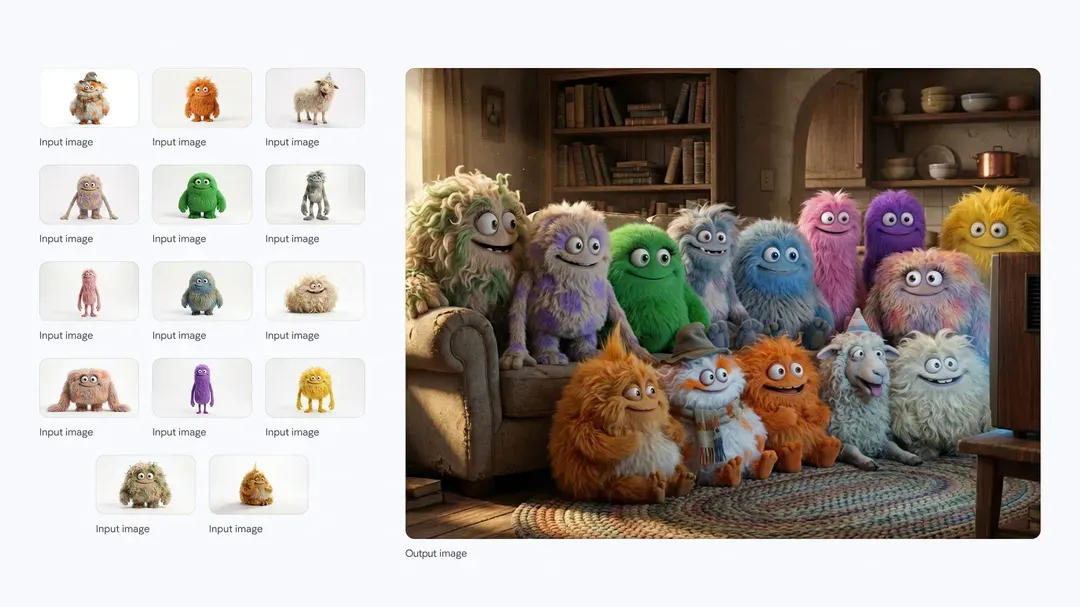
Google's Nano Banana Pro features superior text rendering capabilities
 News
Google's Gemini 3 brings improved reasoning and multimodal understanding